ZAI LLM / hardware benchmarking harness.
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
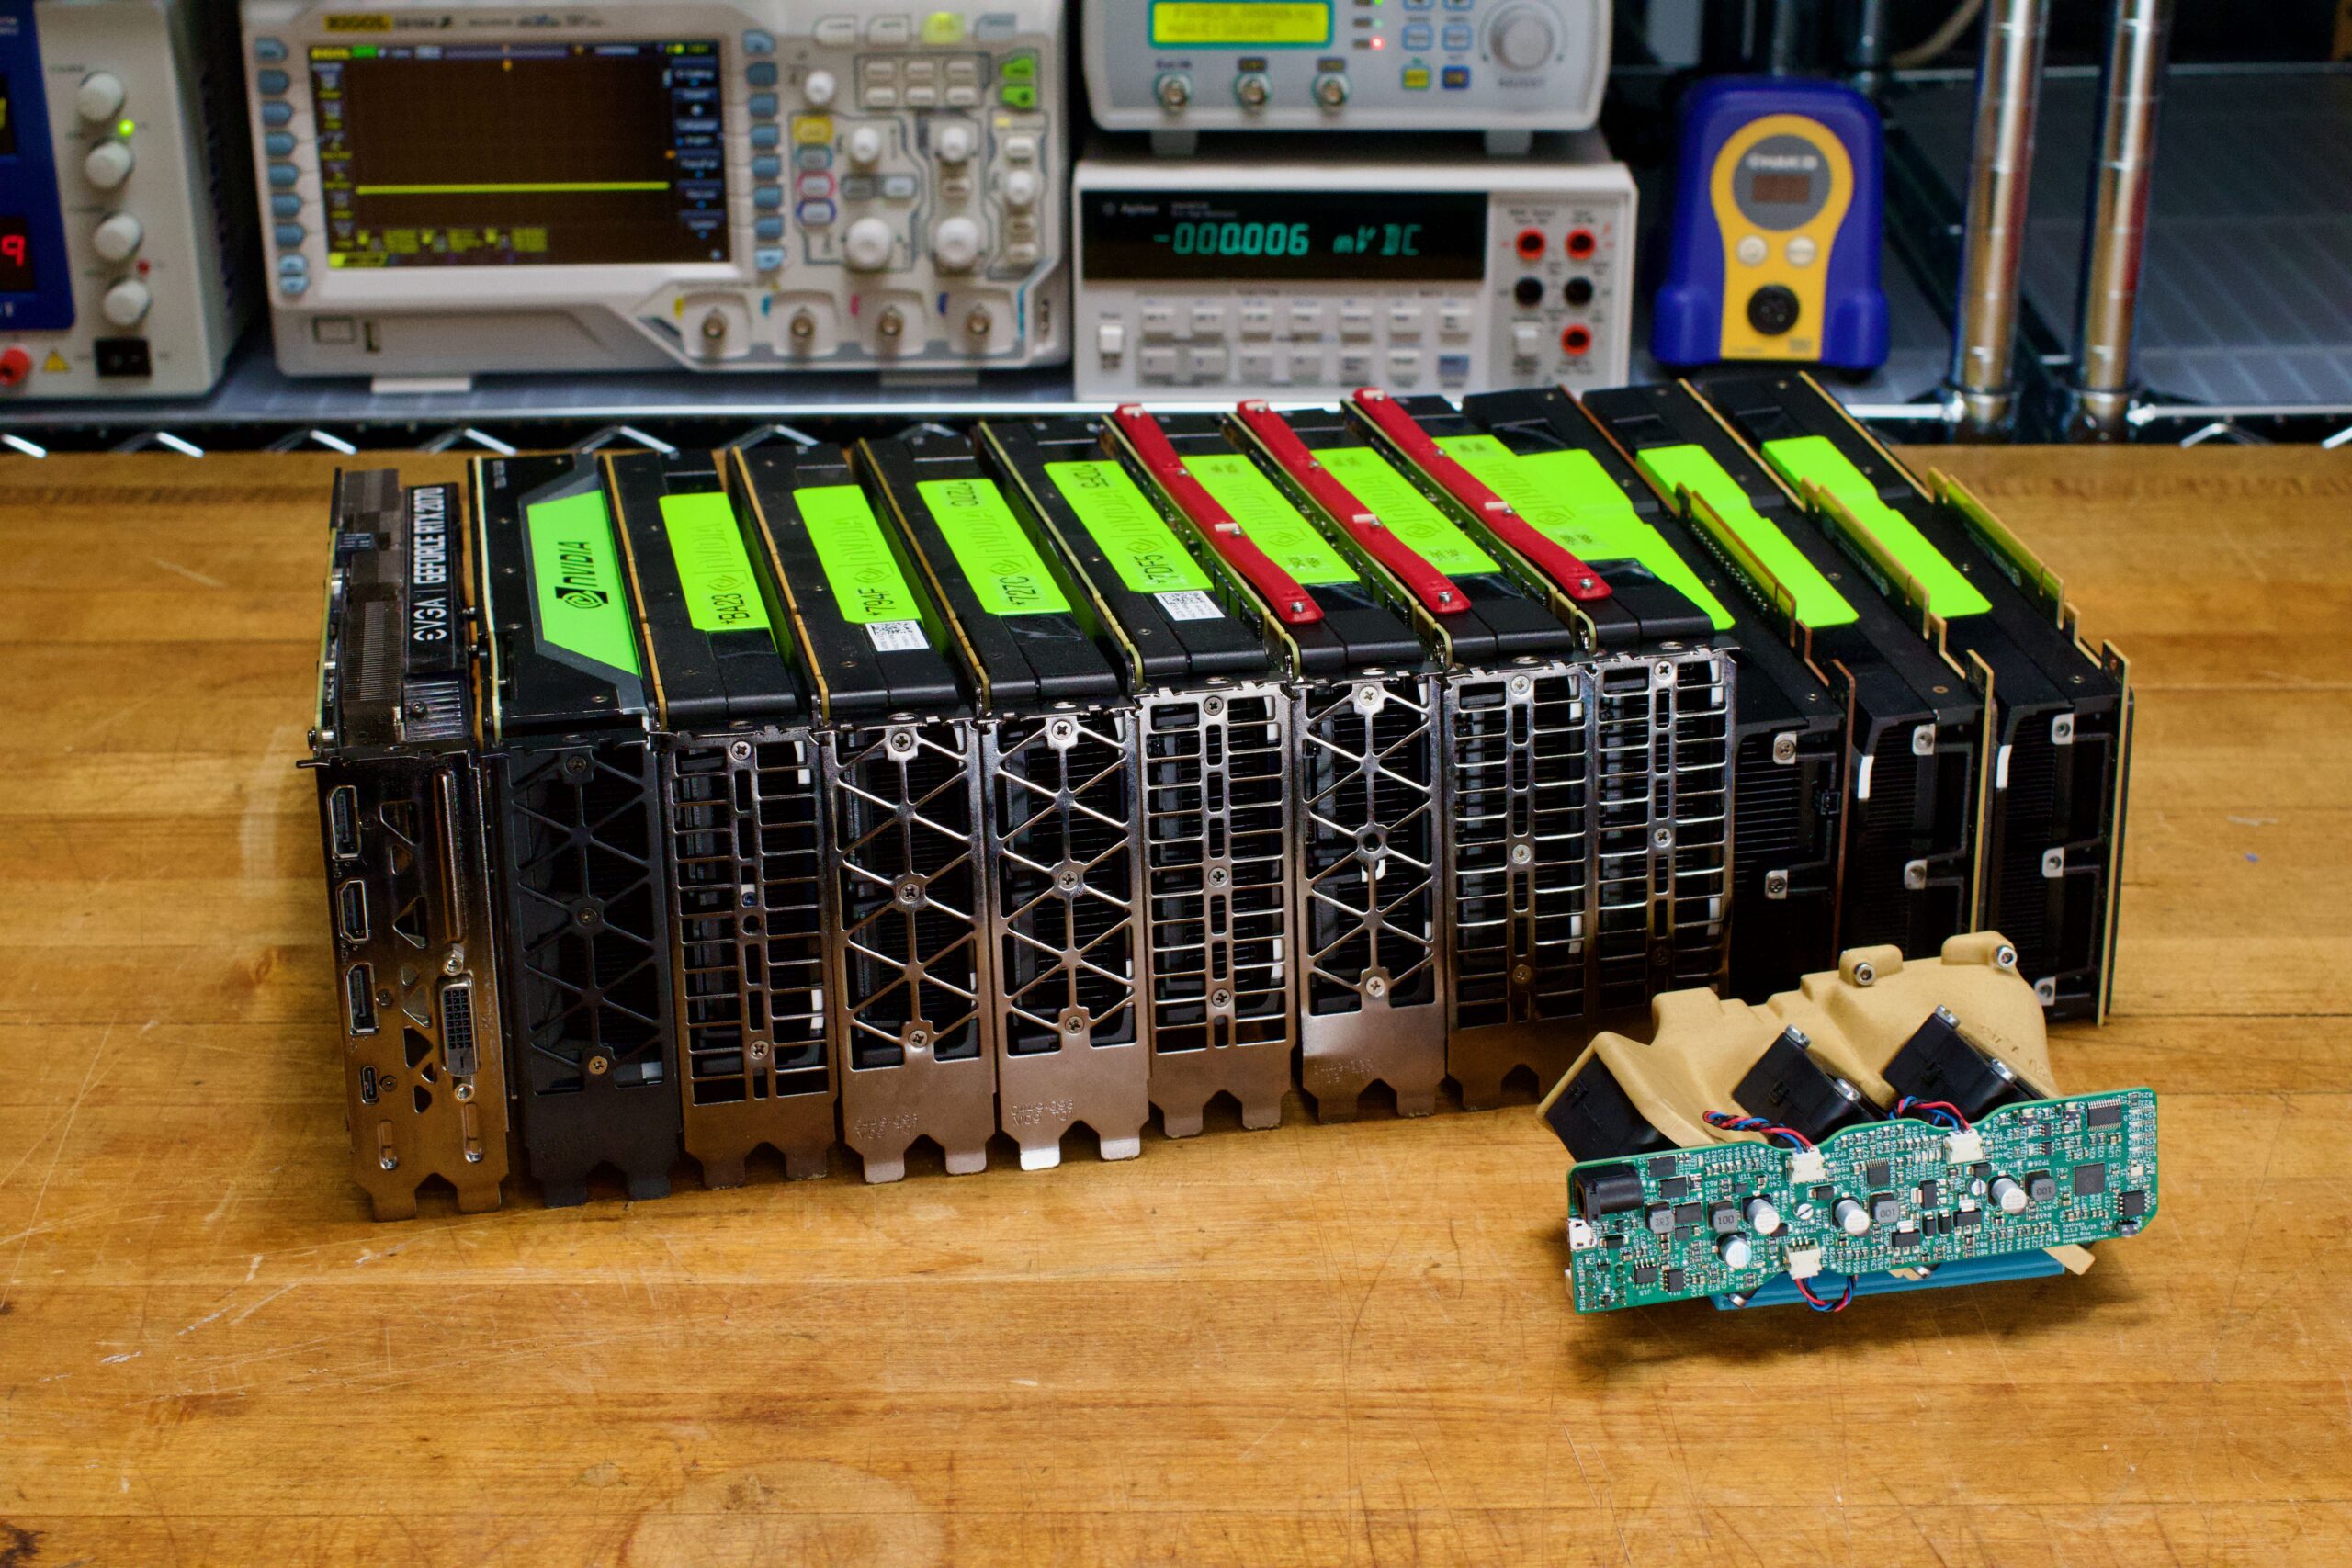
Benchmarking Tesla GPUs - esologic
Decommissioned enterprise tesla GPUs are widely available and extremely cheap. In this post, I benchmark tesla GPUs to see if they are useful
The Big LLM Architecture Comparison
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
François Chollet on Twitter / X
Quick reminder of what's ok vs not ok with harnesses used for playing ARC-AGI-3:1. Not okay: harnesses that were custom-made to solve the benchmark or that contain knowledge about the benchmark format / contents.2. Fine: general-purpose API settings that were not developed…— François Chollet (@fchollet) July 30, 2026
Best LLM for Coding 2026 | AI Coding Model Rankings & Benchmarks
Which AI model writes the best code? We rank every major LLM — open and closed source — across SWE-bench, HumanEval, LiveCodeBench, and Terminal-Bench coding benchmarks. Compare the best LLMs for coding, software engineering, and programming.

Wolfram LLM Benchmarking Project
Results from Wolfram's ongoing tracking of LLM performance. The benchmark is based on a Wolfram Language code generation task.
H100 PCIe vs SXM vs NVL: Which H100 GPU Is Fastest and Most Cost-Effective for Fine-Tuning LLMs?
Benchmarking all three H100 variants for full, LoRA, and QLoRA fine-tuning
Cross-Harness Agentic Memory
Supermemory built a ~99% benchmark ensemble to prove the benchmarks are gameable.Letta scored 74% on LoCoMo with just a filesystem. No vector DB, no graph.
SemiAnalysisAI/InferenceX
Open Source Continuous Inference Benchmark Research Platform — Kimi K3 2.8T, MiniMax M3, DeepSeekv4, GLM5 - GB200 NVL72 vs MI355X vs B200 vs GB300 NVL72 & soon™ TPUv6e/v7/Trainium2/3 | 开源持续推理基准研究平台 — Kimi K2.7-Code、MiniMax M3、DeepSeekv4、GLM5 - GB200 NVL72 vs MI355X vs B200 vs GB300 NVL72,即将推出™ TPUv6e/v7/Trainium2/3
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
Alex Cheema on Twitter / X
This is why we need open benchmarks for local AI.Otherwise it turns into tribalism and name calling.We will be publishing the largest database of open benchmarks for local AI, tested on 1,000+ real hardware setups. Every device, every interconnect, different… https://t.co/ZsU3PCdSsZ— Alex Cheema (@alexocheema) March 9, 2026
InferenceMAX™: Open Source Inference Benchmarking
NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B