

A TurboQuant inference server
Overview - GroqDocs
Fast LLM inference, OpenAI-compatible. Simple to integrate, easy to scale. Start building in minutes.
ggml
AI inference at the edge. ggml has 22 repositories available. Follow their code on GitHub.

Planetary-Scale Inference: Building a Distributed Inference Engine for the Public Internet
We are excited to share a preview of our distributed inference stack — engineered for consumer GPUs and the 100ms latencies of the public internet—plus a research roadmap that scales it into a planetary-scale inference engine.

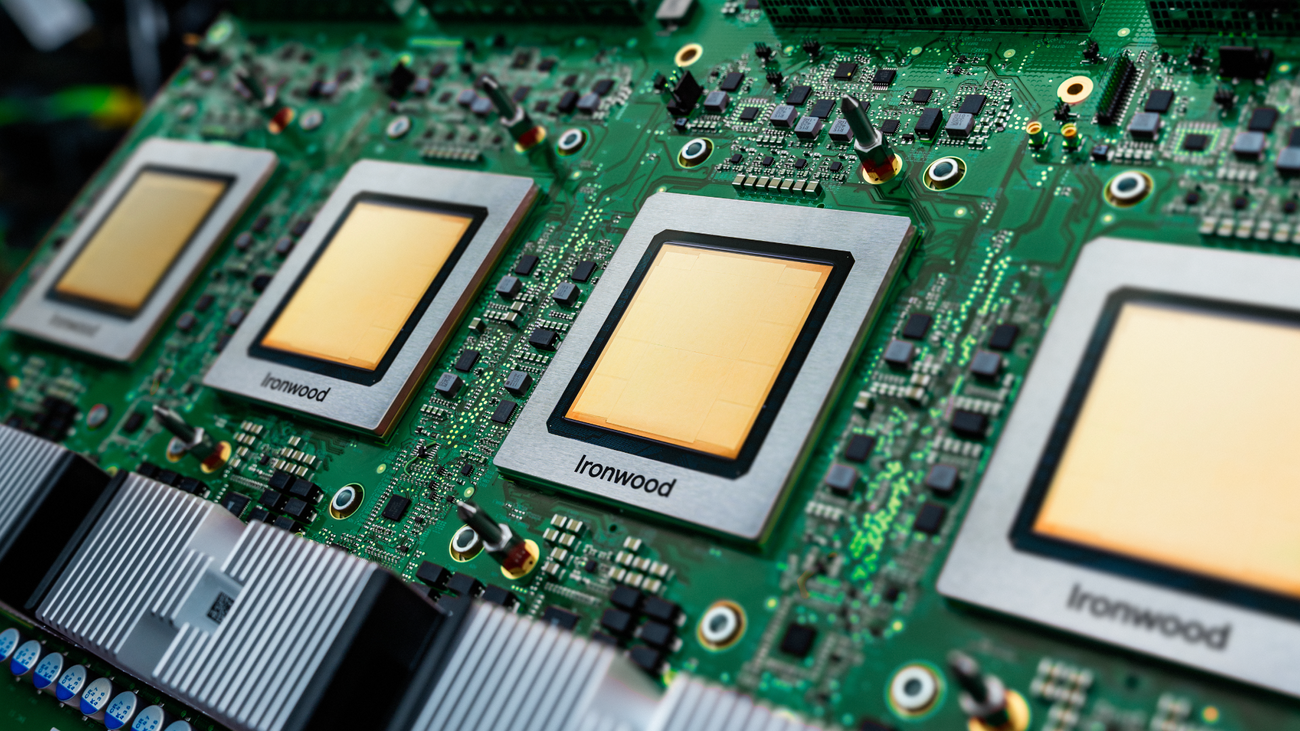
Ironwood: The first Google TPU for the age of inference
We’re introducing Ironwood, our seventh-generation Tensor Processing Unit (TPU) designed to power the age of generative AI inference.
Datacurve | The data engine for frontier AI
Custom data for long-horizon reasoning, software engineering, and data science.
SambaNova | The Fastest AI Inference Platform
Discover SambaNova - the complete AI platform delivering the fastest AI inference, fine-tuning, and scalable solutions for agentic AI easily integrated into existing data center infrastructures.
AI-Efficiency/Awesome-Model-Quantization
A curated collection of papers, benchmarks, surveys, and tools for model quantization, covering low-bit networks, LLMs, multimodal and generative models, vector and lattice quantization, and efficient deployment.
Introduction - How to Write an Inference Engine
A zero-to-hero guide to Muse Glimmer on Apple Metal, kvpack, and disaggregated NVFP4 prefill.
TurboQuant: Redefining AI efficiency with extreme compression
Amir Zandieh, Research Scientist, and Vahab Mirrokni, VP and Google Fellow, Google Research
