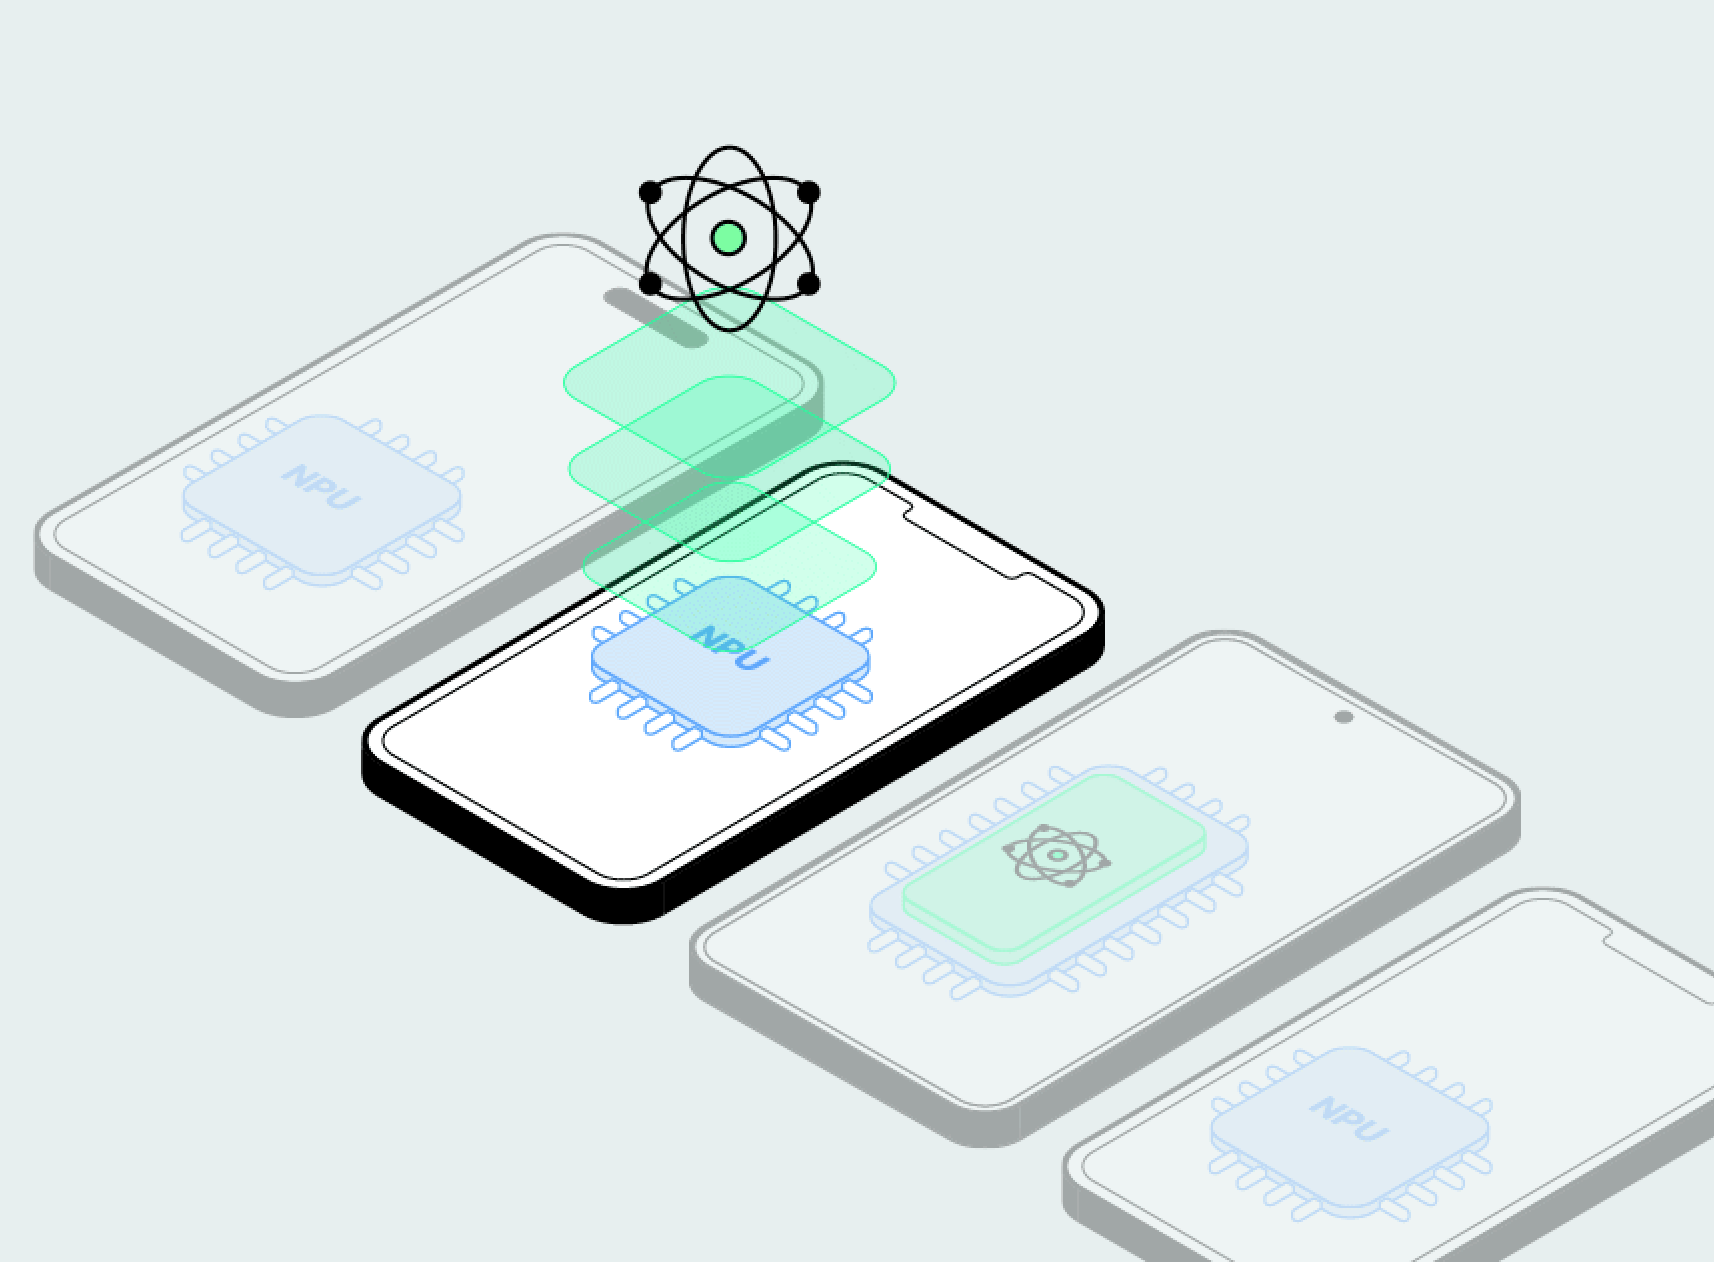
LiteRT, successor to TensorFlow Lite. is Google's On-device framework for high-performance ML & GenAI deployment on edge platforms, via efficient conversion, runtime, and optimization
Google for Developers Blog - News about Web, Mobile, AI and Cloud
LiteRT is the universal framework for on-device AI. The production stack delivers 1.4x faster cross-platform GPU performance, streamlined NPU acceleration, and superior GenAI support for open models like Gemma.

google-ai-edge/gallery
A gallery that showcases on-device ML/GenAI use cases and allows people to try and use models locally.
Google AI Edge Gallery | Google for Developers
Together AI | The AI Native Cloud
Build what's next on the AI Native Cloud. Full-stack AI platform for inference, fine-tuning, and GPU clusters — powered by cutting-edge research.
Bringing Edge AI to the Raspberry Pi GPU | Igalia
Igalia is an open source consulting firm specialised in the development of innovative projects and solutions. Our engineers have expertise in a wide range of technological areas, including browsers and client-side web technologies, graphics pipeline, compilers and virtual machines. We have the most WPE, WebKit, Chromium/Blink and Firefox expertise found in the consulting business, including many reviewers and committers. Igalia designs, develops, customises and optimises GNU/Linux-based solutions for companies across the globe. Our work and contributions are present in many projects such as GStreamer, Mesa 3D, WebKit, Chromium, etc.
generative-ai/gemini/agents/always-on-memory-agent at main · GoogleCloudPlatform/generative-ai
Sample code and notebooks for Generative AI on Google Cloud, with Gemini Enterprise Agent Platform - GoogleCloudPlatform/generative-ai
Lilypad-Tech/lilypad
Run AI workloads easily in a decentralized GPU network. https://www.youtube.com/watch?v=yQnB2Yxia4Y
Introducing LFM2: The Fastest On-Device Foundation Models on the Market | Liquid AI
Today, we release LFM2, a new class of Liquid Foundation Models (LFMs) that sets a new standard in quality, speed, and memory efficiency for on-device deployment. Built on a hybrid architecture, LFM2 delivers 200% faster decode and prefill performance than Qwen3 and Gemma 3 on CPU. It also significantly outperforms models in each size class on instruction-following and function calling—the core capabilities that make LLMs reliable for building AI agents.

On-device intelligence for every product
We're building a frontier lab for on-device AI. Small, specialized models for audio, vision, and text, faster than the cloud and free.
Liquid AI — Device-native foundation models.
Liquid AI is an efficiency-first foundation model company. We build highly capable, compute-optimized models that bring intelligence to any device and medium of choice.
AI gateway capabilities | Apigee | Google Cloud Documentation
Learn how to use Apigee AI gateway features to govern, optimize, and scale AI traffic.

raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
Mesh LLM: distributed AI computing on iroh
How Mesh LLM pools existing GPU resources across machines into a single OpenAI-compatible API, built on iroh.
Melange | On-device AI for Mobile
Select. Benchmark. Deploy | End-to-end on-device AI deployment tool for mobile devs.