

Optimal Transport for Machine Learners
Computational OT #4 - Gradient flow and diffusion models
A course on computational Optimal Transport

Optimal and Diffusion Transports in Machine Learning
Slides for a general introduction to the use of Optimal Transport methods in learning, with an emphasis on diffusion models, flow matching, training 2 l…

Modern GPU Programming For MLSys — Modern GPU Programming For MLSys
Machine learning systems sit at the heart of modern AI workloads. In these systems, performance often comes down to the quality of a small number of GPU kernels. Attention kernels, LLM prefill and decode kernels, low-precision block-scaled GEMMs, fused MoE layers, and other large fused kernels all directly shape end-to-end speed in both training and serving.
Introducing GPT-5.4
Introducing GPT-5.4, OpenAI’s most most capable and efficient frontier model for professional work, with state-of-the-art coding, computer use, tool search, and 1M-token context.
Home - Gpytoolbox
Authors: Silvia Sellán, Columbia University and Oded Stein, University of Southern California
Lightweight Guide to understanding GRPO and RL principles
A beginner-friendly guide to Group Relative Policy Optimization (GRPO) training workflow without assuming prior RL knowledge.

huggingface/ml-intern
🤗 ml-intern: an open-source ML engineer that reads papers, trains models, and ships ML models
karpathy/minGPT
A minimal PyTorch re-implementation of the OpenAI GPT (Generative Pretrained Transformer) training
Everything I Learned Training Frontier Small Models — Maxime Labonne, Liquid AI
Everything I Learned Training Frontier Small Models — Maxime Labonne, Liquid AI
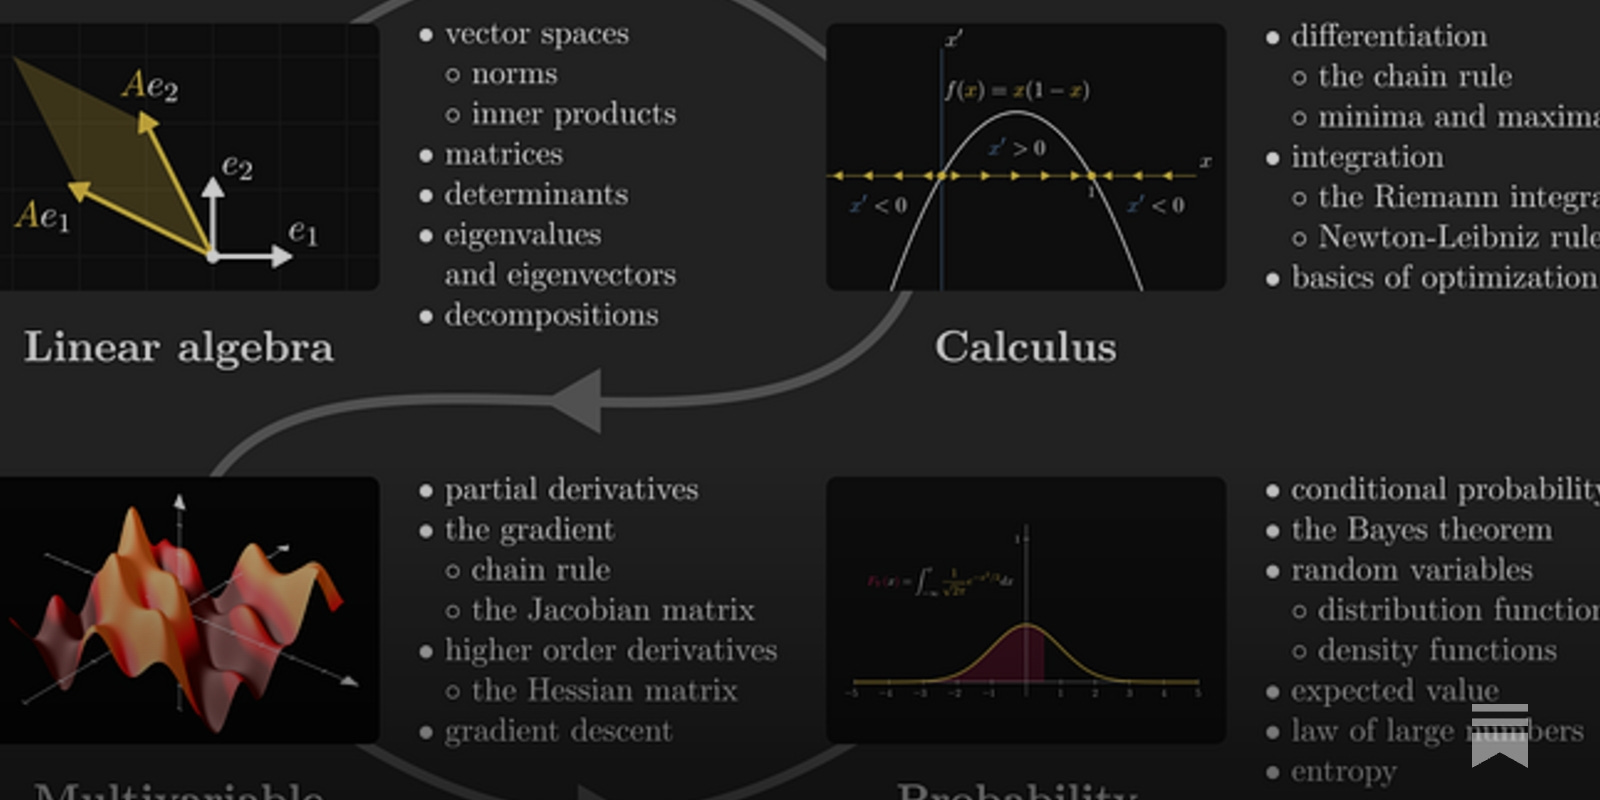
The Roadmap of Mathematics for Machine Learning
A complete guide to linear algebra, calculus, and probability theory
Context Rot: How Increasing Input Tokens Impacts LLM Performance
Large Language Models (LLMs) are typically presumed to process context uniformly—that is, the model should handle the 10,000th token just as reliably as the 100th. However, in practice, this assumption does not hold. We observe that model performance varies significantly as input length changes, even on simple tasks. In this report, we evaluate 18 LLMs, including the state-of-the-art GPT-4.1, Claude 4, Gemini 2.5, and Qwen3 models. Our results reveal that models do not use their context uniformly; instead, their performance grows increasingly unreliable as input length grows.
Readwise MCP Server - Readwise Docs
The Model Context Protocol (MCP) standardizes how applications provide context to Large Language Models (LLMs). The Readwise MCP was created to act as a...