

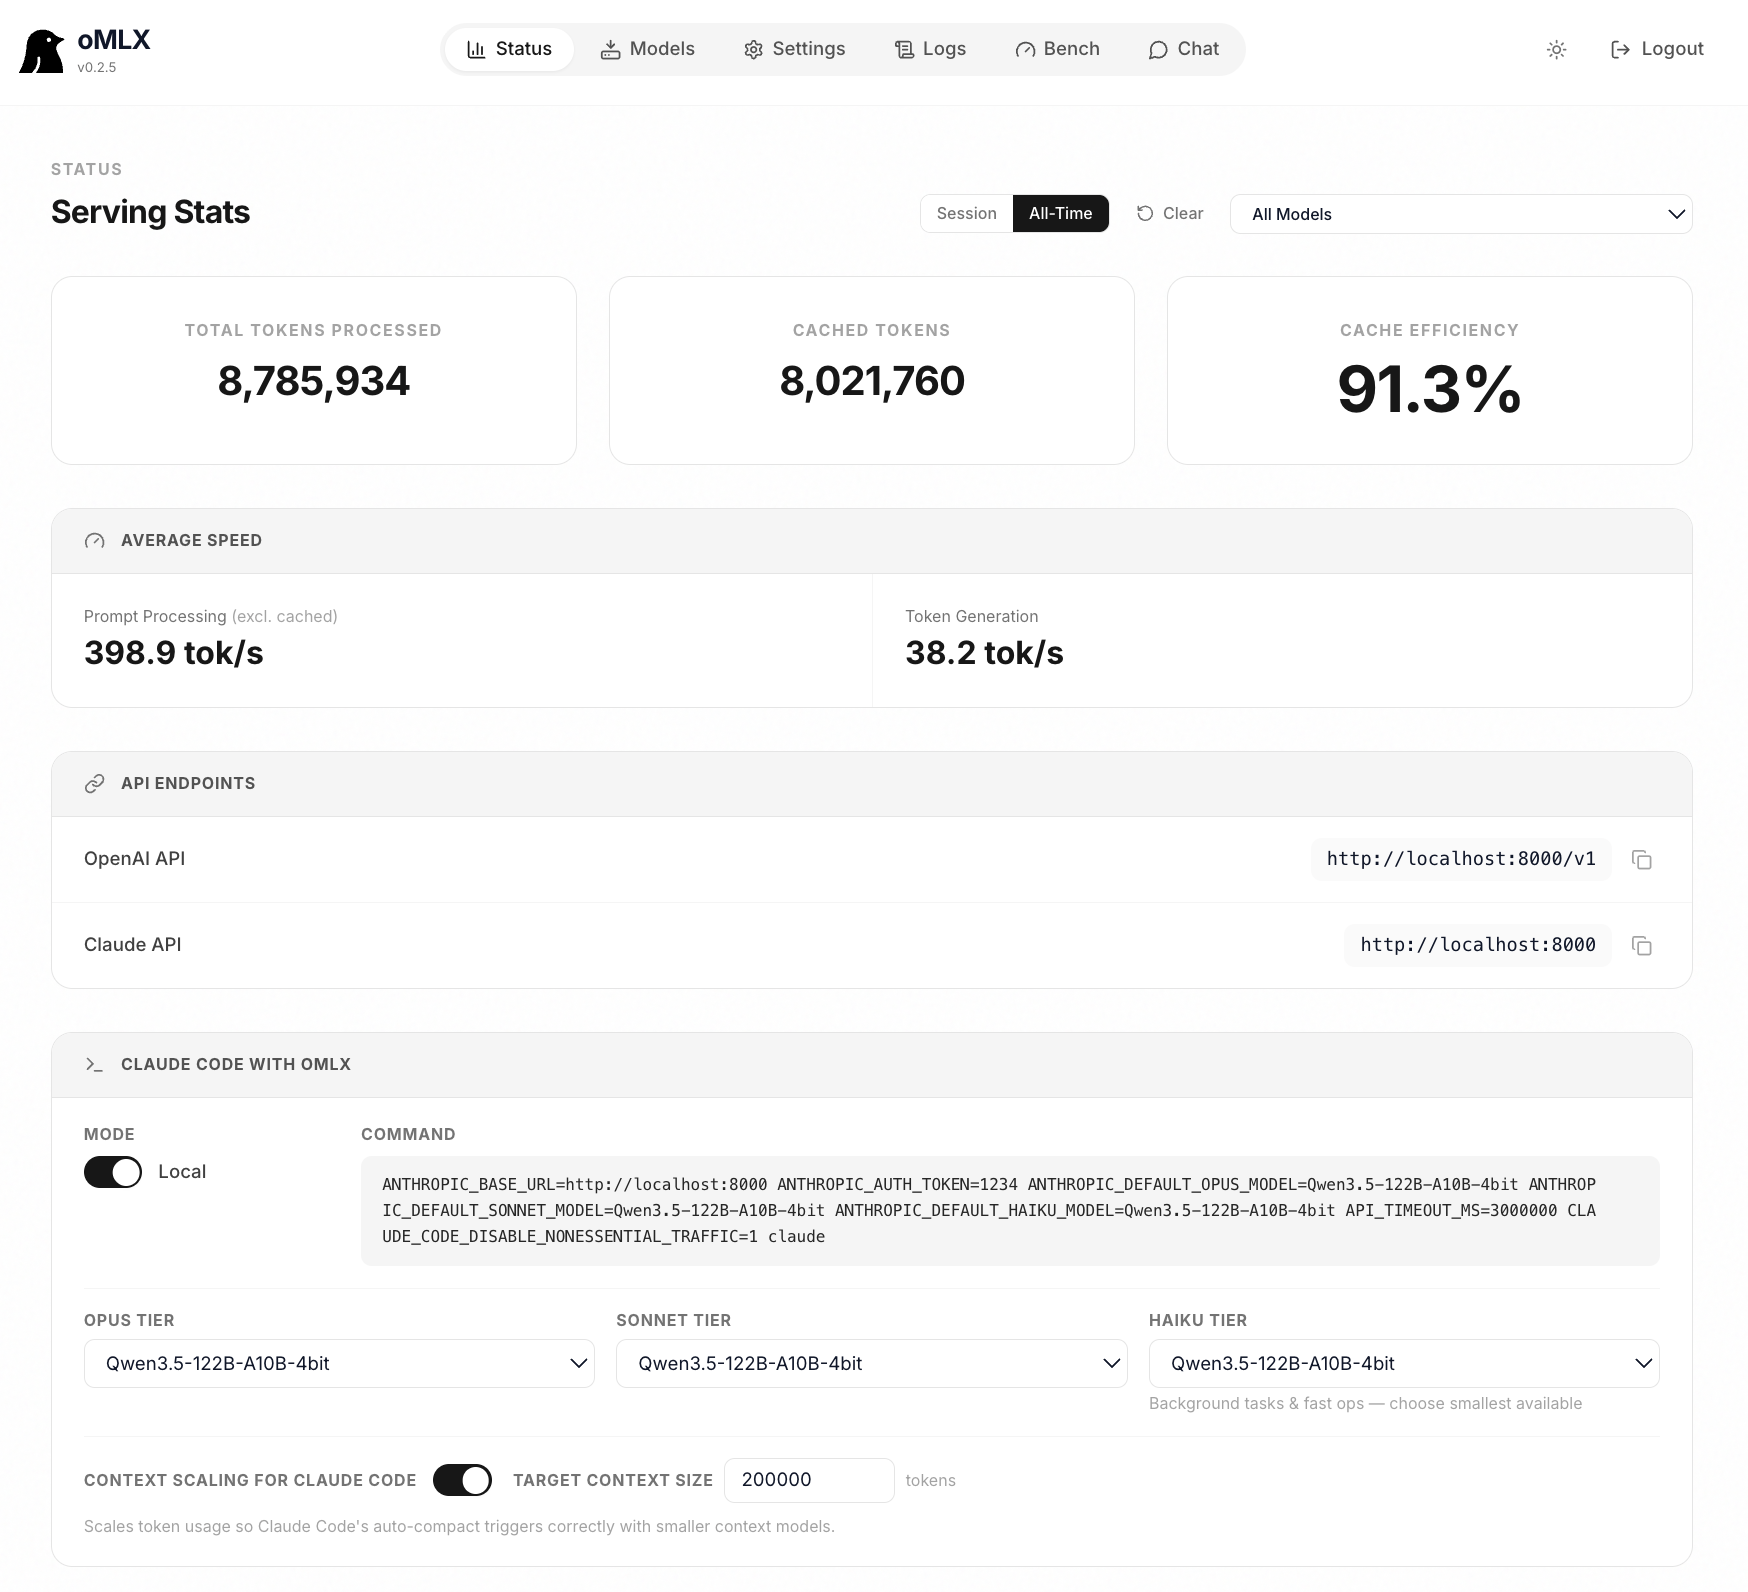
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
omlx/docs/oQ_Quantization.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
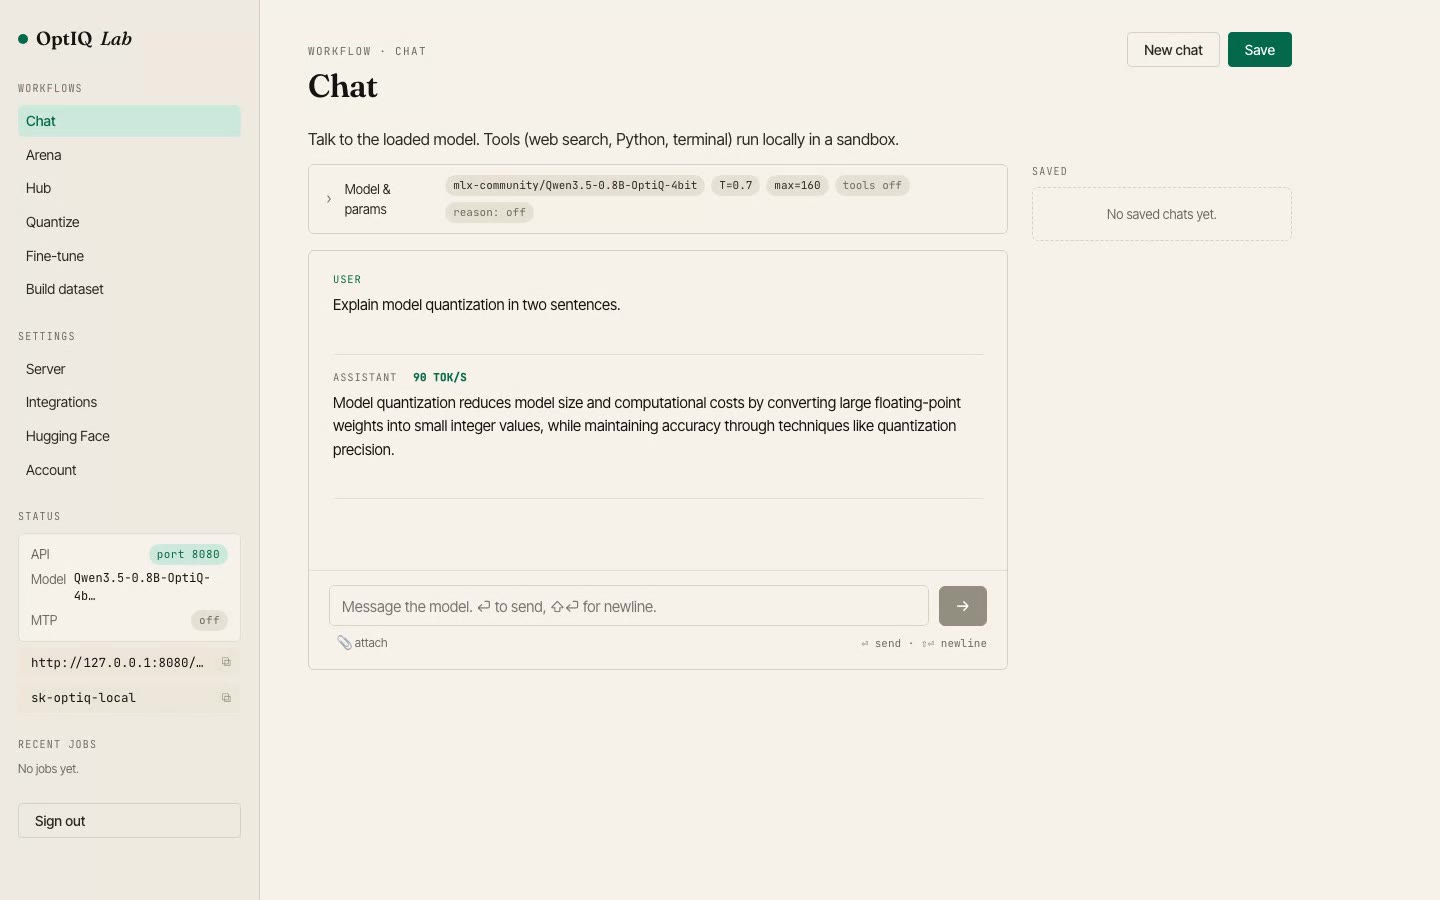
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
Rohan Paul on Twitter / X
👨🔧 Github: Native, Apple Silicon–only local LLM server. Similar to Ollama, but built on Apple's MLX- OpenAI API compatible, - Ollama‑compatible- OpenAI‑style tools + tool_choice, with tool_calls parsing and streaming deltasgithub. com/dinoki-ai/osaurus pic.twitter.com/G0NbWnEJcQ— Rohan Paul (@rohanpaul_ai) September 3, 2025

mzau/broke-cluster
A Poor Man's Apple Silicon LLM Cluster — tuned for MLX, scalable without shame.
Doriandarko/MLX-GRPO
A pure MLX-based training pipeline for fine-tuning LLMs using GRPO on Apple Silicon.
Ollama is now powered by MLX on Apple Silicon in preview· Ollama Blog
Today, we're previewing the fastest way to run Ollama on Apple silicon, powered by MLX, Apple's machine learning framework.
Combining NVIDIA DGX Spark + Apple Mac Studio for 4x Faster LLM Inference with EXO 1.0
Disaggregating Prefill and Decode: Faster First Tokens, Faster Streams
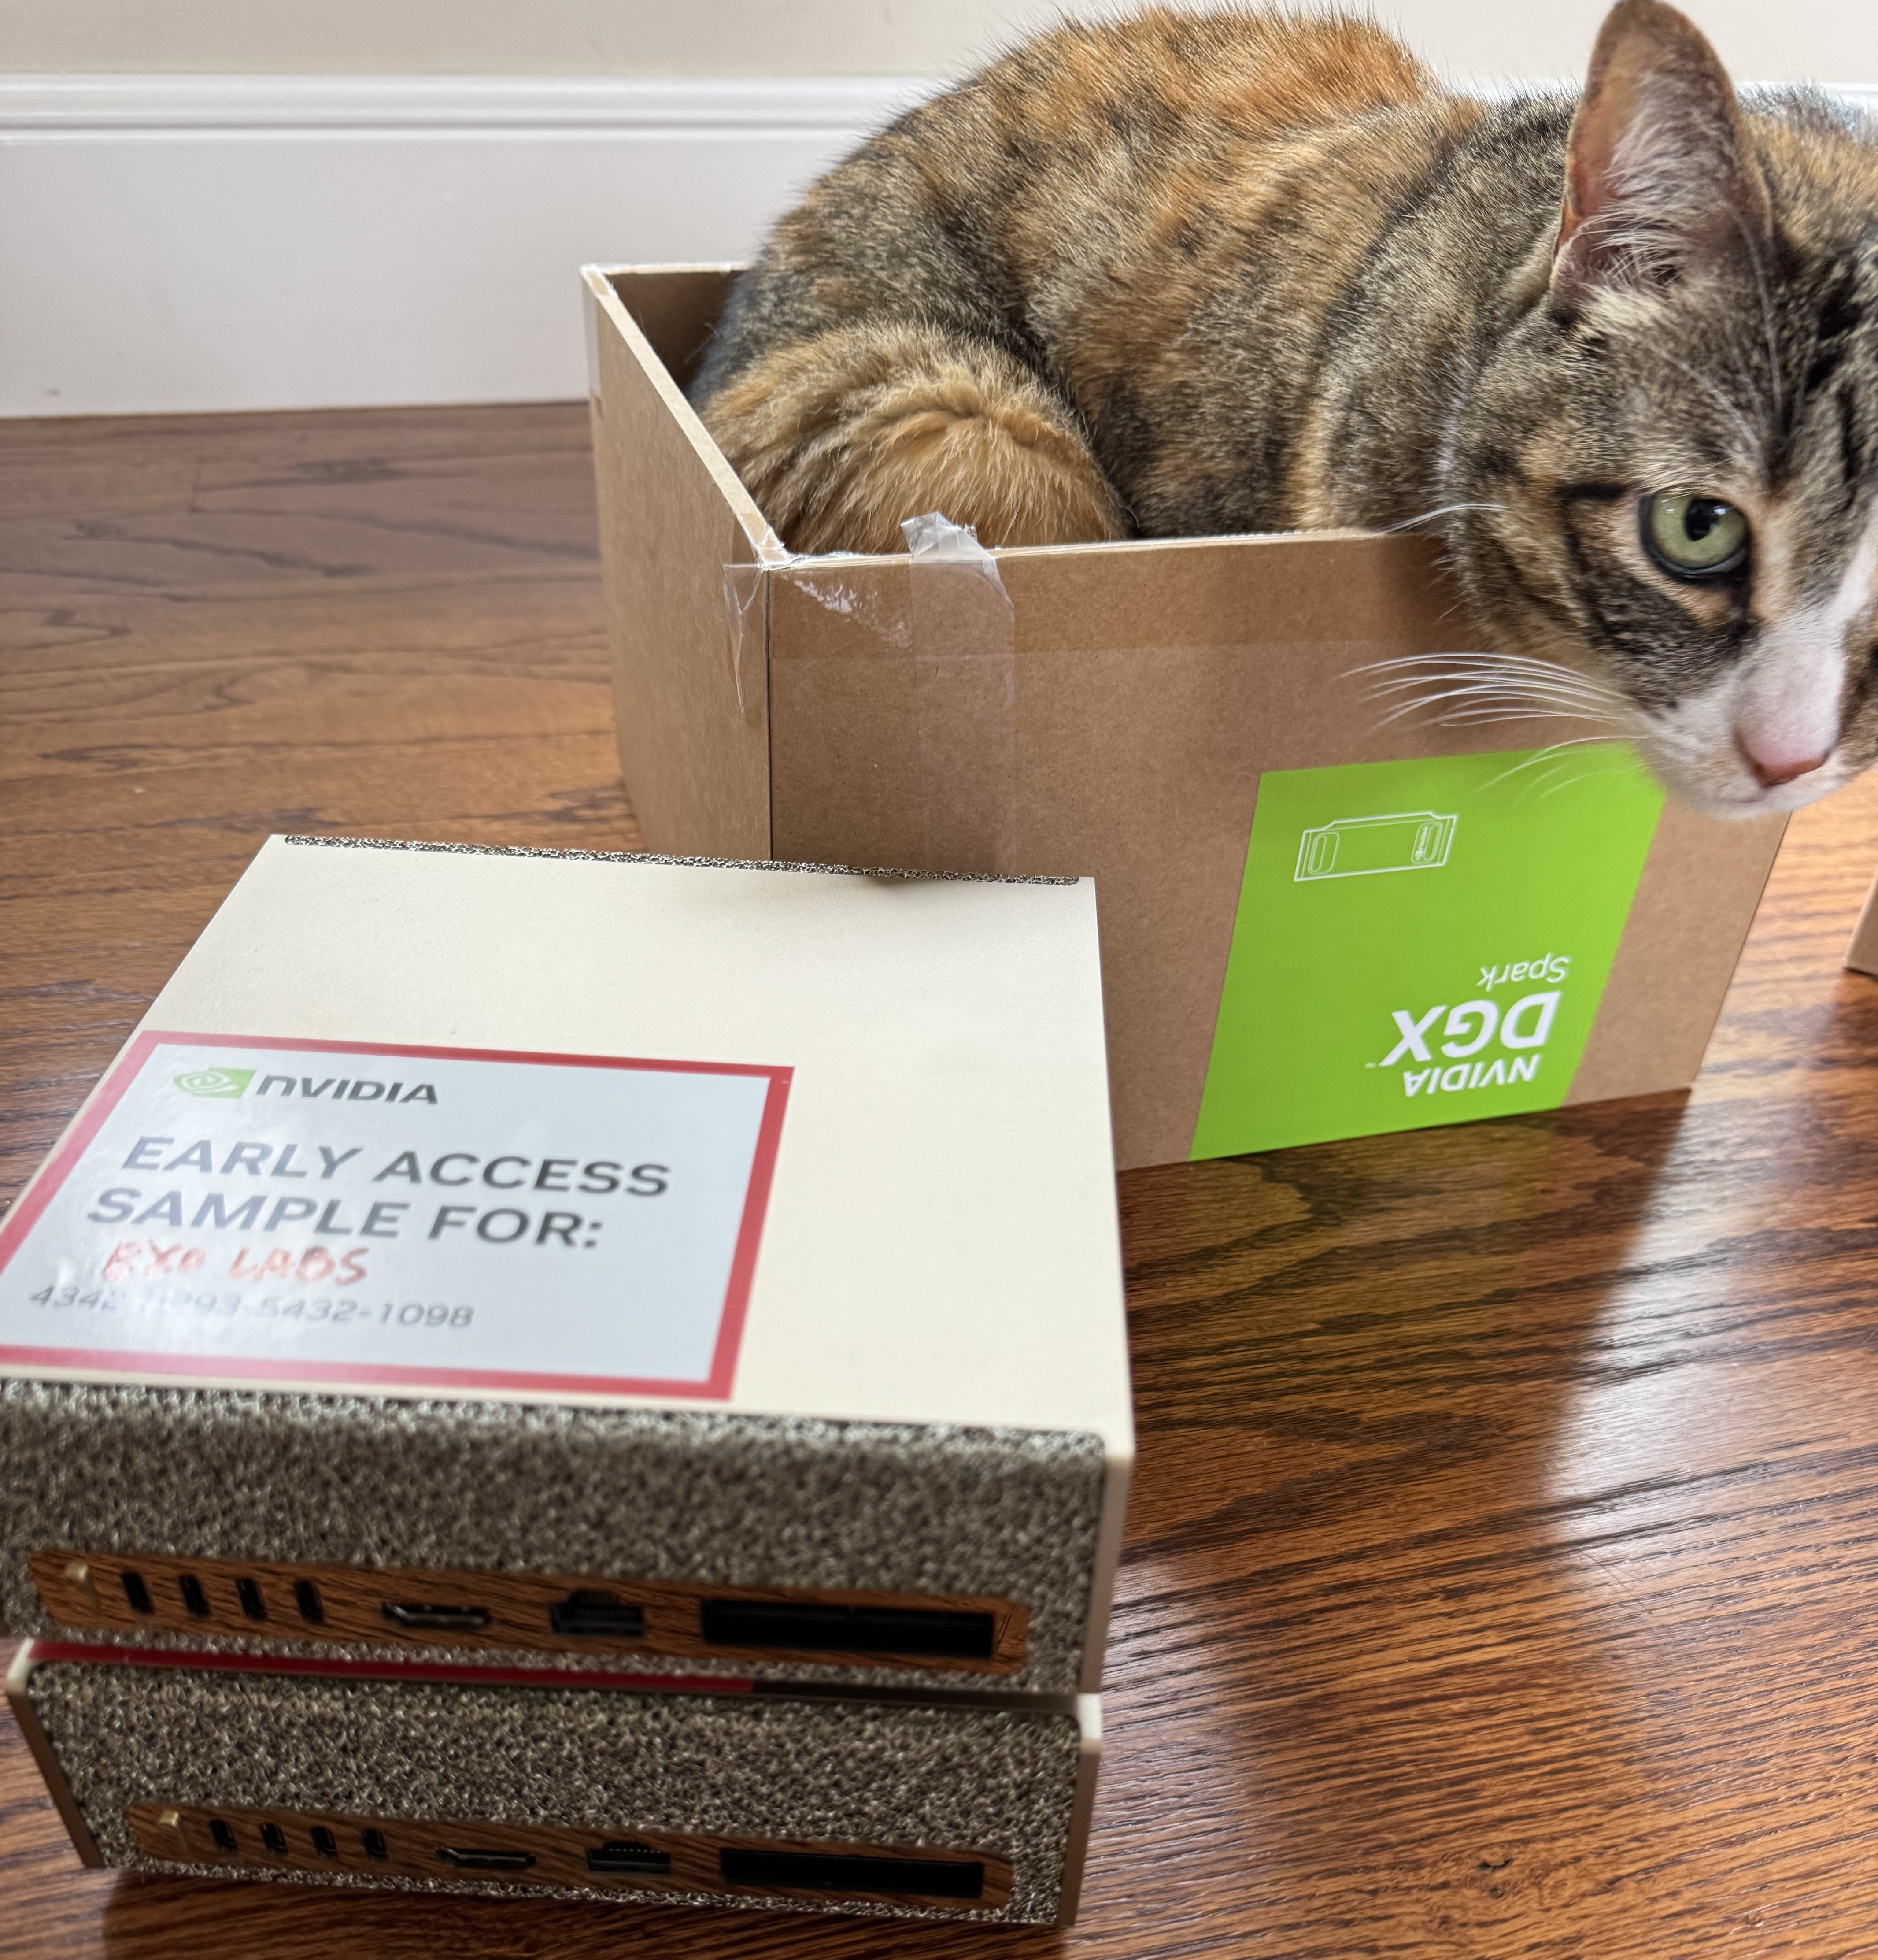
Combining NVIDIA DGX Spark + Apple Mac Studio for 4x Faster LLM Inference with EXO 1.0
Disaggregating Prefill and Decode: Faster First Tokens, Faster Streams
ARahim3/mlx-tune
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.
ARahim3/mlx-tune
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.