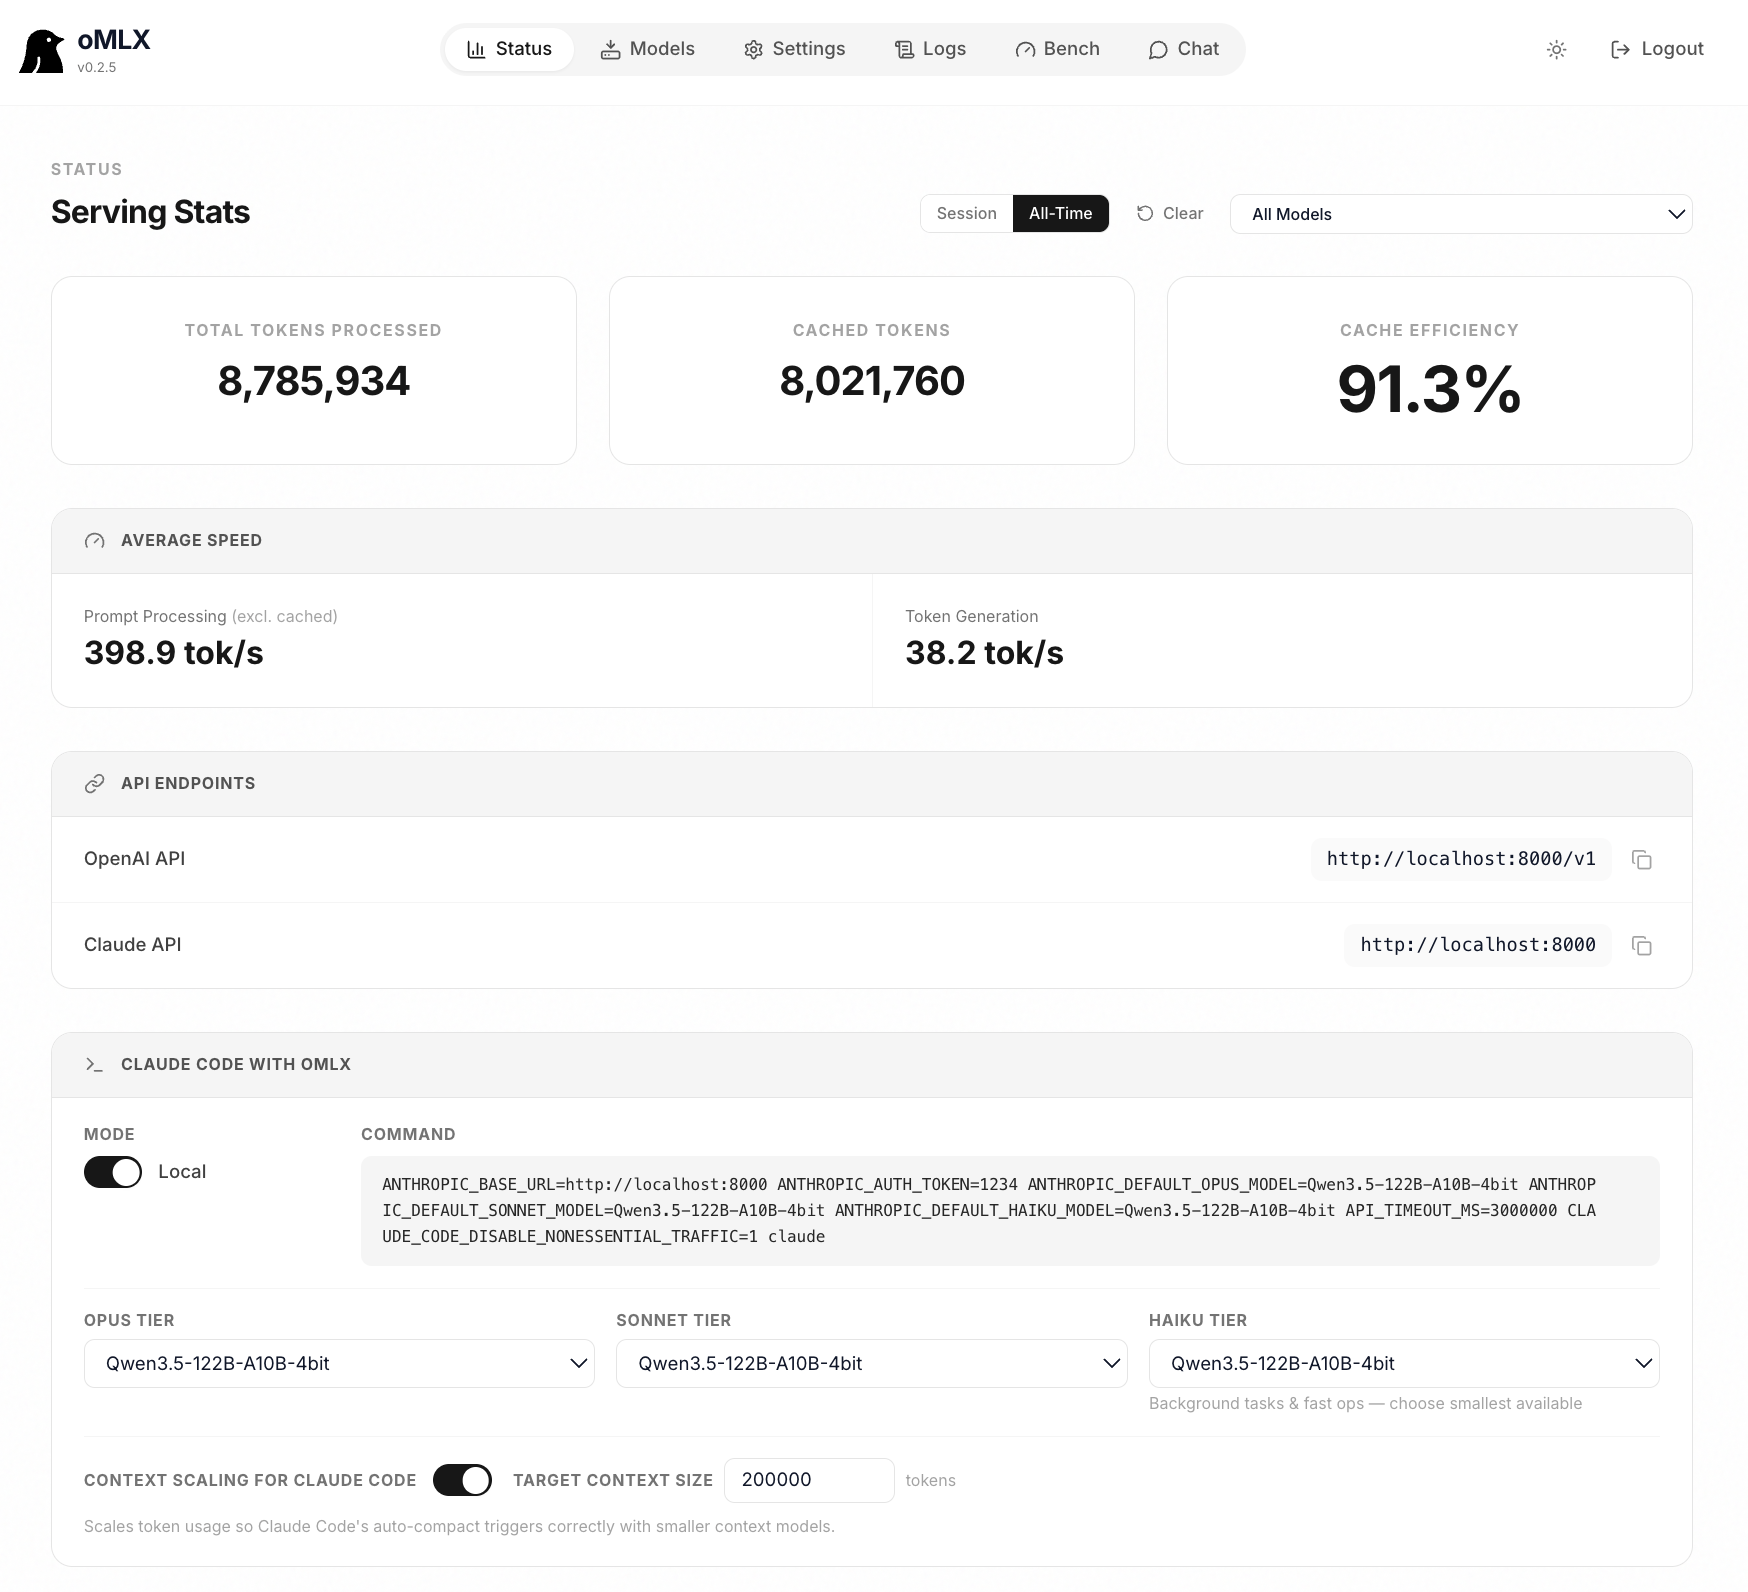
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
omlx/docs/experimental/dflash_mlx_integration.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
Rohan Paul on Twitter / X
👨🔧 Github: Native, Apple Silicon–only local LLM server. Similar to Ollama, but built on Apple's MLX- OpenAI API compatible, - Ollama‑compatible- OpenAI‑style tools + tool_choice, with tool_calls parsing and streaming deltasgithub. com/dinoki-ai/osaurus pic.twitter.com/G0NbWnEJcQ— Rohan Paul (@rohanpaul_ai) September 3, 2025

A Visual Guide to Quantization
Exploring memory-efficient techniques for LLMs
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
Overview - GroqDocs
Fast LLM inference, OpenAI-compatible. Simple to integrate, easy to scale. Start building in minutes.
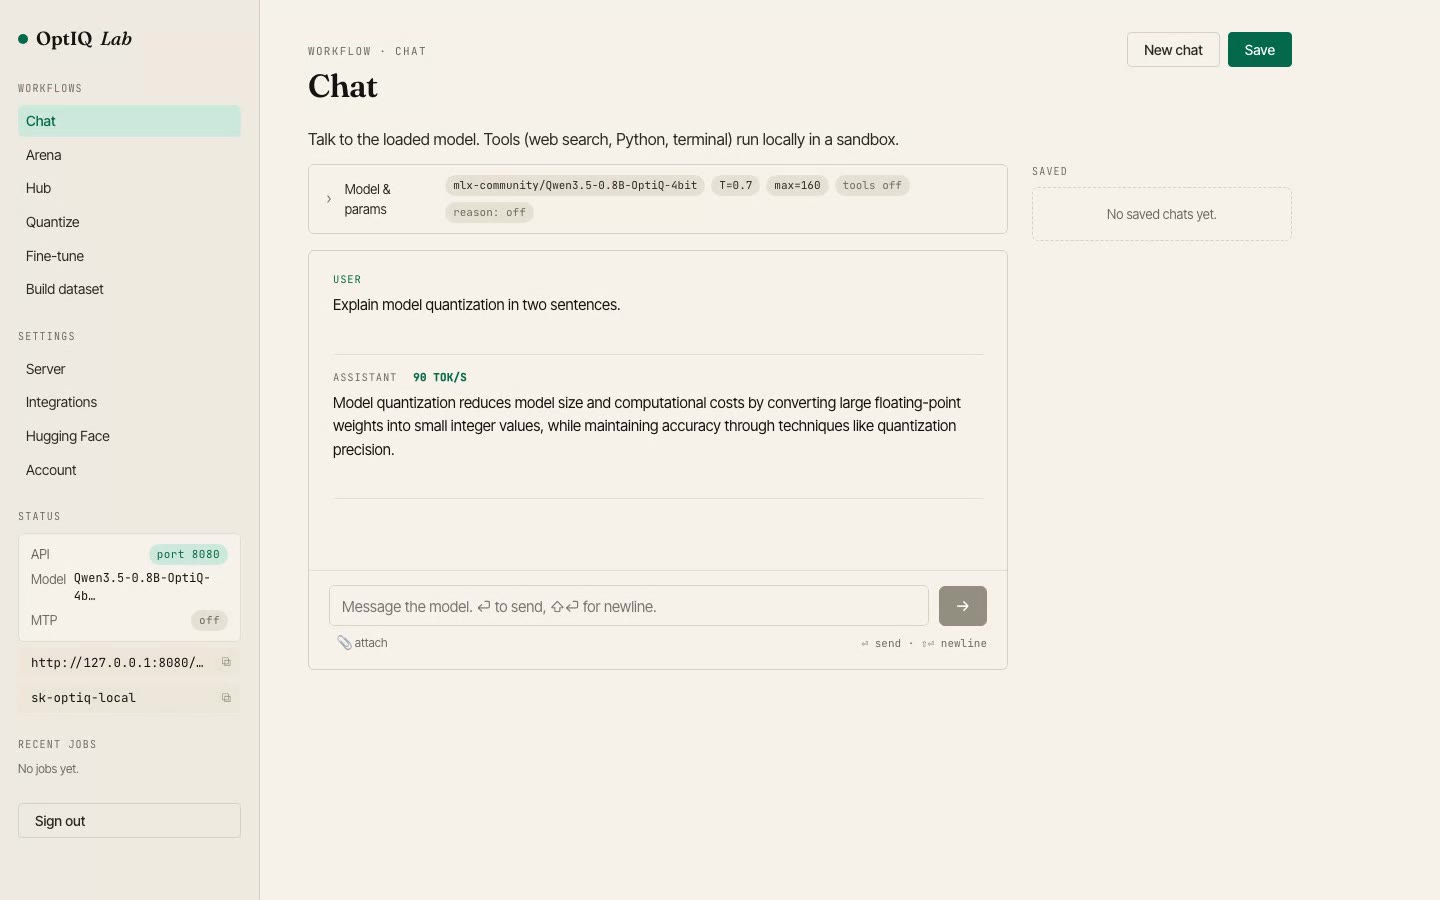
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
vllm-project/vllm
A high-throughput and memory-efficient inference and serving engine for LLMs
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
Artur Chakhvadze on Twitter / X
We are releasing our first quantized checkpoints for the Qwen3.5 series of models, co-designed jointly with our inference engine to achieve maximum possible performance on Apple hardwareStarting from 0.8B, 2B and 4B modelshttps://t.co/2R8BdhAfzv— Artur Chakhvadze (@norpadon) June 8, 2026
Alex Cheema on Twitter / X
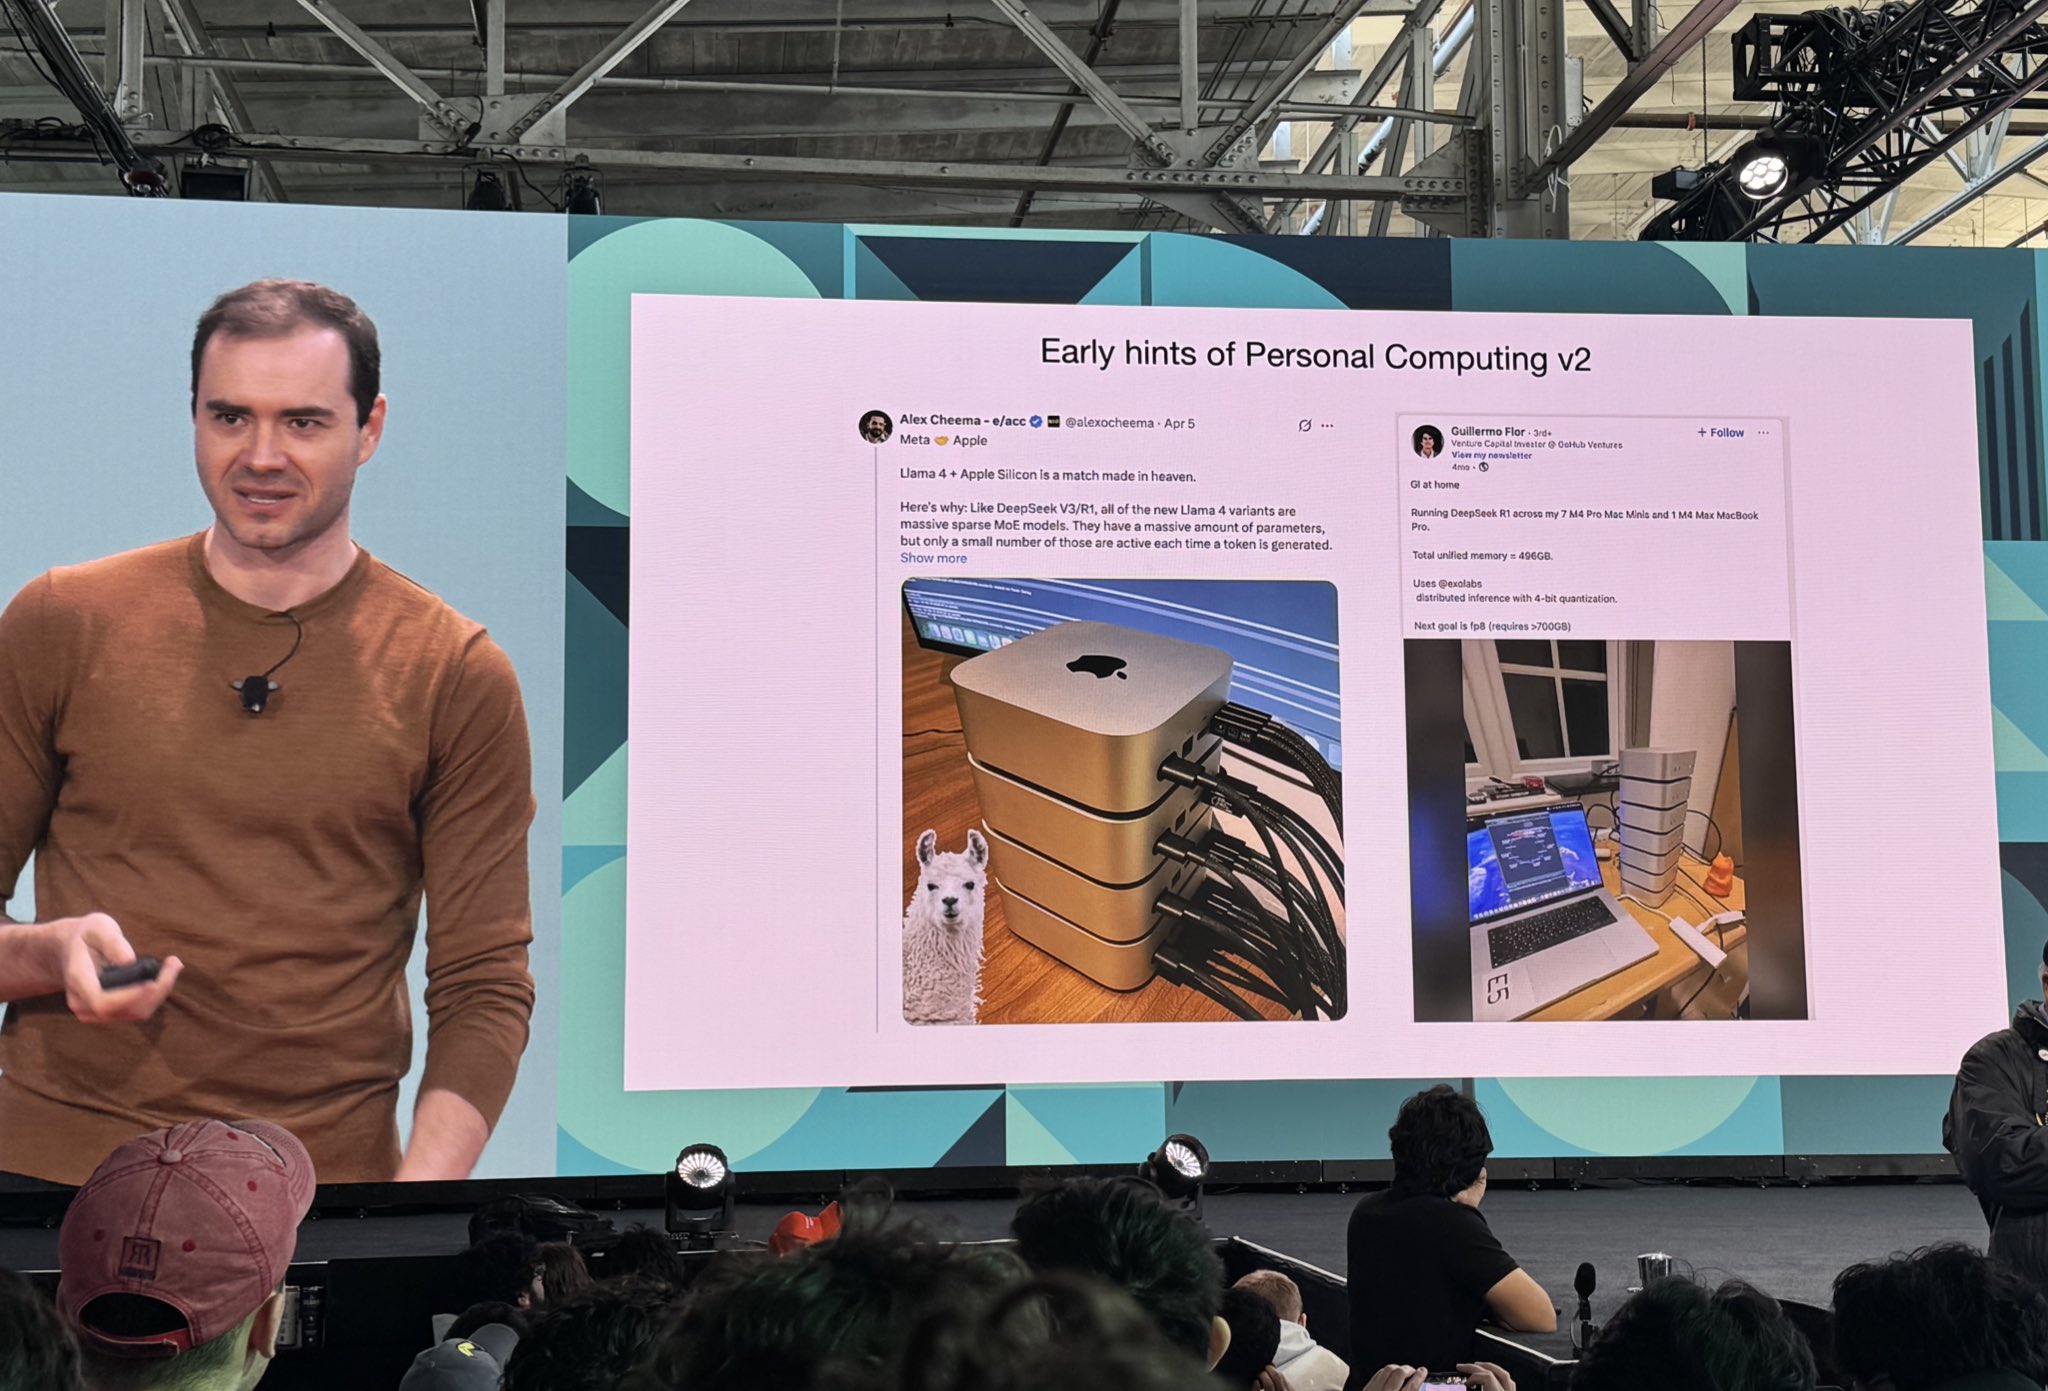
.@karpathy shouted out my work on @exolabs at @ycombinator AI SUS!“we use LLMs similarly to mainframes in the ‘70s - compute is timeshared by having a slice in the batch dimension. models will compress over time, and with this we’ll be able to run more on-device” pic.twitter.com/UKSrquQGAL— Alex Cheema (@alexocheema) June 18, 2025