

RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
As part of the Digital Library's transition to Open Access, new features for researchers are available in the Premium Edition. Click here to learn more.

RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
As part of the Digital Library's transition to Open Access, new features for researchers are available in the Premium Edition. Click here to learn more.
RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
Large Language Models (LLMs) hold significant potential for advancing fact-checking by leveraging their capabilities in reasoning, evidence retrieval, and explanation generation. However, existing benchmarks fail to comprehensively evaluate LLMs and Multimodal Large Language Models (MLLMs) in realistic misinformation scenarios. To bridge this gap, we introduce RealFactBench, a comprehensive benchmark designed to assess the fact-checking capabilities of LLMs and MLLMs across diverse real-world tasks, including Knowledge Validation, Rumor Detection, and Event Verification. RealFactBench consists of 6K high-quality claims drawn from authoritative sources, encompassing multimodal content and diverse domains. Our evaluation framework further introduces the Unknown Rate (UnR) metric, enabling a more nuanced assessment of models' ability to handle uncertainty and balance between over-conservatism and over-confidence. Extensive experiments on 7 representative LLMs and 4 MLLMs reveal their limitations in real-world fact-checking and offer valuable insights for further research. RealFactBench is publicly available at https://github.com/kalendsyang/RealFactBench.git.

RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
Large Language Models (LLMs) hold significant potential for advancing fact-checking by leveraging their capabilities in reasoning, evidence retrieval, and explanation generation. However, existing benchmarks fail to comprehensively evaluate LLMs and Multimodal Large Language Models (MLLMs) in realistic misinformation scenarios. To bridge this gap, we introduce RealFactBench, a comprehensive benchmark designed to assess the fact-checking capabilities of LLMs and MLLMs across diverse real-world tasks, including Knowledge Validation, Rumor Detection, and Event Verification. RealFactBench consists of 6K high-quality claims drawn from authoritative sources, encompassing multimodal content and diverse domains. Our evaluation framework further introduces the Unknown Rate (UnR) metric, enabling a more nuanced assessment of models' ability to handle uncertainty and balance between over-conservatism and over-confidence. Extensive experiments on 7 representative LLMs and 4 MLLMs reveal their limitations in real-world fact-checking and offer valuable insights for further research. RealFactBench is publicly available at https://github.com/kalendsyang/RealFactBench.git.
Large Language Models Require Curated Context for Reliable Political Fact-Checking—Even with Reasoning and Web Search
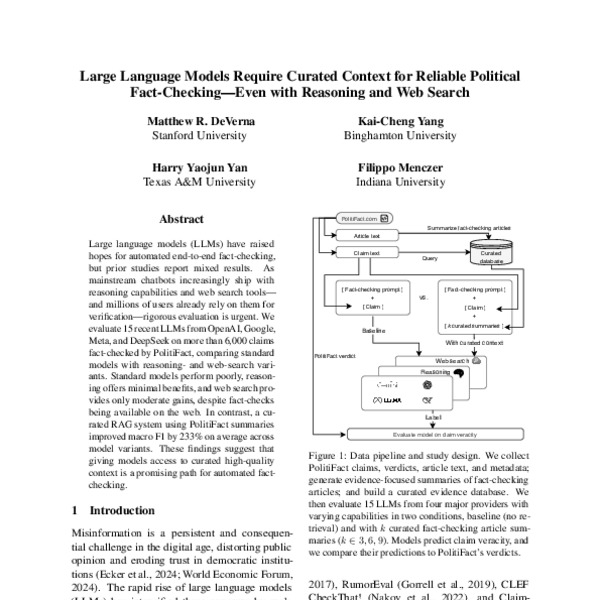
Large language models (LLMs) have raised hopes for automated end-to-end fact-checking, but prior studies report mixed results. As mainstream chatbots increasingly ship with reasoning capabilities and web search tools—and millions of users already rely on them for verification—rigorous evaluation is urgent. We evaluate 15 recent LLMs from OpenAI, Google, Meta, and DeepSeek on more than 6,000 claims fact-checked by PolitiFact, comparing standard models with reasoning- and web-search variants. Standard models perform poorly, reasoning offers minimal benefits, and web search provides only moderate gains, despite fact-checks being available on the web. In contrast, a curated RAG system using PolitiFact summaries improved macro F1 by 233% on average across model variants. These findings suggest that giving models access to curated high-quality context is a promising path for automated fact-checking.
Measuring short-form factuality in large language models
We present SimpleQA, a benchmark that evaluates the ability of language models to answer short, fact-seeking questions. We prioritized two properties in designing this eval. First, SimpleQA is challenging, as it is adversarially collected against GPT-4 responses. Second, responses are easy to grade, because questions are created such that there exists only a single, indisputable answer. Each answer in SimpleQA is graded as either correct, incorrect, or not attempted. A model with ideal behavior would get as many questions correct as possible while not attempting the questions for which it is not confident it knows the correct answer. SimpleQA is a simple, targeted evaluation for whether models "know what they know," and our hope is that this benchmark will remain relevant for the next few generations of frontier models. SimpleQA can be found at https://github.com/openai/simple-evals.
Measuring short-form factuality in large language models
We present SimpleQA, a benchmark that evaluates the ability of language models to answer short, fact-seeking questions. We prioritized two properties in designing this eval. First, SimpleQA is challenging, as it is adversarially collected against GPT-4 responses. Second, responses are easy to grade, because questions are created such that there exists only a single, indisputable answer. Each answer in SimpleQA is graded as either correct, incorrect, or not attempted. A model with ideal behavior would get as many questions correct as possible while not attempting the questions for which it is not confident it knows the correct answer. SimpleQA is a simple, targeted evaluation for whether models "know what they know," and our hope is that this benchmark will remain relevant for the next few generations of frontier models. SimpleQA can be found at https://github.com/openai/simple-evals.
How I Built a Tool to Detect AI-Generated Fake References
Large Language Models(LLMs) have become part of everyday academic and technical writing. But there is...

SimpleQA Verified: A Reliable Factuality Benchmark to Measure Parametric Knowledge
We introduce SimpleQA Verified, a 1,000-prompt benchmark for evaluating Large Language Model (LLM) short-form factuality based on OpenAI's SimpleQA. It addresses critical limitations in OpenAI's benchmark, including noisy and incorrect labels, topical biases, and question redundancy. SimpleQA Verified was created through a rigorous multi-stage filtering process involving de-duplication, topic balancing, and source reconciliation to produce a more reliable and challenging evaluation set, alongside improvements in the autorater prompt. On this new benchmark, Gemini 2.5 Pro achieves a state-of-the-art F1-score of 55.6, outperforming other frontier models, including GPT-5. This work provides the research community with a higher-fidelity tool to track genuine progress in parametric model factuality and to mitigate hallucinations. The benchmark dataset, evaluation code, and leaderboard are available at: https://www.kaggle.com/benchmarks/deepmind/simpleqa-verified.
SimpleQA Verified: A Reliable Factuality Benchmark to Measure Parametric Knowledge
We introduce SimpleQA Verified, a 1,000-prompt benchmark for evaluating Large Language Model (LLM) short-form factuality based on OpenAI's SimpleQA. It addresses critical limitations in OpenAI's benchmark, including noisy and incorrect labels, topical biases, and question redundancy. SimpleQA Verified was created through a rigorous multi-stage filtering process involving de-duplication, topic balancing, and source reconciliation to produce a more reliable and challenging evaluation set, alongside improvements in the autorater prompt. On this new benchmark, Gemini 2.5 Pro achieves a state-of-the-art F1-score of 55.6, outperforming other frontier models, including GPT-5. This work provides the research community with a higher-fidelity tool to track genuine progress in parametric model factuality and to mitigate hallucinations. The benchmark dataset, evaluation code, and leaderboard are available at: https://www.kaggle.com/benchmarks/deepmind/simpleqa-verified.
Language agents achieve superhuman synthesis of scientific knowledge
Language models are known to hallucinate incorrect information, and it is unclear if they are sufficiently accurate and reliable for use in scientific research. We developed a rigorous human-AI comparison methodology to evaluate language model agents on real-world literature search tasks covering information retrieval, summarization, and contradiction detection tasks. We show that PaperQA2, a frontier language model agent optimized for improved factuality, matches or exceeds subject matter expert performance on three realistic literature research tasks without any restrictions on humans (i.e., full access to internet, search tools, and time). PaperQA2 writes cited, Wikipedia-style summaries of scientific topics that are significantly more accurate than existing, human-written Wikipedia articles. We also introduce a hard benchmark for scientific literature research called LitQA2 that guided design of PaperQA2, leading to it exceeding human performance. Finally, we apply PaperQA2 to identify contradictions within the scientific literature, an important scientific task that is challenging for humans. PaperQA2 identifies 2.34 +/- 1.99 contradictions per paper in a random subset of biology papers, of which 70% are validated by human experts. These results demonstrate that language model agents are now capable of exceeding domain experts across meaningful tasks on scientific literature.
openbench: Provider-agnostic, open-source evaluation infrastructure for language models
Provider-agnostic, open-source evaluation infrastructure for language models
Large language models, explained with a minimum of math and jargon
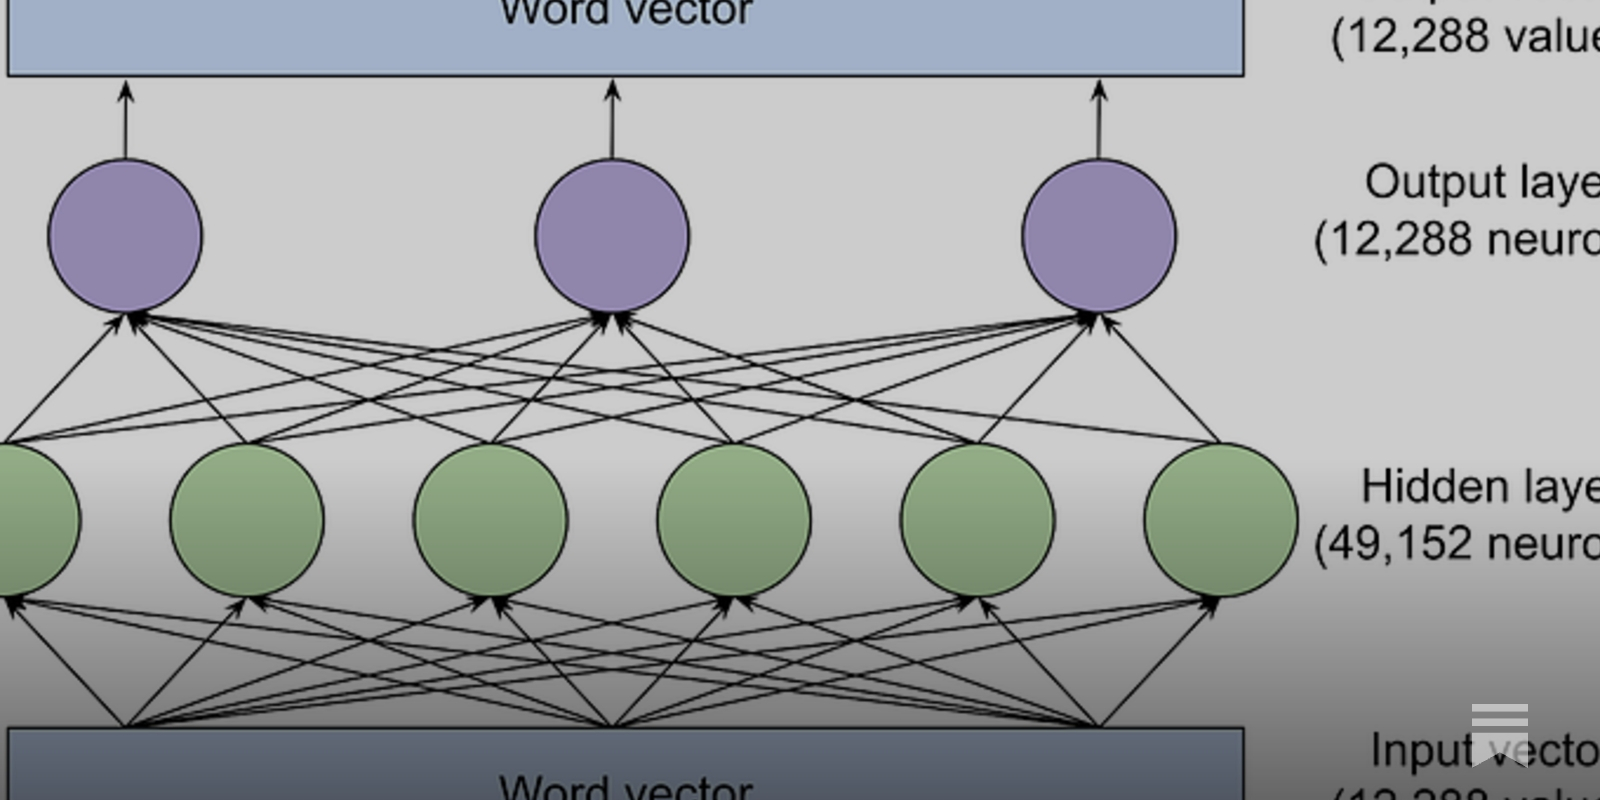
Want to really understand how large language models work? Here’s a gentle primer.
AI Homework
The first obvious casualty of large language models is homework: the real training for everyone, though, and the best way to leverage AI, will be in verifying and editing information.

Technical Report on the Pangram AI-Generated Text Classifier
We present Pangram Text, a transformer-based neural network trained to distinguish text written by large language models from text written by humans. Pangram Text outperforms zero-shot methods such as DetectGPT as well as leading commercial AI detection tools with over 38 times lower error rates on a comprehensive benchmark comprised of 10 text domains (student writing, creative writing, scientific writing, books, encyclopedias, news, email, scientific papers, short-form Q&A) and 8 open- and closed-source large language models. We propose a training algorithm, hard negative mining with synthetic mirrors, that enables our classifier to achieve orders of magnitude lower false positive rates on high-data domains such as reviews. Finally, we show that Pangram Text is not biased against nonnative English speakers and generalizes to domains and models unseen during training.
