Local Laya typed decisions on Apple Core ML and Neural Engine. Validated ports, ~5 ms short decisions on M3 Max, reproducible speed and energy benchmarks.
Making Apple Neural Engine work in a custom inference stack
Apple Neural Engine always looked appealing on paper, but using it inside a custom runtime was harder. In 1.20260410.1, we made ANE practical for 8-bit S models by using CoreML only as an accelerator.
Part 4: Brief history of Apple ML Stack
By Mirai Labs, frontier on-device AI lab. Building the models, inference runtime, and quantization stack from the device constraint up.
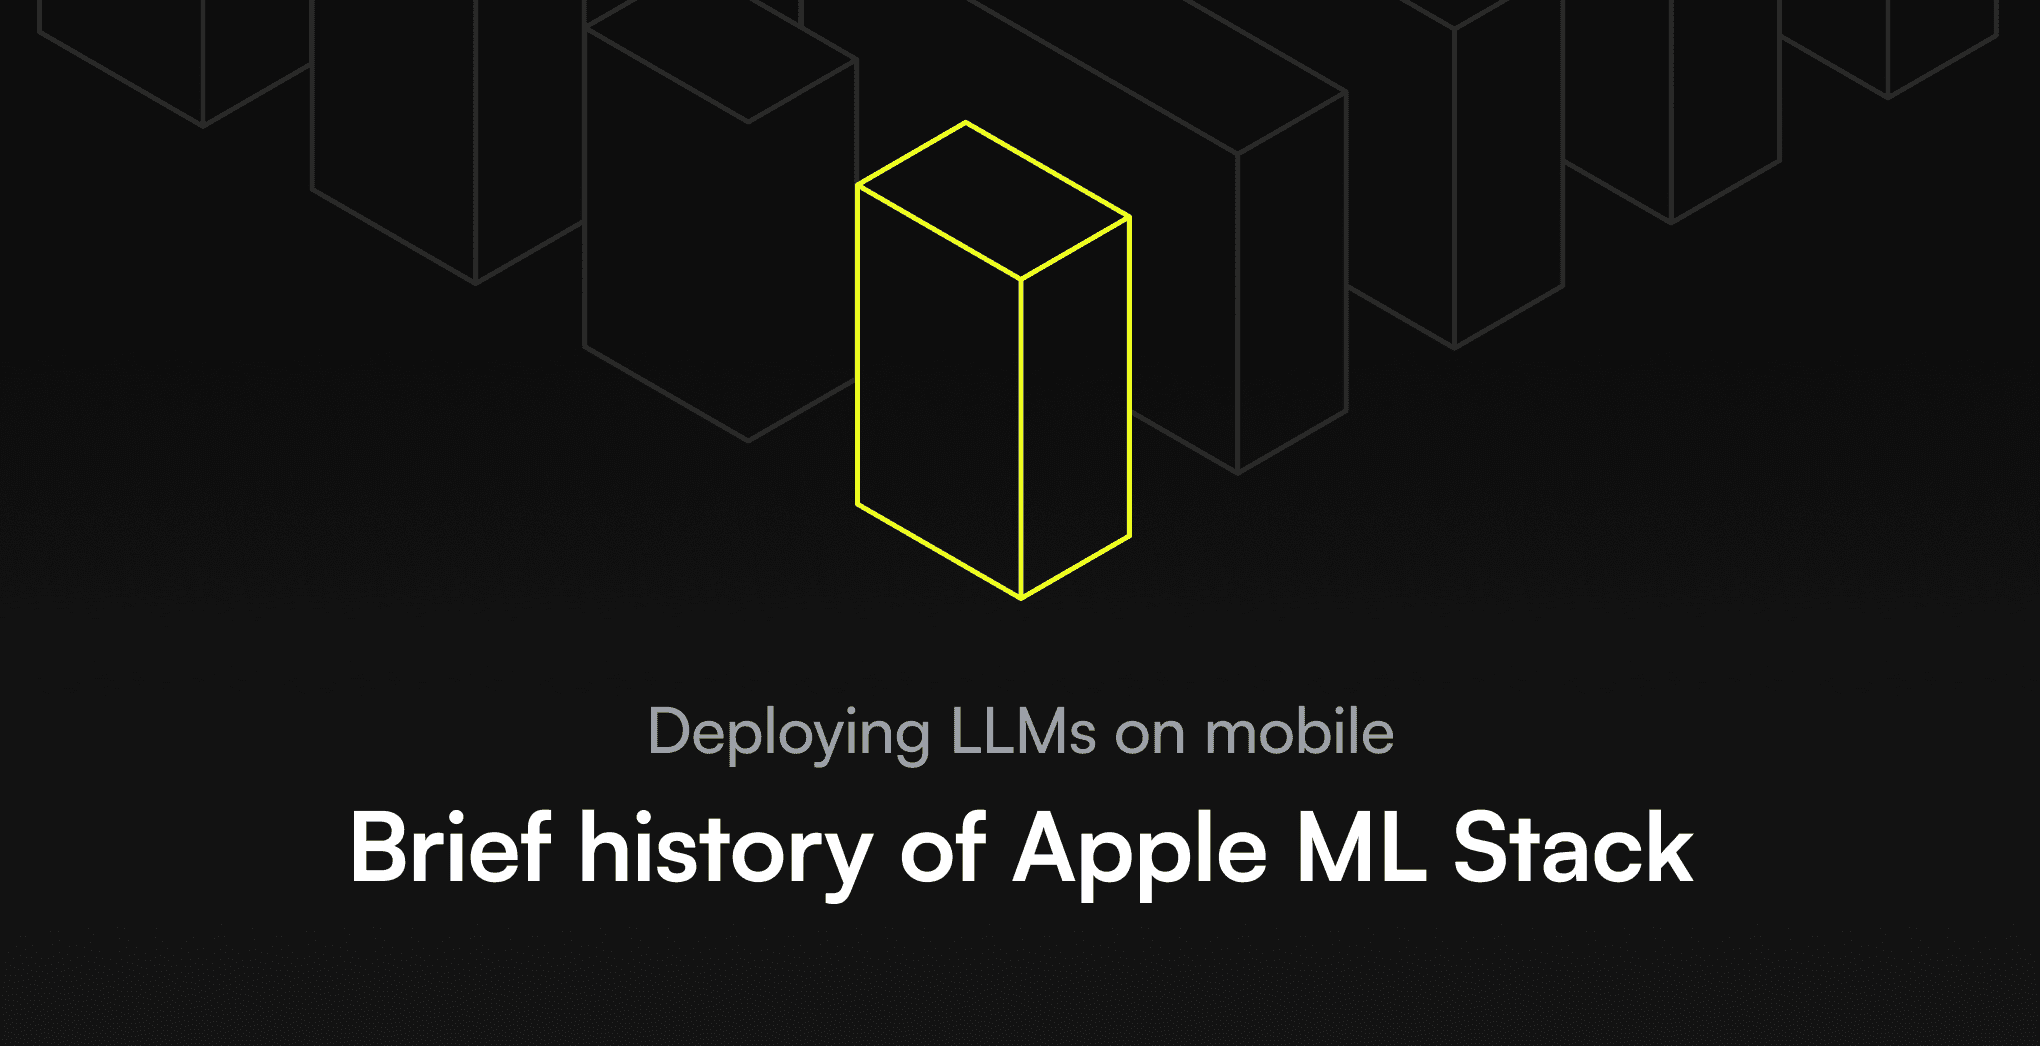
Ivan Fioravanti ᯅ on Twitter / X
"We are releasing Open Source implementations for CoreAILanguageModel and MLXLanguageModel for running a myriad of local models on the Apple Neural Engine or your Mac's GPU" 👀 From #WWDC26: What’s new in the Foundation Models framework video: https://t.co/1NtKWYhNRs pic.twitter.com/HVtBsr3tjL— Ivan Fioravanti ᯅ (@ivanfioravanti) June 9, 2026
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
videlalvaro/ane-book
Production LLM inference on the Apple Neural Engine — a practitioner's guide, complete with converters, Swift runtimes, and validated model manifests
apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
Laya — 33ms Multilingual System 1 Decision Engine
Evaluates typed decisions (choice, score, noul) over 100+ languages in a single forward pass with calibrated probabilities. Outperforms TypeSafe Jev.
Introducing LFM2: The Fastest On-Device Foundation Models on the Market | Liquid AI
Today, we release LFM2, a new class of Liquid Foundation Models (LFMs) that sets a new standard in quality, speed, and memory efficiency for on-device deployment. Built on a hybrid architecture, LFM2 delivers 200% faster decode and prefill performance than Qwen3 and Gemma 3 on CPU. It also significantly outperforms models in each size class on instruction-following and function calling—the core capabilities that make LLMs reliable for building AI agents.

Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
On-Device LLM Throughput Calculator - a Hugging Face Space by FL33TW00D-HF
This tool estimates and visualizes the throughput of Large Language Models on devices with memory bandwidth constraints. Users input device and model configurations, and the tool generates a plot s...
Locally AI - Run AI models locally on your iPhone, iPad, and Mac.
Run Llama, Gemma, Qwen, DeepSeek, and more on your iPhone, iPad, and Mac. Optimized for Apple Silicon. Offline. Private.
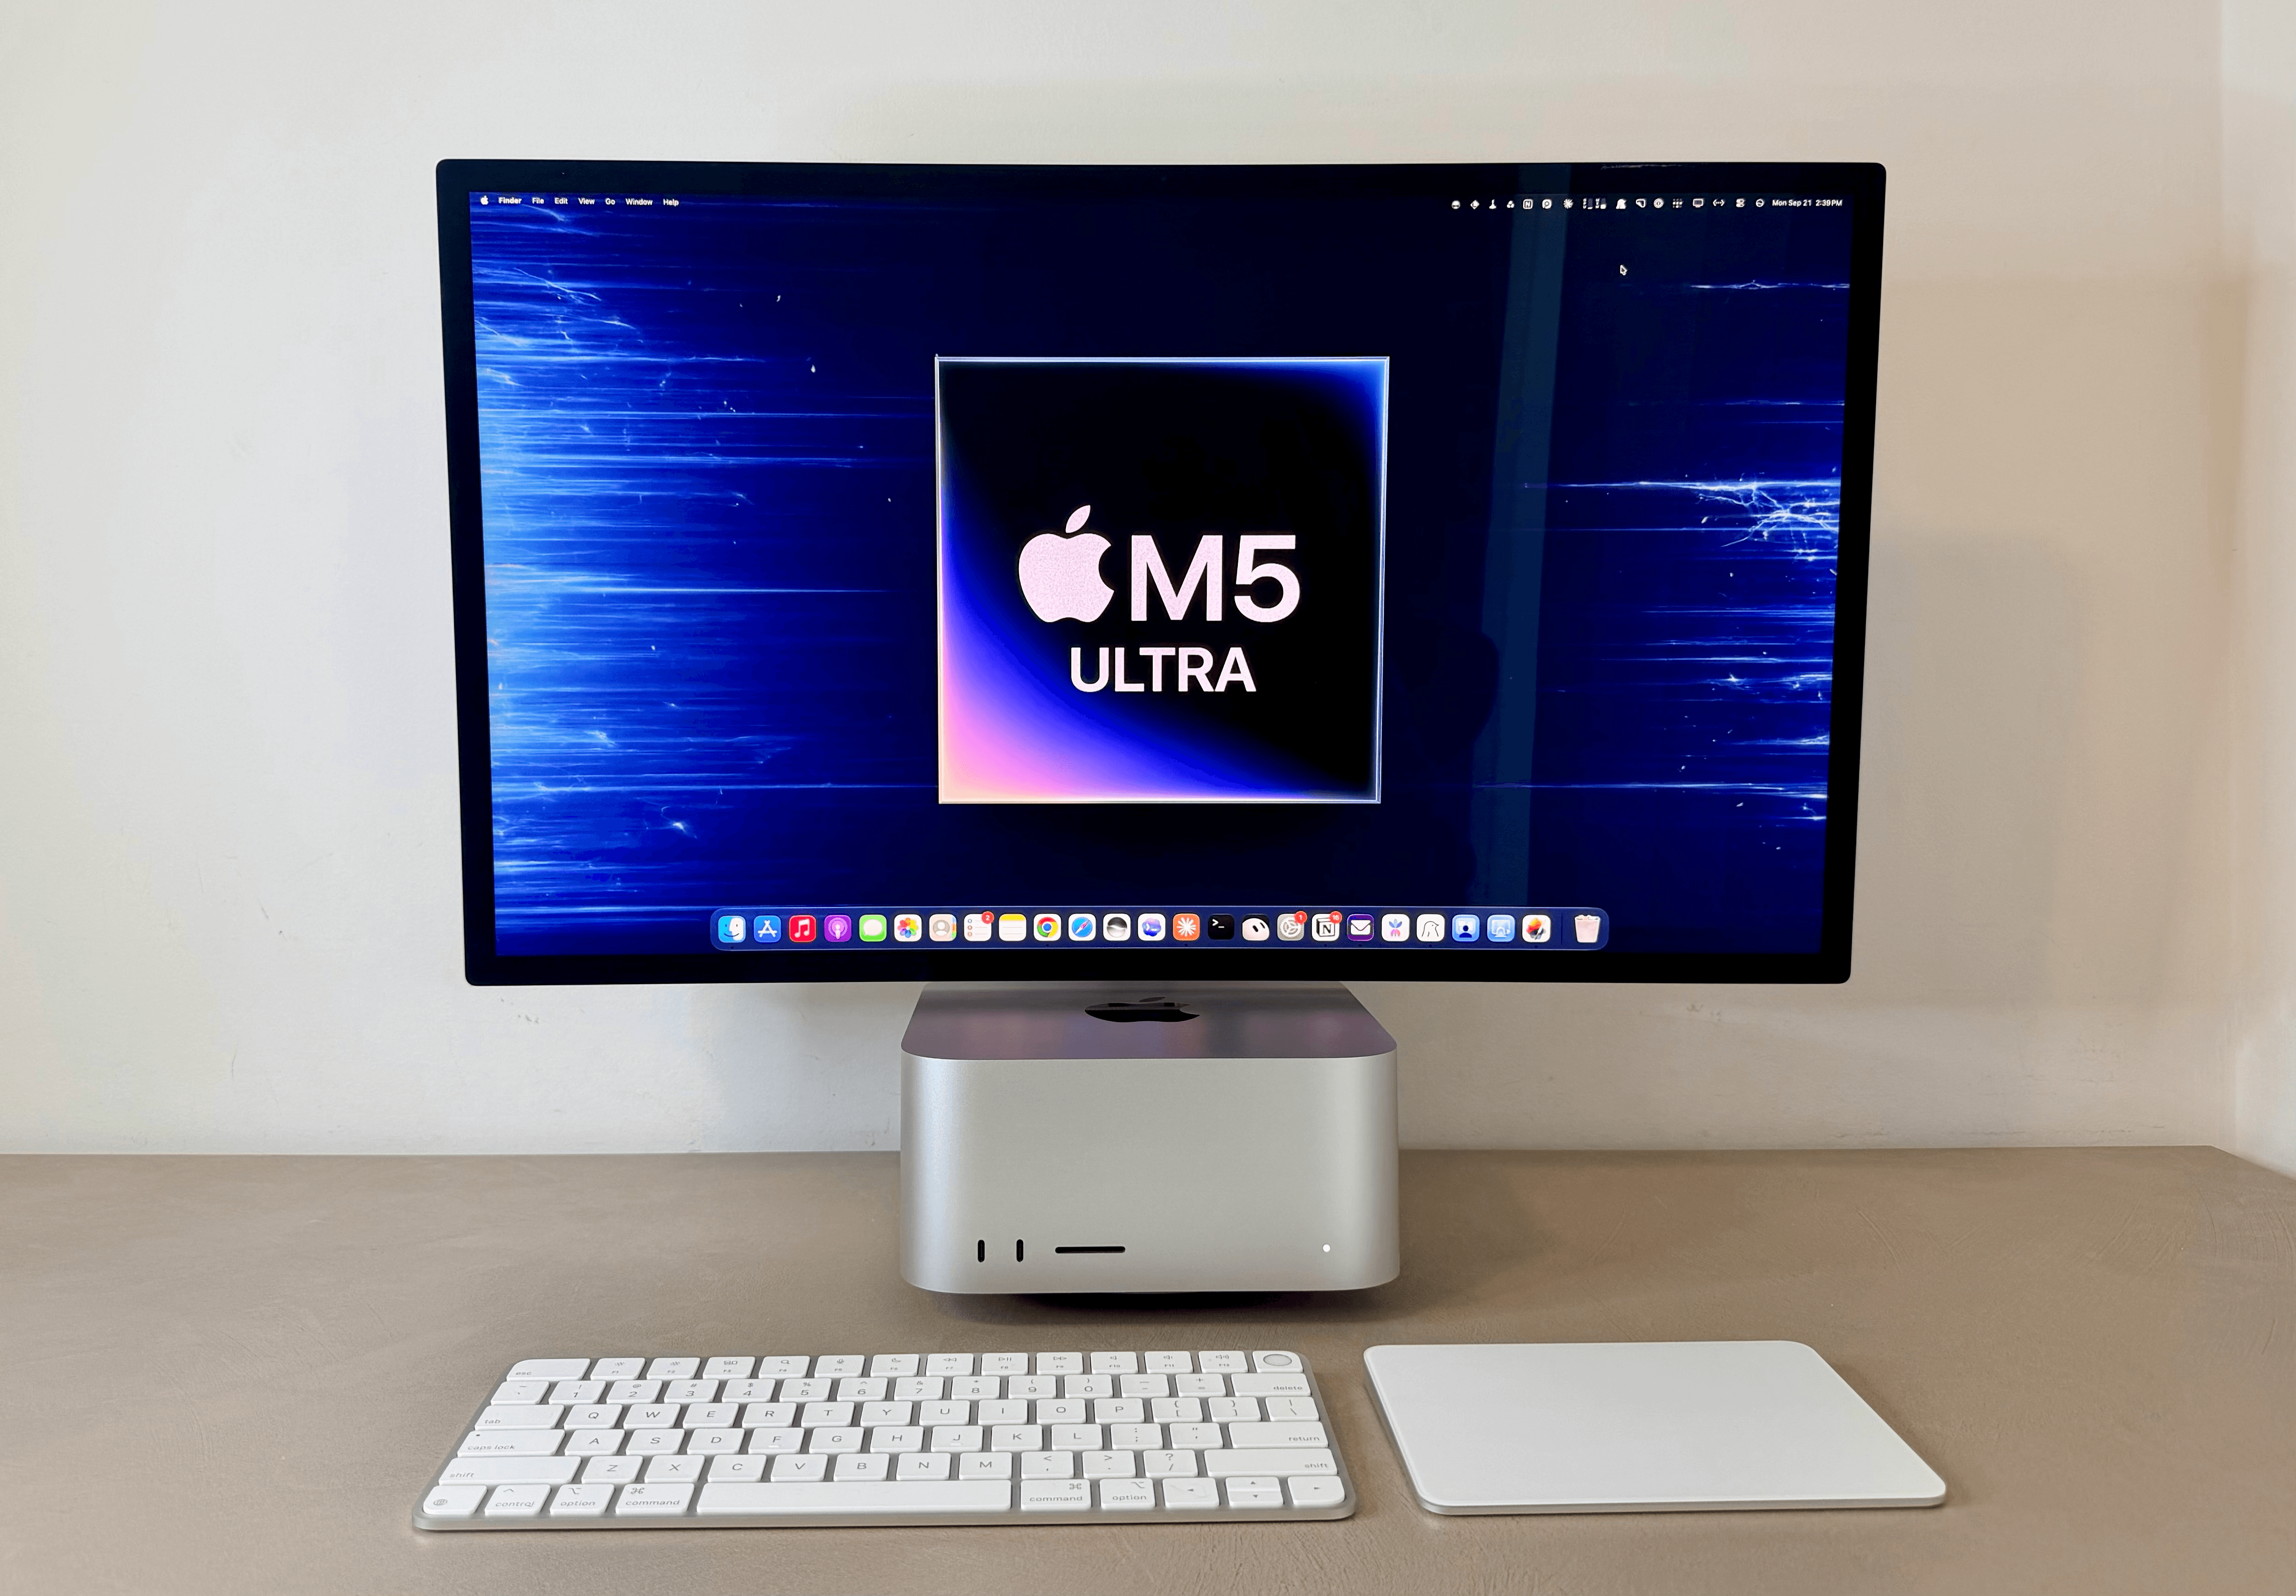
M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents
For the past few days, I’ve been testing the (currently) top-of-the-line M5 Ultra Mac Studio with 256 GB of RAM. I’ll cut to the chase: the M5 Ultra Mac Studio is a dream machine for local AI agents. This computer makes it possible to run personal assistants powered by local models with great performance and
clem 🤗 on Twitter / X
We just released an hf CLI extension to detect the best model/quant for a user's hardware and then spins up a local coding agent. Time to go local/private/free/fast for your agents thanks to open-source! pic.twitter.com/LcVJzGCqWx— clem 🤗 (@ClementDelangue) March 17, 2026

Compiling Models to Megakernels
Fine-grained synchronization, deep pipelines, and zero kernel launch overheads, automatically.