

Run LLMs with MLX
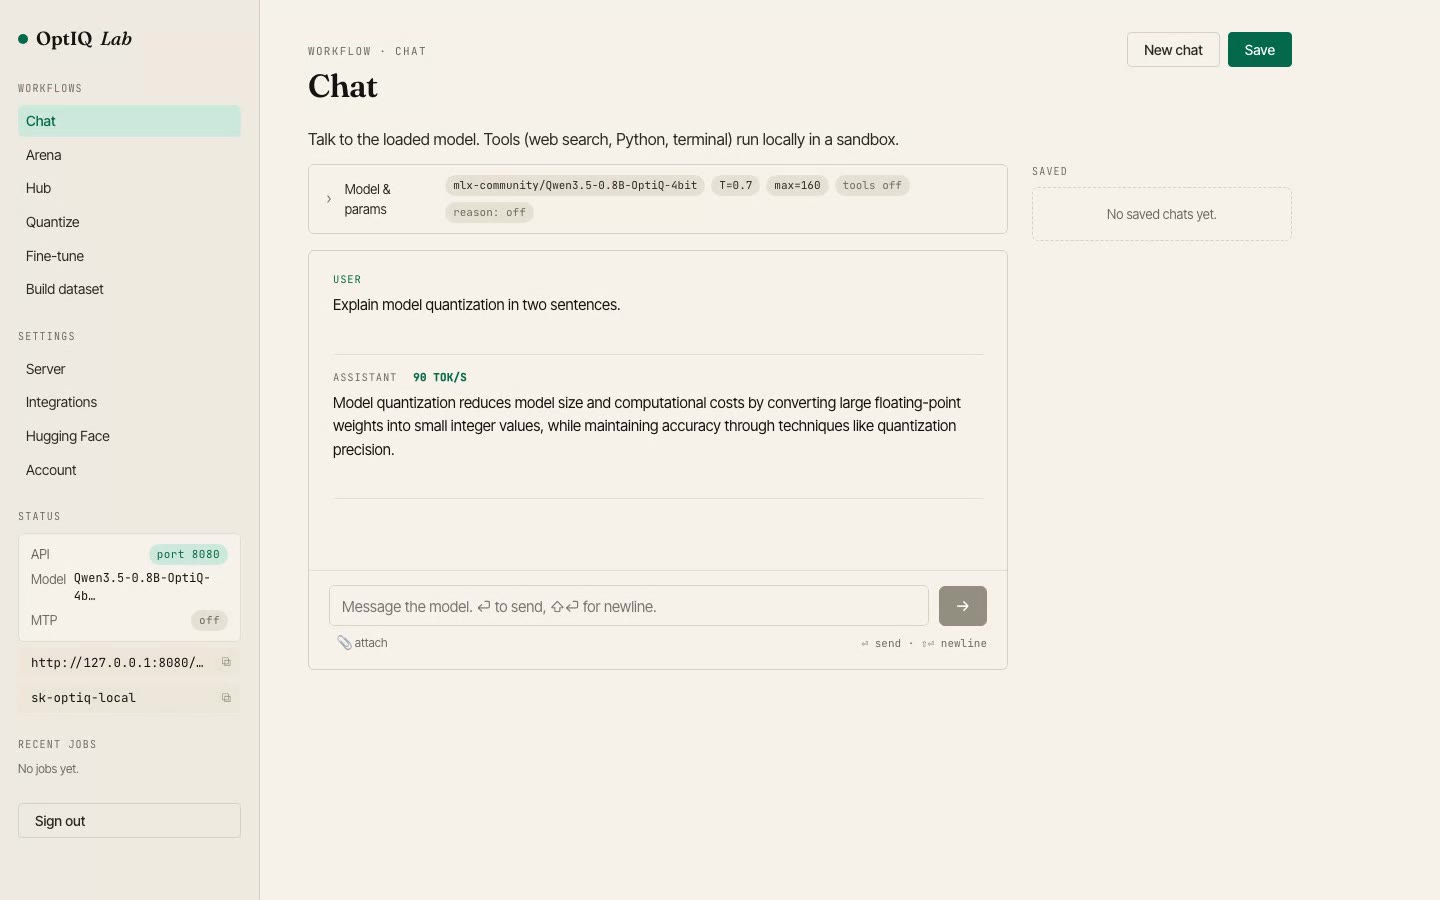
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
Awni Hannun on Twitter / X
The latest mlx-lm is out and it has continuous batching with mlx_lm.server! Added by @angeloskath Check-out the video of 4 simultaneous requests running with Qwen3 30B on the same M2 Ultra: https://t.co/o9sFC3k4DN— Awni Hannun (@awnihannun) December 3, 2025
mlx-examples/stable_diffusion at main · ml-explore/mlx-examples
Examples in the MLX framework. Contribute to ml-explore/mlx-examples development by creating an account on GitHub.
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

Your Laptop Isn’t Ready for LLMs. That’s About to Change
The quest to run large AI models locally on an individual's machine are driving the biggest change in laptop architecture in decades.

omlx/docs/experimental/dflash_mlx_integration.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
Research – Inception
We are leveraging diffusion technology to develop a new generation of LLMs. Our dLLMs are much faster and more efficient than traditional autoregressive LLMs.
mzau/broke-cluster
A Poor Man's Apple Silicon LLM Cluster — tuned for MLX, scalable without shame.
Doriandarko/MLX-GRPO
A pure MLX-based training pipeline for fine-tuning LLMs using GRPO on Apple Silicon.
The Ultimate Guide to Fine-Tuning LLMs from Basics to Breakthroughs: An Exhaustive Review of Technologies, Research, Best Practices, Applied Research Challenges and Opportunities (Version 1.0)
vllm-project/vllm
A high-throughput and memory-efficient inference and serving engine for LLMs