

Speakrail - a low-latency fully-local voice assistant that runs on a single RTX 4090
Serving Voice AI at $1/hr: Open-source, LoRAs, Latency, Load Balancing - Neil Dwyer, Gabber
VoiceInk - Advanced AI Voice Recognition for Mac
Transform Your Voice Into Text Instantly with Offline AI. Built for Mac, Optimized for Privacy. One-Time Purchase, No Subscriptions.
Why MLX — Prince Canuma, Neywa Labs
ICML WhisperKit: On-device Real-time ASR with Billion-Scale Transformers
Real-time Automatic Speech Recognition (ASR) is a fundamental building block for many commercial applications of ML, including live captioning, dictation, meeting transcriptions, and medical scribes. Accuracy and latency are the most important factors when companies select a system to deploy. We present WhisperKit, an optimized on-device inference system for real-time ASR that significantly outperforms leading cloud-based systems. We benchmark against server-side systems that deploy a diverse set of models, including a frontier model (OpenAI gpt-4o-transcribe), a proprietary model (Deepgram nova-3), and an open-source model (Fireworks large-v3-turbo).Our results show that WhisperKit matches the lowest latency at 0.46s while achieving the highest accuracy 2.2\% WER. The optimizations behind the WhisperKit system are described in detail in this paper.
\robotoslablightdots.tts Technical Report
Text-to-speech (TTS) systems have largely solved intelligibility on standard read-speech benchmarks. What users expect from a modern system is broader: expressive and controllable output, real-time synthesis, and coverage of neutral reading, emotional dialogue, paralinguistic events, singing, and general audio. Current systems pursue this goal along three roughly distinct technical routes, and each route has its own unresolved problem.
How OpenAI delivers low-latency voice AI at scale
How OpenAI rebuilt its WebRTC stack to power real-time Voice AI with low latency, global scale, and seamless conversational turn-taking.
kwindla on Twitter / X
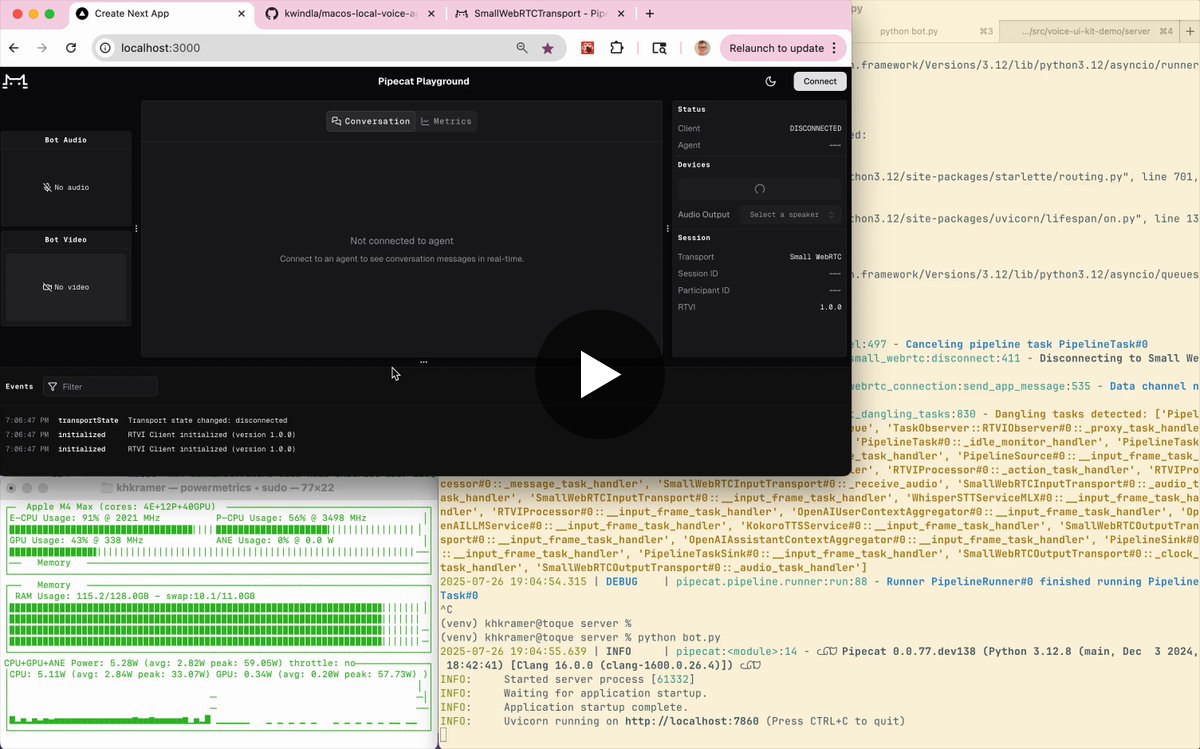
Local voice AI with a 235 billion parameter LLM. ✅- smart-turn v2- MLX Whisper (large-v3-turbo-q4)- Qwen3-235B-A22B-Instruct-2507-3bit-DWQ- KokoroAll models running local on an M4 mac. Max RAM usage ~110GB.Voice-to-voice latency is ~950ms. There are a couple of… pic.twitter.com/iYNQlb9JkI— kwindla (@kwindla) July 27, 2025
Gabber - Build Realtime AI Apps that can see, hear, and speak
Low-latency inference for VLM, TTS, and STT with orchestration for making realtime apps.
BetterWispr: local dictation for macOS
Hold a shortcut, speak, and BetterWispr types clean text into any Mac app. Local speech models, a style for each app, meeting notes and insights. Free and open source, with no account required.
Announcing transcribe.cpp
Meet transcribe.cpp, a new open-source C/C++ speech-to-text inference library with portable, GPU-accelerated support for multiple STT models. Developed through Mozilla.ai's Builders in Residence program, it makes adding fast, local transcription to applications easier than ever.
ChatGPT Voice can keep talking while it works - Sensemaker
OpenAI’s GPT-Live splits live conversation from slower search, reasoning, and agent work in the background.
Realtime and audio | OpenAI API
Learn which realtime and audio guide to use for each speech application.
Pipecat Cloud: Enterprise Voice Agents Built On Open Source - Kwindla Hultman Kramer, Daily
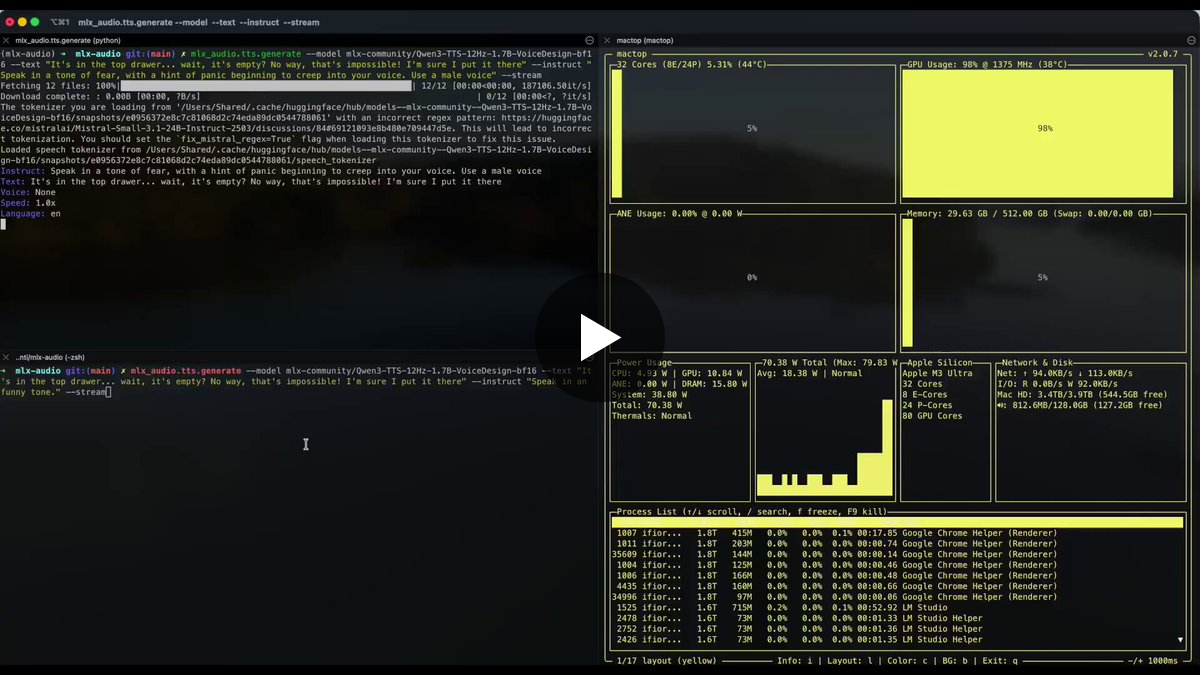
Ivan Fioravanti ᯅ on Twitter / X
Playing with Qwen3-TTS is and MLX-Audio locally on Mac Studio M3 Ultra 🔥Amazing model by @Alibaba_Qwen and great work by @Prince_Canuma bringing this magic to MLX!Tuning the voice with instructions feels like magic!Command and prompts to run it are in the video. pic.twitter.com/qIfWKOedXr— Ivan Fioravanti ᯅ (@ivanfioravanti) January 23, 2026

Introducing **transcribe.cpp** 🎙️ A new open-source C/C++ speech-to-text inference library for fast, local transcription. ✅ Multiple GGUF STT models ✅ GPU acceleration (Metal, Vulkan & CUDA) ✅ Portable across platforms Built through @mozilla.ai's BiR program. Blog: blog.mozilla.ai/announcing-transcribe-cpp/

Announcing transcribe.cpp
blog.mozilla.ai