

🐋 Run 284B DeepSeek-V4-Flash (<59GiB RAM, 44.4 tok/s pp, 9.1-14.7 tok/s) & 30B MoEs (25-111 tok/s) on a pure 64GB CPU at 256K ctx (0 GPUs). SwiGLU-H2, Stockfish-PVS L3 & 13ms Claude Code restore.
DeepSeek-V4.1-Flash: Run Locally Guide | Unsloth Documentation
Run DeepSeek-V4.1-Flash-1017 locally with Unsloth GGUFs and Engram n-gram offloading.

Llama 4: How to Run & Fine-tune | Unsloth Documentation
How to run Llama 4 locally using our dynamic GGUFs which recovers accuracy compared to standard quantization.

Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
The Big LLM Architecture Comparison
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
JITEngine: LLM serving, synthesized for your Mac
LLM serving engines synthesized for your Mac, up to 2.7× as fast as the best other server we measured on the same Mac. Pick your Mac and get its commands, with the speeds we measured.
Compiling Models to Megakernels
Fine-grained synchronization, deep pipelines, and zero kernel launch overheads, automatically.
[Tool Release] Finetune & Quantize 1–3B LLMs on 8GB RAM using LoFT CLI (TinyLlama + QLoRA + llama.cpp)
23 votes, 16 comments. Hey folks — I’ve been working on a CLI tool called LoFT (Low-RAM Finetuning Toolkit), and I finally have a working release. 🔧…
I just rewrote llama.cpp server in Rust (most of it at least), and made it scalable
497 votes, 46 comments. Long story short, I rewrote most of the llama-server, made it scalable, and bundled that into Paddler. Initially, the project…
Dynamic 1-bit DeepSeek-R1-0528 GGUFs out now!
118 votes, 16 comments. Hey guys sorry for the wait, but now you can now run DeepSeek-R1-0528 with our Dynamic 1-bit GGUFs!…
BytePlus Free Trial: 4K AI Image/Video Models + LLM Tokens | 200 Free Images
BytePlus free trial, Seedream 4.0, Seedance 1.0, DeepSeek V3.1, GPT-OSS-120B, free 4K AI images, AI video generation, BytePlus LLM tokens
Underdog Saluki 27B
Qwen3.8-27B in a 7.89 GB file that loads in stock llama.cpp, and how it compares with other 2-bit builds.

Mia on Twitter / X
Fast and Furious ⚡️Update your DeepSeek v4.1 Flash on 3x DGX Sparks- Prose decode tok/s improved by 17%- Code decode tok/s improved by 39%- Mixed decode tok/s improved by 29%Prose single stream is now 50+ tok/s and 85 tok/s at 4 concurrent streams.Changes to 4x DGX… pic.twitter.com/0cMC1kgvDR— Mia (@MiaAI_lab) September 24, 2026
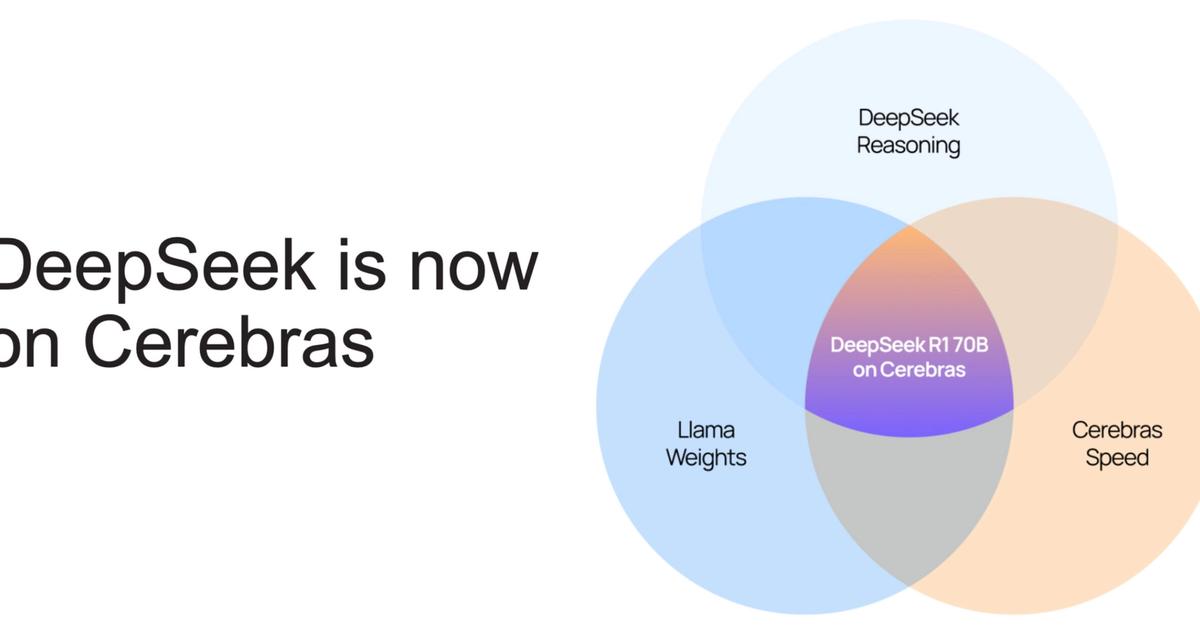
Cerebras Launches World Fastest DeepSeek R1 Llama-70B Inference - Cerebras
Cerebras launches fastest DeepSeek
Tiles version 0.4.13 Alpha 17 has been released. Adds Linux support with llama.cpp, configurable inference runtime controls, capability-based P2P syncing with UCAN, improved device linking, and reliability improvements for tool calling and streaming. Release notes: tiles.run/share/YXQ6Ly9kaWQ6cGxjOnZreGY…

Shared chat session by @ankeshbharti.com | Tiles
www.tiles.run