


Serve the MLX models your cocore agent runs locally to your own tools without round-tripping through the cocore network.
MLX India Community Meetup 2 | Own Your AI by Ankesh Bharti
GradientHQ/parallax
Parallax is a distributed model serving framework that lets you build your own AI cluster anywhere
Improving LM Studio's MLX Engine for Agentic Workflows
mlx-engine v1.8.5 dramatically improves performance for repeated, long-context agentic workflows by checkpointing your KV cache.
Why MLX — Prince Canuma, Neywa Labs
freestylefly/wesight
Open-source desktop AI agent workspace with one-click Claude Code, Codex, OpenClaw, Hermes Agent setup and custom LLM model routing.
Unsloth AI on Twitter / X
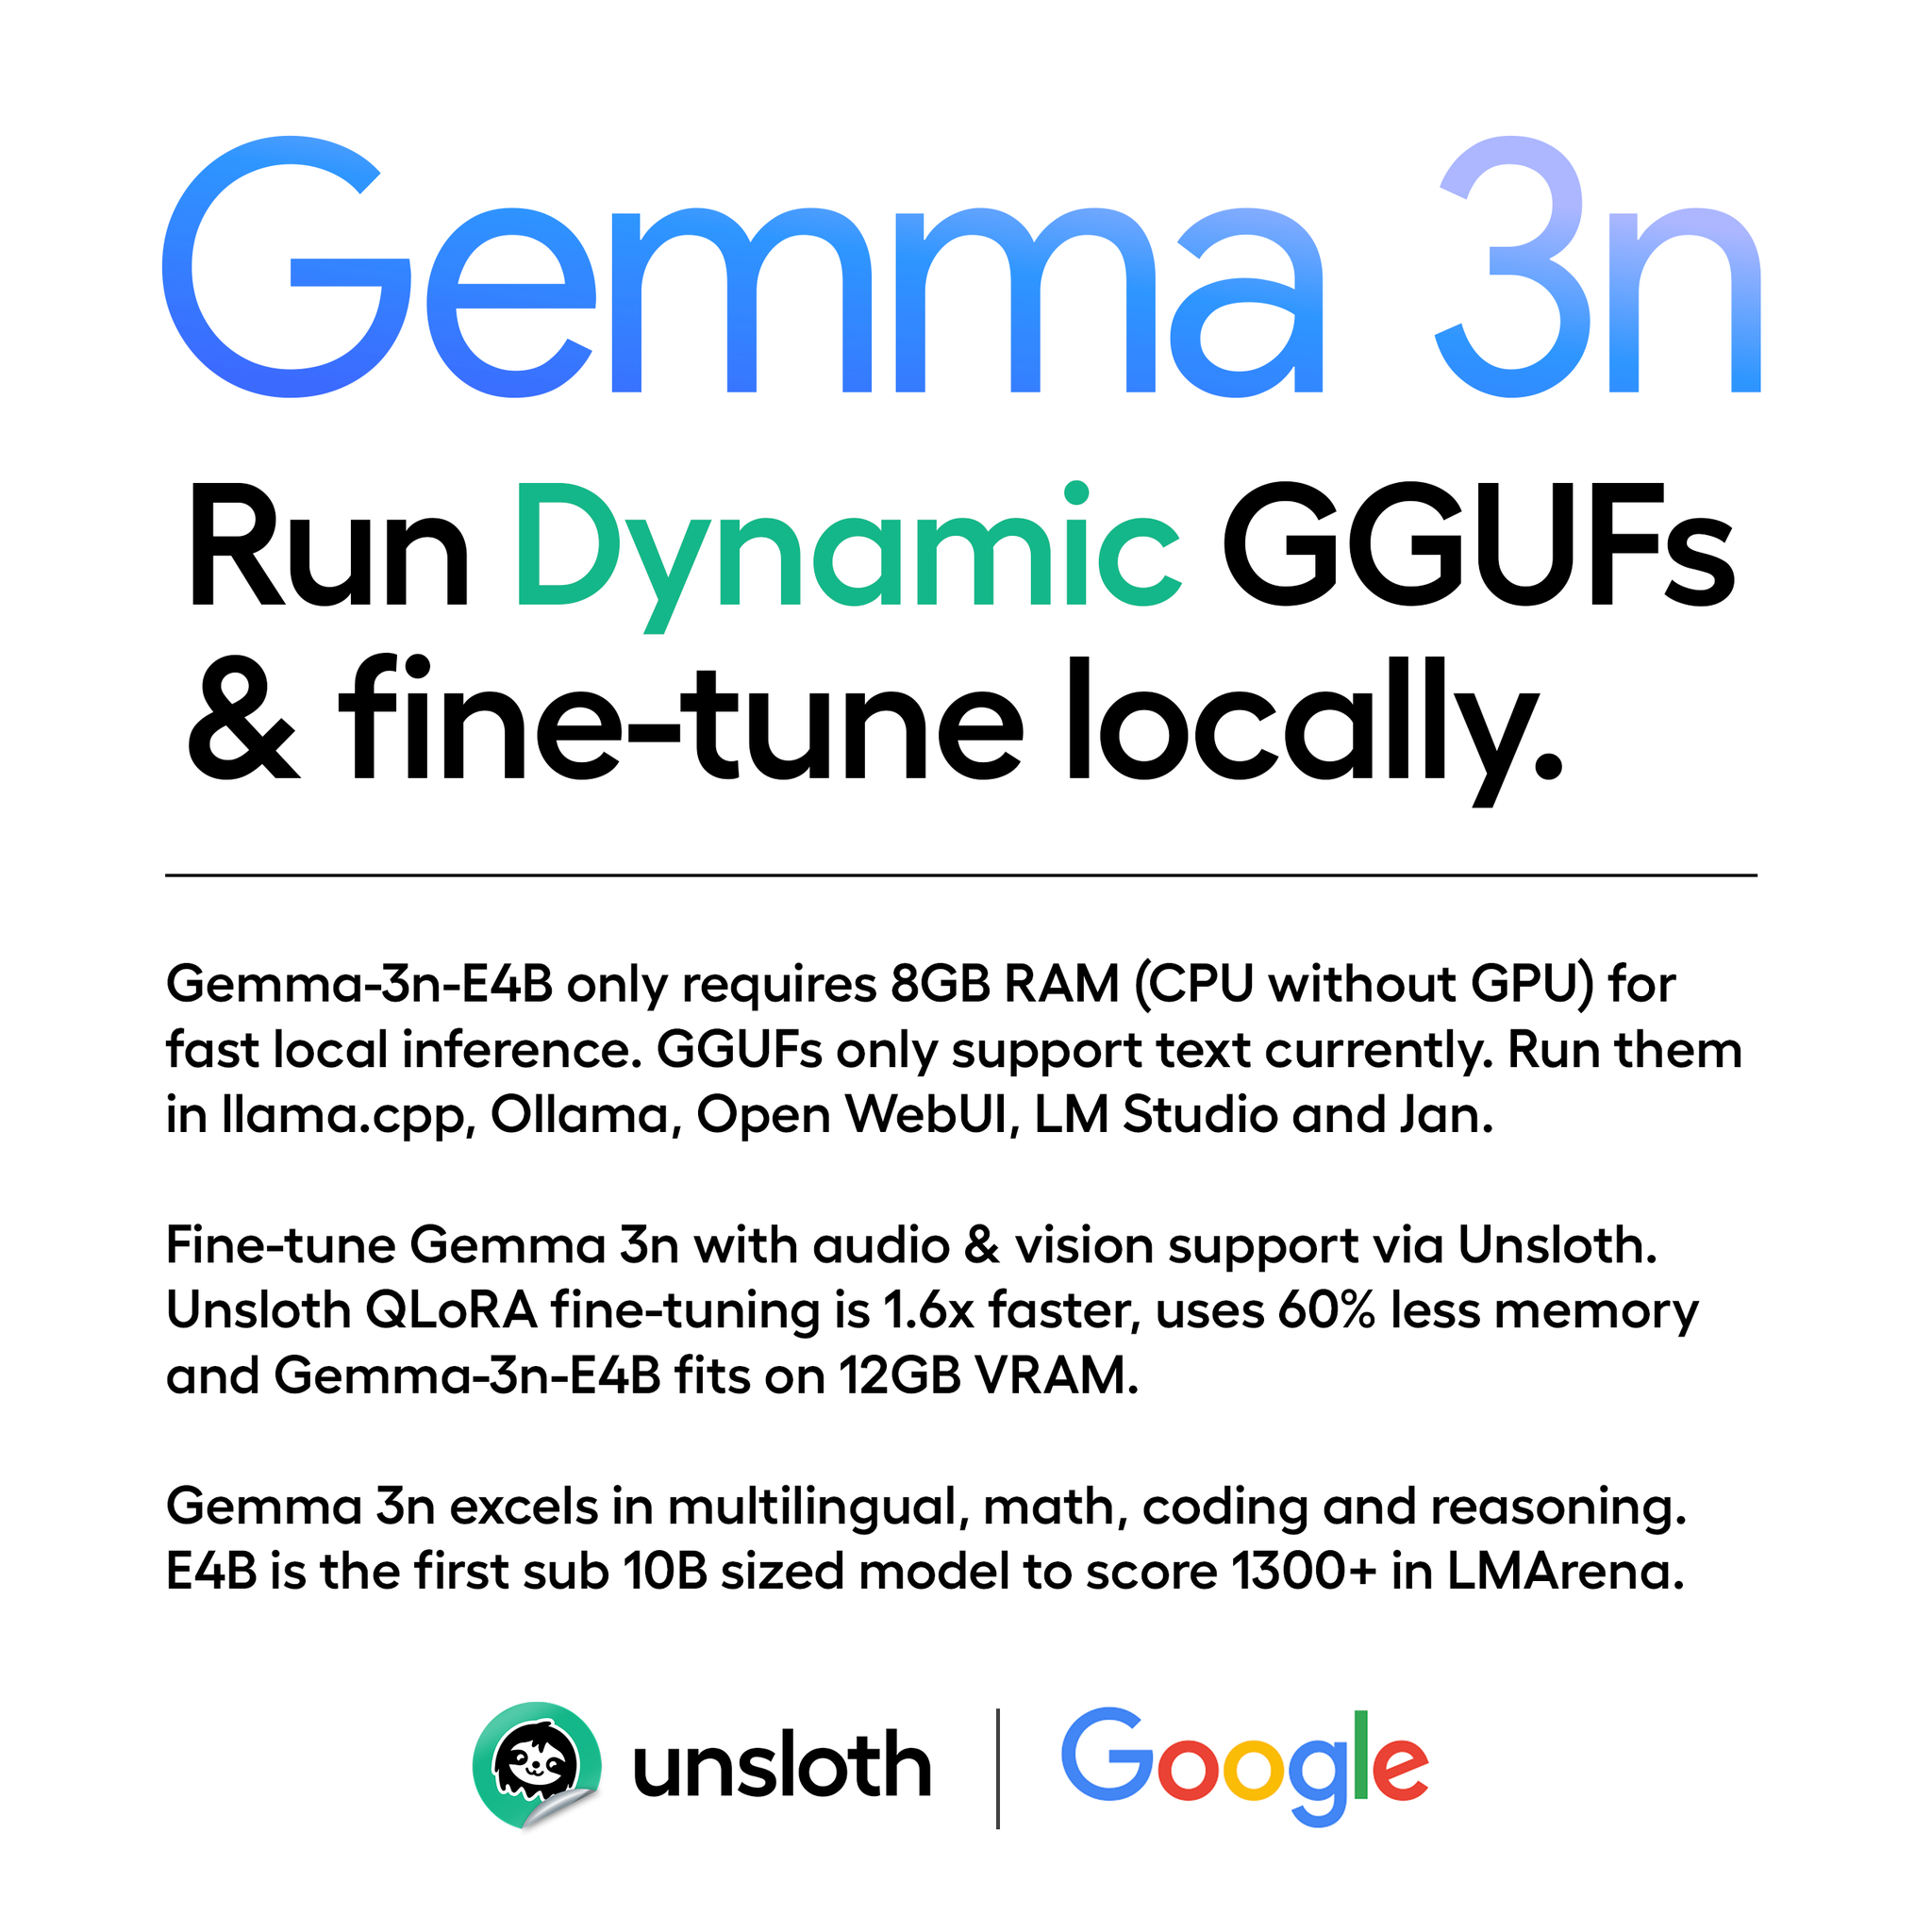
Run Gemma 3n locally with our Dynamic GGUFs!✨@Google's Gemma 3n supports audio, vision, video & text and the 4B model fits on 8GB RAM for fast local inference.Fine-tuning is also supported in Unsloth.Gemma-3n-E4B GGUF: https://t.co/PliynxoKQc https://t.co/wMFWLjNaDR pic.twitter.com/lxsMNDmkW8— Unsloth AI (@UnslothAI) June 26, 2025
Msty Nexus - Inference Gateway
Put one governed inference layer behind your AI tools for model routing, local runtimes, provider keys, usage visibility, and guardrails.
mlx-examples/stable_diffusion at main · ml-explore/mlx-examples
Examples in the MLX framework. Contribute to ml-explore/mlx-examples development by creating an account on GitHub.
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
Mlem - A Beautiful iOS Client for Lemmy
Mlem is a beautiful, intuitive open source iOS client for Lemmy that lets you effortlessly participate in conversations across all Lemmy servers.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
Release v0.29.0 · ml-explore/mlx
Highlights Support for mxfp4 quantization (Metal, CPU) More performance improvements, bug fixes, features in CUDA backend mx.distributed supports NCCL back-end for CUDA What's Changed [CUDA]...
Did an afternoon / evening speedrun of setting up local AI on the @z-space.ca network with @jacob.cascadia.social @vangarderen.net @hadsie.com - proxmox node for openwebui, npm - ASUS GX10 node for inference - Old Macbook running LiteLLM for routing between machines
