

Native Swift/MLX OpenAI-compatible inference server for Apple Silicon
Rohan Paul on Twitter / X
👨🔧 Github: Native, Apple Silicon–only local LLM server. Similar to Ollama, but built on Apple's MLX- OpenAI API compatible, - Ollama‑compatible- OpenAI‑style tools + tool_choice, with tool_calls parsing and streaming deltasgithub. com/dinoki-ai/osaurus pic.twitter.com/G0NbWnEJcQ— Rohan Paul (@rohanpaul_ai) September 3, 2025

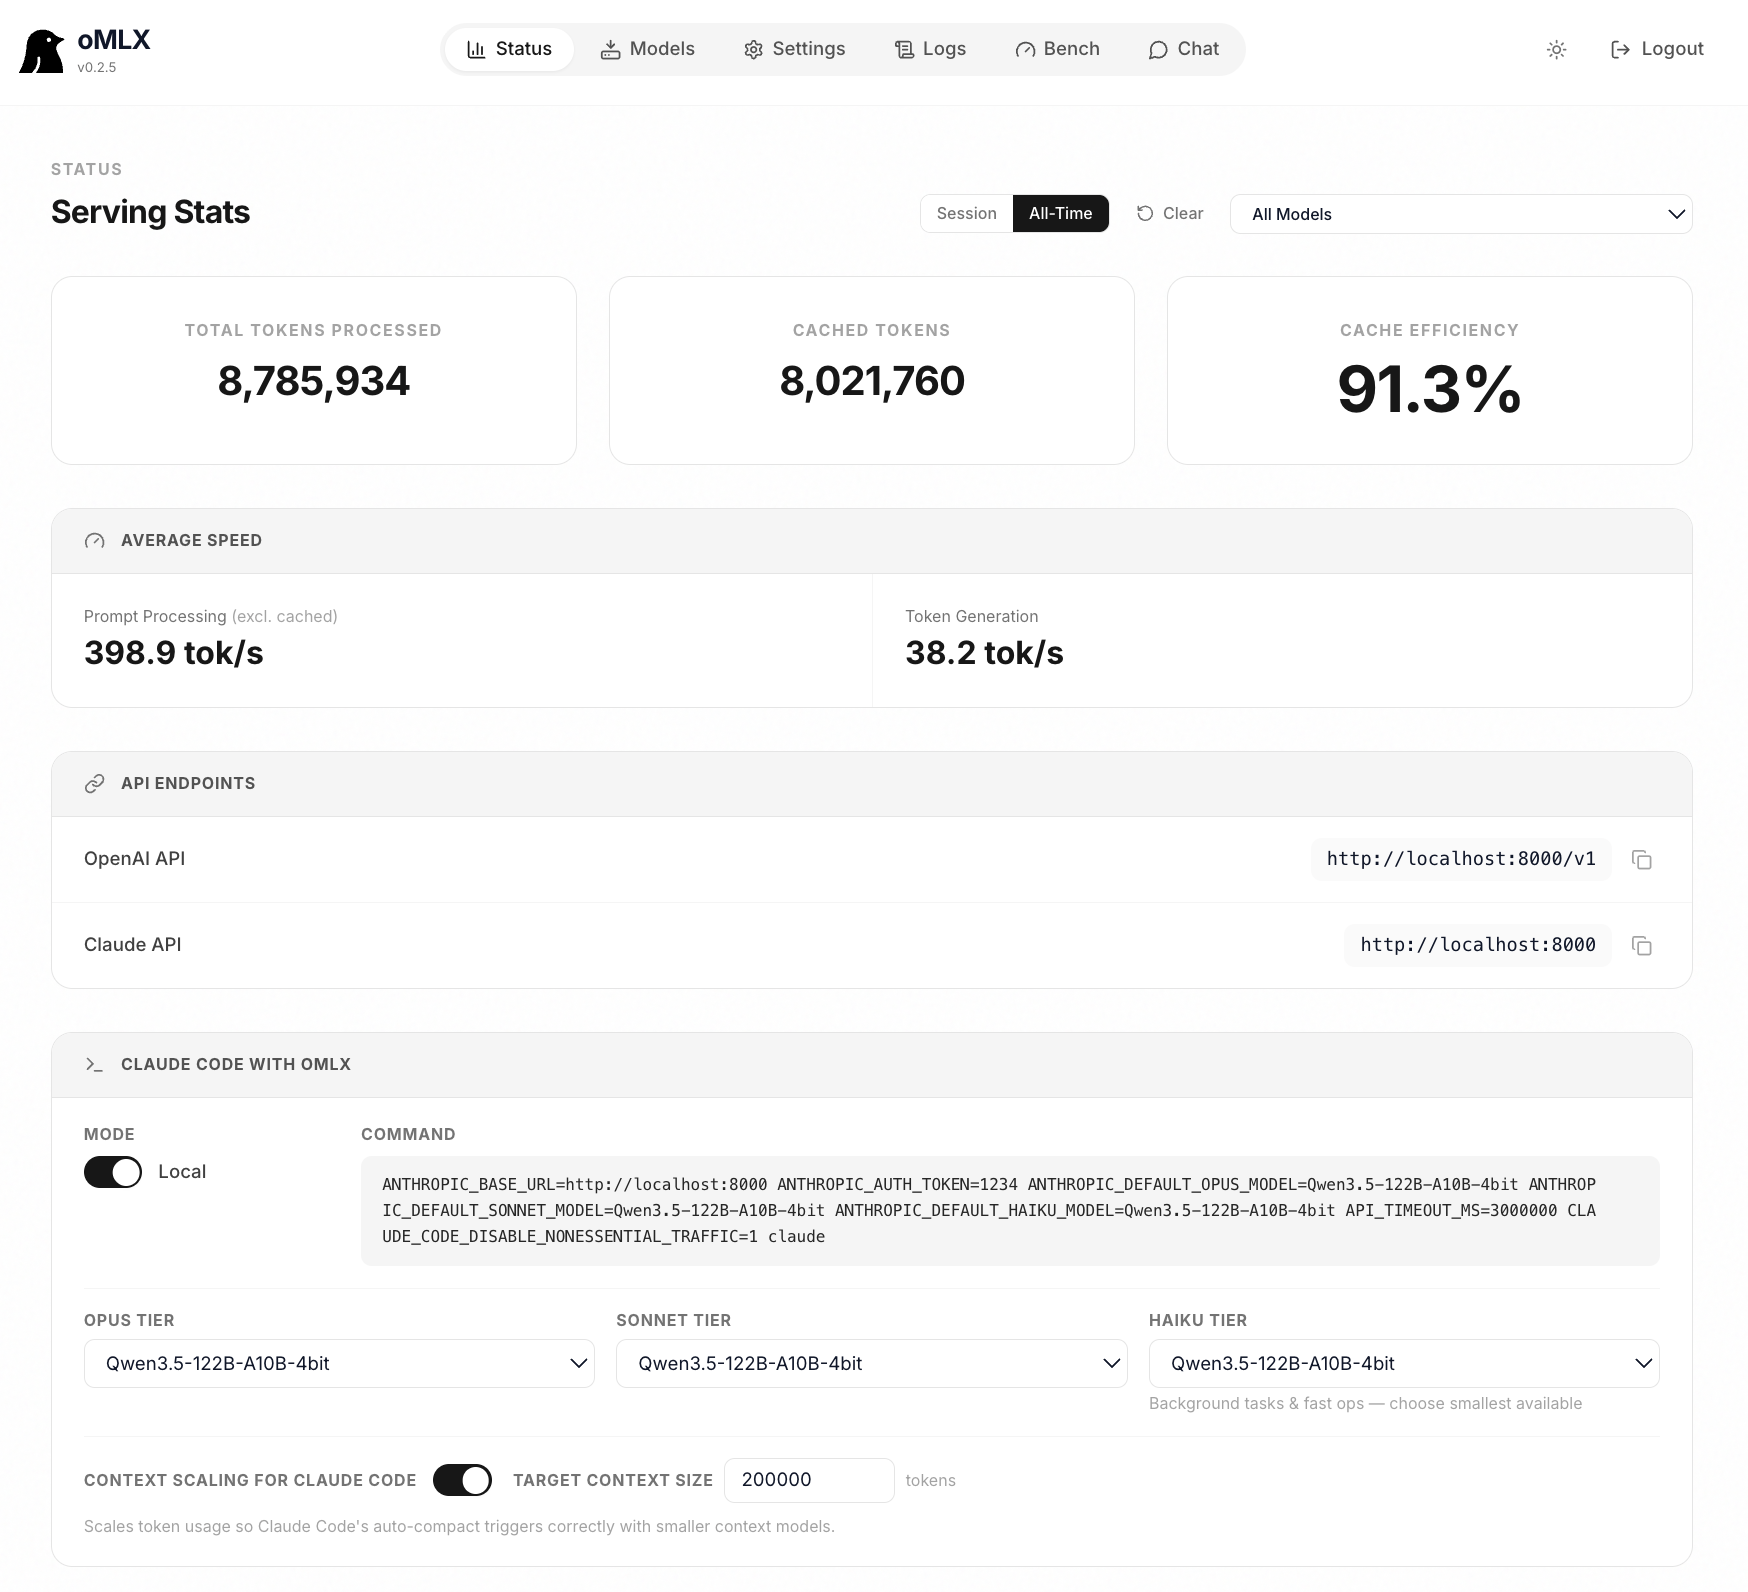
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
OpenAI and Broadcom unveil LLM-optimized inference chip
OpenAI and Broadcom introduce Jalapeño, a custom AI chip built for LLM inference to improve performance, efficiency, and scale across AI systems.
Osaurus — Own Your AI on Apple Silicon
Own your AI: local-first agents with memory, tools, and identity on Apple Silicon. Offline, open source, and API-compatible with OpenAI, Anthropic, and Ollama.

Osaurus — Own Your AI on Apple Silicon
Own your AI: local-first agents with memory, tools, and identity on Apple Silicon. Offline, open source, and API-compatible with OpenAI, Anthropic, and Ollama.
Ollama is now powered by MLX on Apple Silicon in preview· Ollama Blog
Today, we're previewing the fastest way to run Ollama on Apple silicon, powered by MLX, Apple's machine learning framework.
Latency optimization | OpenAI API
Improve latency across a wide variety of LLM-related use cases.
Part 4: Brief history of Apple ML Stack
By Mirai Labs, frontier on-device AI lab. Building the models, inference runtime, and quantization stack from the device constraint up.
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
OpenAI’s Jalapeño chip is built for fast inference at scale, benchmarks show | TechCrunch
Tested on SemiAnalysis’ InferenceX benchmark, Jalapeño registered both more tokens per user and more throughput per kilowatt than the currently available state-of-the art.

Cheng on Twitter / X
We have been expecting this since ollama's first pull request to MLX. It is just the beginning, CUDA & CPU backends are still improving and hopefully we will have one framework unifying inference & training for all platforms. https://t.co/EaBmEaNJhZ— Cheng (@zcbenz) March 31, 2026