

Tokenization and analysis pipeline for full-text search
Introduction
A complete search engine and RAG pipeline in your browser, server or edge network with support for full-text, vector, and hybrid search in less than 2kb.
Tokenization: A Survey for Modern NLP
While modern language models take raw text as their input and produce raw text as output, they do not operate over text directly. Hidden in the very first step of language model pipelines is...
Fast regex search: indexing text for agent tools · Cursor
How we're building indexes for regular expression search so agents can find text in large monorepos without the 15-second ripgrep waits.
turbopuffer: fast search on object storage
Inaugural blog post about the development of turbopuffer, a search engine that uses object storage and SSD caching for cost-effective, low latency search. This post describes into the motivation behind its creation, its unique architecture, and how it significantly reduces costs for large-scale vector searches. Discover how turbopuffer is transforming search infrastructure for companies like Cursor and Suno, offering a scalable and reliable solution.
Semble: Fast and Accurate Code Search for Agents
Fast and Accurate Code Search for Agents. Uses ~98% fewer tokens than grep+read
tantivy
Tantivy is a full-text search engine library inspired by Apache Lucene and written in Rust
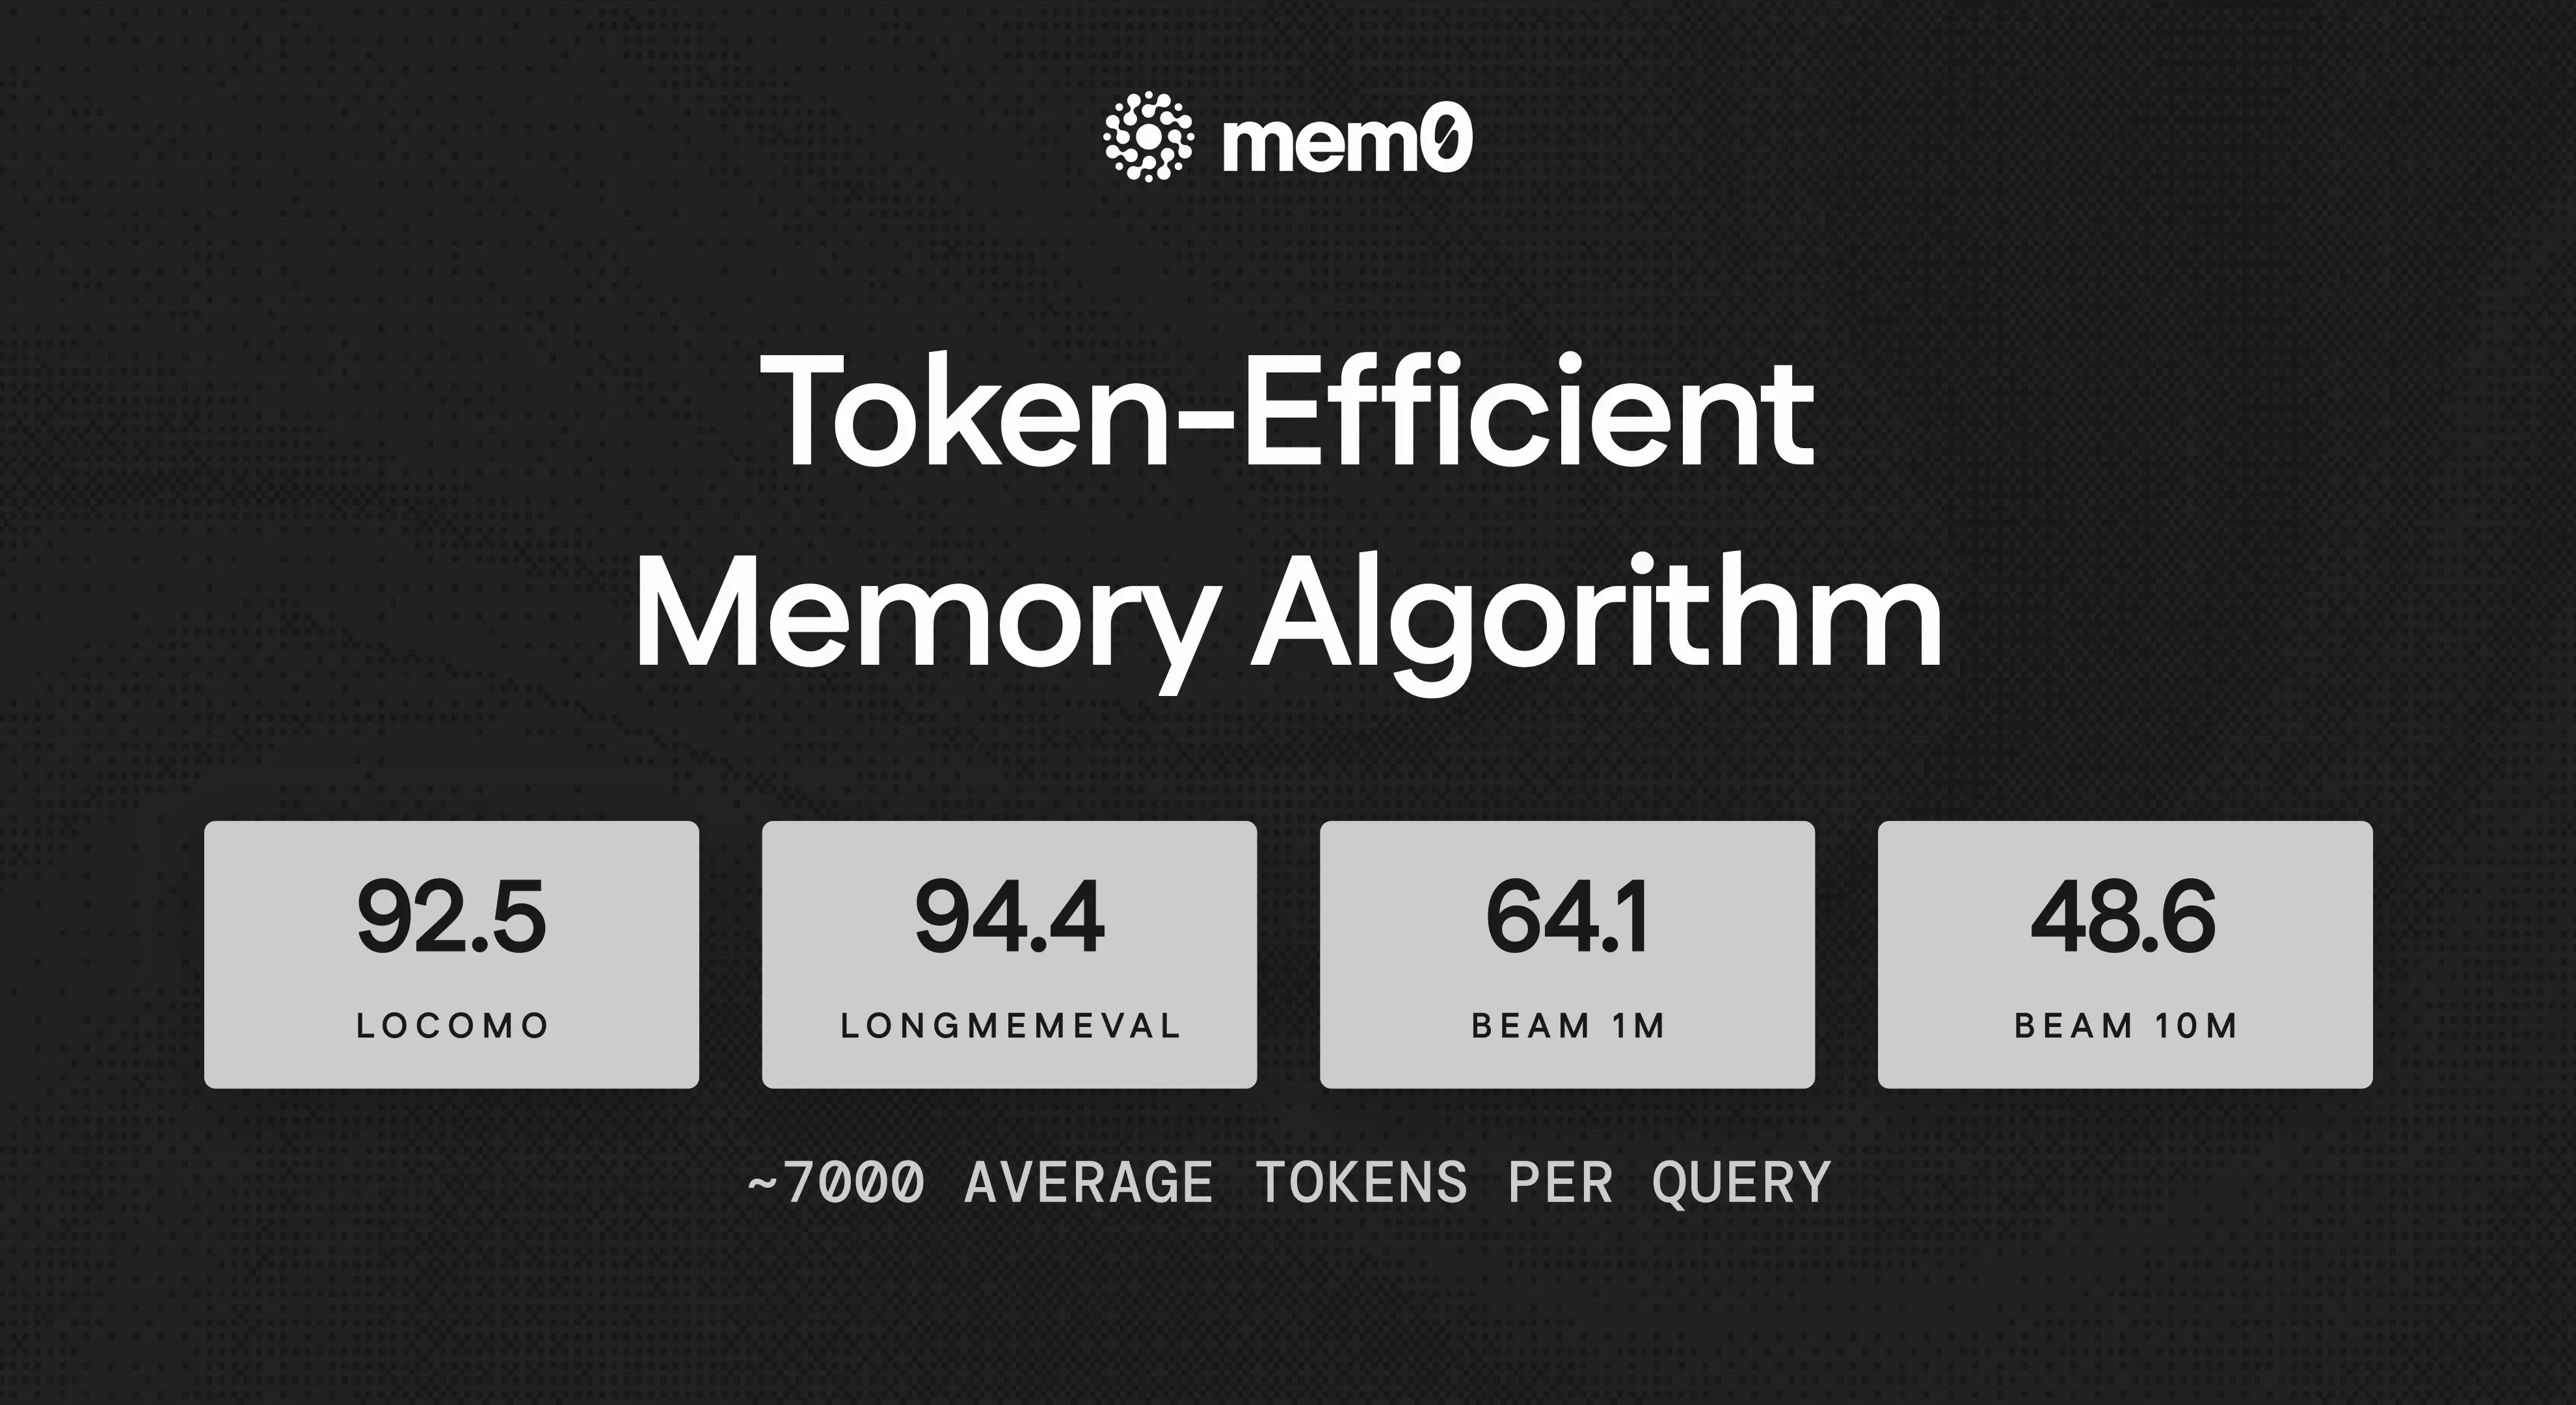
Mem0 Research Paper: Token-Efficient Memory Algorithm
Benchmarked across LoCoMo, LongMemEval, and BEAM, achieves competitive accuracy while using under 7,000 tokens per retrieval call. For comparison, full-context approaches on these benchmarks routinely consume 25,000+ tokens per query.
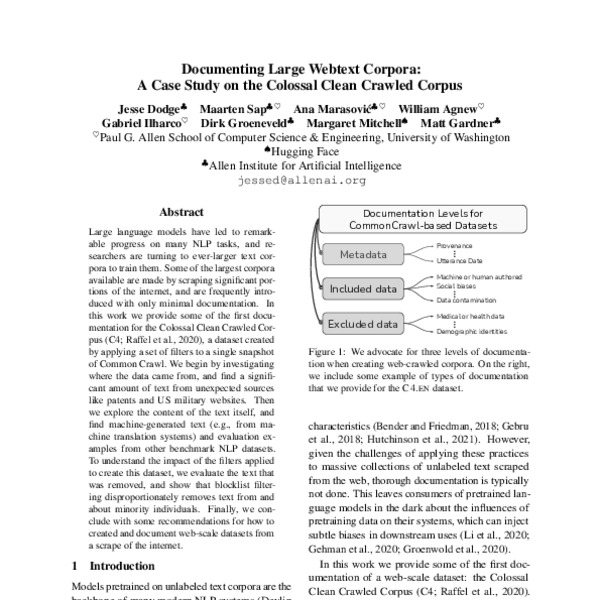
Documenting Large Webtext Corpora: A Case Study on the Colossal Clean Crawled Corpus
Large language models have led to remarkable progress on many NLP tasks, and researchers are turning to ever-larger text corpora to train them. Some of the largest corpora available are made by scraping significant portions of the internet, and are frequently introduced with only minimal documentation. In this work we provide some of the first documentation for the Colossal Clean Crawled Corpus (C4; Raffel et al., 2020), a dataset created by applying a set of filters to a single snapshot of Common Crawl. We begin by investigating where the data came from, and find a significant amount of text from unexpected sources like patents and US military websites. Then we explore the content of the text itself, and find machine-generated text (e.g., from machine translation systems) and evaluation examples from other benchmark NLP datasets. To understand the impact of the filters applied to create this dataset, we evaluate the text that was removed, and show that blocklist filtering disproportionately removes text from and about minority individuals. Finally, we conclude with some recommendations for how to created and document web-scale datasets from a scrape of the internet.
The Anatomy of a Large-Scale Hypertextual Web Search Engine
Our teams advance the state of the art through research, systems engineering, and collaboration across Google.

An 8 Year Algorithm Nemesis: Analyzing long string trends in a body of text with suffix trees
The Beginner’s Guide to Text Embeddings & Techniques | deepset Blog
Text embeddings represent human language to computers, enabling tasks like semantic search. Here, we introduce sparse and dense vectors in a non-technical way.

Why Google’s New AI-Saturated Search Page Will Be A Disaster
Google didn’t invent full-text search of the Internet – that honor belongs to early pioneers such as WebCrawler, Lycos and AltaVista. But for the last 25 years or so, Google has…
Meilisearch: Unified Search & AI Retrieval Platform
Build lightning-fast search and AI retrieval with Meilisearch. Open-source, developer-friendly search engine trusted by 20,000+ teams worldwide.
Deep Dive into ParadeDB's v2 API: The Future of SQL Search
Explore ParadeDB's v2 API that eliminates schema duplication, simplifies tokenization, and provides transparent search operators for intuitive SQL-based full-text search.
Finding real, quotable examples is key to my blog writing workflow. Because Google and the default web search produce a lot of junk, I use Exa, HackerNews, web search, what I've already written, and internal company docs to do this, and I recently added @semble.so to this stack.
