

2.24x decode TPS increase On Qwen 3.6 27B @ temp 0.6 | Native MTP Speculative Decoding On Apple Silicon With No External Drafter.
LM Studio 0.3.10: 🔮 Speculative Decoding
Inference speed up with Speculative Decoding for `llama.cpp` and `MLX`
Joel - coffee/acc on Twitter / X
OKAY - it seemed like DFlash would be the clear winner.But it appears there have been some improvements with MTP.With MTP + split-mode = tensor, Qwen3.6-27B gets over 120 tokens/second on dual RTX 3090s (note I am running PCIE x16 on both, I don't have an NVLink bridge).… https://t.co/AQmqTJrof7 pic.twitter.com/RQSPVsNwMO— Joel - coffee/acc (@JoelDeTeves) June 29, 2026

Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
Jun Kim on Twitter / X
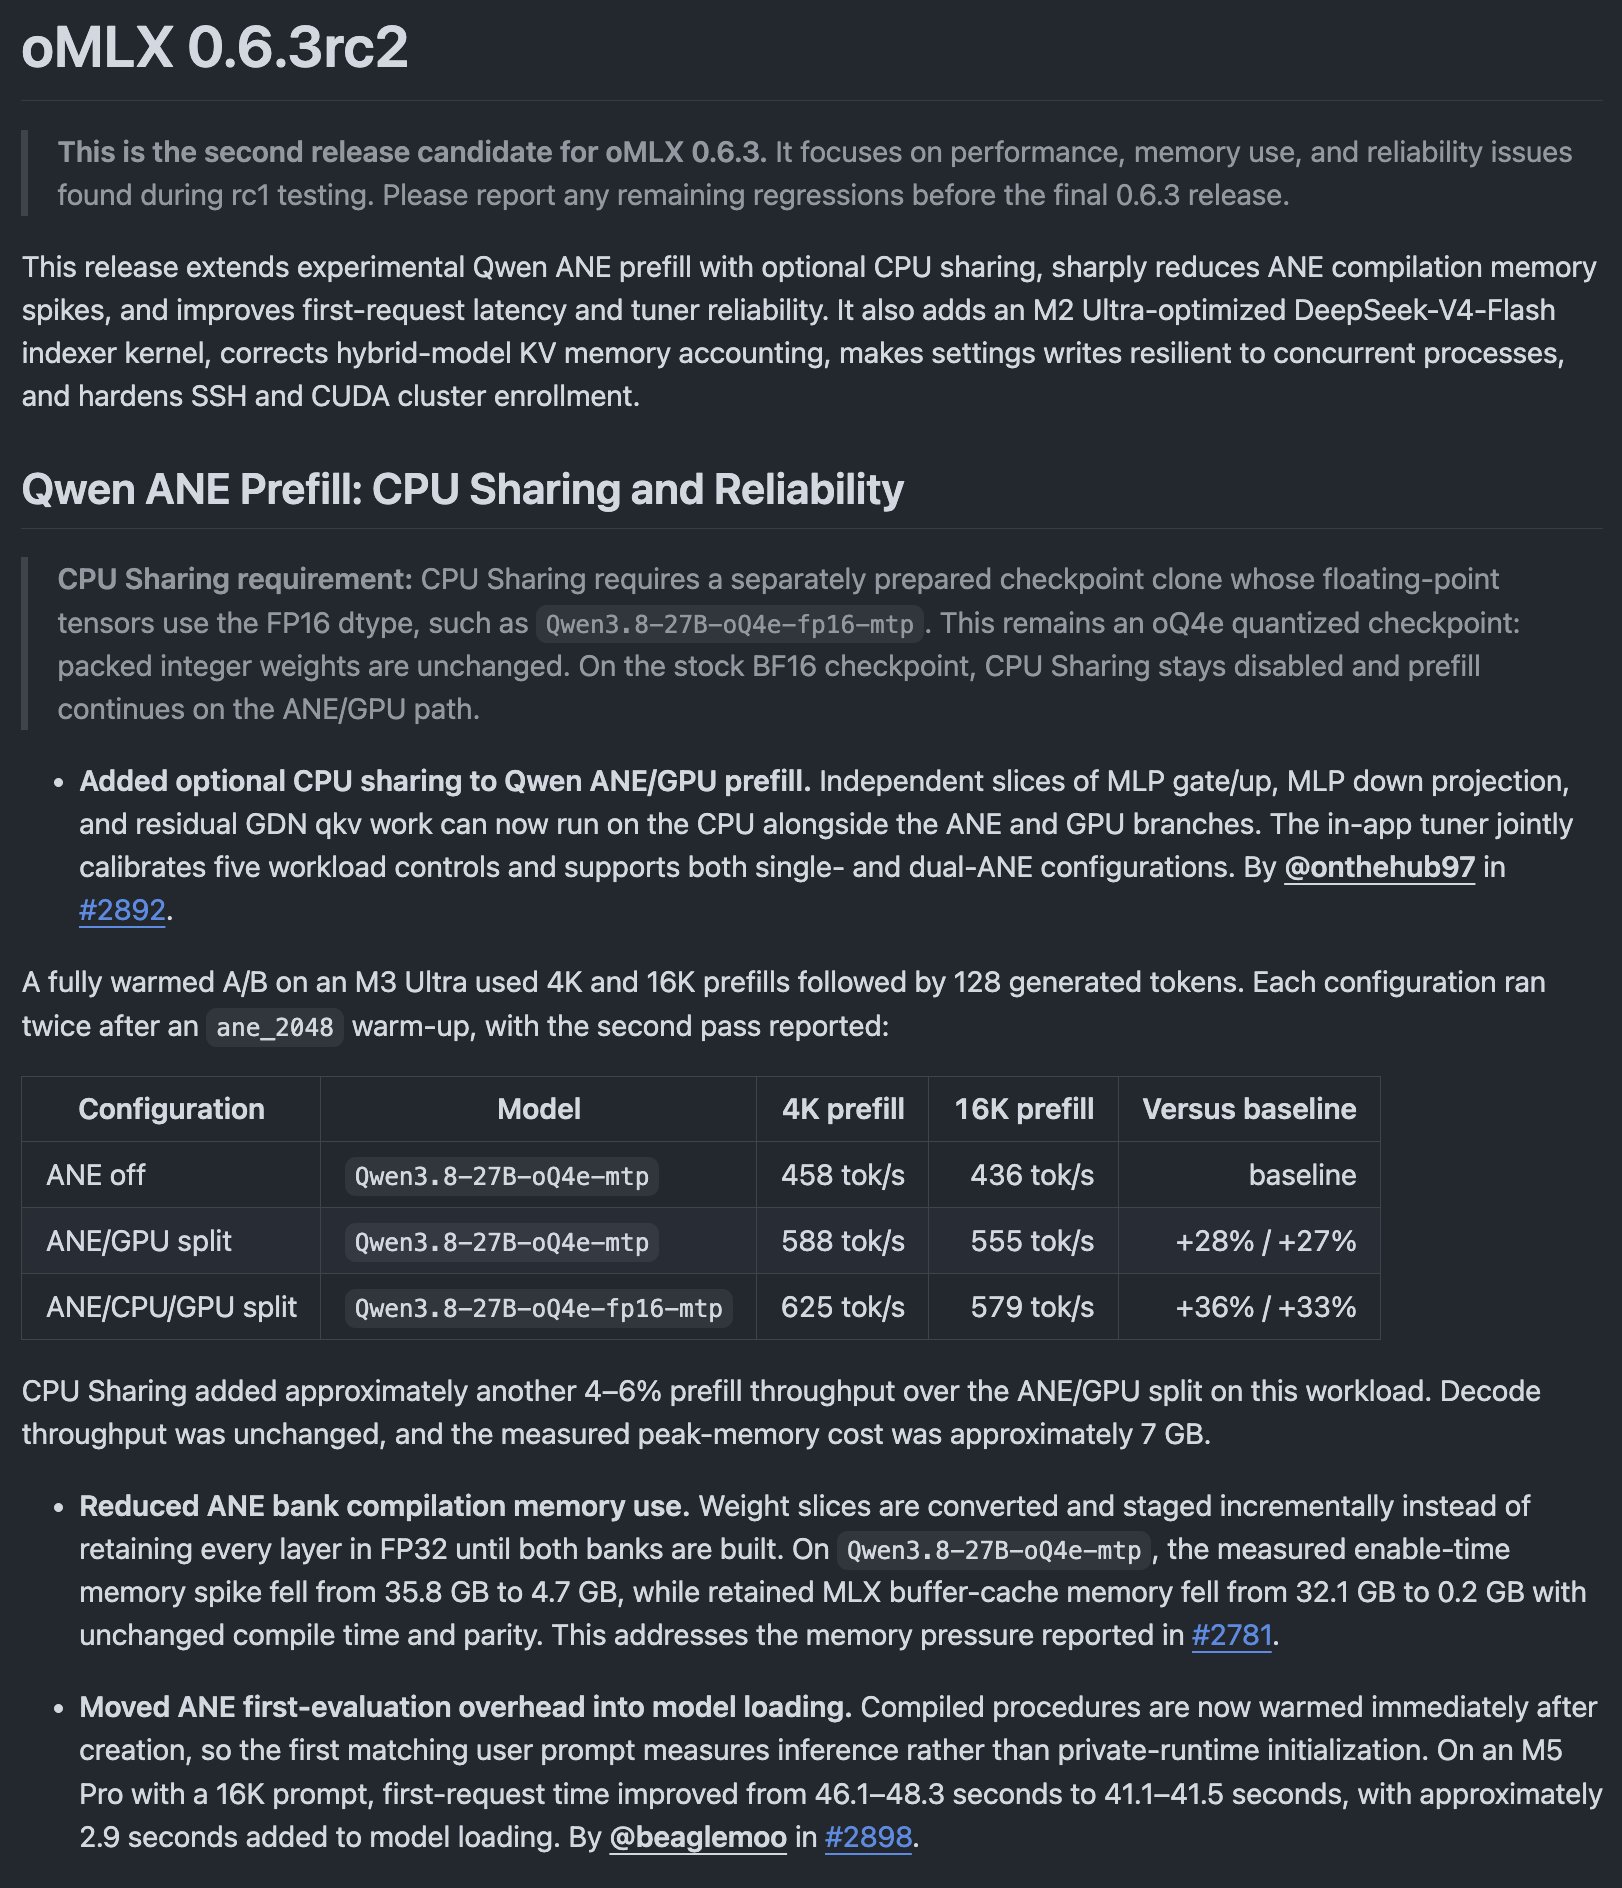
oMLX 0.6.3rc2 is out, and the experimental GPU + ANE + CPU path I mentioned yesterday is now part of it. If you are curious and would like to help test it with us, you can join here: https://t.co/yXYUKqvmHZOn my M3 Ultra, using Qwen3.8-27B-oQ4e-mtp and its FP16-dtype clone at… pic.twitter.com/UAIlu8r4ZA— Jun Kim (@jundotkim) August 20, 2026
tanishqkumar/ssd
A lightweight inference engine supporting speculative speculative decoding (SSD).
0xSero on Twitter / X
Are you compute poor? Do you want to run Qwen3.8-27B? Dude, if you have 8-16gb of vram or 16-24gb of MacOS memory this is by far the smartest model you can runPrimML is doing something phenomenal, they've created a ternary version of Qwen3.8-27B9x smaller 98.2% as smart! https://t.co/rtmNCsIQbA— 0xSero (@0xSero) September 17, 2026
noname on Twitter / X
Upto 1100 tps on RTX 3090x2 for Diffusion Gemma 4 26B.Unleash this mini monster on your gpus now!If you are running nvidia gpus locally, come grab the recipe at club-3090. https://t.co/qKuFcgu1llP.S. a ⭐️ on Github is much appreciated.@googlegemma @vllm_project— noname (@malikwas1f) June 11, 2026
the tiny corp on Twitter / X
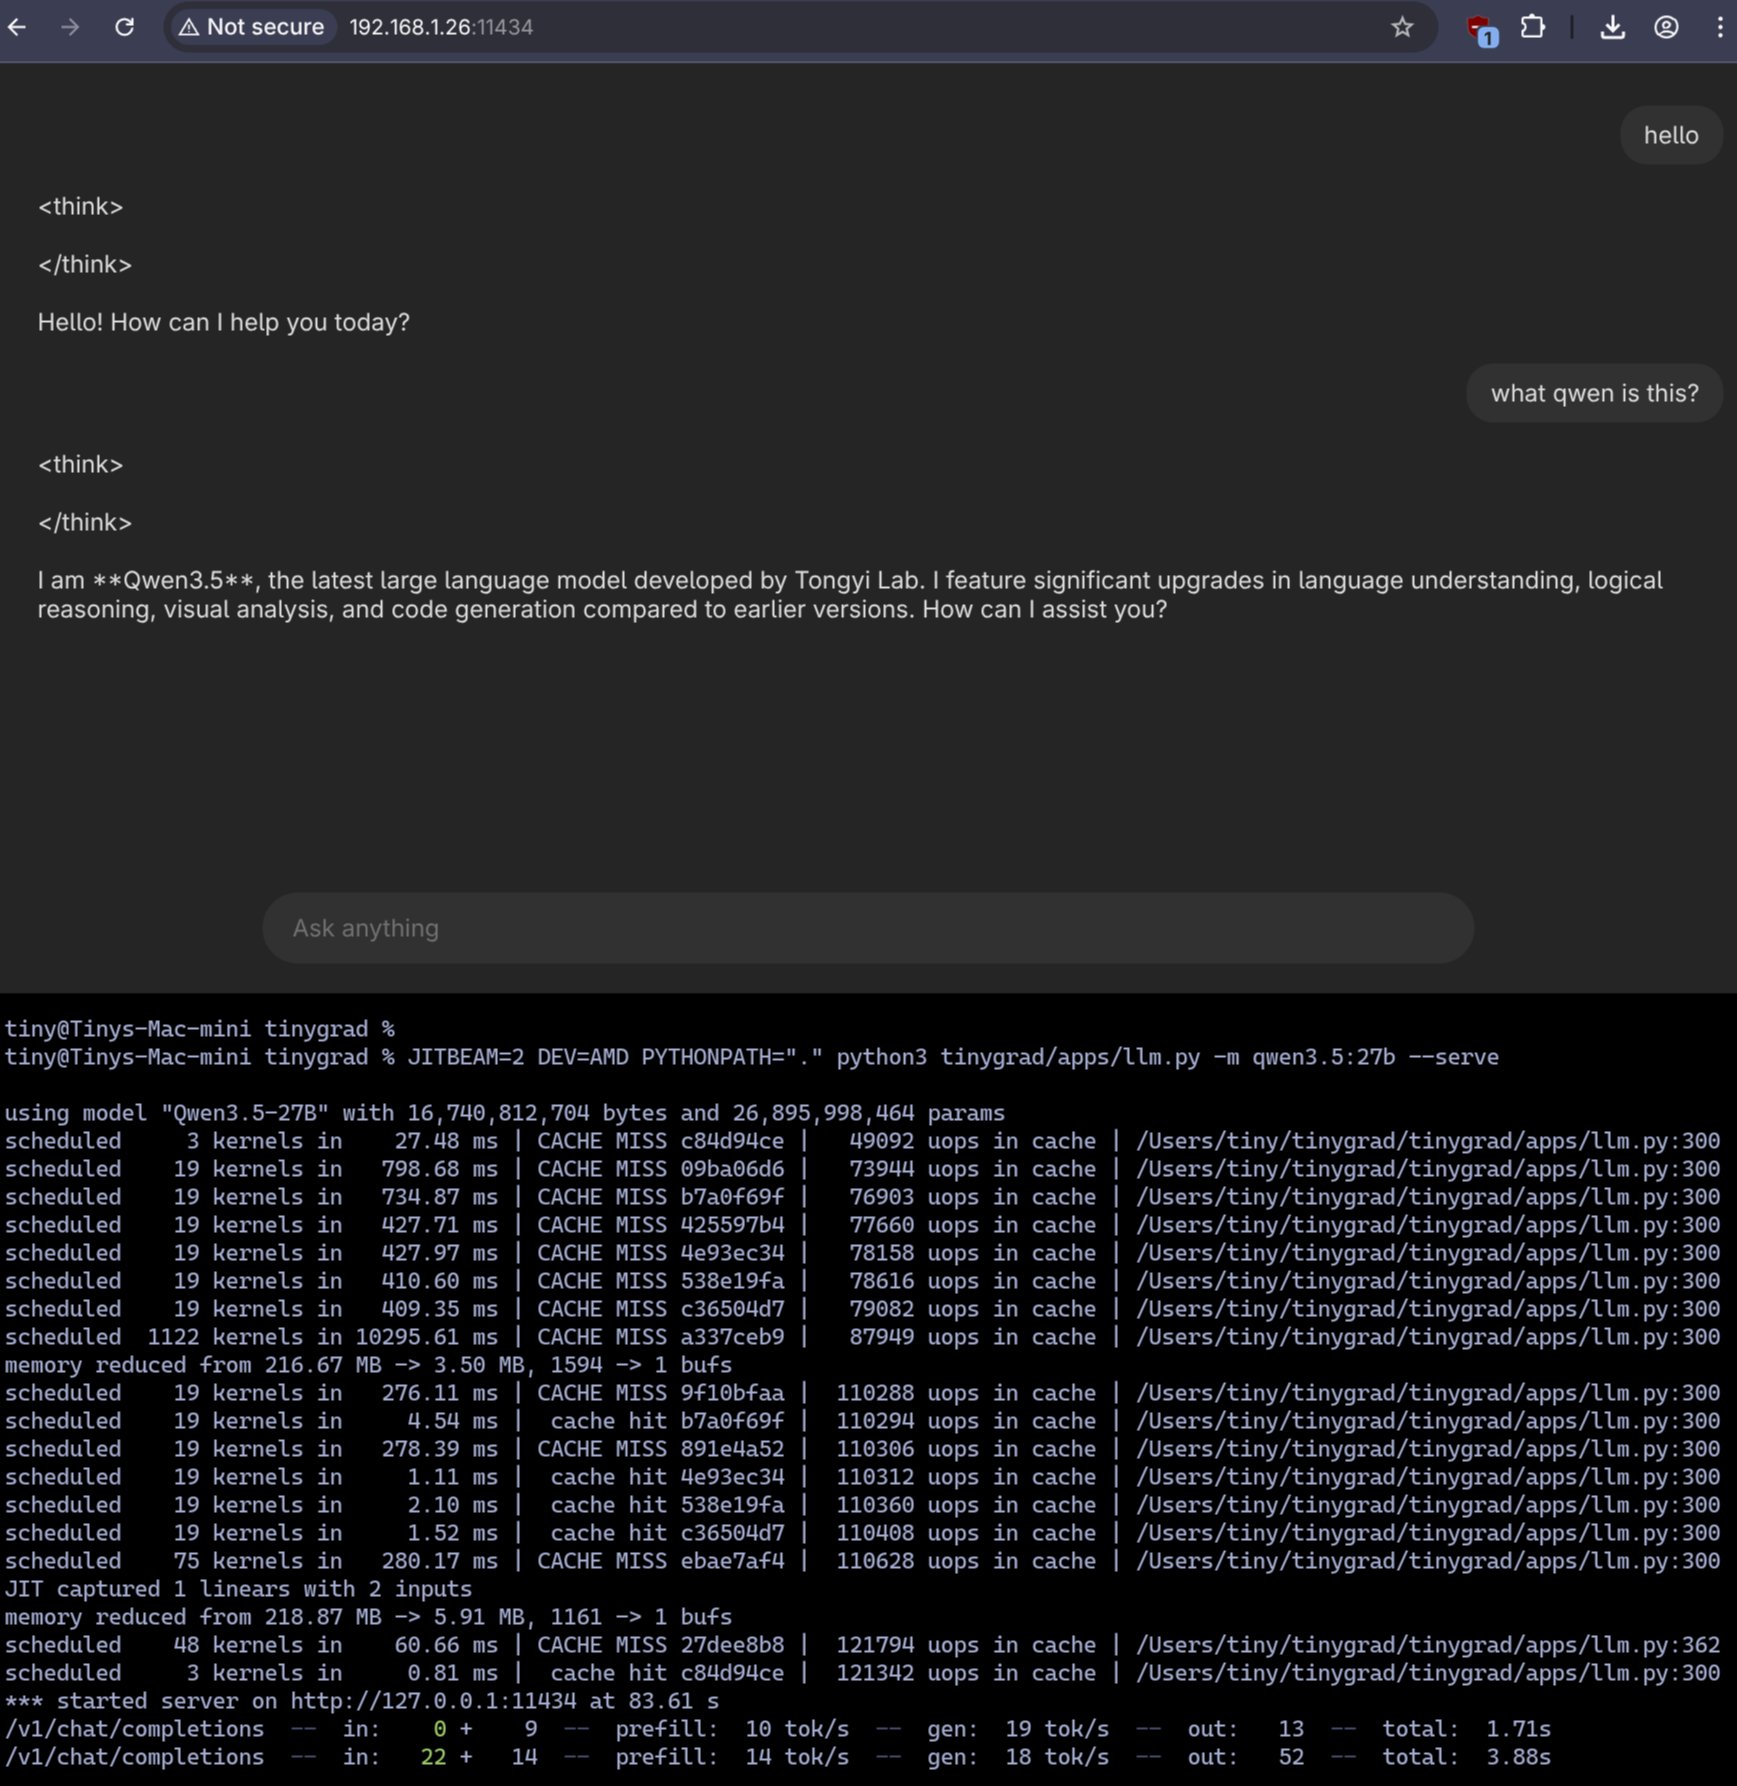
Qwen 3.5 27B getting 18.5 tok/s on Mac Mini with external 7900XTX. It should be able to be 3x faster than this with work, SSM stuff is still in PR. Hopefully Mac eGPU support brings in devs. pic.twitter.com/2aMkUpXY1S— the tiny corp (@__tinygrad__) April 1, 2026
AMD and Anthropic Announce Strategic Partnership to Deploy Up to 2 Gigawatts of AMD Instinct MI450 Series GPUs
News Highlights Anthropic to deploy up to 2 gigawatts of MI450 Series GPUs in AMD Helios rack-scale solutions, with deployment of the first…...
Mia on Twitter / X
Fast and Furious ⚡️Update your DeepSeek v4.1 Flash on 3x DGX Sparks- Prose decode tok/s improved by 17%- Code decode tok/s improved by 39%- Mixed decode tok/s improved by 29%Prose single stream is now 50+ tok/s and 85 tok/s at 4 concurrent streams.Changes to 4x DGX… pic.twitter.com/0cMC1kgvDR— Mia (@MiaAI_lab) September 24, 2026
Taelin on Twitter / X
aaand it is now 1280x fasterQuickSort is synthesized in 6 seconds now, in a single thread(down from 20 seconds with 256 threads!)that's by not matching accumulator arguments - which is wasteful. I implemented that in preparation for a "NeoGen Net" experiment. everything is… https://t.co/qdwkiQbRnI— Taelin (@VictorTaelin) April 13, 2025
Tiles version 0.4.17 Alpha 21 has been released. The new default model is Gemma 4 12B, using Unsloth’s Q4_K_M GGUF. Added quantization tags to Modelfiles and automatic MTP decoding. Upgraded Pi to upstream v0.84.2, plus minor fixes for macOS notarization and GGUF model downloads. Release notes ↗

Shared chat session by @tiles.run | Tiles
chat.tiles.runGemma 4 now runs 2x faster with MTP GGUFs! Run locally on just 6GB RAM. ⚡️ MTP enables Google Gemma 4 run ~1.4–2.2× faster with no accuracy loss. Gemma 4 12B MTP can run at 162 t/s vs. 52 t/s without MTP. 31B reaches 101 t/s. GGUFs + Guide: unsloth.ai/docs/models/mtp
Tiles version 0.4.19 Alpha 23 has been released. MTP is now opt-in, with a new --mtp flag for tiles run and persistent configuration under [llama]. Inference server warnings are now surfaced in the CLI, and fixed an issue where tiles update could install multiple versions. Release notes ↗
Shared chat session by @tiles.run | Tiles
chat.tiles.run
