

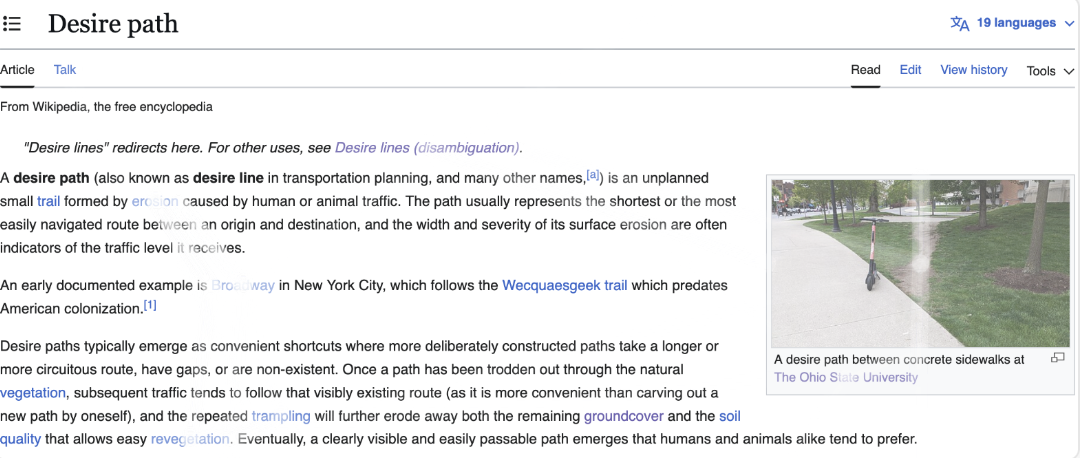
An extension that remembers the path of a cursor over the linked pages of Wikipedia, “wearing” them into the page.
Jared Goering on Twitter / X
Saw this and immediately built it. Open-sourced the whole thing:Ingest URLs, PDFs, tweets, images → LLM compiles a linked markdown wiki → Q&A with citations, knowledge graph, contradiction linting, auto-research, export to HTML/PDF/slides.Been using it nonstop as a personal… https://t.co/ypaXlEA7pn pic.twitter.com/8Z2DLAyQjH— Jared Goering (@jaredgoering) April 4, 2026
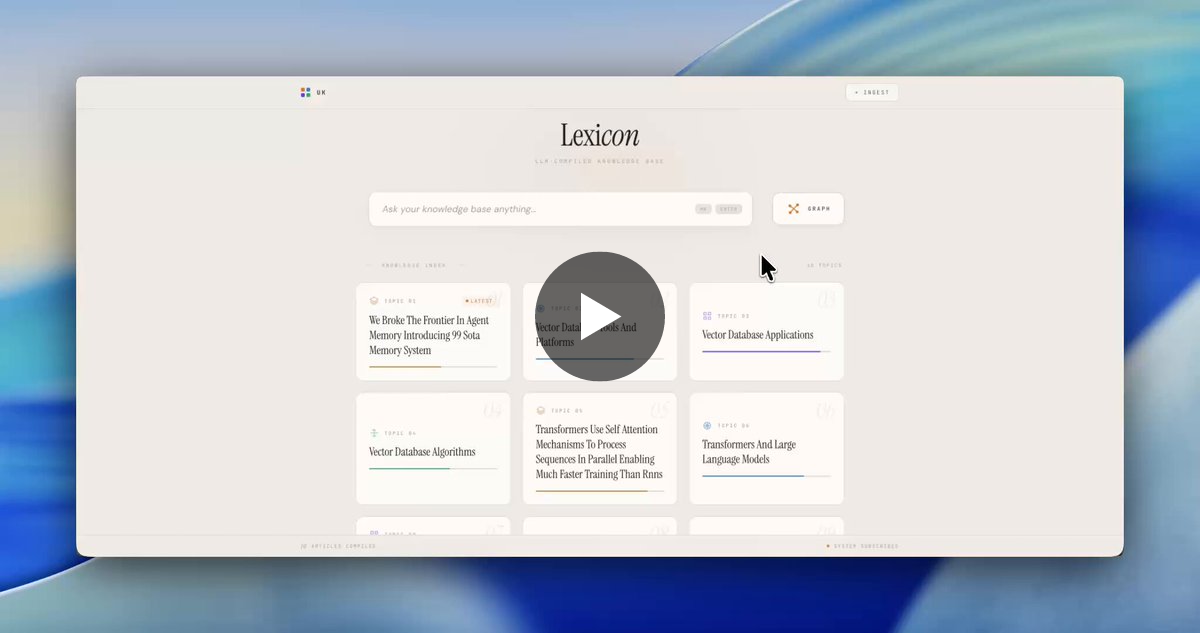

Freeing the Web from the Browser | reinterpretcast.com
The Web is, without a doubt, the most powerful research tool currently available to man. No longer must researchers comb through endless indices and catalogues to find what they are looking for. Instead, hyperlinks allow users to associatively explore rich interconnected structures of information with ease. In just a few clicks, it is possible to navigate through a vast global space of information comprising documents on virtually any subject.
Declare and resolve website links for at:// URIs. A demo of the me.byjp.atproto.deeplink lexicons.
Mustard
A browser extension that lets you annotate any webpage with notes and share them with your Bluesky and/or GitHub followers.
Solutions for Link Rot on the Modern Web
Web links are fundamental to the web, enabling navigation between pages and citations in research articles. However, web links suffer from "link rot", a phenomenon in which links are likely to become inaccessible over time. This can occur if a link’s site disappears, making it impossible to resolve the hostname or establish a server connection, or the linked page has been deleted, resulting in an HTTP 404 "Not Found" error. Today, a common solution to tackle link rot is to rely on web archives, which capture snapshots of web pages for future reference. However, the modern web has evolved significantly since web archives were first introduced, leading to several limitations in their effectiveness. First, the scale of the web has grown tremendously, making it infeasible to crawl every page whenever it changes. As a result, many broken links either have no archived copies, or the archived copies have stale content. Second, modern web pages rely heavily on increasingly complex and diverse JavaScript. This shift has made it more challenging for preserving fidelity in archived copies, significantly increasing both the computational cost of operating browser-based crawlers and engineering effort required to maintain accurate replay systems. This thesis presents a set of solutions to cope with link rot on the modern web. My work aims to mitigate the various limitations of web archives. First, for broken links without any archived copy, or if the archived copy includes stale content or unavailable functionalities, I built Fable. Fable revives the dead link with the new URL to the same page whenever available. Compared to prior approaches, Fable revives 4.6K broken links—a 50% increase—with much higher accuracy. Second, for pages that require dynamic crawling, I show how web archives can achieve a better tradeoff between efficiency and fidelity. By carefully choosing 8.9% of pages to crawl dynamically and strategically reusing resources from those crawls, an archive can serve 99% of the remaining statically crawled pages without any fidelity loss. Third, for fidelity violations in archived copies that are caused by incorrect edits to crawled scripts, I built FidEx. FidEx reliably detects when an archived page differs from its original version and pinpoints the root cause. After fixing the most common errors pinpointed by FidEx, I reduced the fraction of pages for which FidEx reports a violation of fidelity from 15% to 9%.
linkding
A self-hosted bookmarking service that is designed to be minimal, fast and easy to set up.
this is also a thing, but separate from the basic website stuff anna is talking about. the at:// potential is sort of about navigating to that sort of URI in browser bar. but I think more realistically, having anchor links. <a atref="at://..."> (or more realistically: data-atp="at://...")


