

Archiving the Web, because nothing lasts forever: statistics, online archive services, extracting URLs automatically from browsers, and creating a daemon to regularly back up URLs to multiple sources.
Solutions for Link Rot on the Modern Web
Web links are fundamental to the web, enabling navigation between pages and citations in research articles. However, web links suffer from "link rot", a phenomenon in which links are likely to become inaccessible over time. This can occur if a link’s site disappears, making it impossible to resolve the hostname or establish a server connection, or the linked page has been deleted, resulting in an HTTP 404 "Not Found" error. Today, a common solution to tackle link rot is to rely on web archives, which capture snapshots of web pages for future reference. However, the modern web has evolved significantly since web archives were first introduced, leading to several limitations in their effectiveness. First, the scale of the web has grown tremendously, making it infeasible to crawl every page whenever it changes. As a result, many broken links either have no archived copies, or the archived copies have stale content. Second, modern web pages rely heavily on increasingly complex and diverse JavaScript. This shift has made it more challenging for preserving fidelity in archived copies, significantly increasing both the computational cost of operating browser-based crawlers and engineering effort required to maintain accurate replay systems. This thesis presents a set of solutions to cope with link rot on the modern web. My work aims to mitigate the various limitations of web archives. First, for broken links without any archived copy, or if the archived copy includes stale content or unavailable functionalities, I built Fable. Fable revives the dead link with the new URL to the same page whenever available. Compared to prior approaches, Fable revives 4.6K broken links—a 50% increase—with much higher accuracy. Second, for pages that require dynamic crawling, I show how web archives can achieve a better tradeoff between efficiency and fidelity. By carefully choosing 8.9% of pages to crawl dynamically and strategically reusing resources from those crawls, an archive can serve 99% of the remaining statically crawled pages without any fidelity loss. Third, for fidelity violations in archived copies that are caused by incorrect edits to crawled scripts, I built FidEx. FidEx reliably detects when an archived page differs from its original version and pinpoints the root cause. After fixing the most common errors pinpointed by FidEx, I reduced the fraction of pages for which FidEx reports a violation of fidelity from 15% to 9%.
Webrecorder: Web Archiving for All
Webrecorder provides open source solutions for everyone to archive the complex, interactive Web.
Archiving web sites
I recently took a deep dive into web site archival for friends who were worried about losing co [...]
Archival | Content-First Websites
Archival is the simplest way to build an easy-to-maintain website for your business, product, or brand.
archive.today
archive.today is a web archiving website that saves snapshots on demand. It has support for JavaScript-heavy sites such as Google Maps and X.com. archive.today records two snapshots: one replicates the original webpage including any functional live links; the other is a screenshot of the page.

Archivist - Storage That Can't Be Stopped
Archivist is a decentralized durable storage network. Data is encrypted, erasure-coded, and dispersed across independent operators. Verified by zero-knowledge proofs. Sovereign storage that survives censorship, provider failure, and time.
webrecorder/browsertrix-crawler
Run a high-fidelity browser-based web archiving crawler in a single Docker container
On Link Rot
The web suffers from link rot: hyperlinks that were valid upon creation will often point into nothingness after some time has passed. Within the framework of the web, the typical solution is to link to a snapshot of the original page, hosted on archive.org.
On Link Rot
The web suffers from link rot: hyperlinks that were valid upon creation will often point into nothingness after some time has passed. Within the framework of the web, the typical solution is to link to a snapshot of the original page, hosted on archive.org.
Freeing the Web from the Browser | reinterpretcast.com
The Web is, without a doubt, the most powerful research tool currently available to man. No longer must researchers comb through endless indices and catalogues to find what they are looking for. Instead, hyperlinks allow users to associatively explore rich interconnected structures of information with ease. In just a few clicks, it is possible to navigate through a vast global space of information comprising documents on virtually any subject.
ArchiveBox
ArchiveBox is a self-hosted app that lets you preserve content from websites in a variety of formats.
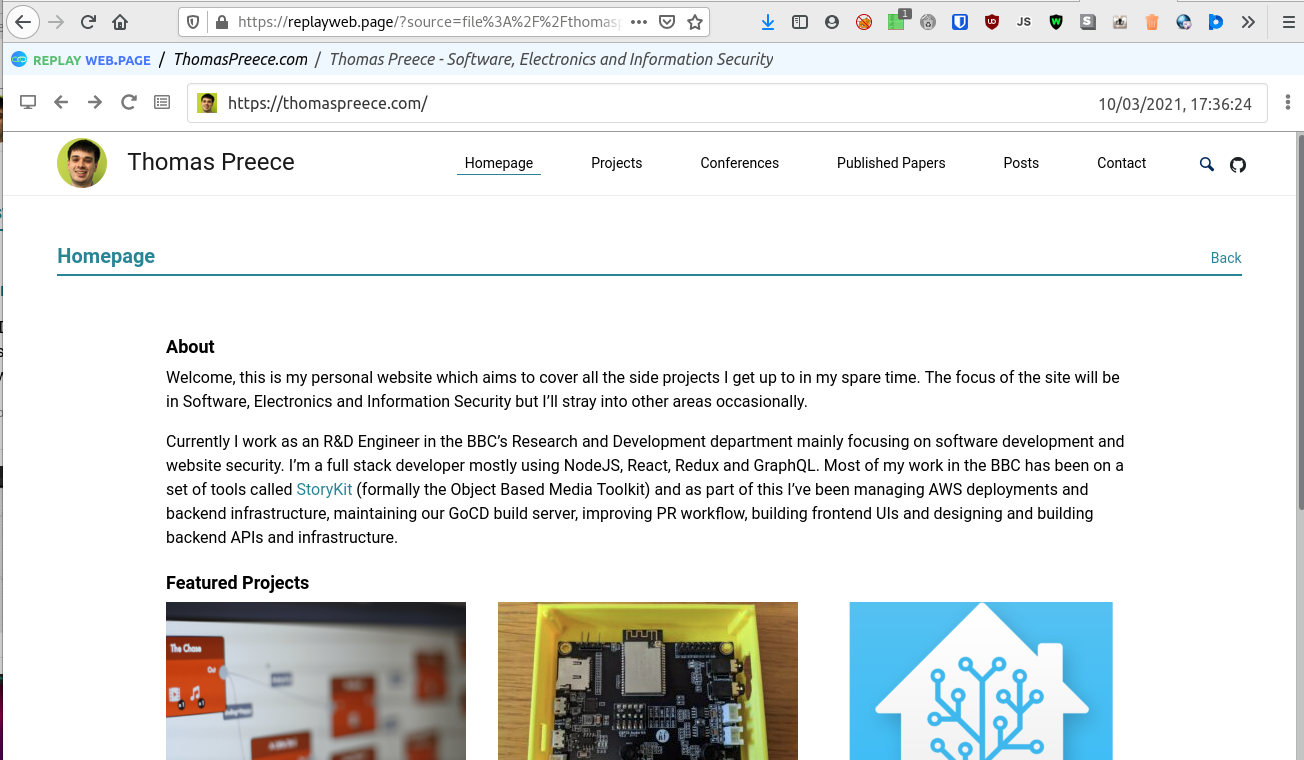
Web Archiving: Playback Tools - Thomas Preece
Web Archiving: Playback Tools - Below I've listed some of the tools I found to playback web archives. The two most popular tools that I found were OpenWayback and PyWb. Of the tests I
My journey to the heart of the forgotten internet
Slowly but surely, huge swaths of the internet are vanishing. But the artefacts of the early web are still out there, and they have lessons for the future.

Quit (using) Archive.today

This is *not* the Internet Archive/Wayback Machine (archive.org), but rather archive.today aka archive.is aka archive.fo aka archive.li aka archive.md aka archive.ph aka archive.vn (Don’t click on the links; kept the URLs intact for searchability) Separated out into its own collection for sharing convenience
WikipediaがDDoS攻撃疑惑を受けアーカイブサービスのArchive.todayをブラックリストに追加

archive.today is directing a DDOS attack against my blog
Wikipedia:archive.today guidance
This is *not* the Internet Archive/Wayback Machine (archive.org), but rather archive.today aka archive.is aka archive.fo aka archive.li aka…

The headline does not convey how completely batshit this story is. The Archive Today (archive.ph etc) admin weaponized the site's captcha to…
Wikipedia blacklists Archive.today, starts removing 695,000 archive links