

Learnings from Sentry's data and why web discoverability as a whole shifted our strategy.
Brandon Stewart on Twitter / X
1/ New @Nature! We study how powerful institutions shape the information environment for LLMs. Commercial LLM training is opaque, so we trace a path from state-coordinated media -> training data -> model responses. pic.twitter.com/5LdFvzbFaf— Brandon Stewart (@b_m_stewart) May 13, 2026
Dan Shipper 📧 on Twitter / X
this is true and is a big reason why you don’t need to be a highly technical researcher to use LLMs in surprising and novel ways https://t.co/TuxNzXzToU— Dan Shipper 📧 (@danshipper) July 27, 2025
Andrej Karpathy on Twitter / X
LLM Knowledge BasesSomething I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating…— Andrej Karpathy (@karpathy) April 2, 2026
State of AI 2025: 100T Token LLM Usage Study | OpenRouter
Read OpenRouter's 2025 State of AI report — an empirical 100 trillion token study of real LLM usage, model trends, and developer insights.
Philipp Schmid on Twitter / X
Should we build the web for agents, not agents for the web? 🤔 A new paper argues that current research is misguidedly focuses on improving LLMs leading to significant problems with efficiency, reliability, and safety, proposing a new "Agentic Web Interface" (AWI) that sits on… pic.twitter.com/I90k6kdYdk— Philipp Schmid (@_philschmid) June 14, 2025

The Big Reverse of the Web
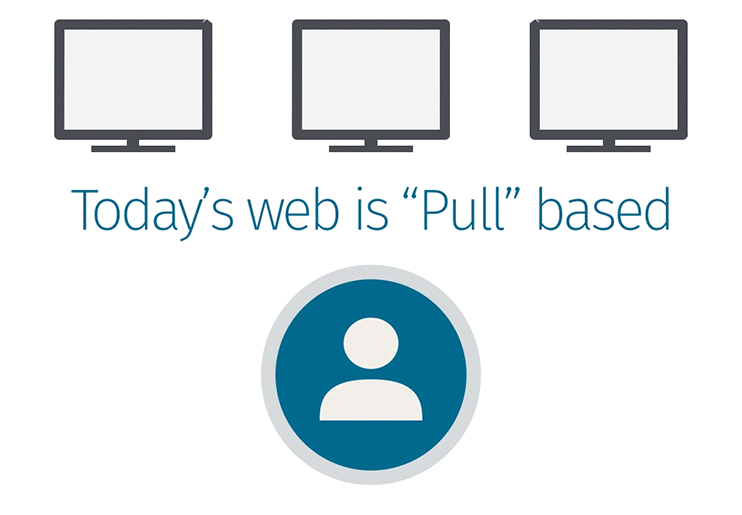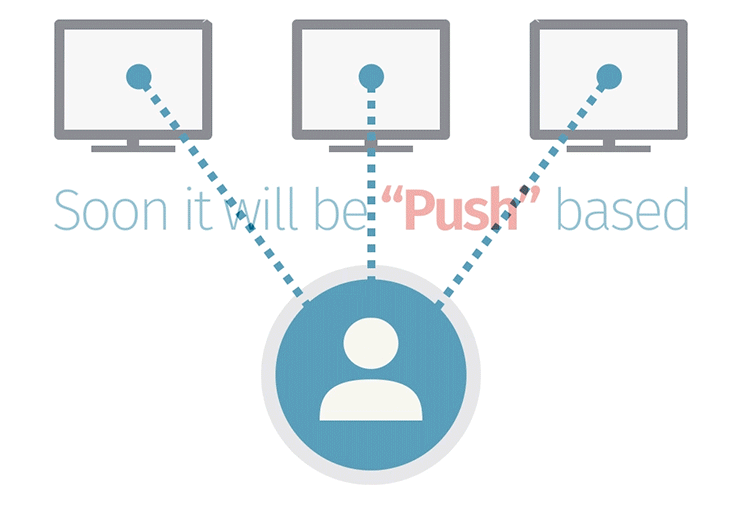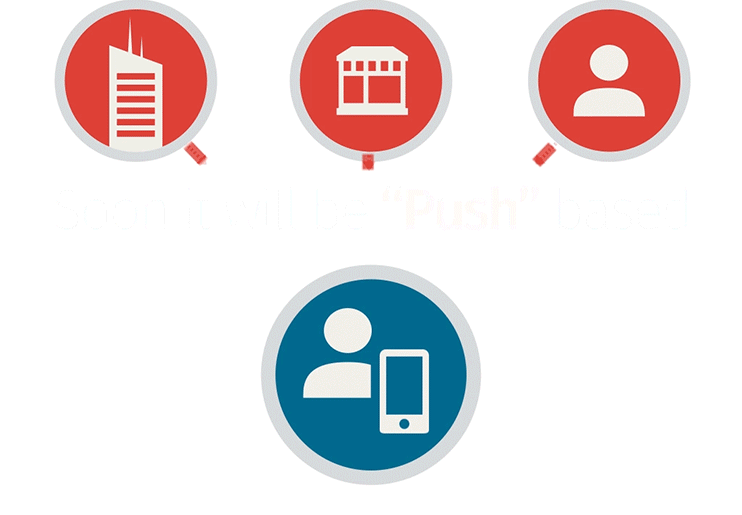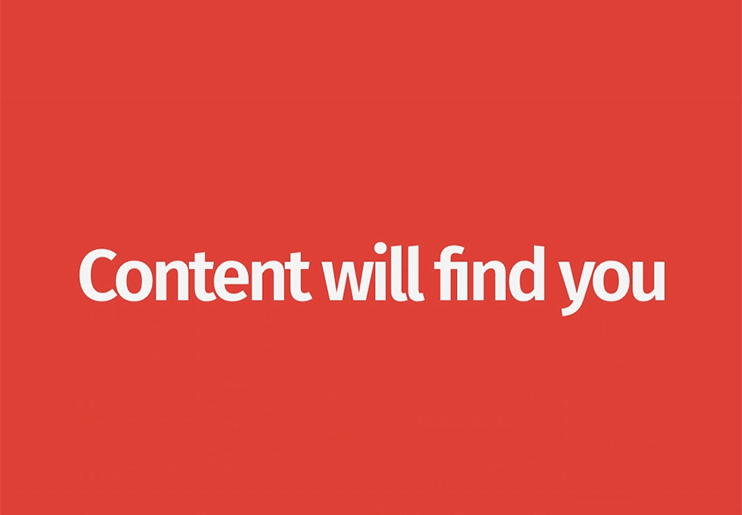
We are at the beginning of a massive re-architecture of the web where we go from "pull" to "push". Eventually, content will find us.
My journey to the heart of the forgotten internet
Slowly but surely, huge swaths of the internet are vanishing. But the artefacts of the early web are still out there, and they have lessons for the future.

Meet the Pirates of the RAG: Adaptively Attacking LLMs to Leak Knowledge Bases
Meet the Pirates of the RAG: Adaptively Attacking LLMs to Leak Knowledge Bases

himanshu on Twitter / X
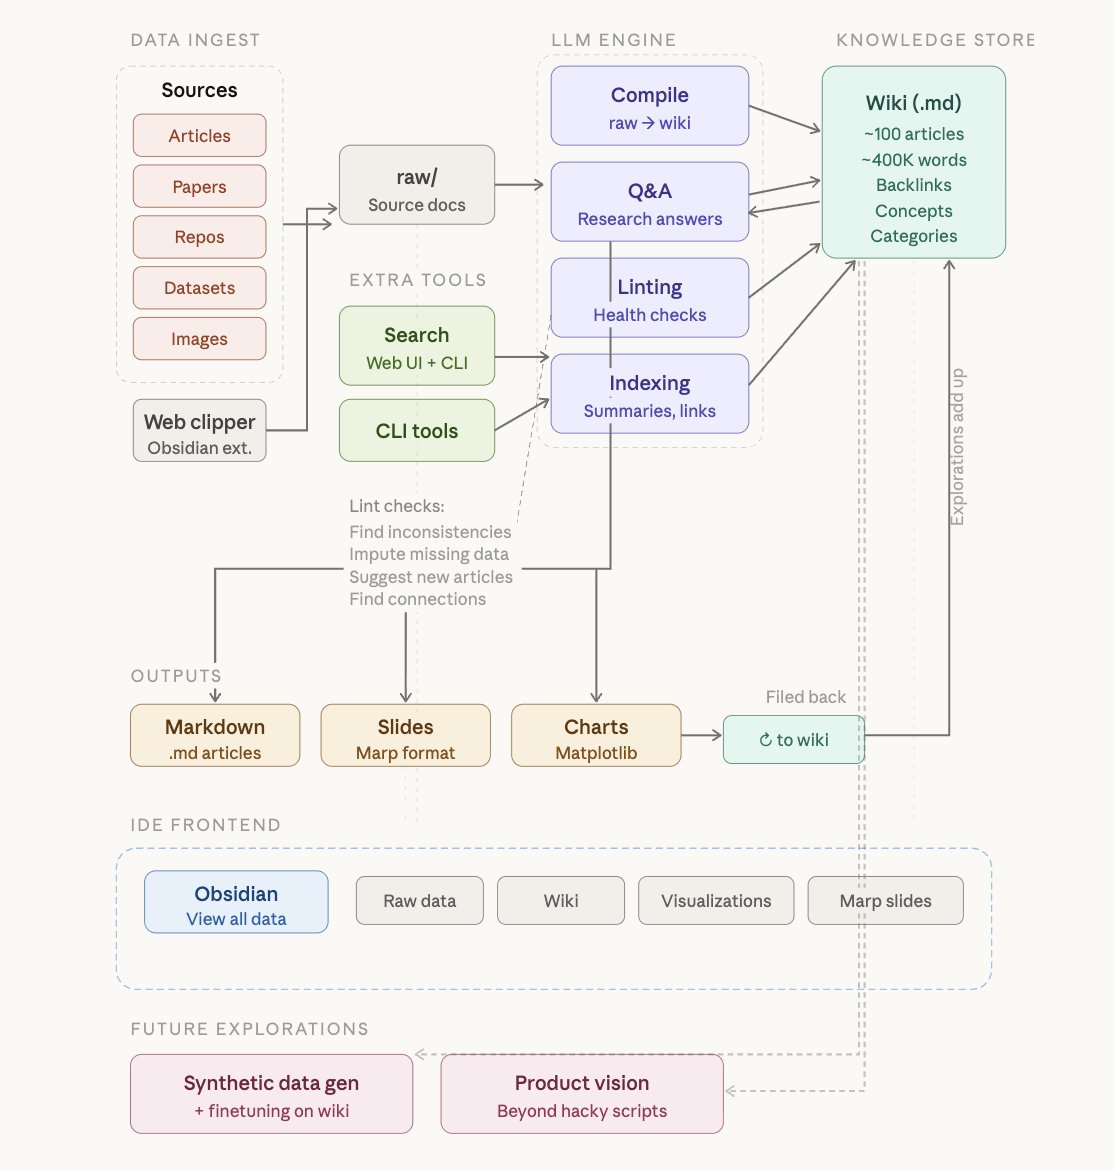
and here is the full architecture of the LLM Knowledge Base system covering every stage from ingest to future explorations. https://t.co/Wmn48gB0g0 pic.twitter.com/ObJet8Esfu— himanshu (@himanshustwts) April 2, 2026
Making Content from Discoverable Servers Easier to Discover
Starting on November 16, 2026, conversations in Discoverable Servers will be easier to find for people searching the web. Admins can choose which channels are surfaced on the web. Private servers, DMs, and GDMs are not included.

Semble: Collective knowledge foraging in trail-based social networks beyond feeds (Lightning Talk)
LLM Rankings | OpenRouter
LLM rankings and AI leaderboard based on benchmarks and real usage data from millions of users. See which AI models developers actually use.
The State of the Web at Google I/O 2018
The web is a global treasure, and has many strengths we all enjoy. It is a distribution platform like no other, providing people around the ...

Notion’s Knowledge Board
Evaluating how models perform across a range of knowledge work tasks, using live anonymized traffic and judged by models from Anthropic, OpenAI, and Google. An ongoing experiment.
elvis on Twitter / X
Diagram of the LLM Knowledge Base system.Feed this to your favorite agent and get your own LLM knowledge base going. https://t.co/4AQSFOv4PV pic.twitter.com/nPSNi4Ayqv— elvis (@omarsar0) April 3, 2026

I've been shouting for a long time about how LLMs-as-search despoils our information ecosystem, which among other things puts our democracy at risk. Here is a very direct example of that: washingtonpost.com/technology/2026/10/24/we-aske… >>

We asked AI chatbots to make voter guides. They invented races and misidentified candidates.
www.washingtonpost.com