This tool estimates and visualizes the throughput of Large Language Models on devices with memory bandwidth constraints. Users input device and model configurations, and the tool generates a plot s...
Qalculate! - the ultimate desktop calculator
Previewing Ultrafast mode: GPT-5.6 Sol at up to 14X the speed
Preview Ultrafast, a new OpenAI API service tier that runs GPT-5.6 Sol up to 14× faster. Powered by Cerebras, it delivers up to 750 output tokens per second.
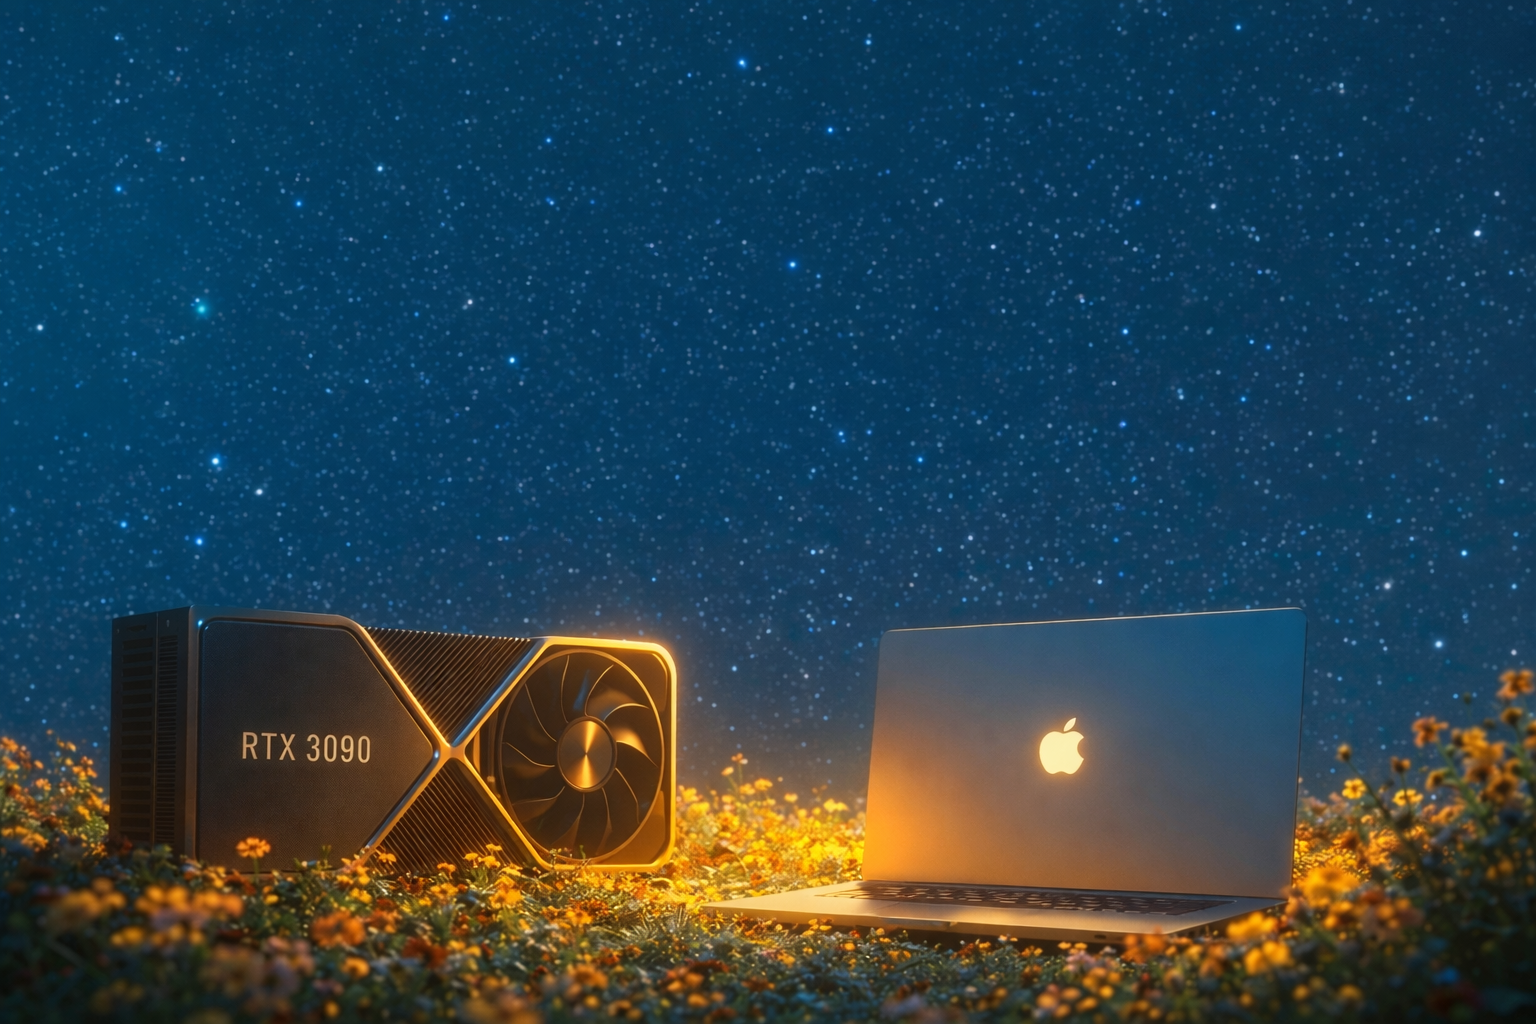
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
KaTeX – The fastest math typesetting library for the web
Simple API, no dependencies – yet super fast on all major browsers.
SpeedCurve by Embrace | Website Performance Monitoring
User focused observability for mobile and web. See how people experience the speed of your website, then identify and fix performance issues.
Faster double-to-string conversion
There comes a time in every software engineer’s life when they come up with a new binary-to-decimal floating-point conversion method. I guess my time has come. I just wrote one, mostly over a weekend: https://github.com/vitaut/zmij.
The Complete Power Automate Functions List - Matthew Devaney
A cheat sheet with 140+ Power Automate functions, links to the official documentation and an easy to follow visual guide.
The Unbearable Slowness of Being: Why do we live at 10 bits/s?
Researchers at Caltech quantify human behavioral information throughput at approximately 10 bits/s across various tasks, highlighting a vast discrepancy with the brain's sensory input capacity,...
Brandon on Twitter / X
Wasn't fast enough, needed to use shared array buffer, web workers, and better GPU upload batching pic.twitter.com/o6BfVetKY1— Brandon (@brandon_xyzw) March 26, 2025

Koru
C-class throughput with none of the ceremony. Koru hides a wild amount of complexity at compile time — so the runtime stays lean.
AlexsJones/llmfit
Hundreds of models & providers. One command to find what runs on your hardware.

100% Utilization
Since the end of the Second World War, we have come to expect continual growth in computing power and the rapid development of digital technology. This dynam...
Vaibhav (VB) Srivastav on Twitter / X
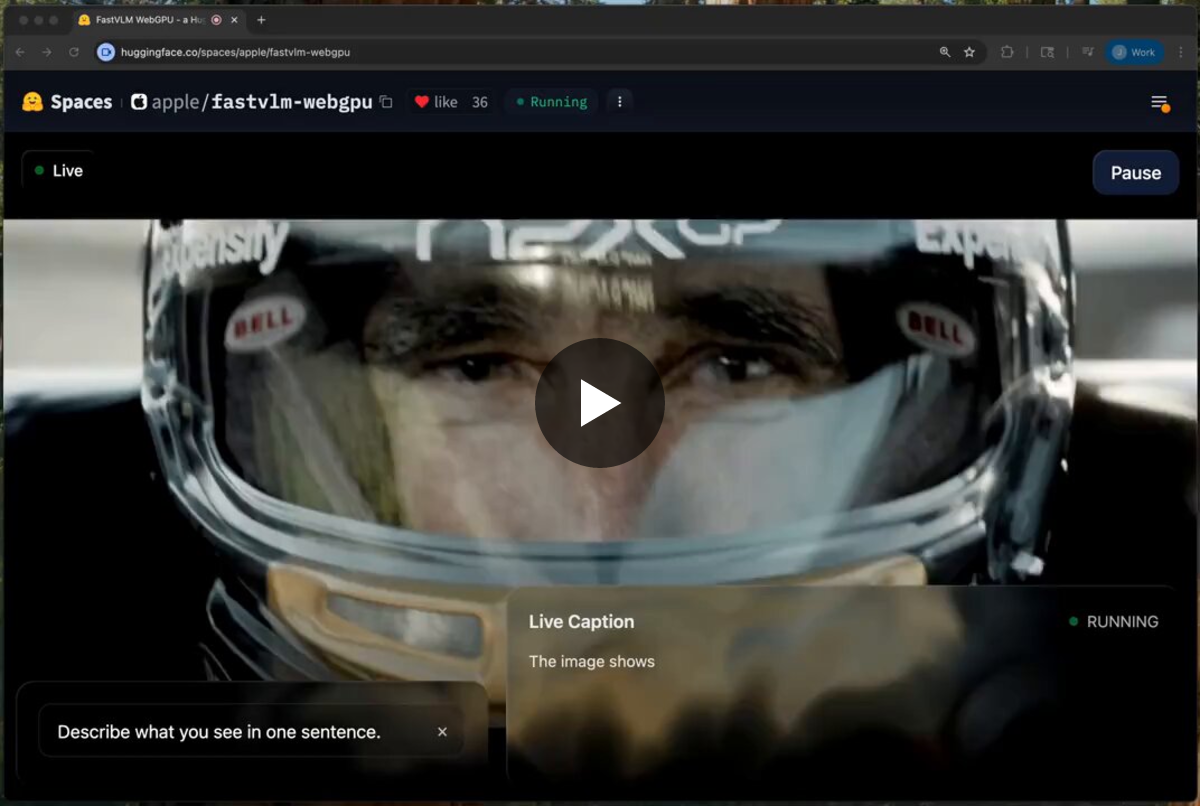
🚨 Apple just released FastVLM on Hugging Face - 0.5, 1.5 and 7B real-time VLMs with WebGPU support 🤯> 85x faster and 3.4x smaller than comparable sized VLMs> 7.9x faster TTFT for larger models> designed to output fewer output tokens and reduce encoding time for high… pic.twitter.com/7cPBWdTQw3— Vaibhav (VB) Srivastav (@reach_vb) August 29, 2025