

TTS systems evaluated on objective metrics.
\robotoslablightdots.tts Technical Report
Text-to-speech (TTS) systems have largely solved intelligibility on standard read-speech benchmarks. What users expect from a modern system is broader: expressive and controllable output, real-time synthesis, and coverage of neutral reading, emotional dialogue, paralinguistic events, singing, and general audio. Current systems pursue this goal along three roughly distinct technical routes, and each route has its own unresolved problem.
Pocket TTS: a high-quality TTS with voice cloning that runs on CPU
Our mission is to build and democratize artificial general intelligence through open science.
Arena Leaderboard - a Hugging Face Space by lmarena-ai
This app displays the LMArena leaderboard in a full‑screen view, letting you see the latest rankings of language models at a glance. Just open the page and the leaderboard loads automatically—no in...
Practical Examples and Analysis of TTRPG Layouts (Or, Steal From These Games) - Part 1
Once you have read this blog post you will be able to make your tabletop roleplaying game look very good, either: Without having any illustr...

Why We Built VIBE Bench: Rethinking Evaluation for Real Workloads
A Blog post by MiniMax on Hugging Face

Sing-song: a speakable encoding for long numbers and keys
Converting hex numbers like 51ac0759fc4d into singable and memorable sirings like kalo-tadu-komu-tigi.
Fontastic Space
Compare Google Fonts with anatomy overlays, metrics & pairing scores. Free.
The State of On-Device LLMs
Xuan-Son Nguyen, an engineer at Hugging Face, specializes in on-device large language models (LLMs) and runtime optimization, working extensively with llam...

The State of On-Device LLMs
Xuan-Son Nguyen, an engineer at Hugging Face, specializes in on-device large language models (LLMs) and runtime optimization, working extensively with llam...
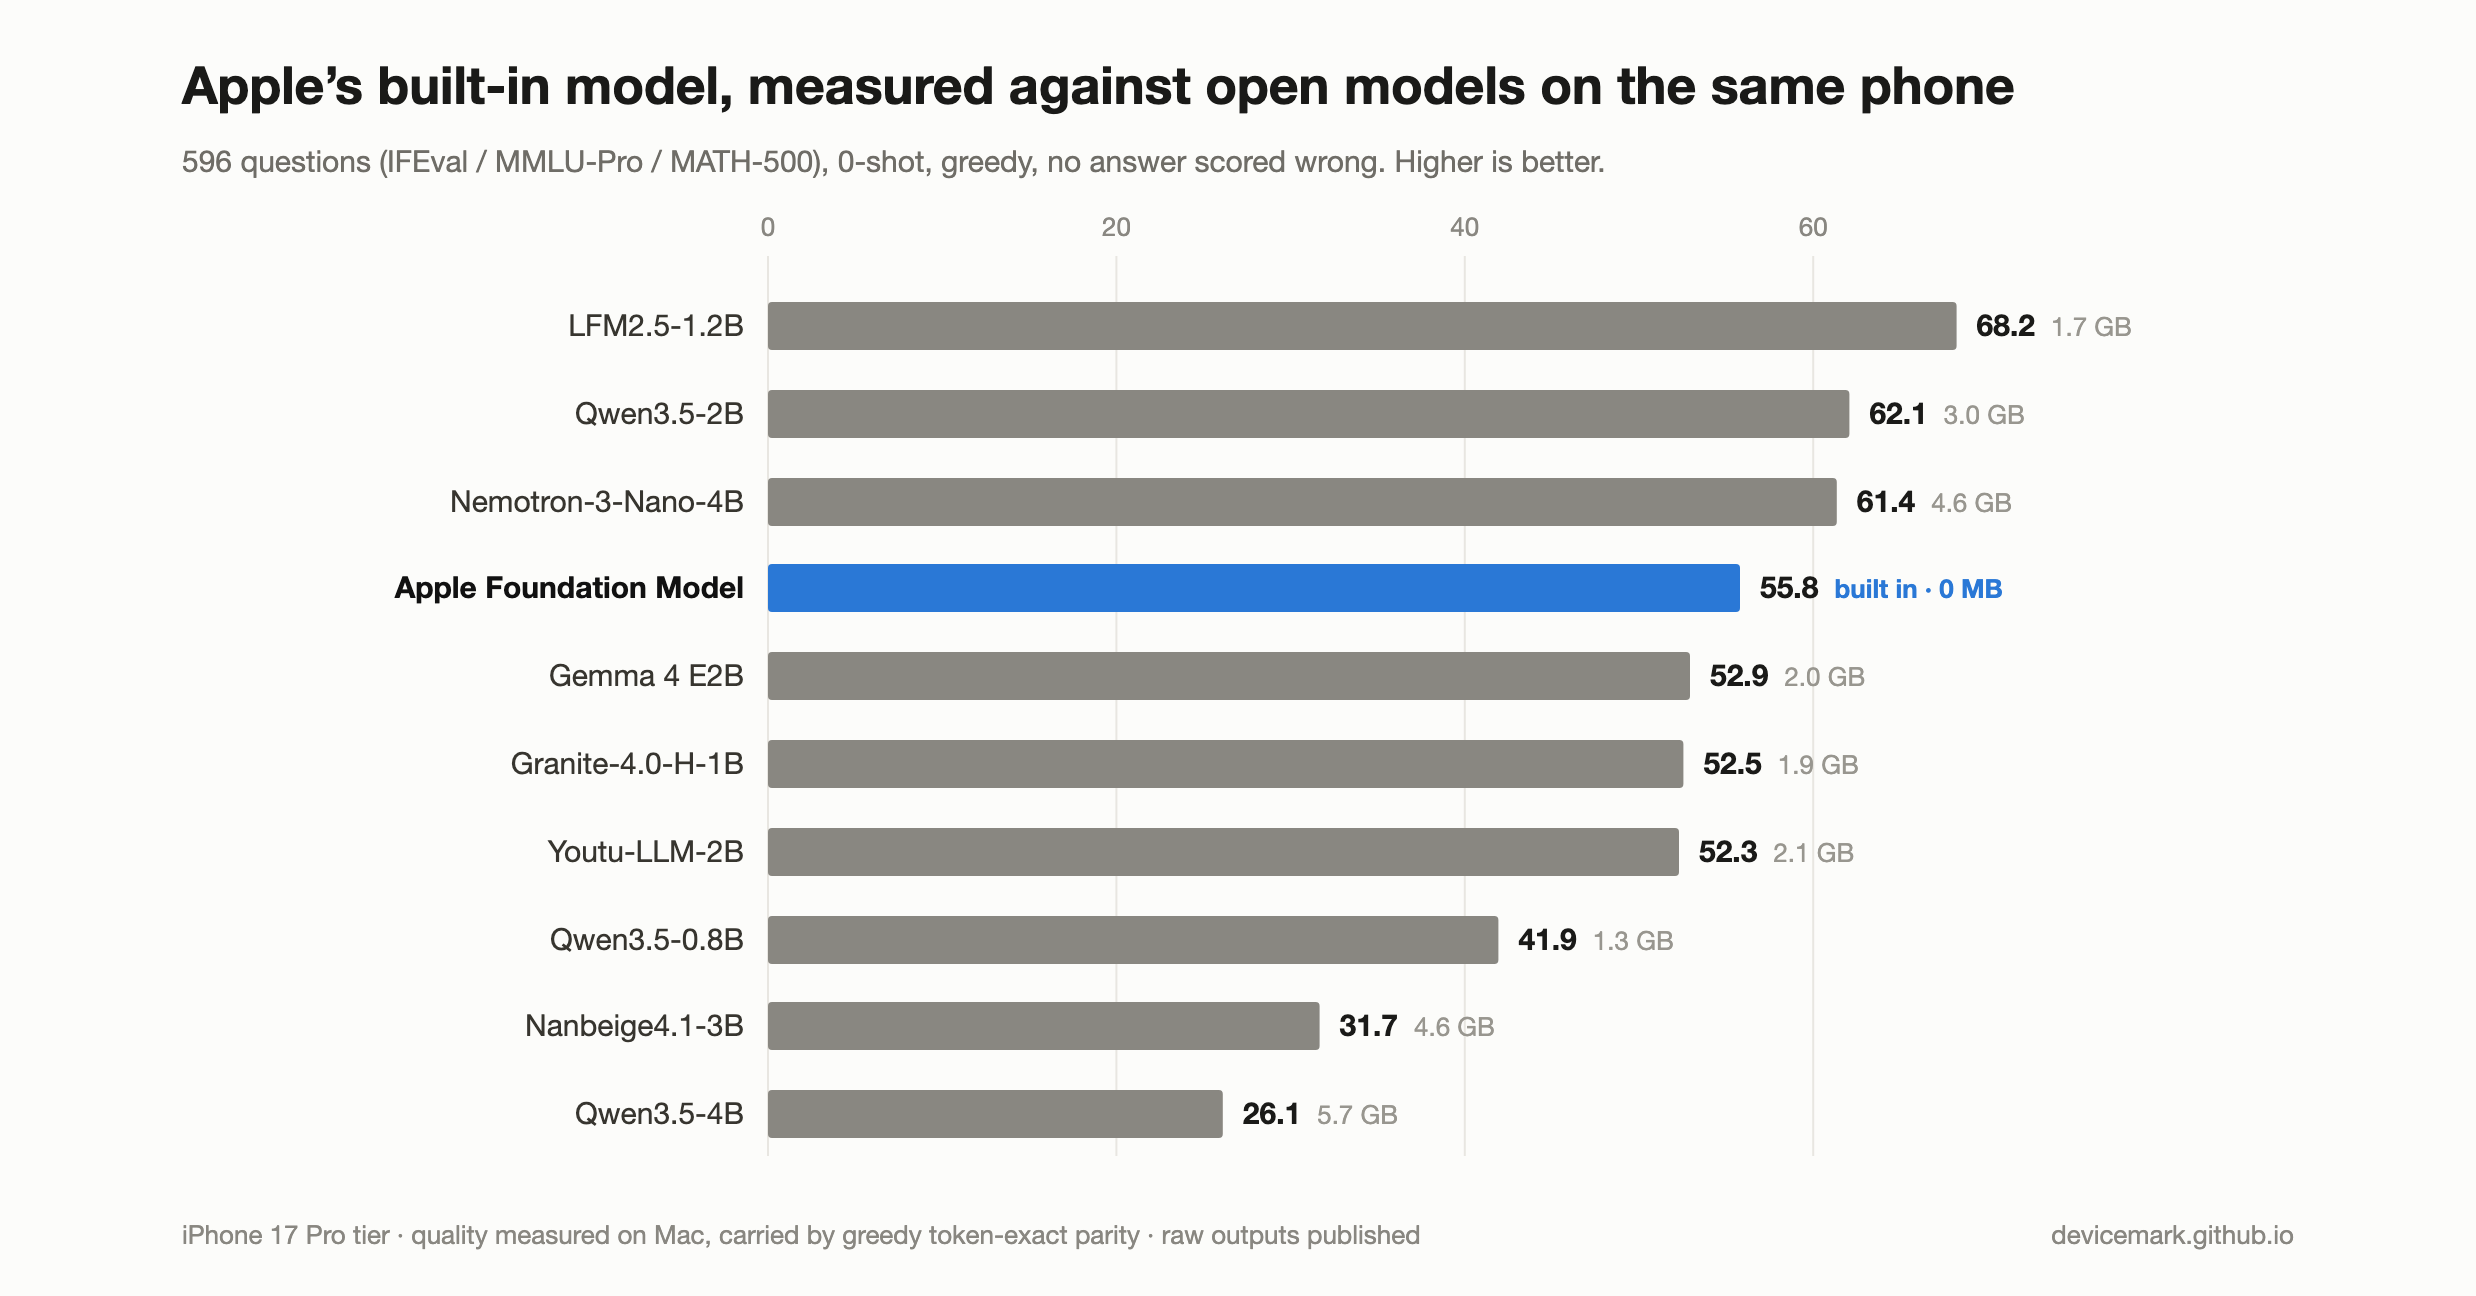
On-Device LLM Leaderboard
Intelligence × decode speed × memory × quantization retention, under real iPhone limits. Same protocol for every model; Apple's built-in FM on the board.
MiniMax H3: An Open Model Breaking the Boundaries Between Tasks and Modalities - MiniMax Research
Today, we're officially launching MiniMax H3, a general-purpose omni-modal generation model. H3 can jointly understand multimodal contexts spanning text, images, video, and audio. It generates video with native stereo audio at up to 2K resolution and 15 seconds in length.
Osaurus — All your AI. One app.
Chat with GPT-5, Claude, Llama, and more — or download local MLX models from Hugging Face. Supercharge Cursor with powerful tools. Open source and built for Mac.
Vaibhav (VB) Srivastav on Twitter / X
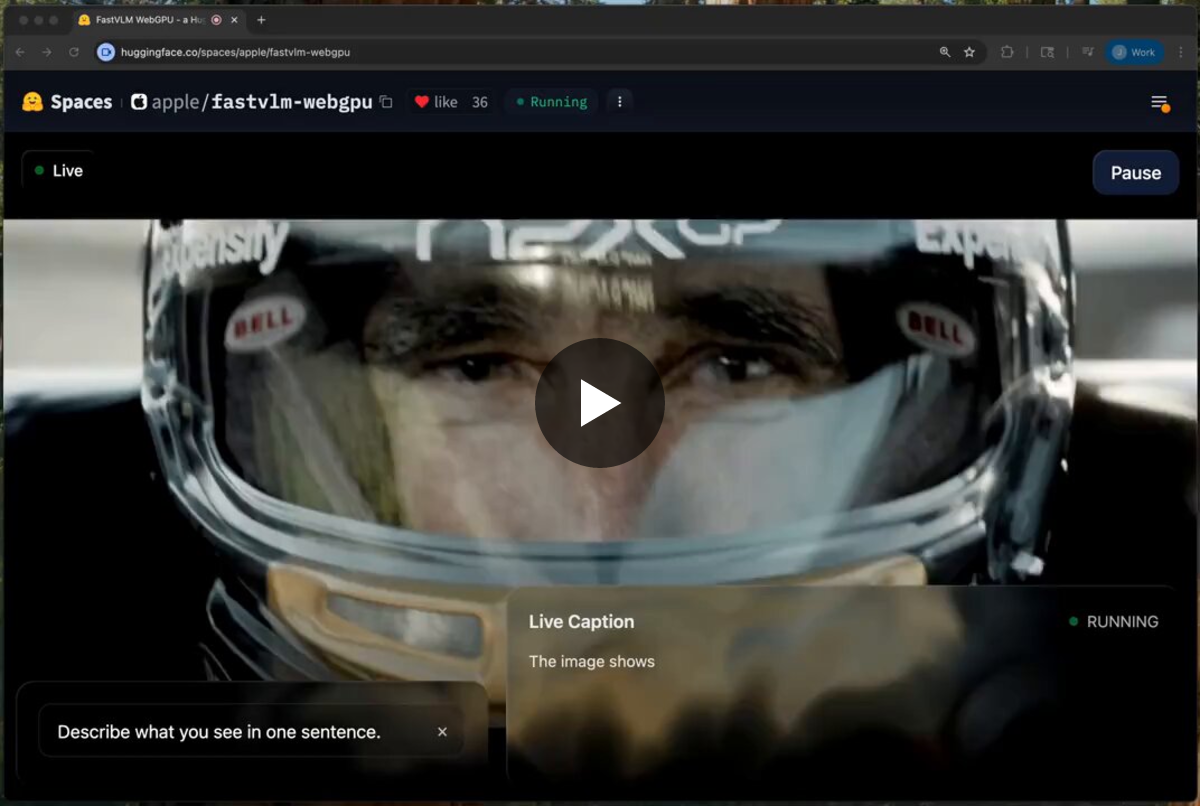
🚨 Apple just released FastVLM on Hugging Face - 0.5, 1.5 and 7B real-time VLMs with WebGPU support 🤯> 85x faster and 3.4x smaller than comparable sized VLMs> 7.9x faster TTFT for larger models> designed to output fewer output tokens and reduce encoding time for high… pic.twitter.com/7cPBWdTQw3— Vaibhav (VB) Srivastav (@reach_vb) August 29, 2025
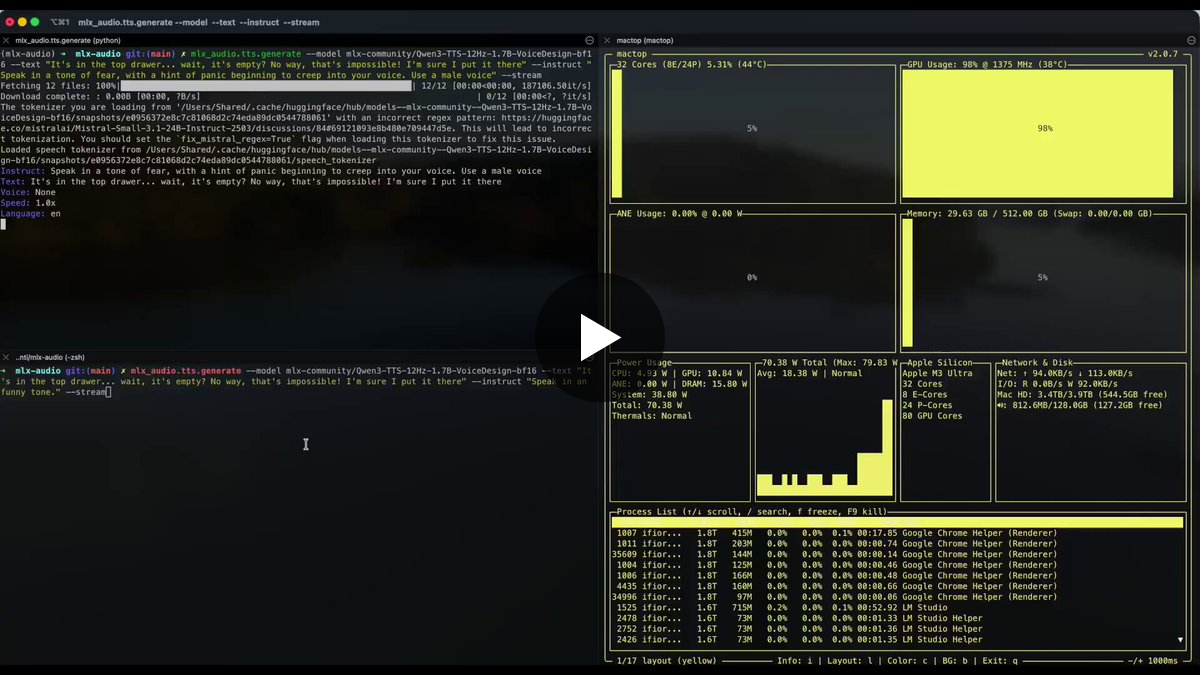
Ivan Fioravanti ᯅ on Twitter / X
Playing with Qwen3-TTS is and MLX-Audio locally on Mac Studio M3 Ultra 🔥Amazing model by @Alibaba_Qwen and great work by @Prince_Canuma bringing this magic to MLX!Tuning the voice with instructions feels like magic!Command and prompts to run it are in the video. pic.twitter.com/qIfWKOedXr— Ivan Fioravanti ᯅ (@ivanfioravanti) January 23, 2026
The Plan B OS for ubiquitous computing. Voice control, security, and terminals as case studies