

Search publisher-controlled information, public knowledge, and the open social web.
The information flaneur: a fresh look at information seeking
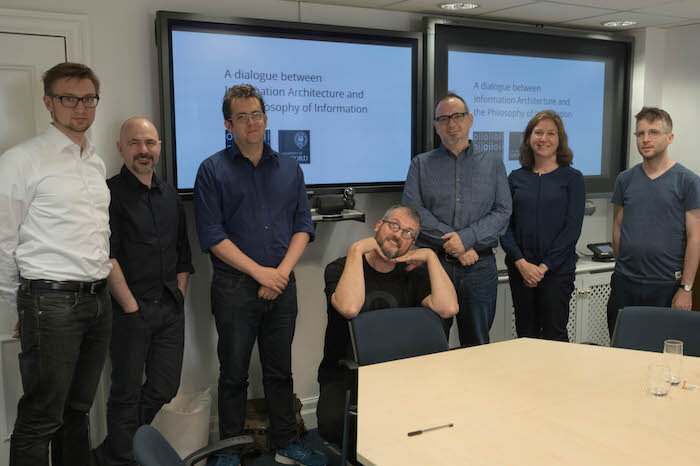
Information Architecture meets the Philosophy of Information - The Policy and Internet Blog
Advancing the practical and theoretical basis for how we conceptualise and shape the infosphere.
A Brief History & Ethos of the Digital Garden
A newly revived philosophy for publishing personal knowledge on the web
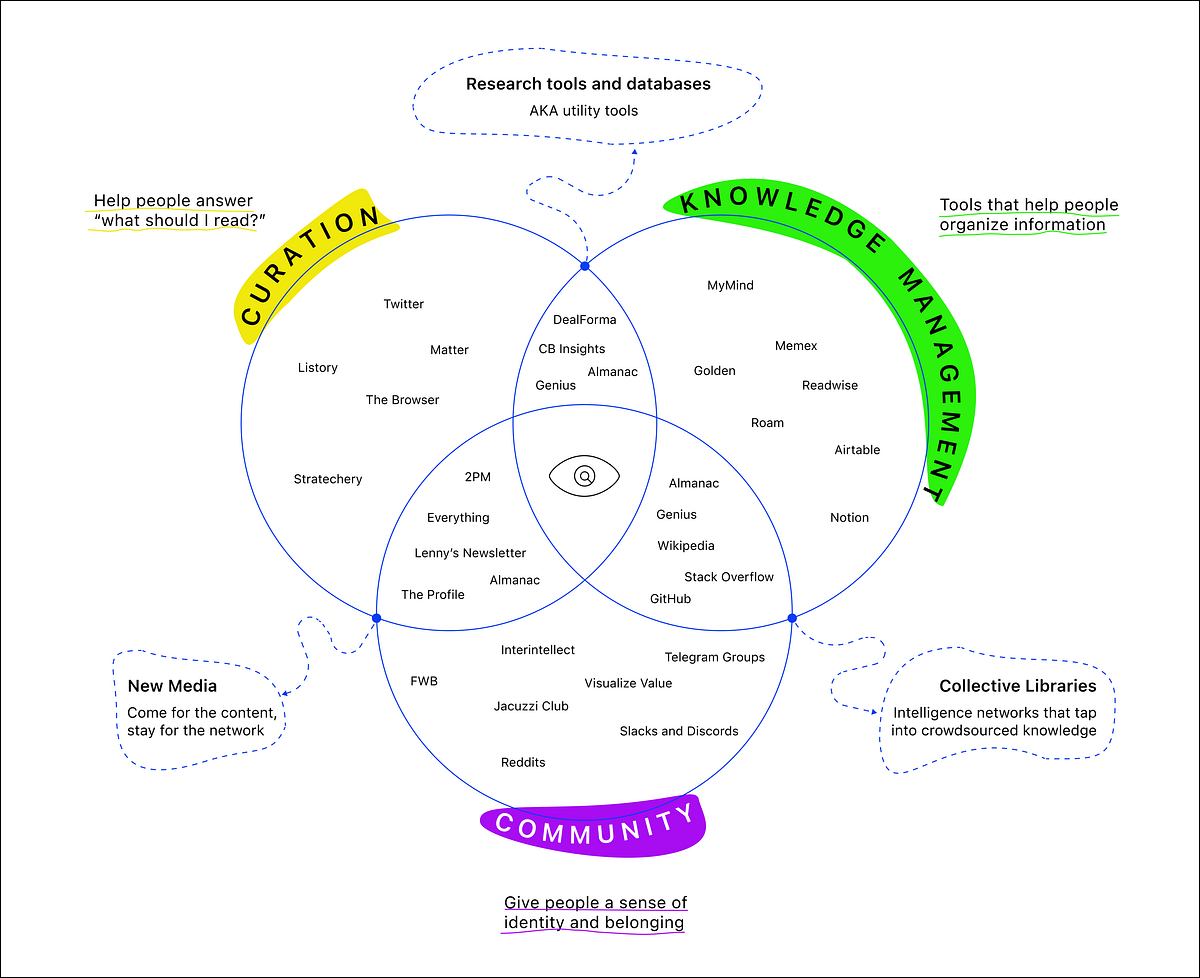
The rise of community-curated knowledge networks
The Internet put thousands of years of human thought at our fingertips, and enabled billions of people to create content. At least 2.5…
your long-form atmosphere · pub search
what you publish, who reads it, your semantic neighborhoods, and what you recommend
Notion’s Knowledge Board
Evaluating how models perform across a range of knowledge work tasks, using live anonymized traffic and judged by models from Anthropic, OpenAI, and Google. An ongoing experiment.
epistemic garden - mapping how ideas spread online
We're building tools to help communities understand their information landscape and protect against harmful coordinated narratives.
DITA Open Toolkit
The open-source publishing engine for content authored in the Darwin Information Typing Architecture
The Atmosphere . Building the open social web
A privacy-first, open-source knowledge base
A privacy-first, open-source platform for knowledge management and collaboration.

The anatomy of a nanopublication
As the amount of scholarly communication increases, it is increasingly difficult for specific core scientific statements to be found, connected and curated. Additionally, the redundancy of these statements in multiple fora makes it difficult to determine attribution, quality and provenance. To tackle these challenges, the Concept Web Alliance has promoted the notion of nanopublications (core scientific statements with associated context). In this document, we present a model of nanopublications along with a Named Graph/RDF serialization of the model. Importantly, the serialization is defined completely using already existing community-developed technologies. Finally, we discuss the importance of aggregating nanopublications and the role that the Concept Wiki plays in facilitating it.
atproto-aware concept search engine
a mockup of a webpage search engine that only indexes webpages that are referenced in atproto records. Surfaces related links based on social and community context.
Google: Organize the world's information Atmosphere: Let the world's information self-organize

TJ
In some ways, atproto, bluesky, @semble.so, @sill.social, @standard.site and so on are building new indexes for the web. I really hope atproto succeeds and goes fully mainstream. Think of the amazing search engines that can be built on such rich index data. Maybe web3 can actually happen.
