

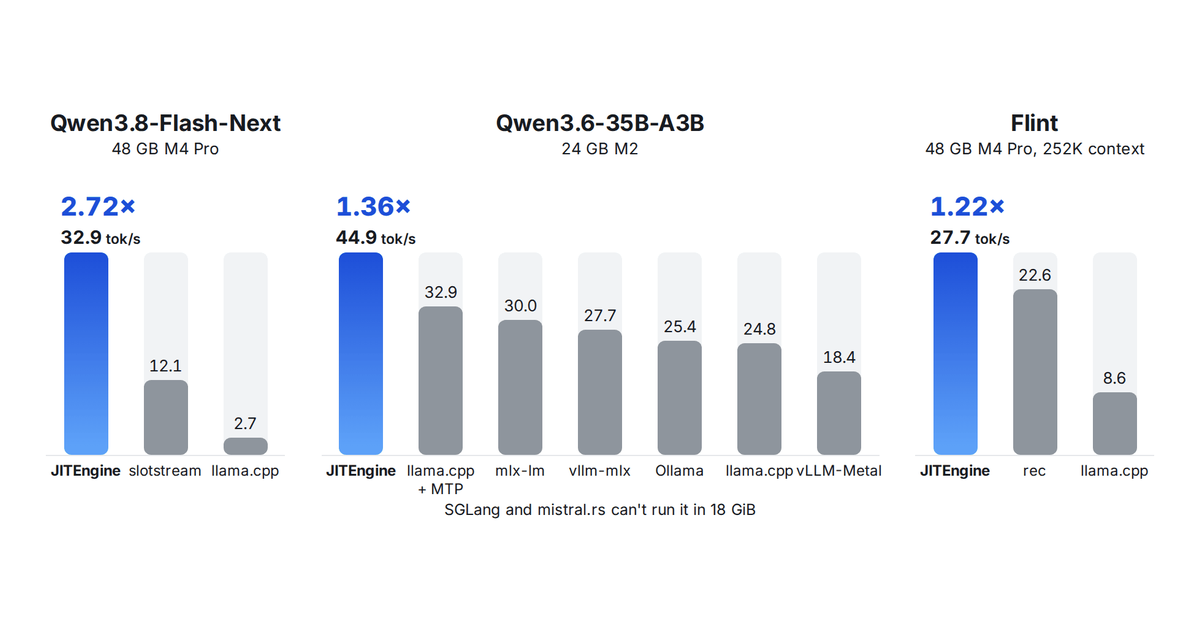
LLM serving engines synthesized for your Mac, up to 2.7× as fast as the best other server we measured on the same Mac. Pick your Mac and get its commands, with the speeds we measured.
Your Mac Deserves Its Own LLM Engine
Six LLM serving engines for Apple silicon, built by coding agents with SkySynth. Up to 2.72x faster than the fastest other server we measured on the same Mac.
ModelScope on Twitter / X
🤯 400 Token/S on a MacBook? Yes, you read that right!Shaohong Chen just fine-tuned the Qwen3-0.6B LLM in under 2 minutes using Apple's MLX framework. This is how you turn your MacBook into a serious LLM development rig. A step-by-step guide and performance metrics inside! 🧵… pic.twitter.com/31Cmycy8Mh— ModelScope (@ModelScope2022) October 13, 2025
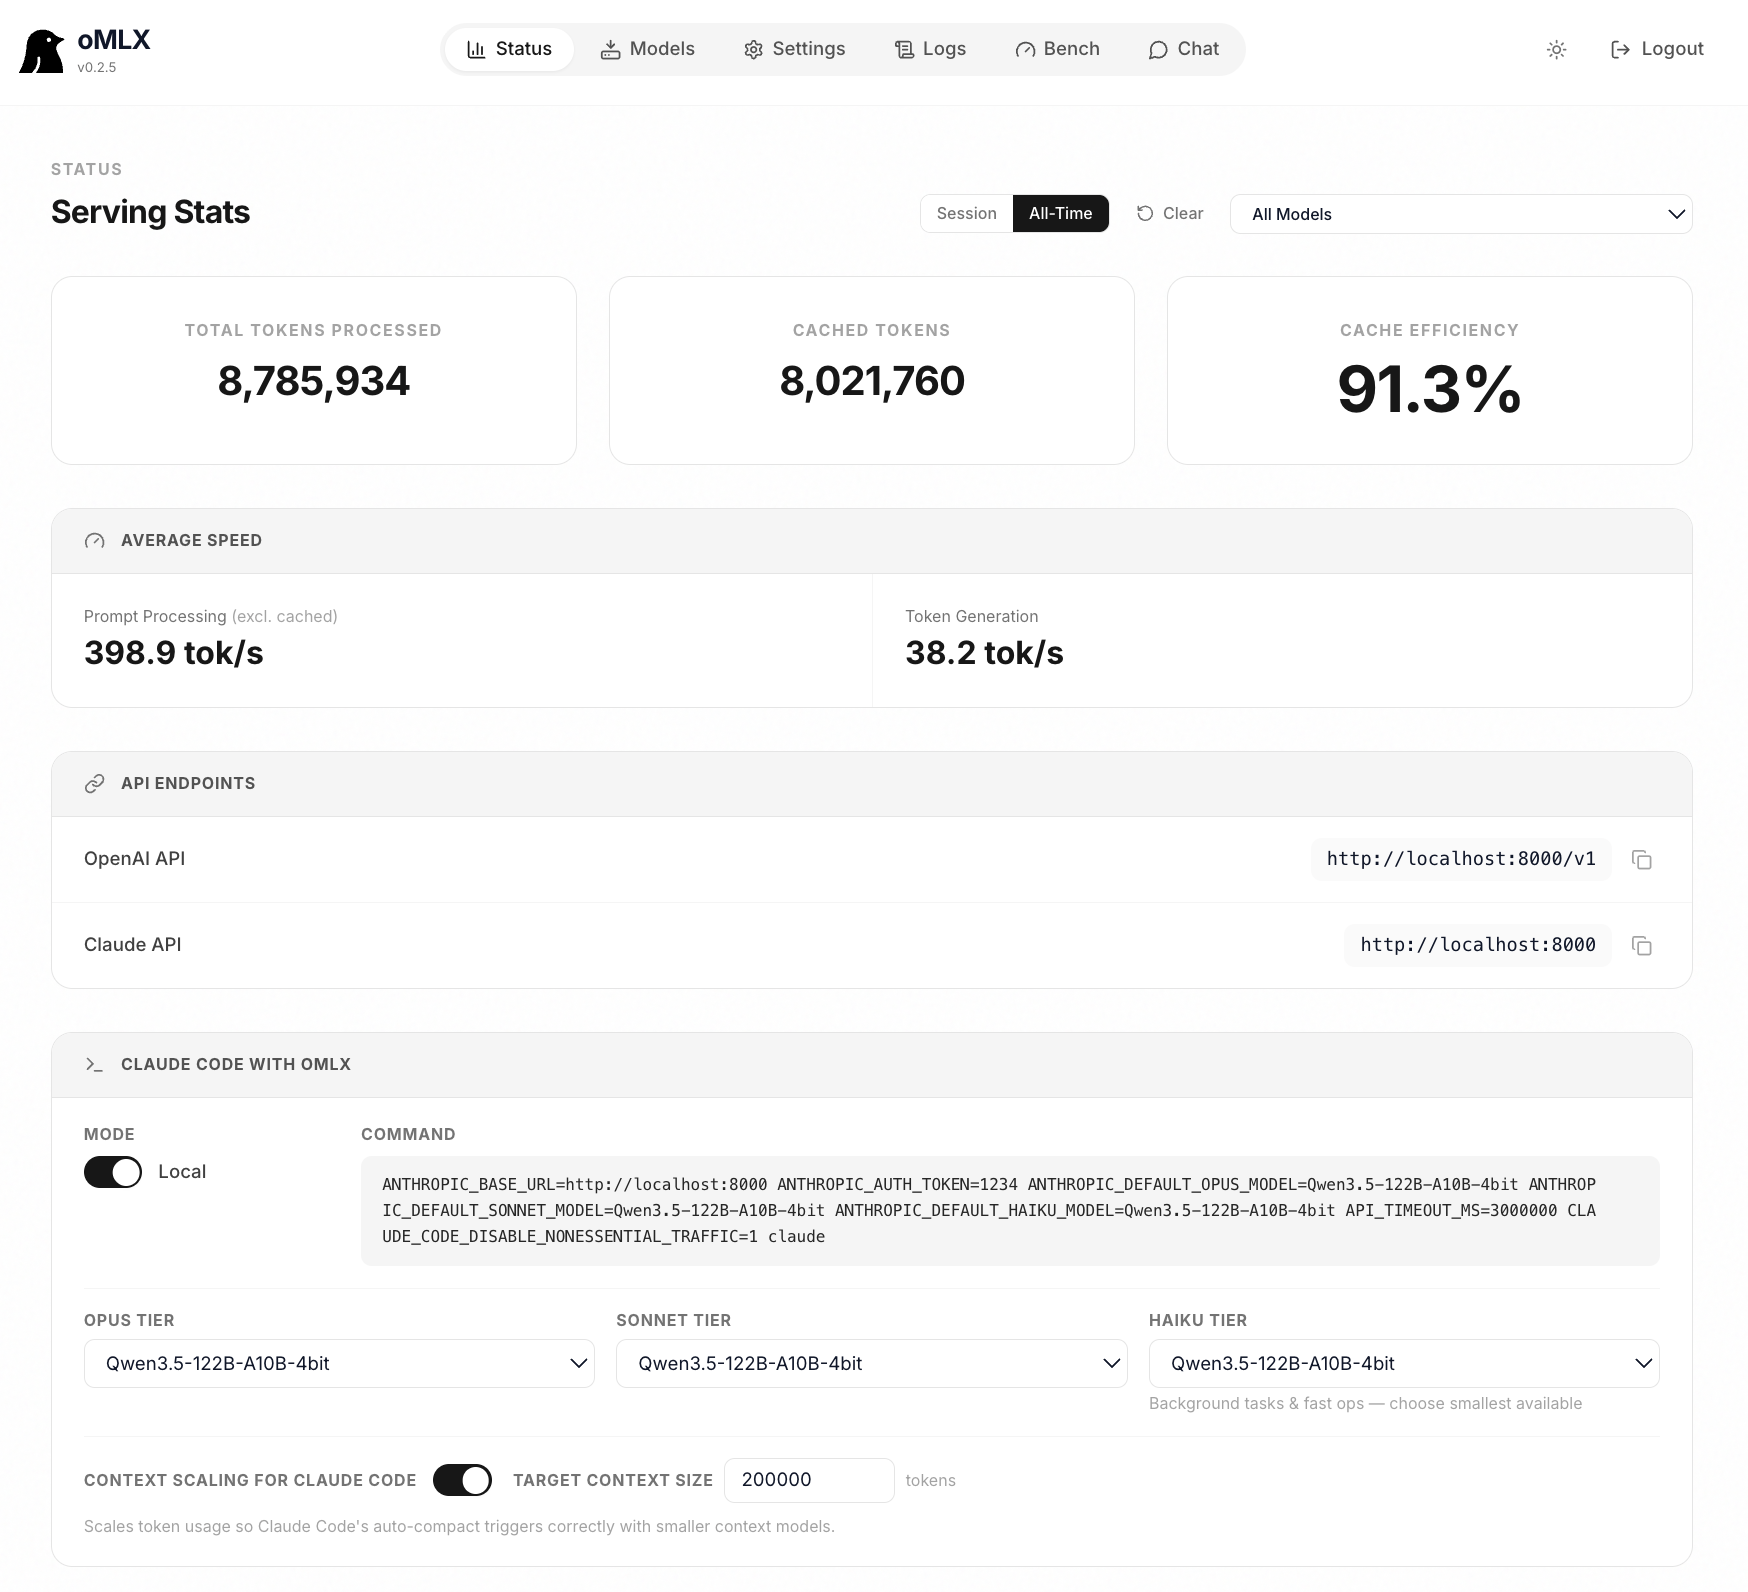
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
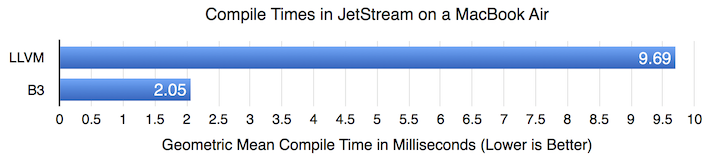
Introducing the B3 JIT Compiler
WebKit's FTL JIT now uses a new backend on OS X — the Bare Bones Backend, or B3 for short, replaces LLVM as the low-level optimizer.
omlx/docs/oQ_Quantization.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
omlx/docs/experimental/dflash_mlx_integration.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
chad/whichlang
What programming language do LLMs default to when you don't tell them? A small benchmark.
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
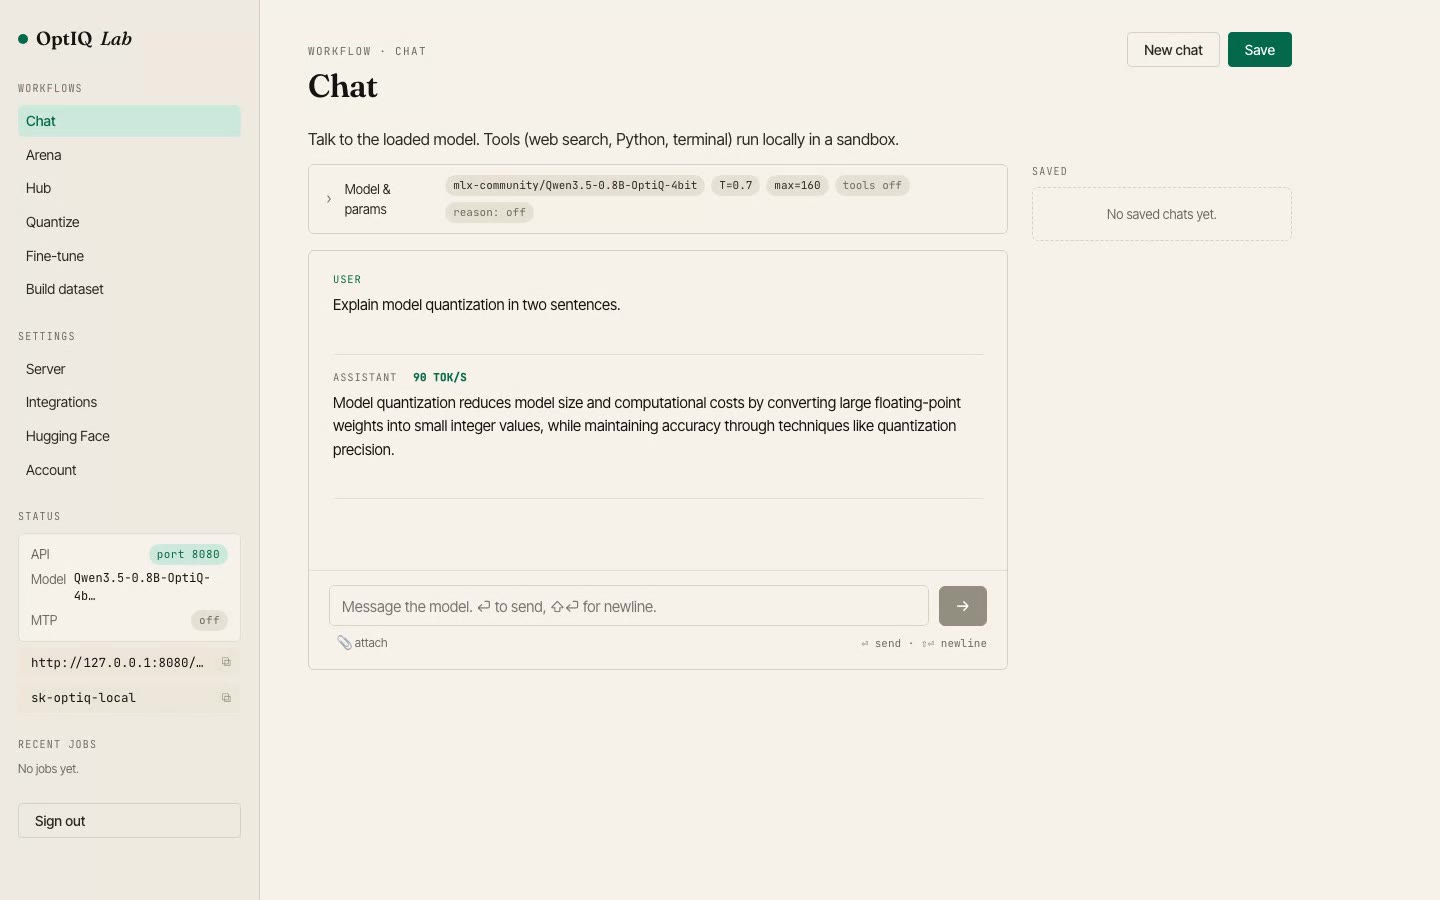
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
There continue to be reasons for software to be slow
A discussion on the various reasons why performance is slow, and which ones are unlikely to be affected by LLMs. Originally written as a counter-point to Dan Luu