

Experiments with getting usable outputs out of local models on a standard Macbook
ModelScope on Twitter / X
🤯 400 Token/S on a MacBook? Yes, you read that right!Shaohong Chen just fine-tuned the Qwen3-0.6B LLM in under 2 minutes using Apple's MLX framework. This is how you turn your MacBook into a serious LLM development rig. A step-by-step guide and performance metrics inside! 🧵… pic.twitter.com/31Cmycy8Mh— ModelScope (@ModelScope2022) October 13, 2025
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents
For the past few days, I’ve been testing the (currently) top-of-the-line M5 Ultra Mac Studio with 256 GB of RAM. I’ll cut to the chase: the M5 Ultra Mac Studio is a dream machine for local AI agents. This computer makes it possible to run personal assistants powered by local models with great performance and
Alex Cheema on Twitter / X
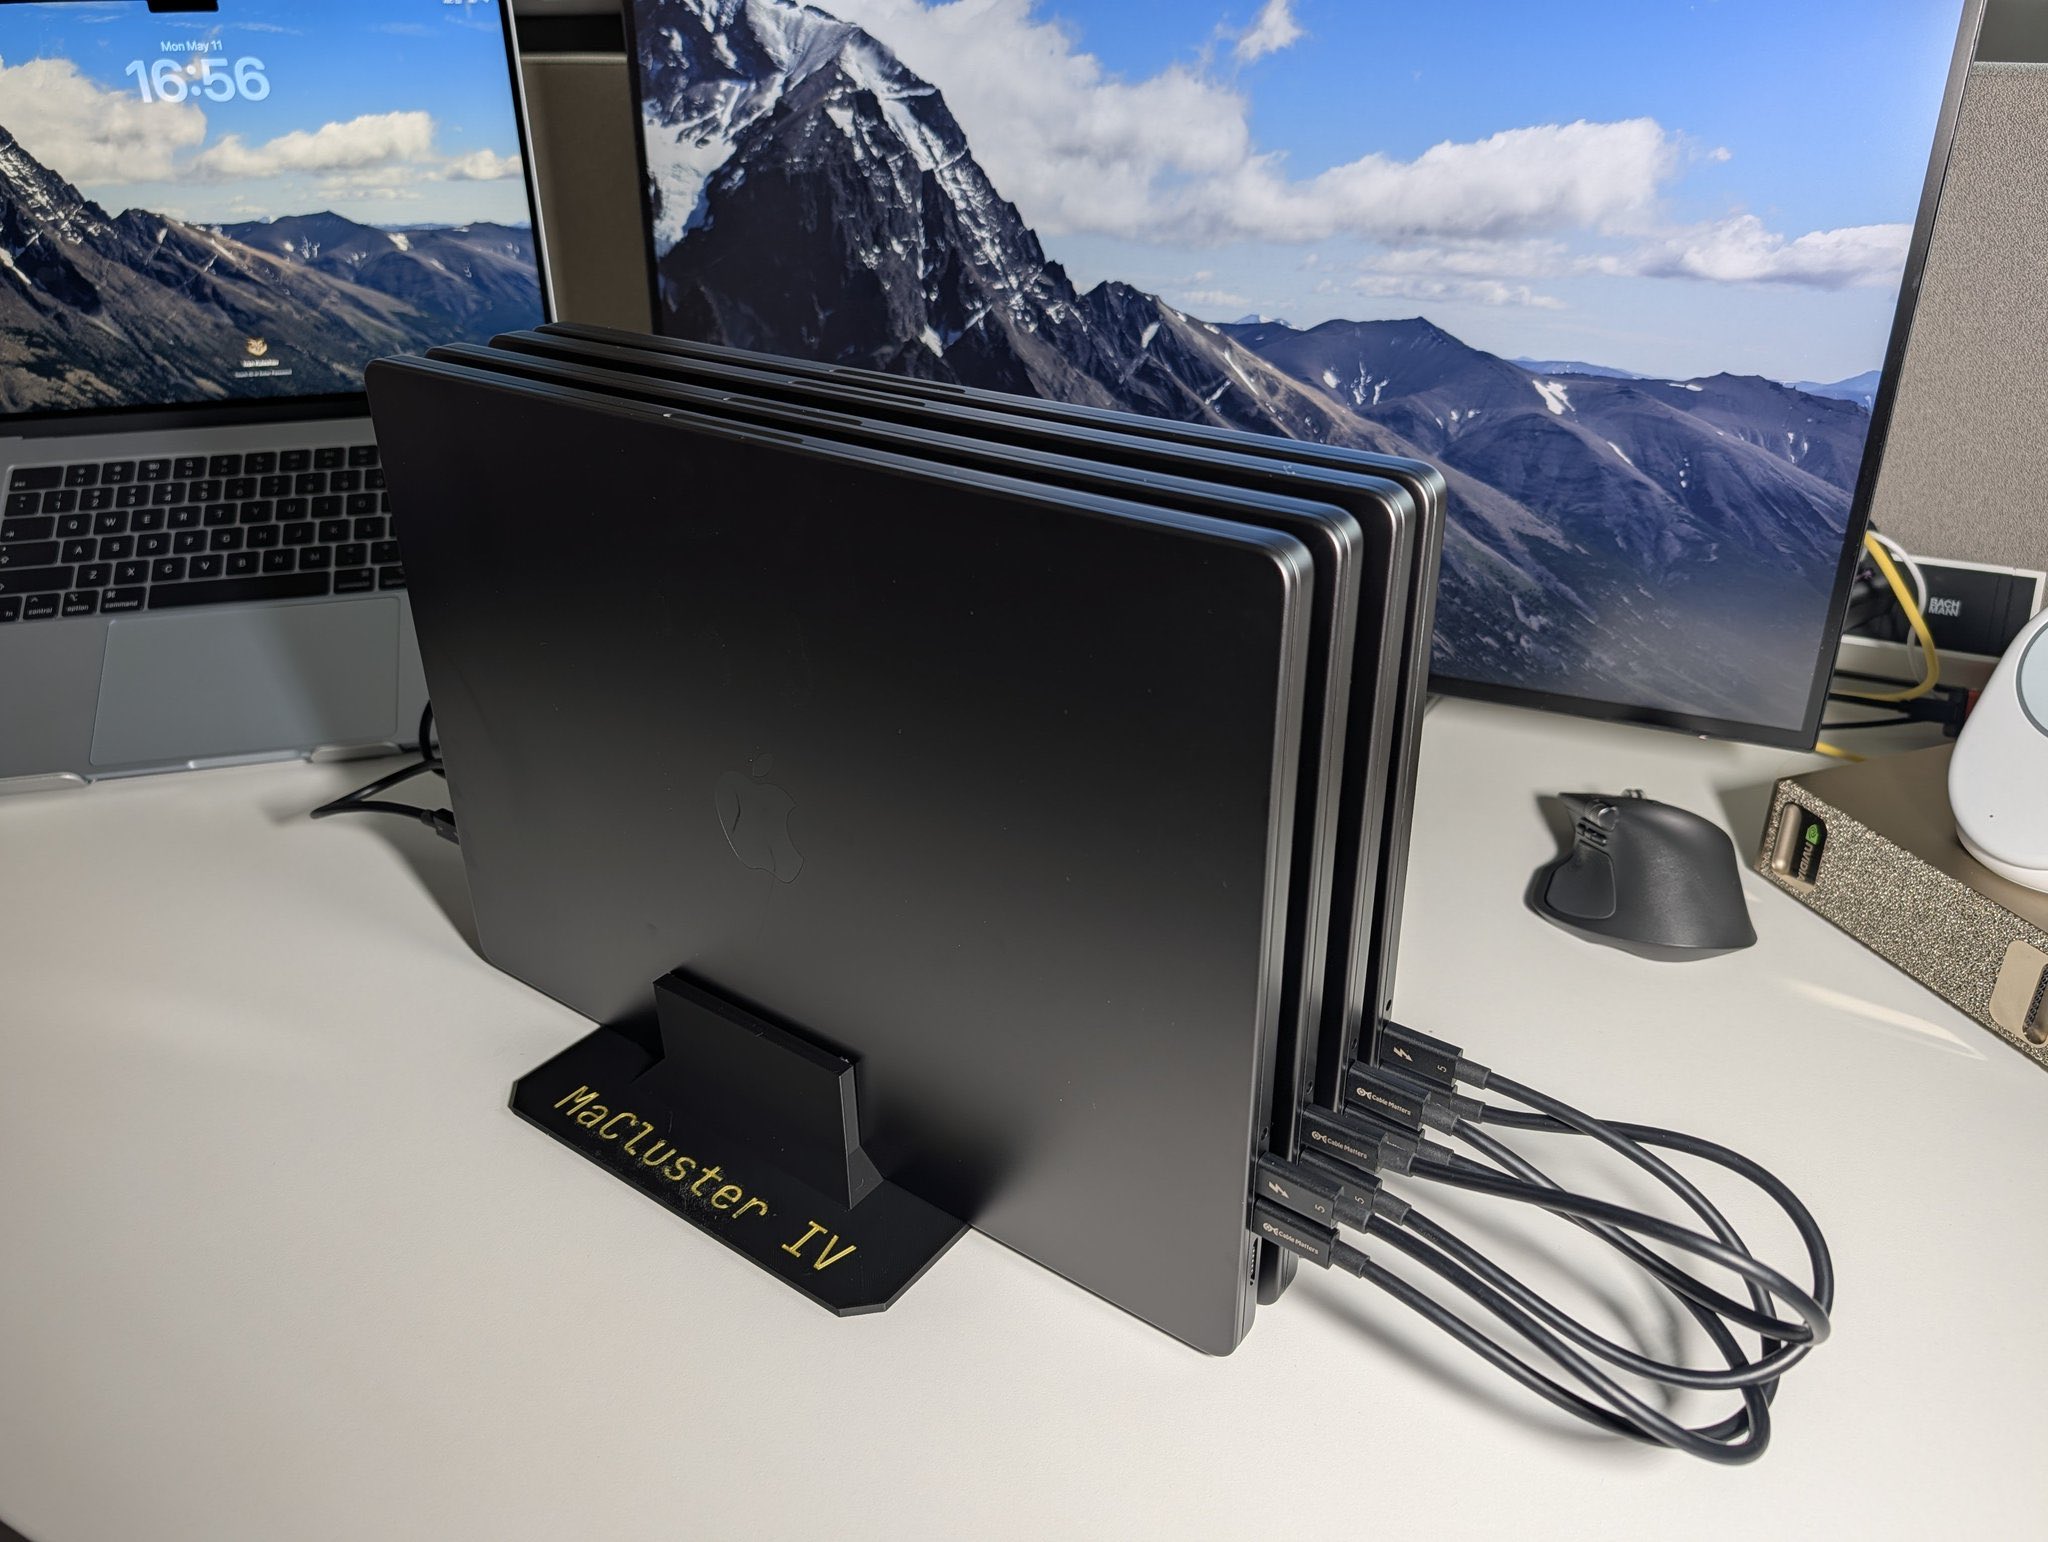
It’s kind of crazy but the shitstorm of supply chain issues has created a new best-in-class local AI deployment: M5 Max MacBook clusters.- The memory unit economics are great - each MacBook has 128GB @ 614GB/s for $5k- M5 Max added tensor cores (Apple Neural Accelerators) with… https://t.co/f8STQ0tLZs pic.twitter.com/FLm3oOnyEl— Alex Cheema (@alexocheema) May 14, 2026
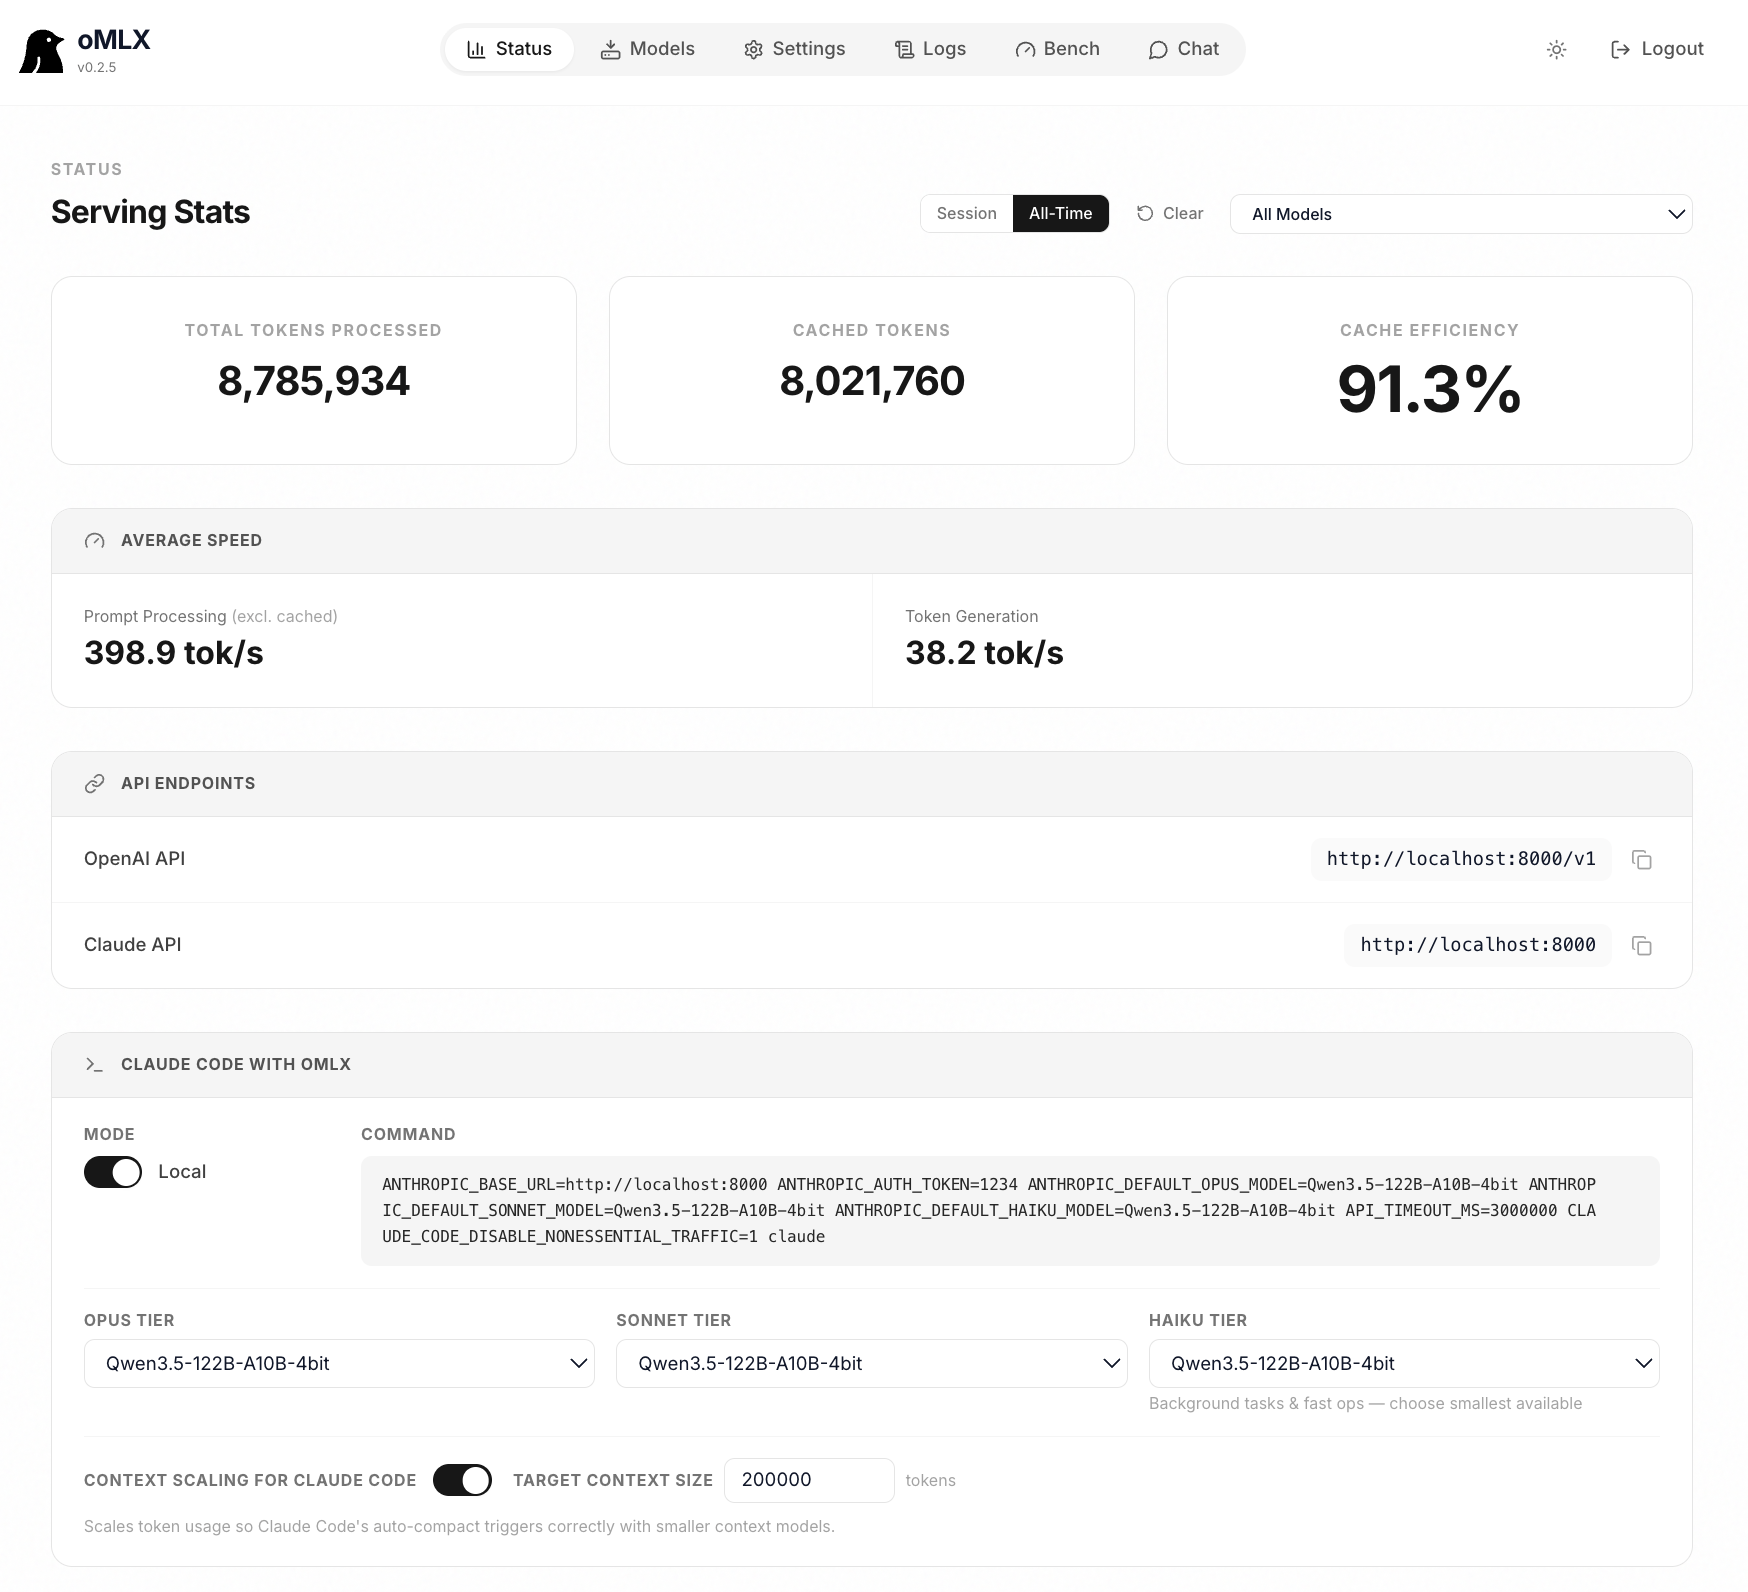
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
The Potential of M6 and M5 Ultra for Local AI on macOS
Earlier today, Apple unveiled the new generation of Mac mini and Mac Studio, featuring the latest entries in the Apple silicon family of chips: the M6, available in the Mac mini, and the M5 Ultra, exclusive to the Mac Studio. You can read more details about the announcement and related specs in John’s overview. As
DHH on Twitter / X
Going to double down on the MacBook mission with Omarchy. We almost have perfect coverage for the vintage Intel era going from 2009-2020. There's a straight shot to get the M1 and M2 machines going too, even if it's a lot more work. But we'll do the work. We'll fix everything.— DHH (@dhh) August 22, 2026
Compiling Models to Megakernels
Fine-grained synchronization, deep pipelines, and zero kernel launch overheads, automatically.
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
mzau/broke-cluster
A Poor Man's Apple Silicon LLM Cluster — tuned for MLX, scalable without shame.
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

First look at the DGX Spark
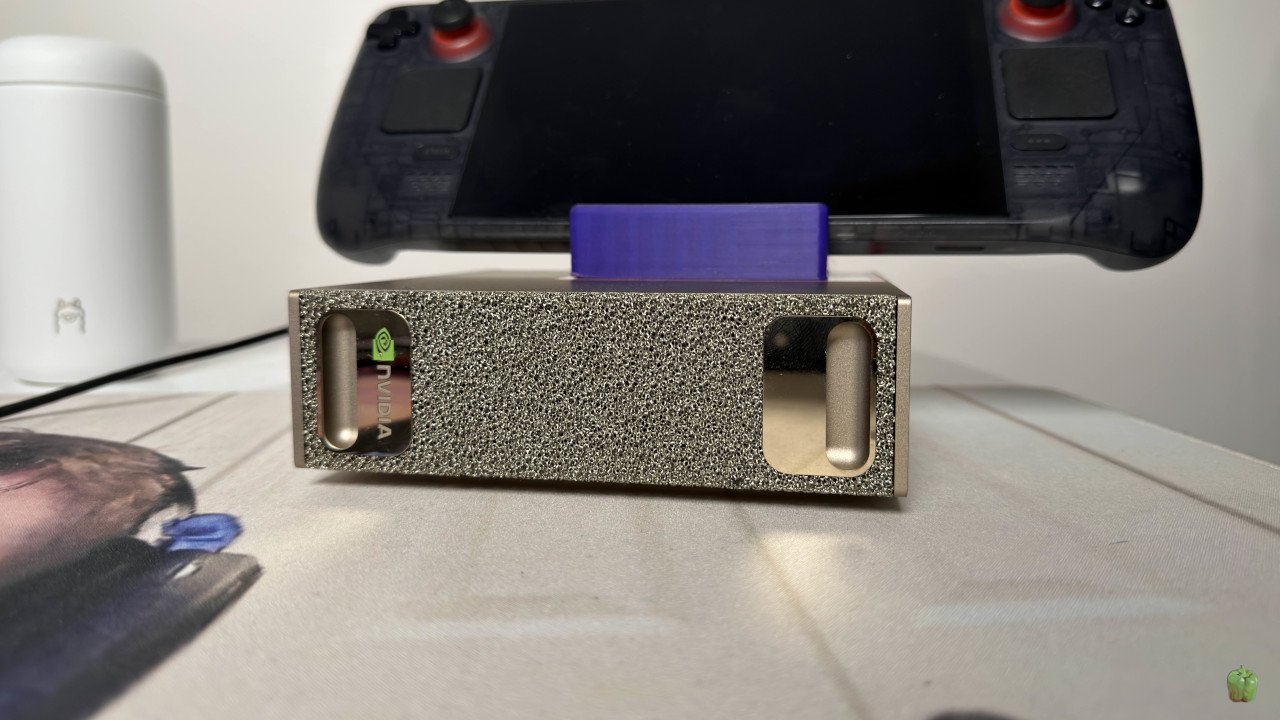
A local supercomputer between the size of a Mac mini and a Mac mini.
Build Bigger With Small Ai: Running Small Models Locally
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
Your Laptop Isn’t Ready for LLMs. That’s About to Change
The quest to run large AI models locally on an individual's machine are driving the biggest change in laptop architecture in decades.
