

We present , an Artificial Intelligence (AI) multiagent system designed to serve as a scientific research assistant. can perform many different tasks, such as generating ideas, checking the literature, developing research plans, writing and executing code, making plots, and drafting a scientific paper. The system has a modular architecture, allowing it to handle specific tasks, such as generating an idea or carrying out near end-to-end scientific analysis using as a deep-research backend (end-to-end except for the novelty assessment, which is intentionally left for the user to inspect). In this work, we describe in detail and its modules, and illustrate its capabilities by presenting multiple AI-generated papers generated by it in many different scientific disciplines such as astrophysics, biology, biophysics, biomedical informatics, chemistry, material science, mathematical physics, medicine, neuroscience, and planetary science. can also produce work that combines ideas from different disciplines, which we illustrate with a single ( N = 1 ) example: a paper that applies methods from quantum physics and machine learning to astrophysical data. We report the evaluations performed on these papers by domain experts, who provided both numerical scores and reviewlike feedback. These papers were scored by domain experts on our team; we report these scores as an indicative self-assessment rather than an independent evaluation, and we flag the resulting conflict of interest explicitly. Most drafts were rated above the midpoint of a 0–10 scale, with several rated 8–9, indicating that the generated papers reach the level a good undergraduate or early graduate student could achieve after weeks or a few months of work. They should be regarded as first drafts that require expert development, not publication-ready papers. We also document an important failure mode in which, when the input data cannot be read, the system may silently generate synthetic data, which we flag explicitly as a key limitation. We then highlight the strengths, weaknesses, and limitations of the current system. Finally, we discuss the ethical implications of AI-driven research and reflect on how such technology relates to the philosophy of science. We publicly release the code at . A demo can also be run directly on the web at , and the full app will be deployed on the cloud.
Towards Automating Scientific Review with Google's Paper Assistant Tool
Artificial intelligence is driving a revolution in scientific discovery, accelerating everything from hypothesis generation to mathematical theorem proving. However, this rapid acceleration is creating a systemic challenge: traditional human peer review cannot scale to match the influx of AI-assisted science. Ultimately, to resolve this tension, we must also deploy AI to accelerate the verification and review process itself. To frame the discussion around this transition, we propose a taxonomy consisting of four progressive levels of AI-human collaboration in scientific evaluation, and discuss various trade-offs involved with each. As a step toward this future, we introduce the Paper Assistant Tool (PAT), an agentic AI framework built for deep scientific review and verification. PAT ingests full scientific manuscripts and produces a comprehensive evaluation, checking theoretical results, validating experiments, suggesting improvements, and identifying potential flaws. By utilizing inference scaling techniques, PAT is able to identify deeper issues than a single model call alone, achieving a 34% improvement over zero-shot recall on mathematical errors in the SPOT benchmark. Pilot deployments of PAT as a pre-submission tool for authors at two major Computer Science conferences -- STOC and ICML -- demonstrate its ability to identify critical errors and suggest substantive improvements to research papers. By catching errors early, PAT eases the cognitive burden placed on referees, while preserving their control over the outcomes of the review process.

Towards End-to-End Automation of AI Research
The automation of science is a long-standing ambition in the field of AI. While the community has made significant progress in automating individual components of the scientific process, a system that autonomously navigates the entire research lifecycle -- from conception to publication -- has remained out of reach. Here, we present the strongest demonstration to date toward automating the entire process end-to-end. We present The AI Scientist, which creates research ideas, writes code, runs experiments, plots and analyzes data, writes the entire scientific manuscript and performs its own peer review. Its ideas, execution, and presentation are of sufficient quality to produce a manuscript generated by an AI system that passes the first round of peer review at a major machine learning conference workshop. The workshop has an acceptance rate of 70 percent. Our system leverages modern foundation models within a complex agentic system. We evaluate The AI Scientist in two settings: a focused mode using human-provided code templates as an initial scaffold to conduct research on a specific topic, and a template-free, open-ended mode that leverages agentic search for wider scientific exploration. Both settings produce diverse ideas and automatically test, report on, and evaluate them. This achievement demonstrates AI's growing capacity for scientific contribution and signifies a potential paradigm shift in how research is conducted. As with any impactful new technology, there could be significant risks, including taxing overwhelmed review systems and adding noise to scientific literature. However, if developed responsibly, such autonomous systems could greatly accelerate scientific discovery.
ScientistTwo: Pioneering the Human Knowledge Frontier with Autonomous AI
Scientific discovery is defined by the ability to identify the boundaries of existing knowledge and venture into unexplored territory. The ultimate vision for AI in science is problem-driven autonomous research: given a fundamental challenge by a human expert, the AI independently navigates the scientific landscape, uncovers theoretical and empirical bottlenecks, and systematically expands the frontier of knowledge. In this paper, we introduce ScientistTwo, a fully autonomous multi-agent framework designed to realize this vision. Specifically, ScientistTwo takes an initial problem as input, establishes state-of-the-art baselines, formulates novel hypotheses, and coordinates specialized agents to orchestrate an end-to-end discovery cycle without human intervention. Moreover, the framework rigorously conducts experiments using diverse datasets and metrics, refines methodologies through automated ablation studies, and validates research findings via a closed-loop simulated peer-review rebuttal engine. To evaluate ScientistTwo's capabilities against the highest standards of human scientific achievement, we benchmark it across papers accepted at top-tier conferences such as ICLR, ICML, and NeurIPS. As a result, ScientistTwo autonomously generates expert-level, publishable papers and fully verified, executable codebases. Its solutions consistently outperform human state-of-the-art models, and achieve higher average review ratings than human-authored papers under automated AI review agents. These results show that ScientistTwo is not merely an assistive tool but an autonomous scientific pioneer capable of pushing the frontiers of human discovery. Project website: https://scientist-two.github.io/
AI Scientists as Engines of Discovery: A Case for Development within Reformed Institutions
Agentic artificial intelligence (AI) systems are beginning to assist, accelerate, and partially automate scientific discovery, performing tasks that span literature synthesis, code generation, data analysis, hypothesis proposal, and model criticism. We argue that this transition is qualitative rather than incremental, and that suitably designed multi-agent systems may evolve from passive computational tools into ``AI scientists'' that can expand the hypothesis-generating and verification capacity of science. Such systems must be developed and deployed within a scientific ecosystem fit for purpose: institutions must be redesigned for verification, accountability, interpretability, and dual-use safety. We sketch how multi-agent architectures, illustrated by the prototype framework \textit{Denario}, accelerate the discovery cycle and traverse model spaces beyond human reach; examine what this implies for authorship, peer review, and the enduring role of human scientists; and close with recommendations for governing AI as an epistemic actor rather than a mere instrument.
Reimagining research papers as interactive and reliable AI agents
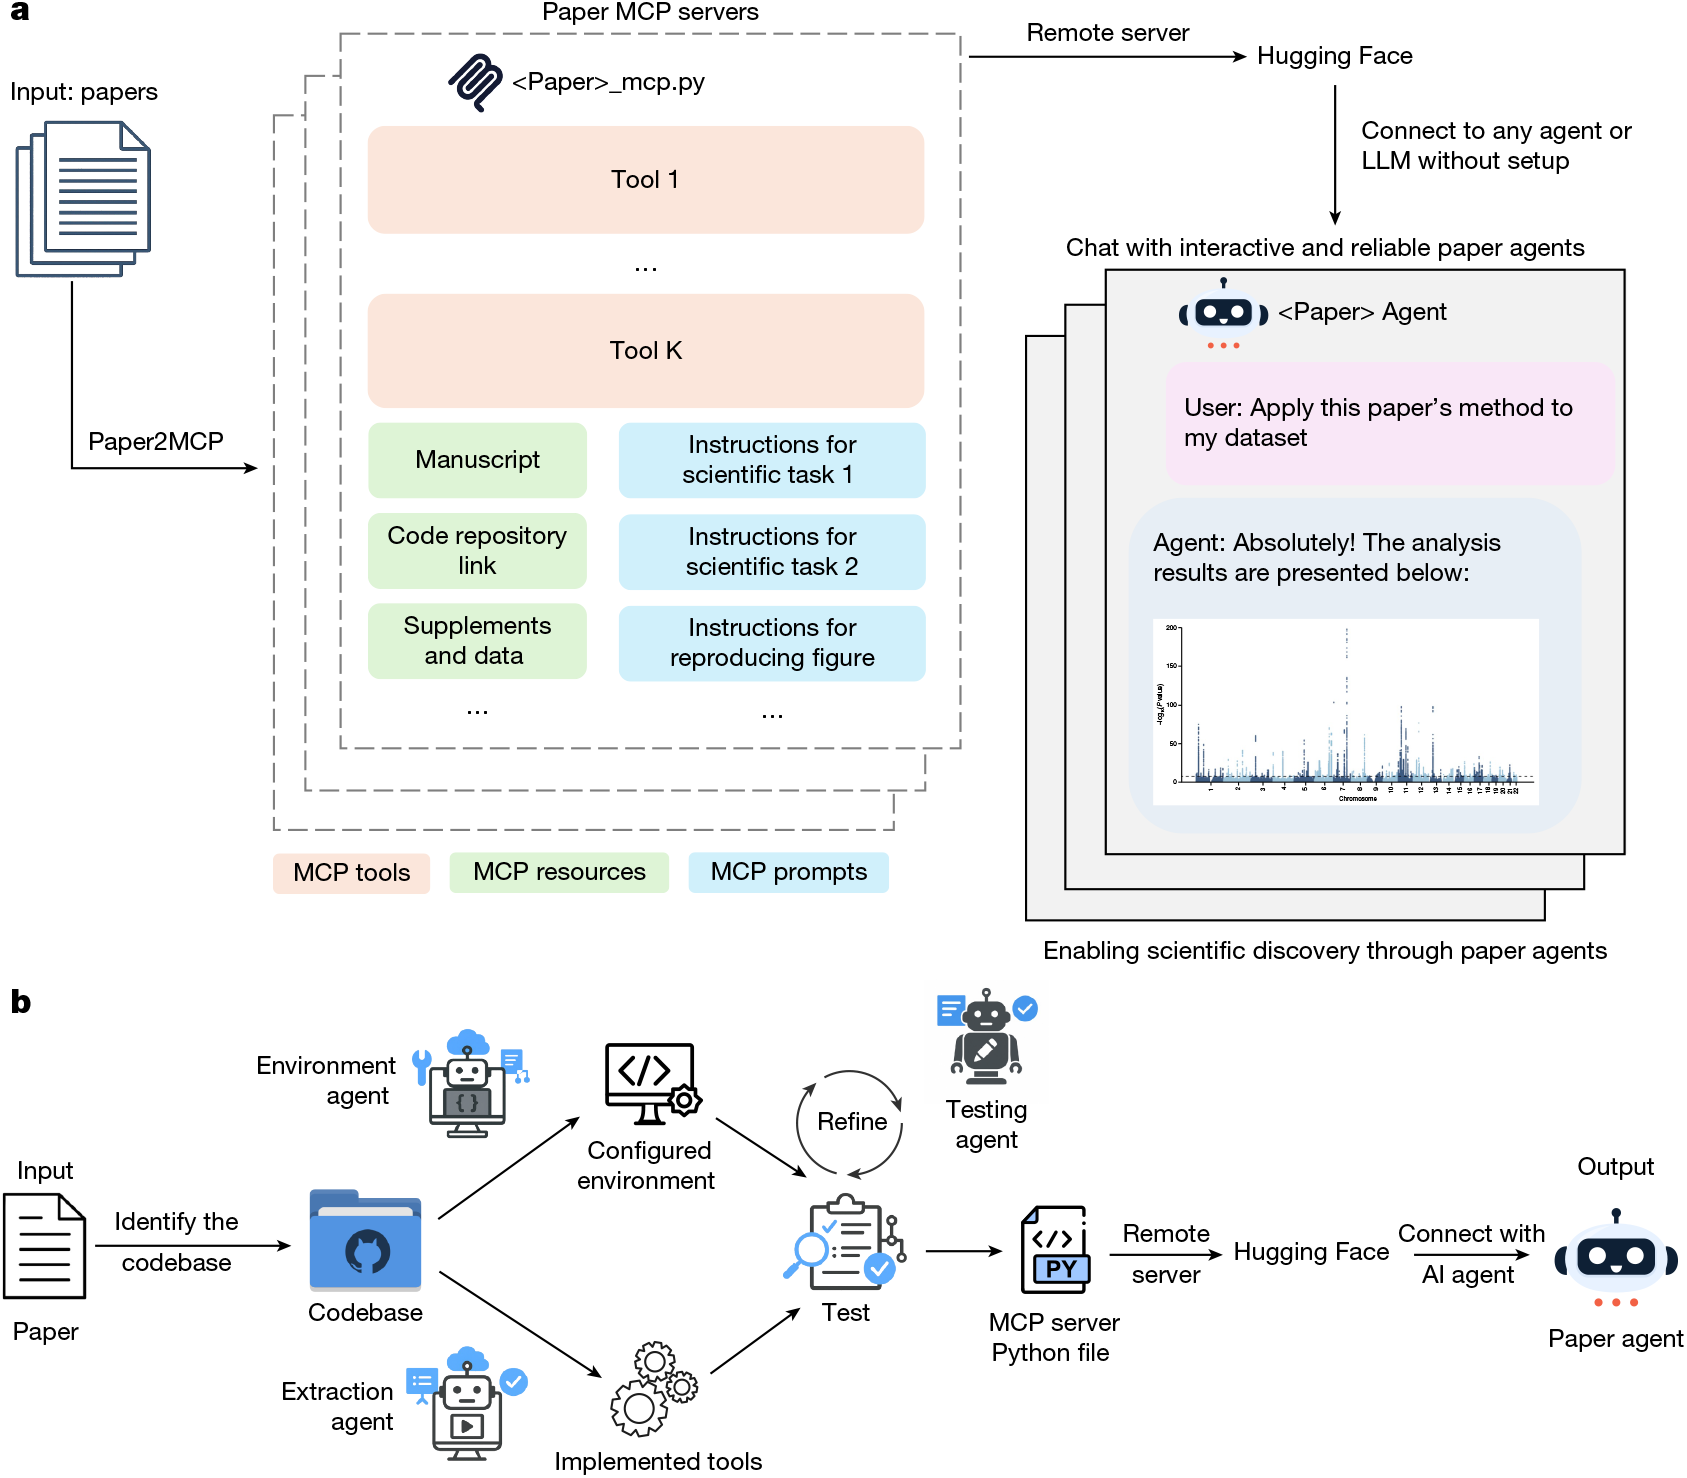
Here we introduce Paper2Agent, an automated framework that converts research papers into artificial intelligence (AI) agents. Paper2Agent transforms research output from passive artefacts into active systems that accelerate use and discovery. Conventional research papers require readers to understand and adapt the paper’s code, data and methods to their work, creating barriers to dissemination and reuse. Paper2Agent addresses this challenge by converting a paper into an AI agent that functions as a virtual corresponding author, exposing its manuscript, supplementary materials, datasets, code and workflows as active, agent-native knowledge rather than static text. It analyses the paper and codebase using multiple agents to construct a model context protocol (MCP) server, then generates and runs tests to refine and increase robustness of the MCP. These paper MCPs can be connected to a chat agent (such as Claude Code) to carry out complex scientific queries through natural language while invoking tools and workflows from the paper. We demonstrate Paper2Agent’s effectiveness through case studies. Paper2Agent created an agent that leveraged AlphaGenome1 to interpret genomic variants and agents based on Scanpy2 and TISSUE (transcript imputation with spatial single-cell uncertainty estimation)3 to conduct single-cell and spatial transcriptomics analyses. We validate that these agents reproduce the results of the original papers and carry out novel user queries. Paper2Agent created multiple agents that collaborate to prioritize a causal gene for psoriasis. By turning static papers into interactive AI agents, Paper2Agent introduces a paradigm for knowledge dissemination and a collaborative ecosystem of AI co-scientists.
Reimagining research papers as interactive and reliable AI agents
Here we introduce Paper2Agent, an automated framework that converts research papers into artificial intelligence (AI) agents. Paper2Agent transforms research output from passive artefacts into active systems that accelerate use and discovery. Conventional research papers require readers to understand and adapt the paper’s code, data and methods to their work, creating barriers to dissemination and reuse. Paper2Agent addresses this challenge by converting a paper into an AI agent that functions as a virtual corresponding author, exposing its manuscript, supplementary materials, datasets, code and workflows as active, agent-native knowledge rather than static text. It analyses the paper and codebase using multiple agents to construct a model context protocol (MCP) server, then generates and runs tests to refine and increase robustness of the MCP. These paper MCPs can be connected to a chat agent (such as Claude Code) to carry out complex scientific queries through natural language while invoking tools and workflows from the paper. We demonstrate Paper2Agent’s effectiveness through case studies. Paper2Agent created an agent that leveraged AlphaGenome1 to interpret genomic variants and agents based on Scanpy2 and TISSUE (transcript imputation with spatial single-cell uncertainty estimation)3 to conduct single-cell and spatial transcriptomics analyses. We validate that these agents reproduce the results of the original papers and carry out novel user queries. Paper2Agent created multiple agents that collaborate to prioritize a causal gene for psoriasis. By turning static papers into interactive AI agents, Paper2Agent introduces a paradigm for knowledge dissemination and a collaborative ecosystem of AI co-scientists.
EurekaBench: Measuring Agentic Ability to Discover New Scientific Insights
When Isaac Newton discovered the law of gravitation, he did so through an iterative process of analyzing observed data such as planetary patterns, finding the underlying mechanisms by describing patterns in mathematical equations, and refining his theory against the Moon's orbit, revealing the startling insight that the same force governs both falling apples and orbiting planets. Would it be possible for AI agents to make similar discoveries? To measure this ability, we introduce EurekaBench, a cross-domain benchmark that tests AI agents' ability to conduct long-horizon experiments and discover mechanisms that explain observations. We evaluate these mechanisms by the scientific insights that can be derived from them. EurekaBench contains an expert-verified set of 26 long-horizon tasks across neuroscience, computer science, chemistry, astrophysics, geophysics, and plasma physics, with a total of 306 scientific insights that the discovered mechanisms are expected to support. Our evaluation framework tests three axes of scientific discovery: agents' ability to follow known scientific constraints, the predictive accuracy of the discovered mechanisms, and whether these mechanisms yield scientific insights or inform future research. Our results show that current AI agents often overly fixate on predictive accuracy optimization, surpassing human scientists, while falling substantially short in deriving scientific insights.
AI Research Agents Narrow Scientific Exploration
AI research agents now support large-scale AI-assisted scientific discovery. We examine whether AI-generated ideas broaden scientific exploration or primarily reinforce existing work. Using five agent frameworks and five large language models, we generate 219,655 ideas for different scientific fields. Across experiments, four consistent patterns emerge. First, AI-generated ideas are more concentrated than human-authored papers within the same research area. Second, they remain much closer to starting literature than later human follow-on work does. Third, AI-generated ideas align less with future human research. Last, AI-generated ideas are located in lower-impact regions of the historical scientific landscape. Overall, current AI research agents appear better suited to local elaboration than to broadening scientific exploration.
Training AI Scientists to Replicate Research
The replicability of papers is a cornerstone of scientific knowledge, ensuring the reliability of existing results and providing a base for further experiments. The act of replication typically illuminates details that were previously underspecified, and thus requires similar hypothesis-driven exploration to open-ended research. In this work, we develop Replica, a scalable task space for paper replication. To provide reward signal, we introduce an auto-generated rubric-based judge that has low noise and agrees with human assessment of replication quality. We post-train Faraday, a 27B-parameter "AI Scientist" agent that leverages coding agents as tools, surpassing the performance of Claude Opus 4.8 and GPT-5.5 on held-out replication tasks. Qualitative analysis of individual rollouts reveals that Faraday adopts a more scientifically-principled approach. We believe that our results provide a stepping stone towards AI agents capable of long-horizon scientific innovation without requiring complex harnesses.
Accelerating Scientific Research with Gemini: Case Studies and Common Techniques
Recent advances in large language models (LLMs) have opened new avenues for accelerating scientific research. While models are increasingly capable of assisting with routine tasks, their ability to contribute to novel, expert-level mathematical discovery is less understood. We present a collection of case studies demonstrating how researchers have successfully collaborated with advanced AI models, specifically Google's Gemini-based models (in particular Gemini Deep Think and its advanced variants), to solve open problems, refute conjectures, and generate new proofs across diverse areas in theoretical computer science, as well as other areas such as economics, optimization, and physics. Based on these experiences, we extract common techniques for effective human-AI collaboration in theoretical research, such as iterative refinement, problem decomposition, and cross-disciplinary knowledge transfer. While the majority of our results stem from this interactive, conversational methodology, we also highlight specific instances that push beyond standard chat interfaces. These include deploying the model as a rigorous adversarial reviewer to detect subtle flaws in existing proofs, and embedding it within a "neuro-symbolic" loop that autonomously writes and executes code to verify complex derivations. Together, these examples highlight the potential of AI not just as a tool for automation, but as a versatile, genuine partner in the creative process of scientific discovery.
PaperOrchestra: A Multi-Agent Framework for Automated AI Research Paper Writing
Synthesizing unstructured research materials into manuscripts is an essential yet under-explored challenge in AI-driven scientific discovery. Existing autonomous writers are rigidly coupled to specific experimental pipelines, and produce superficial literature reviews. We introduce PaperOrchestra, a multi-agent framework for automated AI research paper writing. It flexibly transforms unconstrained pre-writing materials into submission-ready LaTeX manuscripts, including comprehensive literature synthesis and generated visuals, such as plots and conceptual diagrams. To evaluate performance, we present PaperWritingBench, the first standardized benchmark of reverse-engineered raw materials from 200 top-tier AI conference papers, alongside a comprehensive suite of automated evaluators. In side-by-side human evaluations, PaperOrchestra significantly outperforms autonomous baselines, achieving an absolute win rate margin of 50%-68% in literature review quality, and 14%-38% in overall manuscript quality.
ScienceIDE: Turning World's Scientific Codebase into Agent Learnable Environments
Scientific code repositories encode decades of human knowledge in executable models, methods, and tools. Yet fragmented toolchains, implicit domain conventions, and specialized correctness criteria make this knowledge difficult to convert into reliable learning experience-a challenge we call the scientific experience bottleneck. We introduce ScienceIDE, infrastructure for turning the world's scientific code into programmable environments for scientific agents. Guided by expert-defined scientific cases and acceptance criteria, agents transform repositories into executable environments that support task generation, execution, and scientific verification. These environments provide a shared foundation for supervised fine-tuning, reinforcement learning, and evaluation. Using verified interaction trajectories, we train PhAI-IDE-72B, PhAI-IDE-9B, and PhAI-IDE-4B. The model family shows gains in held-out scientific-code repair and across selected general-purpose benchmarks in code, reasoning, and knowledge, providing evidence of positive transfer from scientific experience to broader capabilities. ScienceIDE lays the foundation for an integrated workspace for agent learning and scientific practice, making humanity's scientific software a shared substrate for developing scientific intelligence. Code: https://github.com/aitofound/ScienceIDE
Deep Research, information vs. insight, and the nature of science
What AI will accelerate in the scientific process, what it cannot do, and how we can prepare for new manners of scientific investigation.
Can AI Agents Synthesize Scientific Conclusions?
Scientific AI agents increasingly retrieve evidence, reason across sources, and synthesize conclusions used in consequential decisions. Yet, their ability to do so in high-stakes domains such as health remains unclear. We introduce SciConBench, a large-scale live benchmark of 9.11K questions and expert-written conclusions from systematic reviews to evaluate open-domain scientific conclusion synthesis. The benchmark draws on an expert-validated automated evaluation pipeline that decomposes conclusions into atomic facts and measures correctness and comprehensiveness via factual precision and recall. To mitigate data leakage, we further introduce SciConHarness, a clean-room evaluation harness that equips agents with controlled web interaction to ensure valid measurement. Evaluating 8 frontier models and deep research agents, we find that factual quality remains low: under clean-room settings, the best agent achieves only a factual F1 of 0.337. Our clean-room setting consistently reduces performance relative to unconstrained evaluation, suggesting that leakage inflates estimates of models' true synthesis capabilities. Finally, we audit consumer-facing agents (e.g., Google AI Overview, OpenEvidence) and find they frequently generate incomplete and sometimes contradictory conclusions, even when the ground-truth answer is available. Overall, our results show that reliable synthesis of scientific conclusions remains an open challenge, and that clean-room evaluation is essential for assessing open-domain AI agents.
Networked Intelligence: Active Shared Context Graphs for Human-AI Team Science
Most AI-for-science systems focus on scaling a single reasoning process by using better models, larger context windows, long-horizon agentic execution, or digital co-scientists working with one principal user. However, challenging scientific problems are rarely solved by one reasoner alone. They are solved by teams whose members carry different priors, experimental background, tacit knowledge, and domain-trained intuitions. The open problem is therefore not only how to scale models, but how to develop "networked intelligence", scaling the connections between humans and AI systems so that a result or hypothesis produced in one context reaches another person, agent, instrument or robot that can act on it. We introduce Mycelium, an active shared workspace that automatically connects researchers and AI agents. As human users and agents work, the system captures important observations and hypotheses, tracks how they relate to the team's evolving knowledge model, and routes them to the person or agent whose next decision they can inform. We evaluate Mycelium through a real-world scientific discovery use case: a biological multi-omics campaign where shared context turned a local analytical finding into a cross-expert mechanistic constraint and ultimately into an experimental design. Finally, we describe networked intelligence as sparse conditional computation over distributed scientific contexts. This framework establishes when a scaled standalone agent is sufficient, and when isolated data and specialized expertise make a networked approach essential.
Large Knowledge Model: From Papers to a Scientific Reasoning Landscape
Accumulated scientific knowledge advances inquiry when prior findings help researchers choose new questions, design investigations, and interpret results. Realizing this value at scale requires access to the reasoning that connects research problems, scientific procedures, conclusions, and evidence. We introduce the Large Knowledge Model (LKM), a scientific knowledge infrastructure that transforms the literature into a shared, computationally accessible reasoning resource. LKM represents papers as source-grounded reasoning graphs, couples structural traversal with semantic retrieval over the same objects, and aligns related questions, claims, and reasoning chains across papers. This representation forms a Scientific Reasoning Landscape with three connected views: a Question Landscape that organizes research problems and open directions, a Workflow Landscape that exposes reusable scientific procedures, and an Evidence Landscape that connects conclusions to their support, disagreement, and conditions. The unified substrate supports reasoning-aware scientific search, evidence-grounded question answering, comparative evidence analysis, and research planning. Researchers and agents can retrieve relevant work through its scientific intent, synthesize answers with inspectable supporting arguments, and develop research plans informed by established workflows and unresolved evidence. We describe a corpus-scale system and evaluate scientific retrieval and knowledge-intensive question answering. With the answering model fixed, LKM retrieval improves accuracy by 9.30%, 4.20%, and 14.69% on ChemBench, PubMedQA, and SciBench, respectively. By connecting knowledge access to scientific reasoning and action, LKM provides a common foundation for discovering relevant research, reusing scientific knowledge, and coordinating cumulative inquiry across researchers, agents, and research cycles.