The increasing demand for GPU-accelerated machine learning inference has exposed limitations in centralized GPU infrastructures, including…
Alex Cheema on Twitter / X
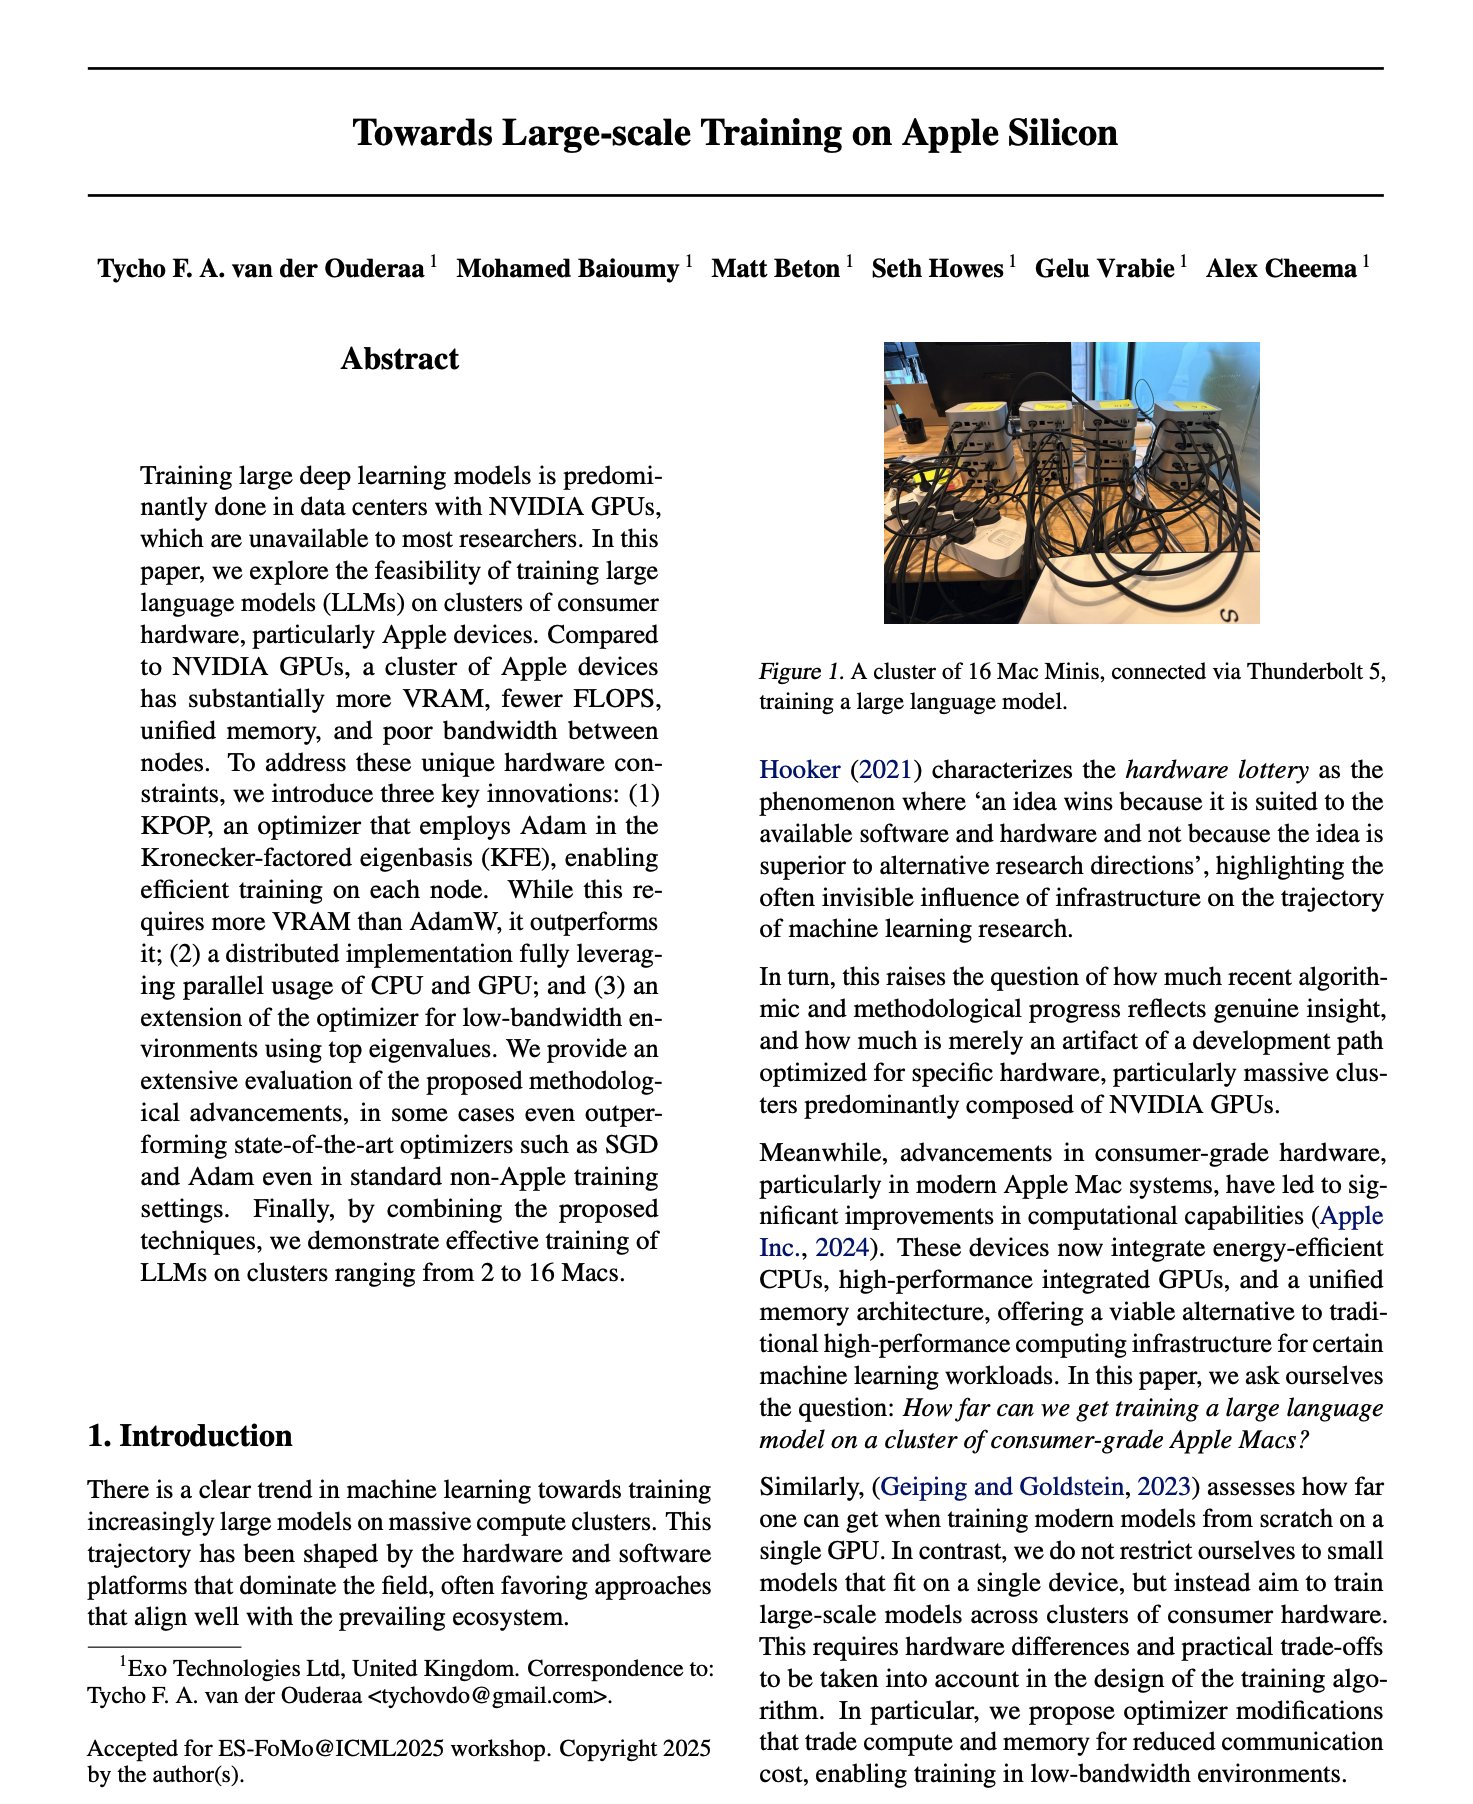
A new approach to efficient large scale distributed training on Apple Silicon.Most AI research today is focused on traditional GPUs. These GPUs have a LOT of FLOPS but not much memory. They have a low memory:flops ratio. Apple Silicon has a lot more memory available for the GPU… https://t.co/FsNFnsvphJ pic.twitter.com/LFE1gtAm33— Alex Cheema (@alexocheema) July 11, 2025
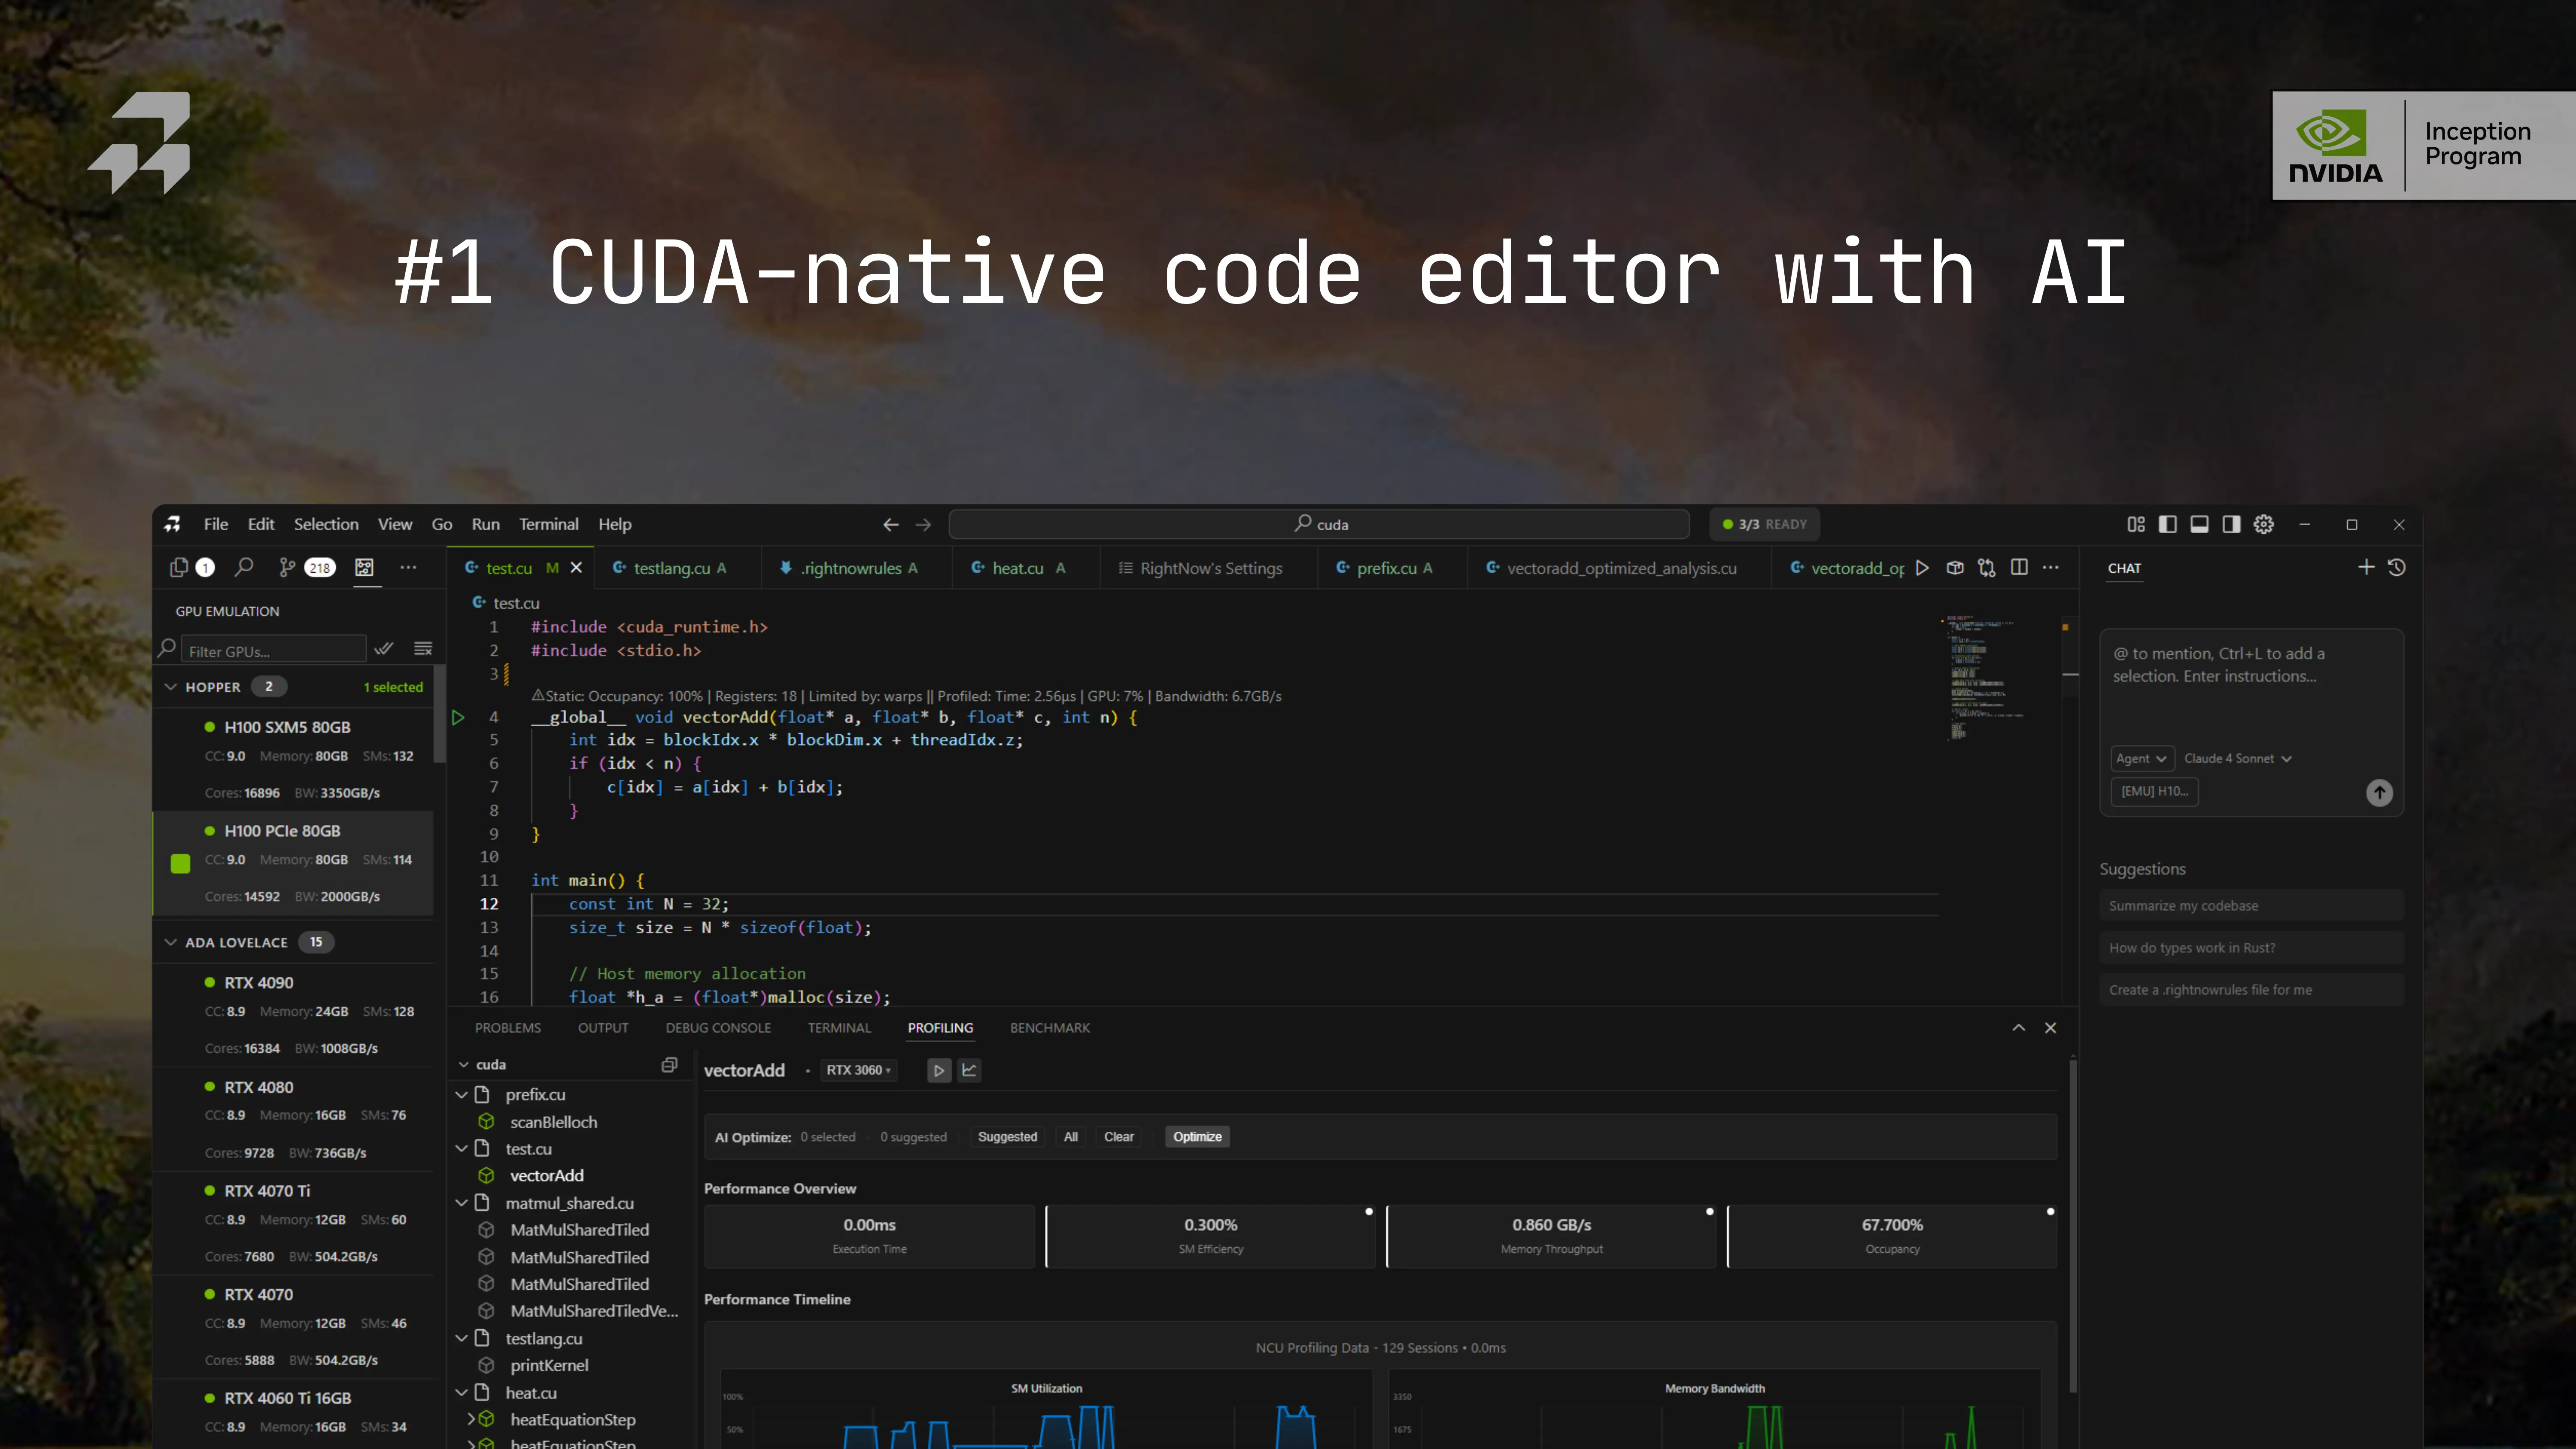
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
Open Source AI Inference Benchmark | InferenceX
Compare AI inference performance across GPUs and frameworks. Real benchmarks on NVIDIA GB200, B200, AMD MI355X, and more. Free, open-source, continuously updated.
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…
Together AI | The AI Native Cloud
Build what's next on the AI Native Cloud. Full-stack AI platform for inference, fine-tuning, and GPU clusters — powered by cutting-edge research.
Mesh LLM: distributed AI computing on iroh
How Mesh LLM pools existing GPU resources across machines into a single OpenAI-compatible API, built on iroh.
Pricing | Runpod
GPU cloud computing at up to 80% less than hyperscalers. Explore pricing for on-demand Pods, Serverless, Clusters, and Network Storage.
Modern GPU Programming For MLSys — Modern GPU Programming For MLSys
Machine learning systems sit at the heart of modern AI workloads. In these systems, performance often comes down to the quality of a small number of GPU kernels. Attention kernels, LLM prefill and decode kernels, low-precision block-scaled GEMMs, fused MoE layers, and other large fused kernels all directly shape end-to-end speed in both training and serving.
InferenceMAX™: Open Source Inference Benchmarking
NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
Mount Thor — AI Execution Environments on Apple Hardware
Managed macOS environments for AI workloads that require native desktop access, persistent state, or model inference on Apple silicon.
Wafer - Ship the fastest inference in the world
Autonomous AI agents that profile, diagnose, and optimize GPU inference across your entire stack — from kernels to models to production pipelines.

GPU Pricing — Live Platform Rates | Vast.ai
Live GPU pricing on Vast.ai. Prices set by supply and demand across 40+ data centers. On-demand, interruptible, or reserved — find the right GPU at the right price.
Import AI 470: No rights for machines; automating environment generation with SPADE; and building better GPU kernels with Hawkeye
Differential acceleration of cyber, math, and AI