


Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
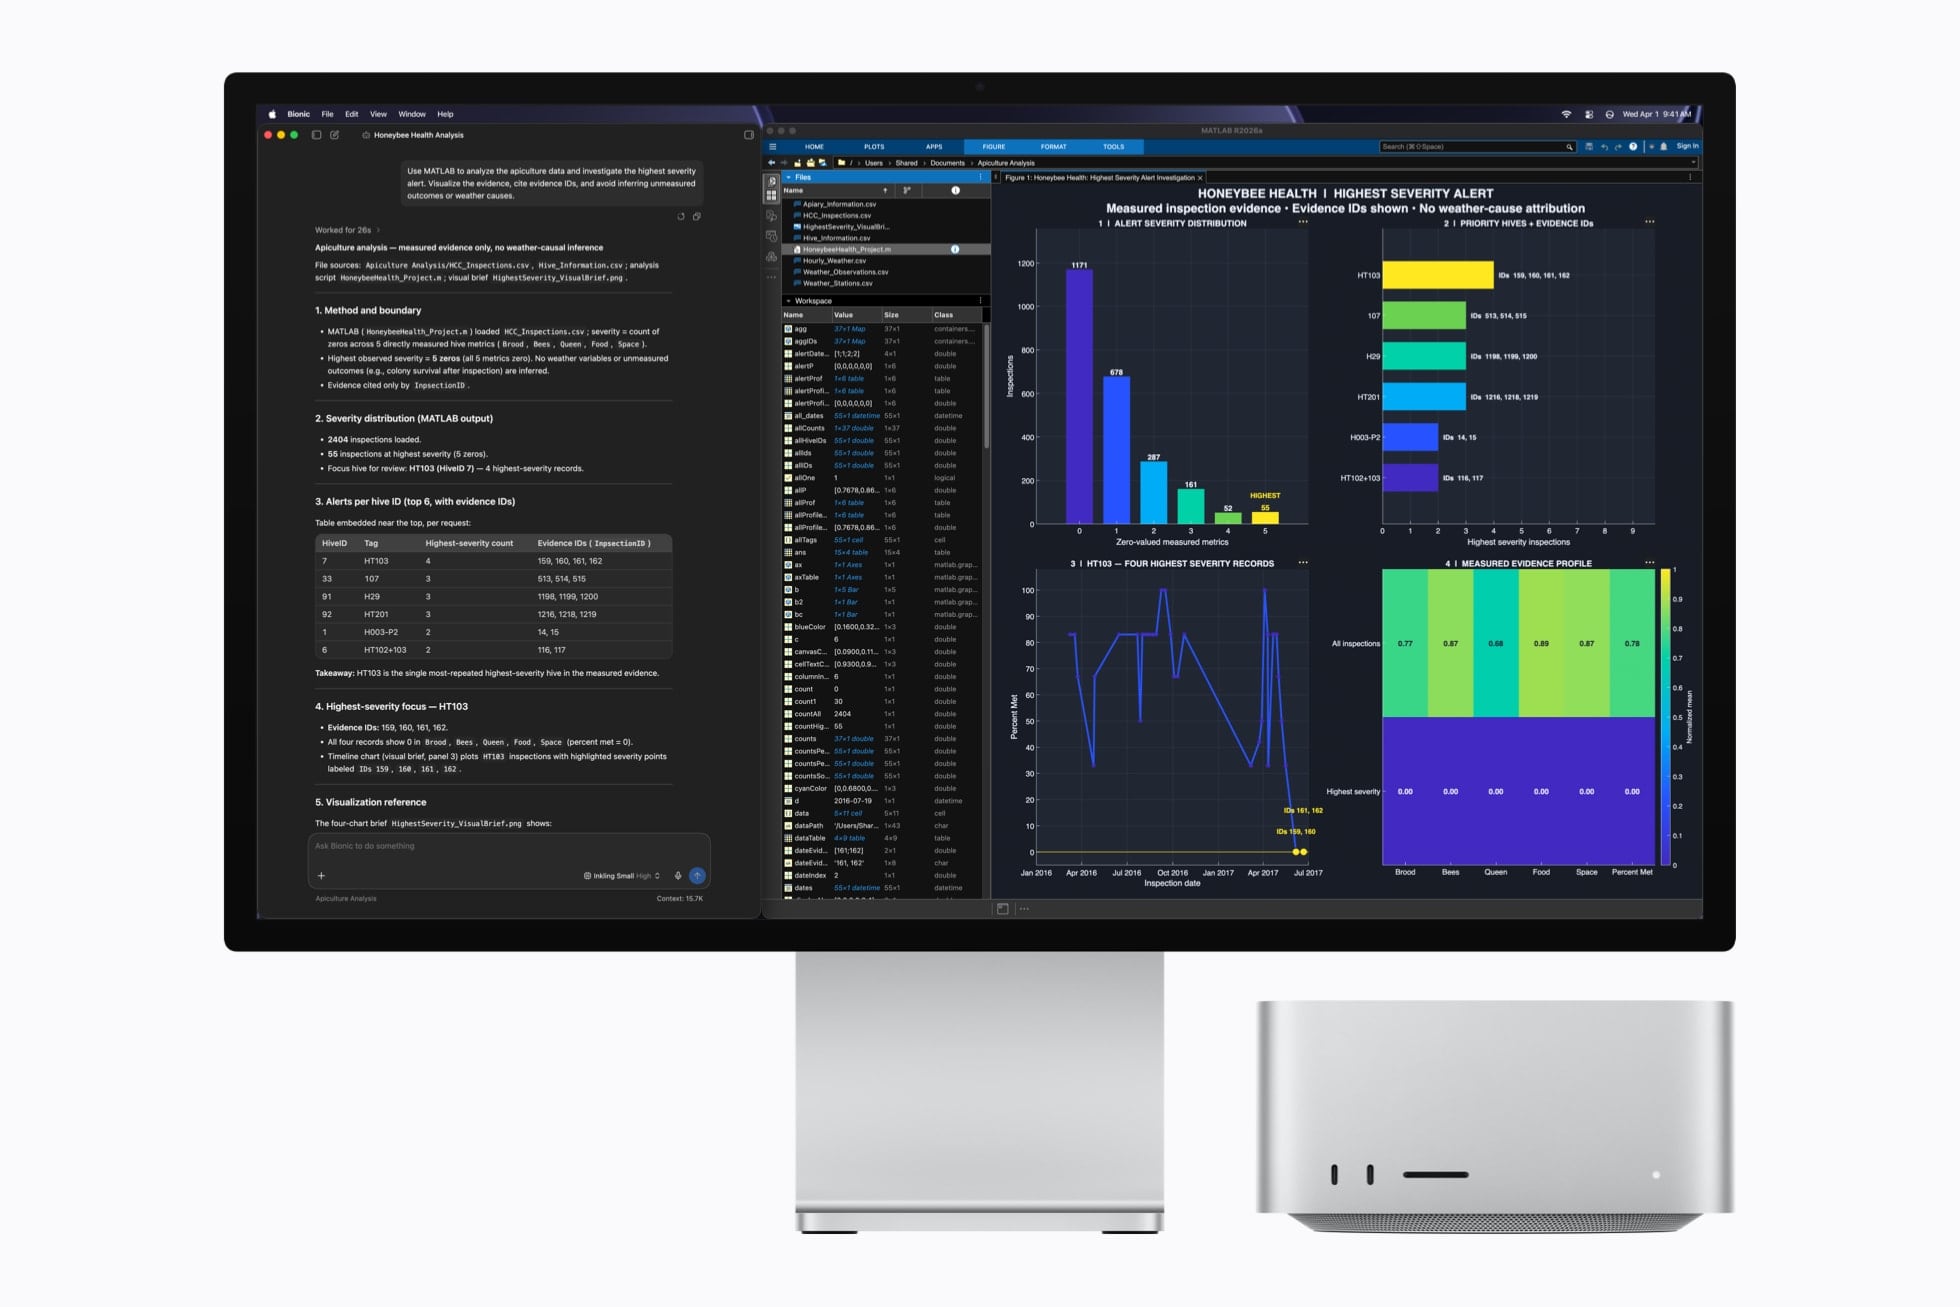
The Potential of M6 and M5 Ultra for Local AI on macOS
Earlier today, Apple unveiled the new generation of Mac mini and Mac Studio, featuring the latest entries in the Apple silicon family of chips: the M6, available in the Mac mini, and the M5 Ultra, exclusive to the Mac Studio. You can read more details about the announcement and related specs in John’s overview. As
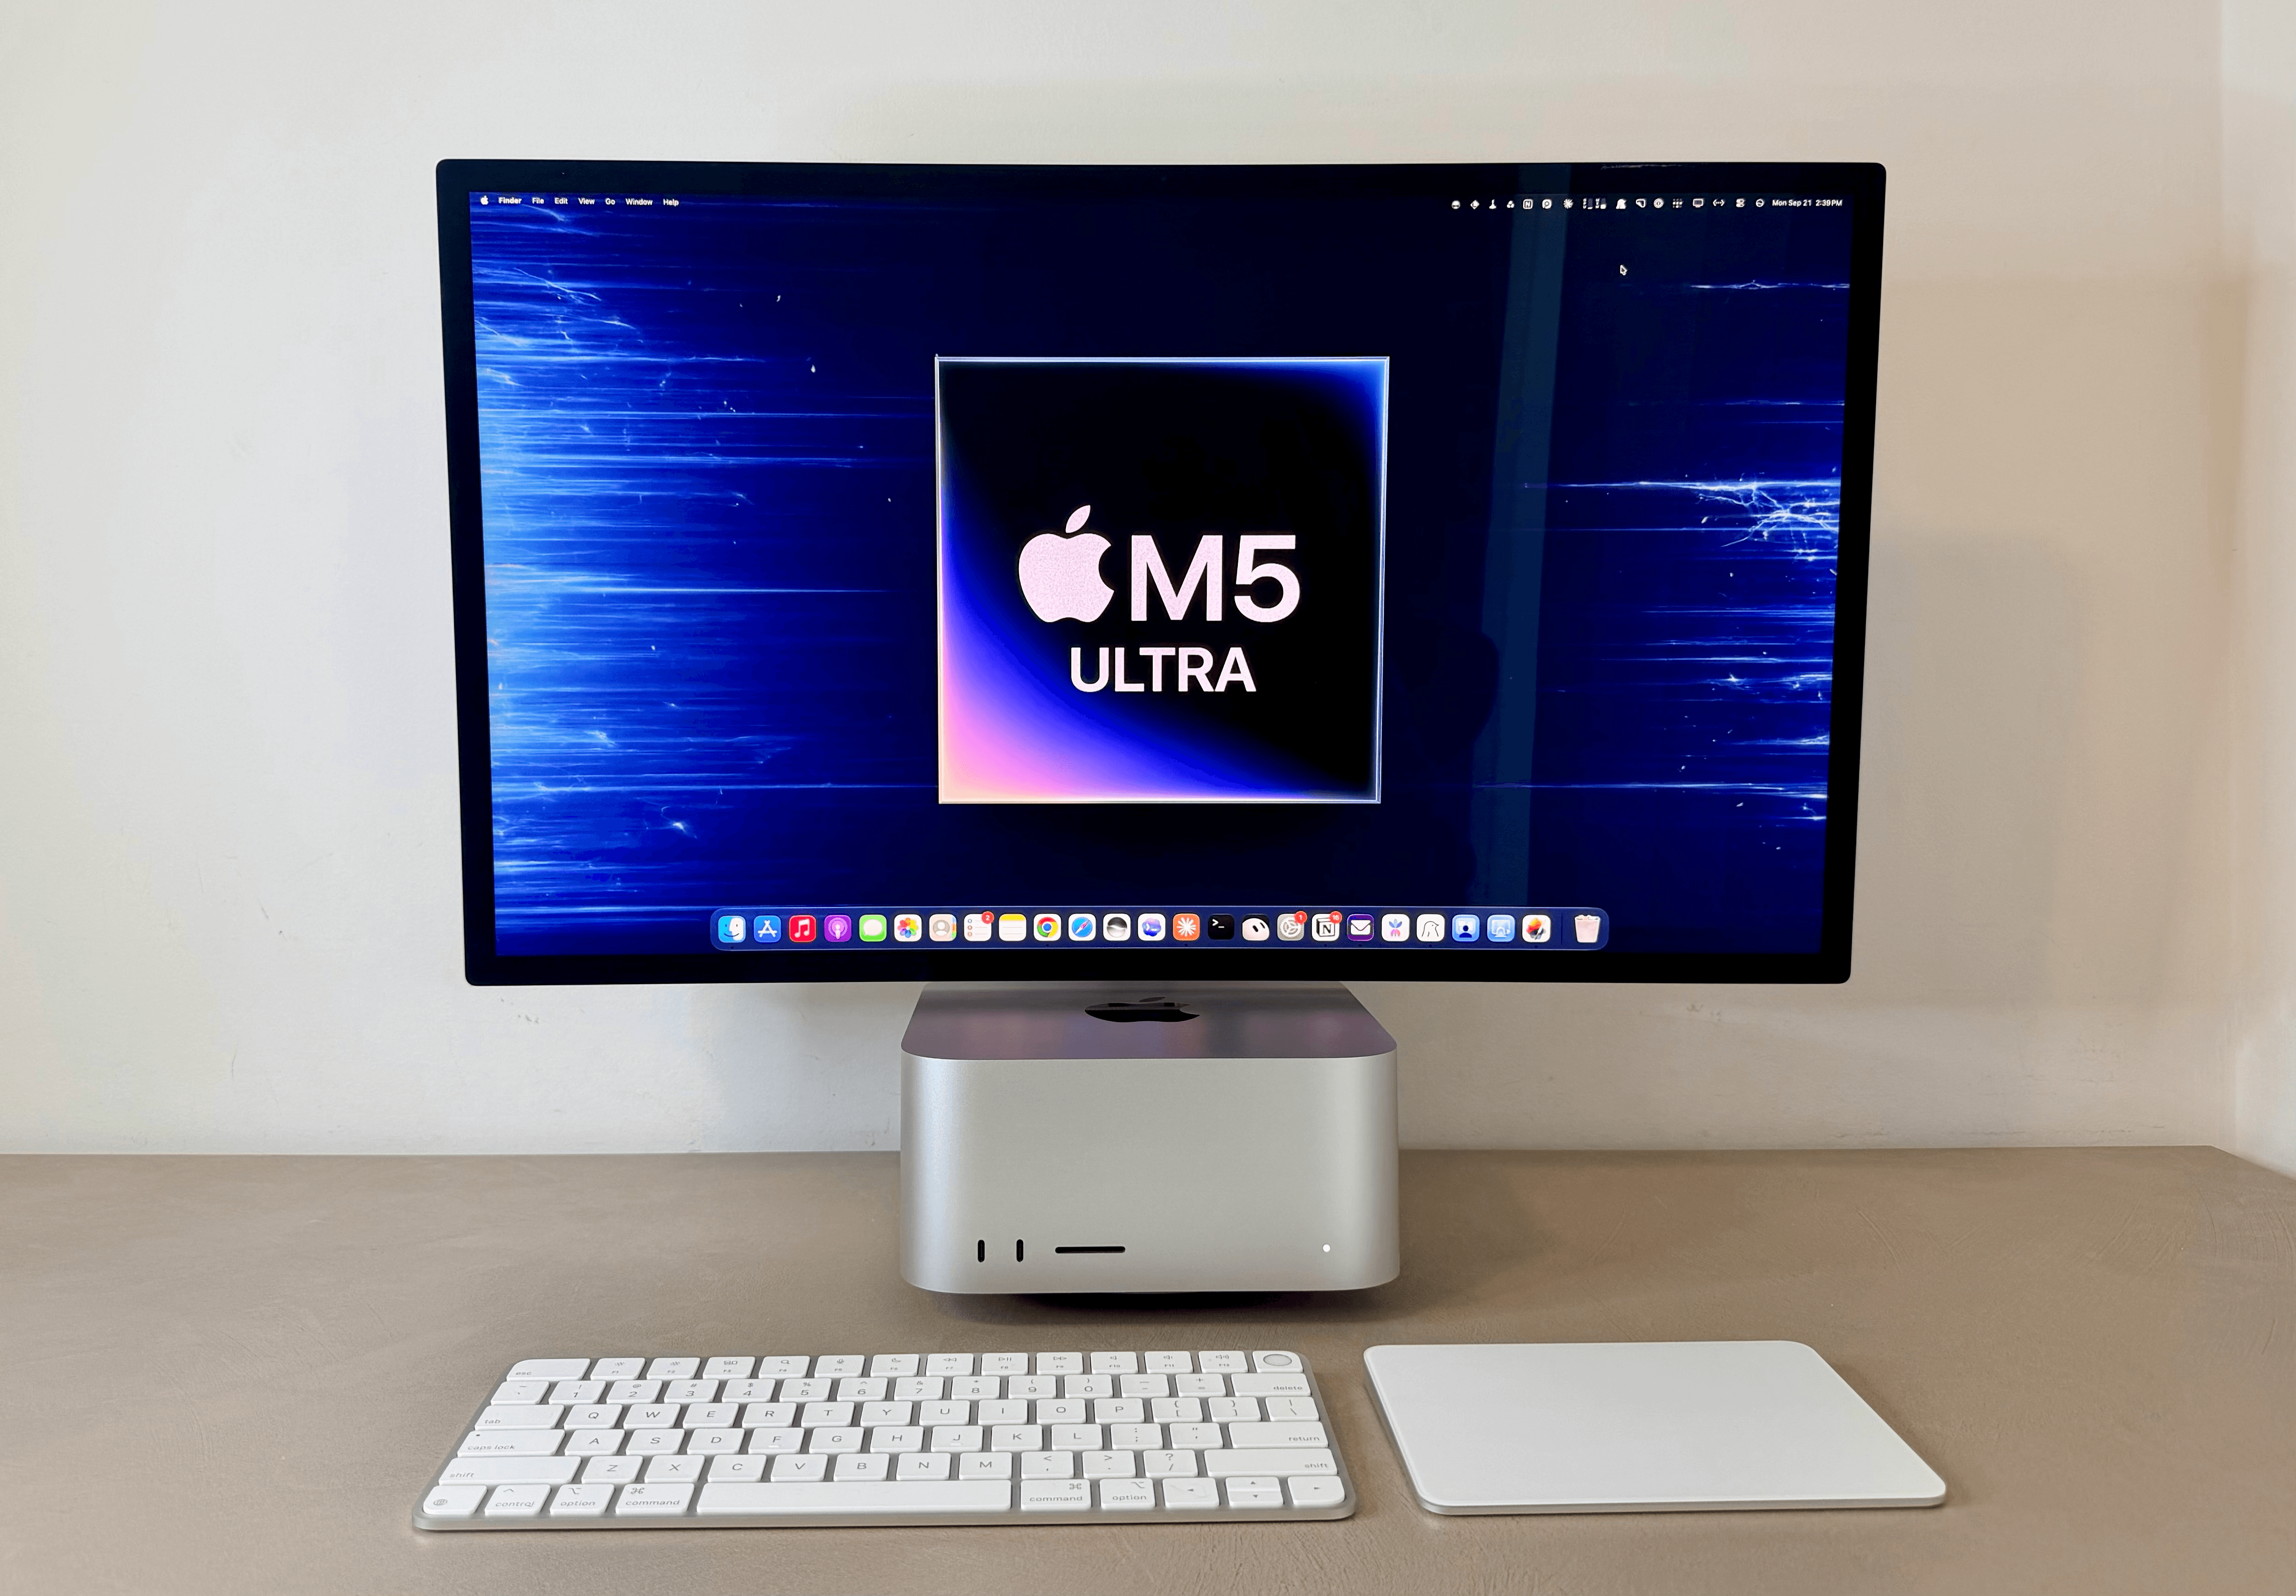
M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents
For the past few days, I’ve been testing the (currently) top-of-the-line M5 Ultra Mac Studio with 256 GB of RAM. I’ll cut to the chase: the M5 Ultra Mac Studio is a dream machine for local AI agents. This computer makes it possible to run personal assistants powered by local models with great performance and
mzau/broke-cluster
A Poor Man's Apple Silicon LLM Cluster — tuned for MLX, scalable without shame.
Doriandarko/MLX-GRPO
A pure MLX-based training pipeline for fine-tuning LLMs using GRPO on Apple Silicon.
Apple introduces M6 and M5 Ultra for a big leap in performance and AI compute
Apple debuted M6 in the new Mac mini and M5 Ultra in the new Mac Studio, providing an extraordinary leap in performance and AI capabilities.

Alex Cheema on Twitter / X
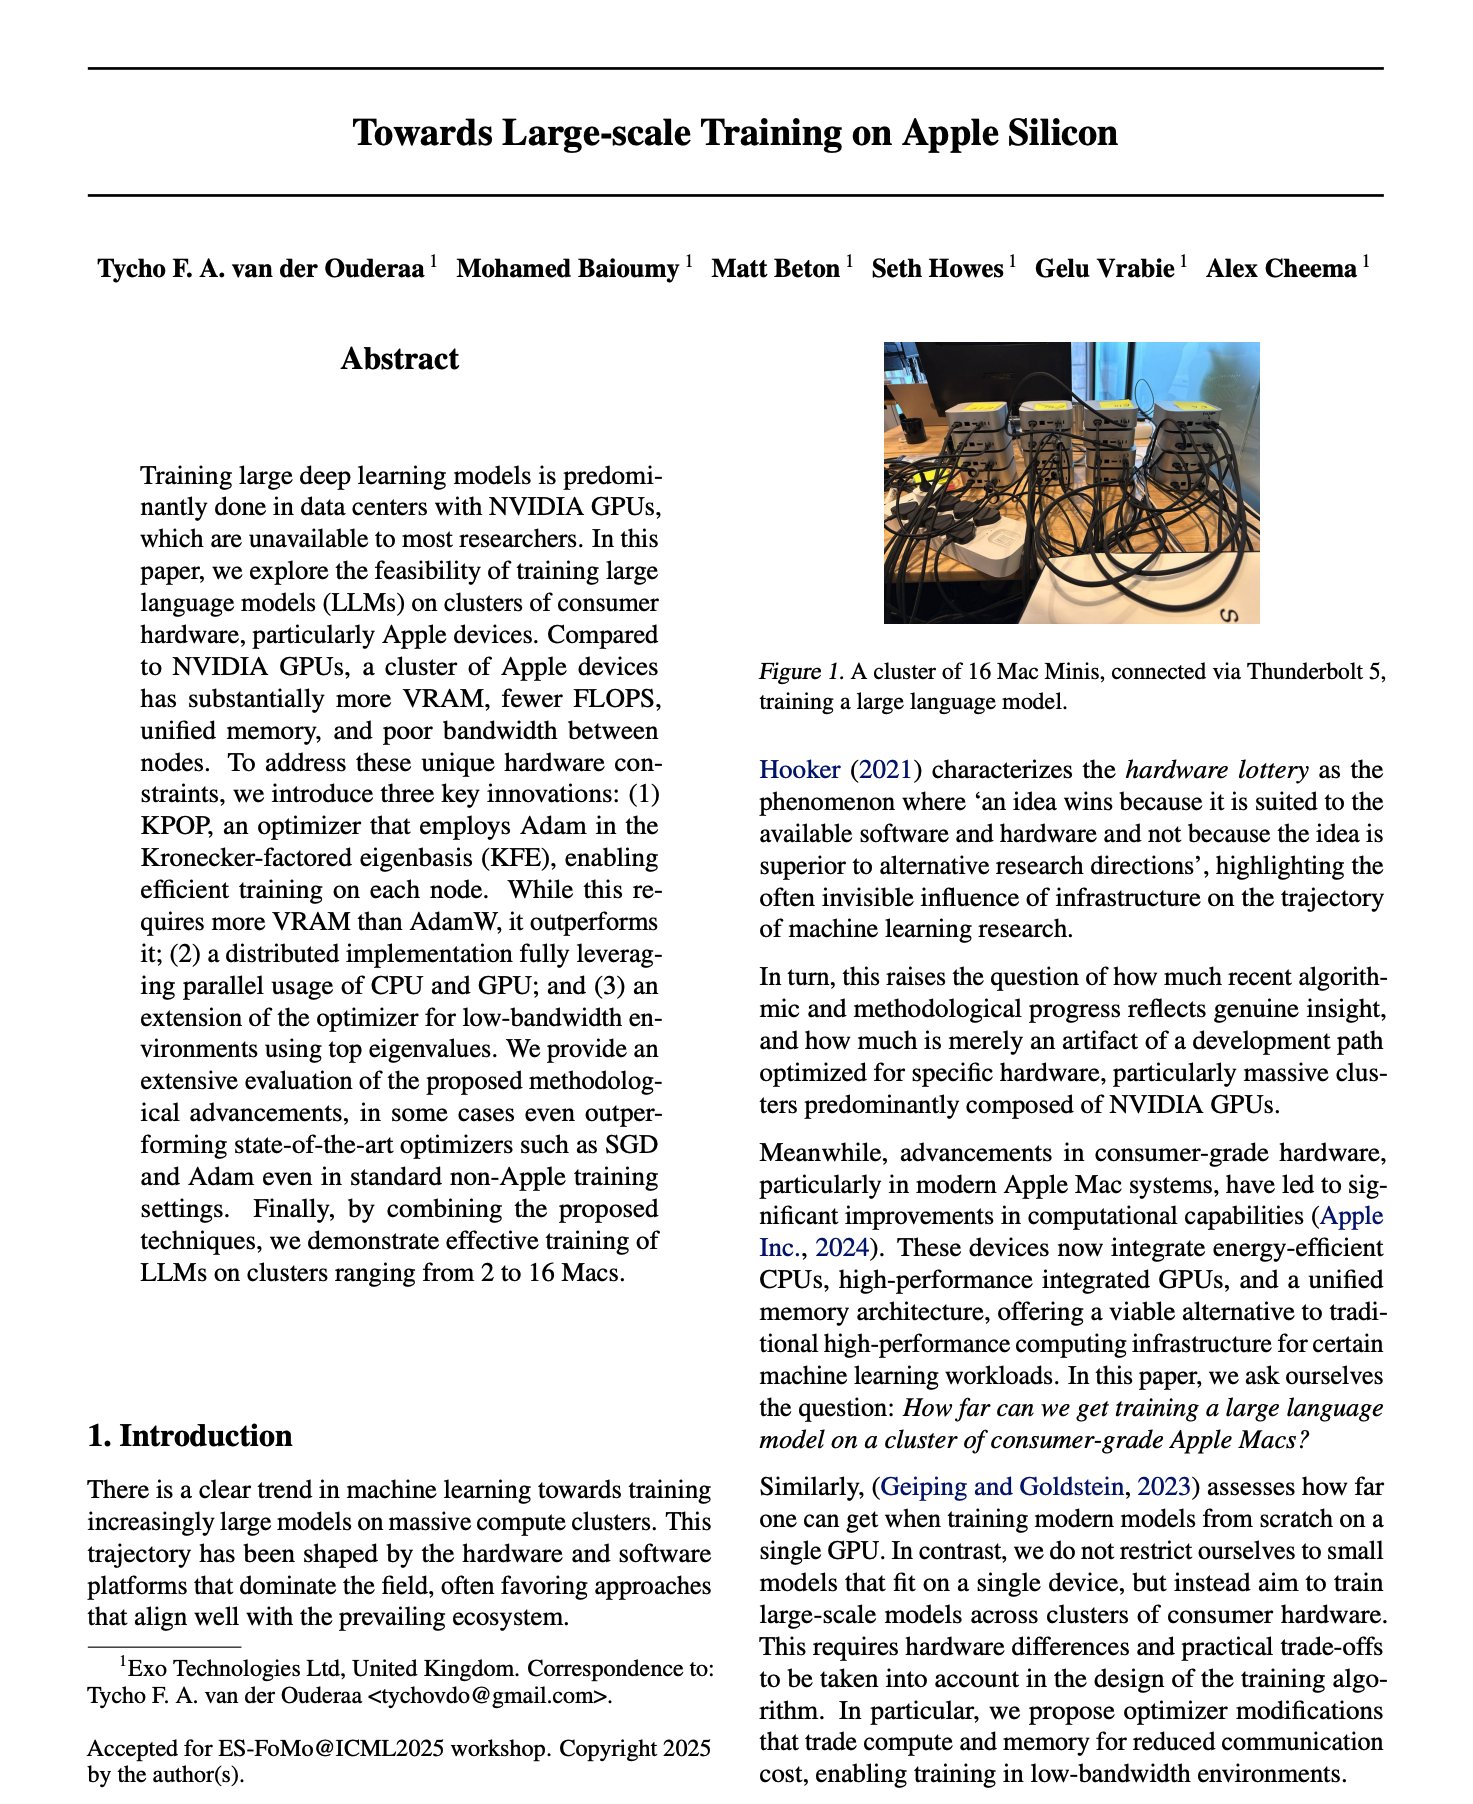
A new approach to efficient large scale distributed training on Apple Silicon.Most AI research today is focused on traditional GPUs. These GPUs have a LOT of FLOPS but not much memory. They have a low memory:flops ratio. Apple Silicon has a lot more memory available for the GPU… https://t.co/FsNFnsvphJ pic.twitter.com/LFE1gtAm33— Alex Cheema (@alexocheema) July 11, 2025
Alex Cheema on Twitter / X
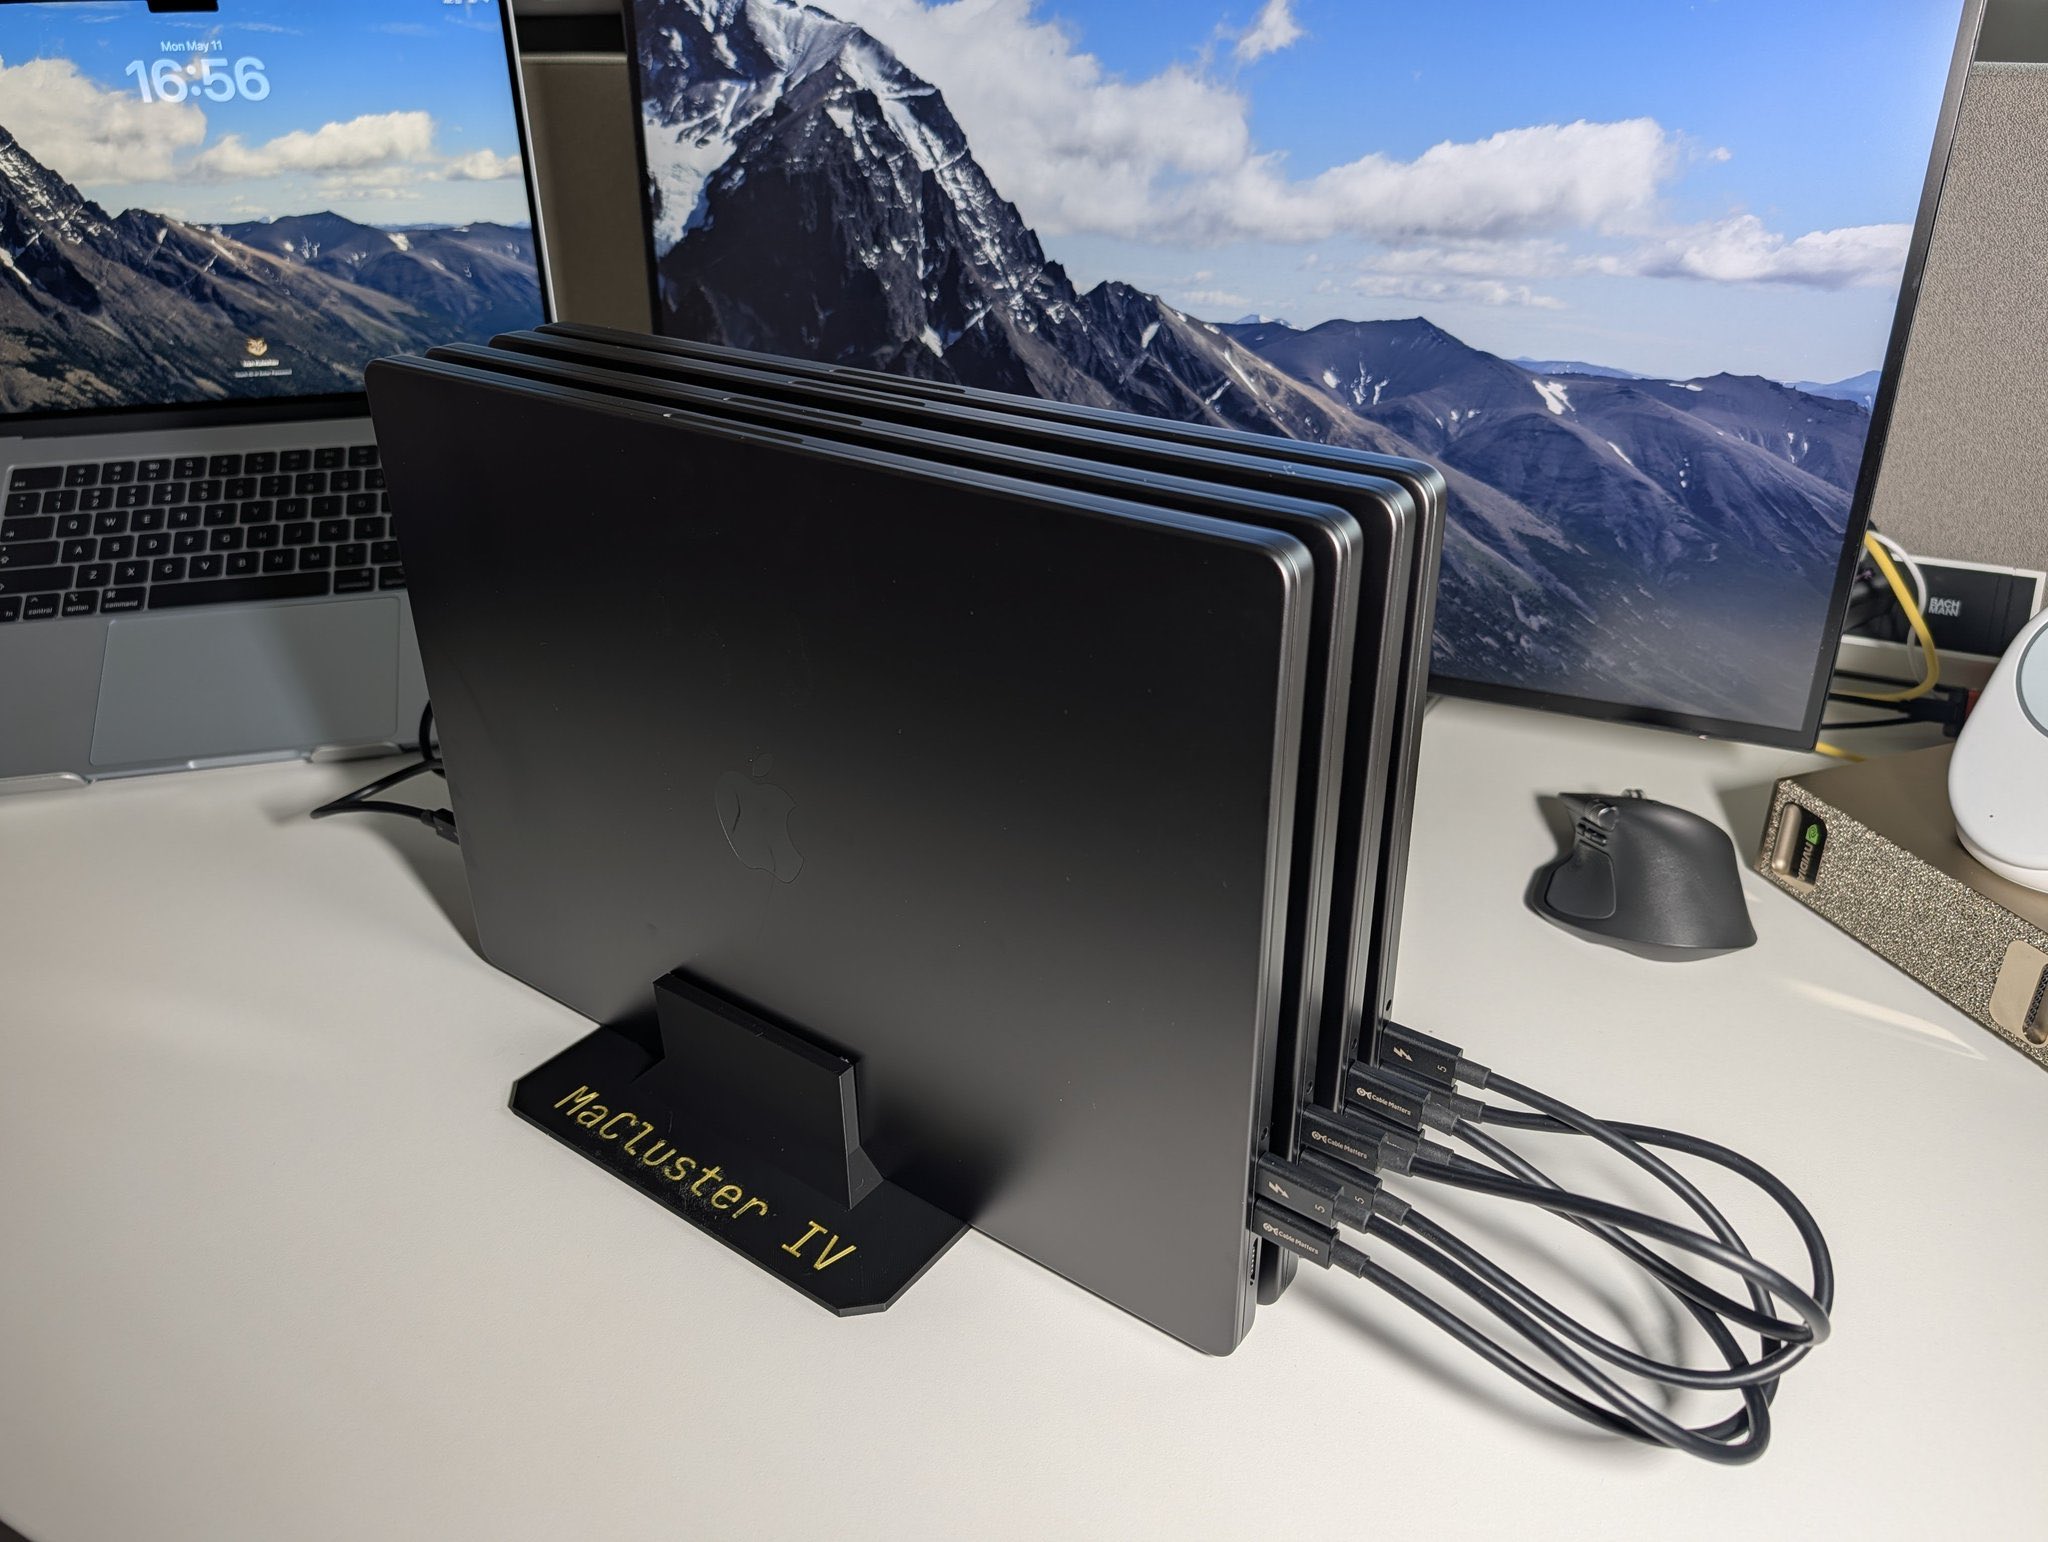
It’s kind of crazy but the shitstorm of supply chain issues has created a new best-in-class local AI deployment: M5 Max MacBook clusters.- The memory unit economics are great - each MacBook has 128GB @ 614GB/s for $5k- M5 Max added tensor cores (Apple Neural Accelerators) with… https://t.co/f8STQ0tLZs pic.twitter.com/FLm3oOnyEl— Alex Cheema (@alexocheema) May 14, 2026
MPS or MLX for Domestic AI? The Answer Will Surprise You
Let’s explore new Apple’s deep learning framework, run modern LLM on a laptop, and find an intriguing hint for performance of PyTorch MPS

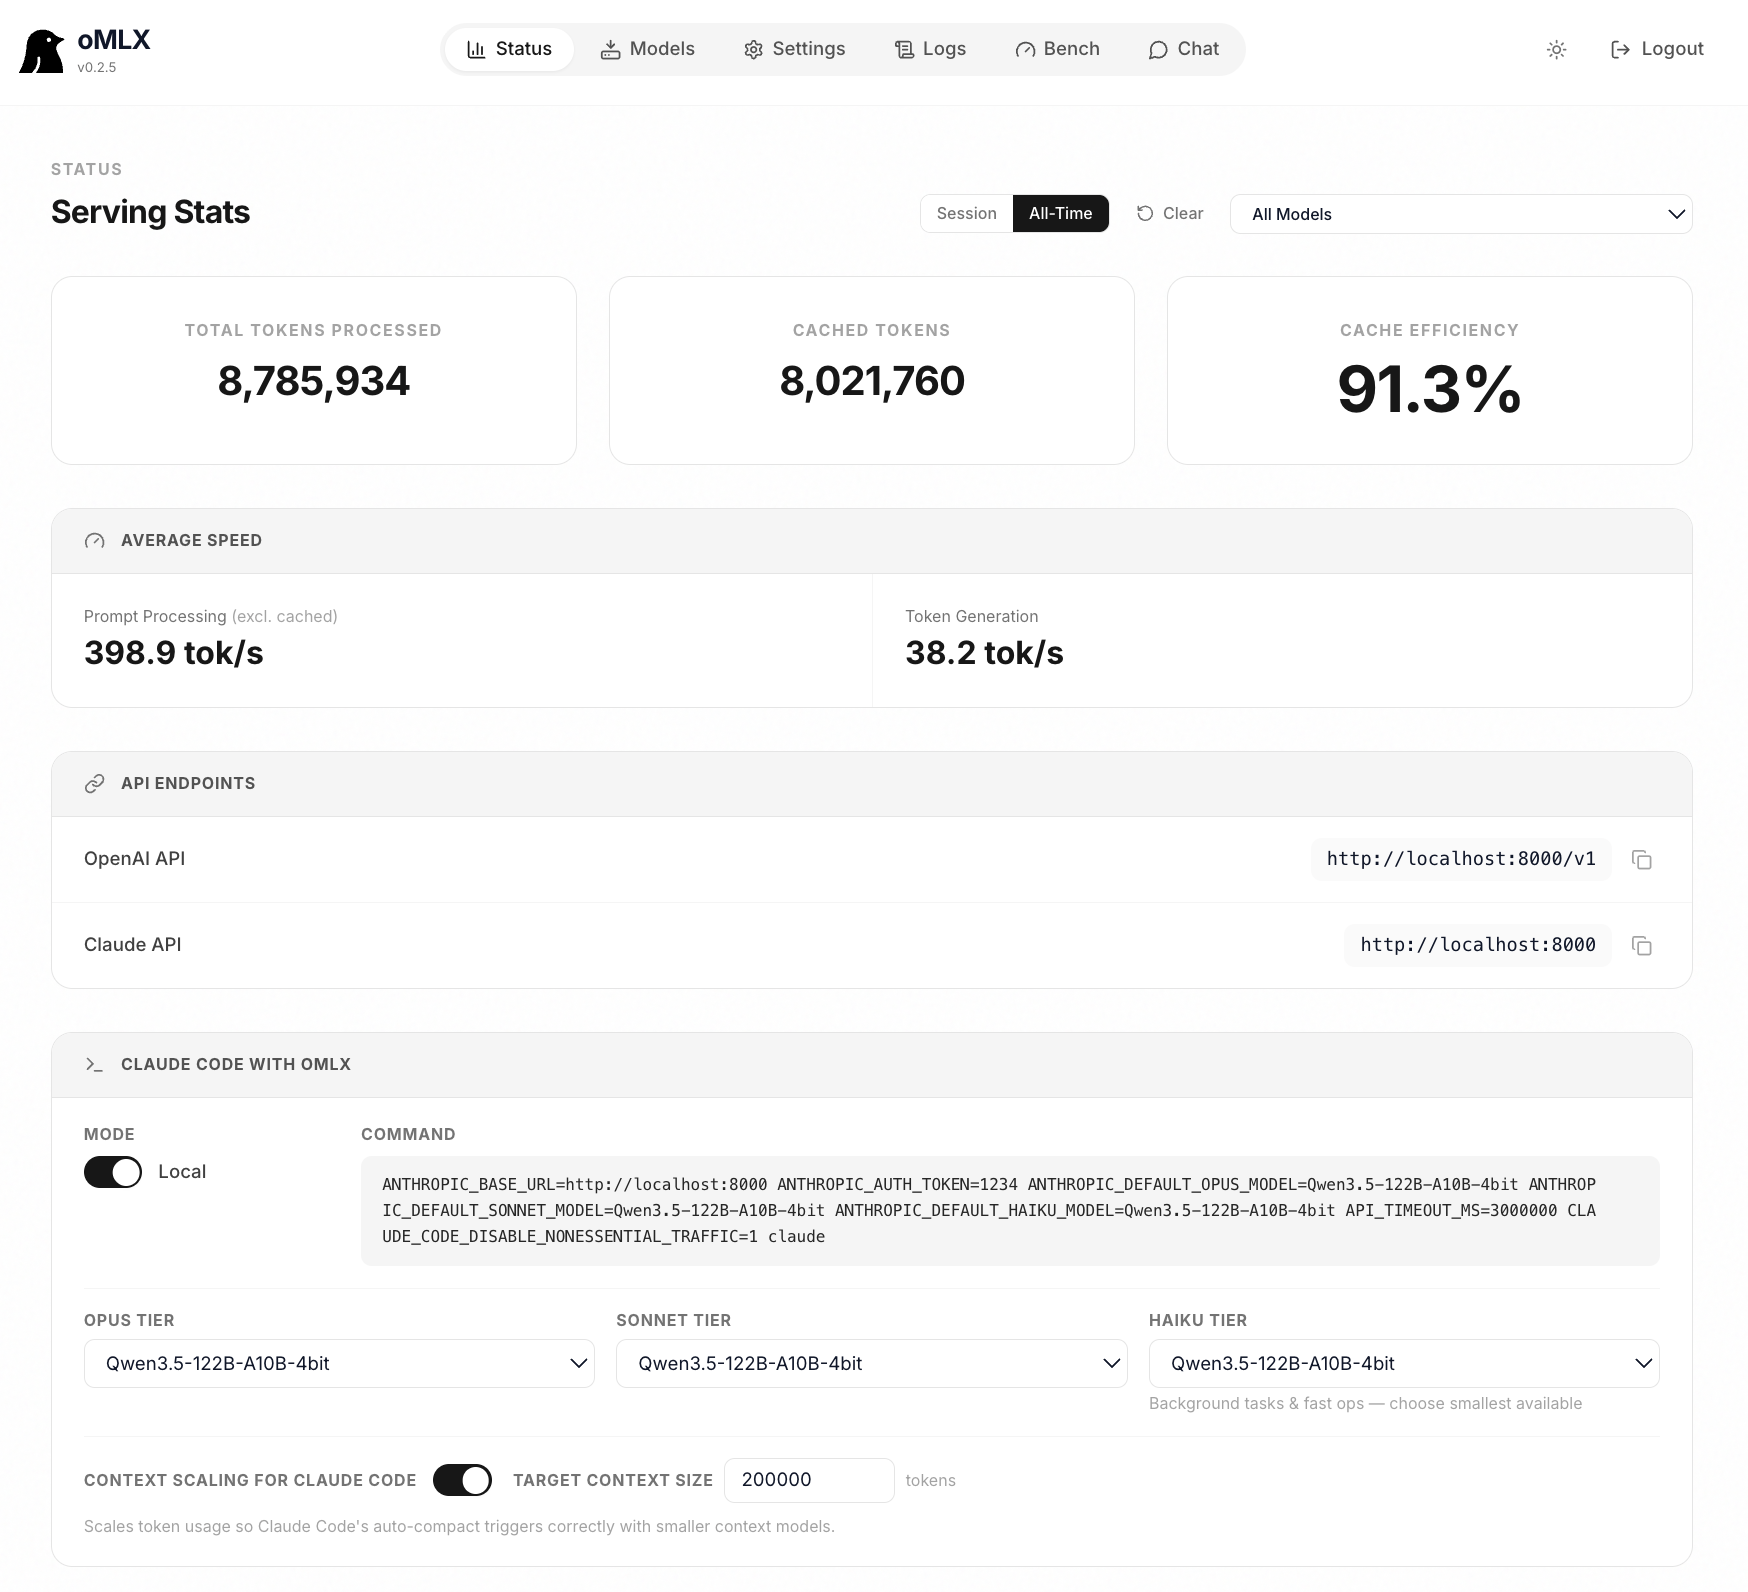
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
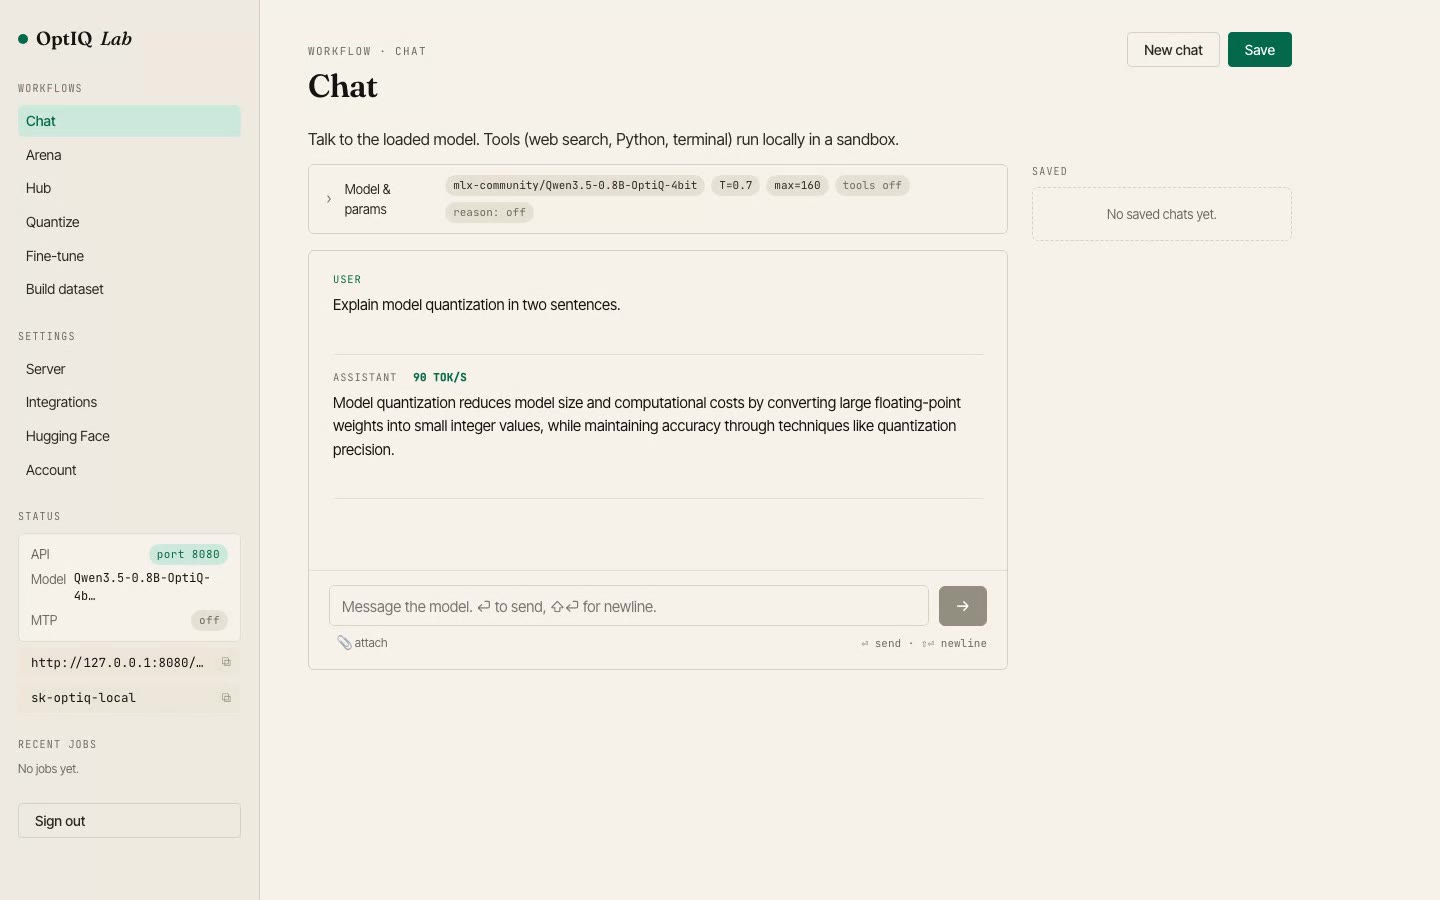
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
Minions: A Dynamic and Distributed Virtual GPU Cloud Built on Idle Apple Silicon Devices
The increasing demand for GPU-accelerated machine learning inference has exposed limitations in centralized GPU infrastructures, including…
ARahim3/mlx-tune
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.
ARahim3/mlx-tune
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.
Your Laptop Isn’t Ready for LLMs. That’s About to Change
The quest to run large AI models locally on an individual's machine are driving the biggest change in laptop architecture in decades.
