

* Still working on metrics for comparative analysis and definition. ** Zero dependencies. *** Strict compliance could result in slower processing when running comparative benchmarking.
Speed Comparison - Programming Languages
Benchmarks run on GitHub Actions. Results may vary based on runner hardware.
When benchmarks go bad - what I learned from measuring performance wrong - Holly Cummins
The world of performance analysis is littered with flawed claims, cognitive biases, dangerous intuitions, and beguiling fallacies. Sadly…
Epoch Capabilities Index
The Epoch Capabilities Index combines many benchmarks into a single capability scale for comparing models over time.
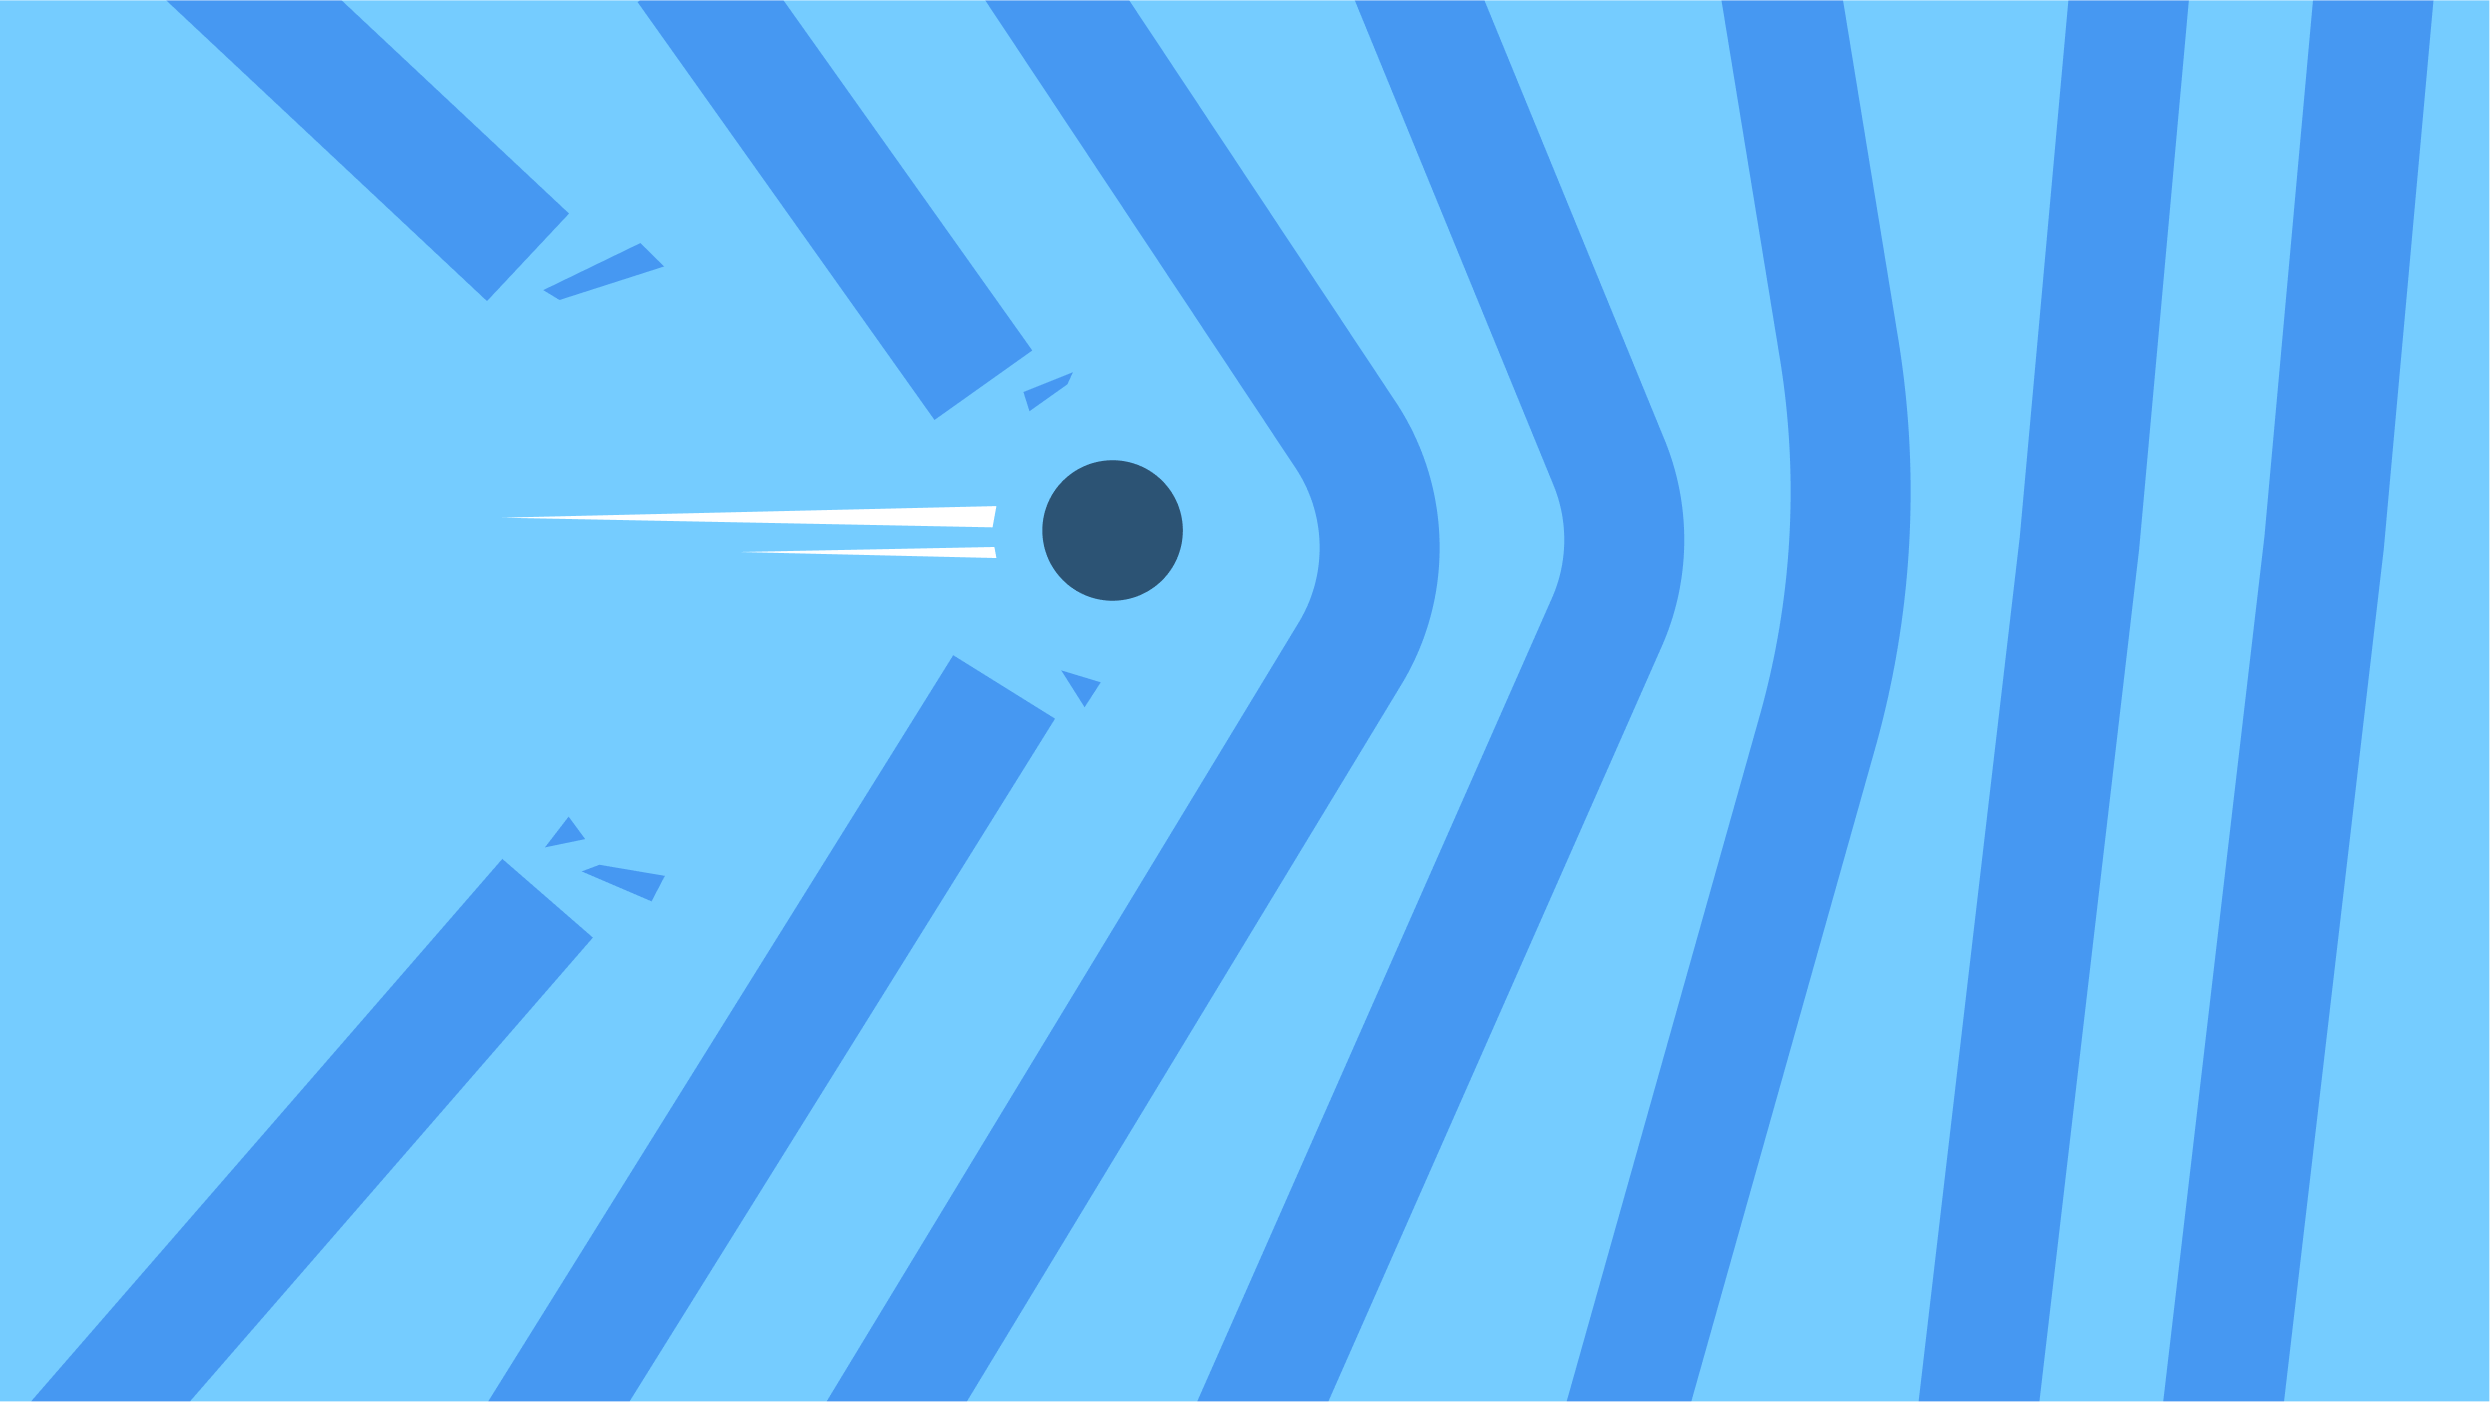
Performance Explorer — oMLX
Compare model performance across context lengths with community benchmark data.
BetterBench: Assessing AI Benchmarks, Uncovering Issues, and Establishing Best Practices
AI models are increasingly prevalent in high-stakes environments, necessitating thorough assessment of their capabilities and risks. Benchmarks are popular for measuring these attributes and for comparing model performance, tracking progress, and identifying weaknesses in foundation and non-foundation models. They can inform model selection for downstream tasks and influence policy initiatives. However, not all benchmarks are the same: their quality depends on their design and usability. In this paper, we develop an assessment framework considering 46 best practices across an AI benchmark's lifecycle and evaluate 24 AI benchmarks against it. We find that there exist large quality differences and that commonly used benchmarks suffer from significant issues. We further find that most benchmarks do not report statistical significance of their results nor allow for their results to be easily replicated. To support benchmark developers in aligning with best practices, we provide a checklist for minimum quality assurance based on our assessment. We also develop a living repository of benchmark assessments to support benchmark comparability, accessible at betterbench.stanford.edu.

Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
Wolfram LLM Benchmarking Project
Results from Wolfram's ongoing tracking of LLM performance. The benchmark is based on a Wolfram Language code generation task.
Model Performance Evaluation to SubQ 1.1 Small Preview Performance Evaluation | Appen
A third-party benchmark assessment of Subquadratic's preview models, conducted by Appen across long-context retrieval, code generation, business-workflow automation, and graduate-level reasoning benchmarks.
When the Scoreboard Becomes the Game, It’s Time to Recalibrate Research Metrics - The Scholarly Kitchen
Today's guest post discusses research metrics and their relationship to research integrity, inclusivity, and long-term impact.
Unified Versus Split Diff
Which is better for code reviews, a unified diff or a split diff?
SemiAnalysisAI/InferenceX
Open Source Continuous Inference Benchmark Research Platform — Kimi K3 2.8T, MiniMax M3, DeepSeekv4, GLM5 - GB200 NVL72 vs MI355X vs B200 vs GB300 NVL72 & soon™ TPUv6e/v7/Trainium2/3 | 开源持续推理基准研究平台 — Kimi K2.7-Code、MiniMax M3、DeepSeekv4、GLM5 - GB200 NVL72 vs MI355X vs B200 vs GB300 NVL72,即将推出™ TPUv6e/v7/Trainium2/3
