In basic research, such as pure mathematics, one might naively expect that the natural question to ask with regards to a given problem X in a field is "What is the answer to X?". But in many cases the more valuable question is "What can be learned from studying X?" The answer to X itself can of course be one of the things learned in this process of study; but one can learn far more useful information besides, such as * What are the main difficulties to overcome to resolve X? * What new techniques can one discover in order to solve X? * Why are existing techniques insufficient to solve the problem by itself? * How does X relate to results in prior literature? * Can one uncover new connections between X and other topics Y, Z, ...? * What are some natural related or followup questions X', X'', ... to study? Nevertheless, until recently the two questions were closely aligned, to the point where it was not really necessary to distinguish the two: the only practical route to solving a difficult problem was to first address many of the subquestions listed above. (1/3)
Terence Tao (@tao@mathstodon.xyz)
I wrote recently about how the collection of good, fruitful open problems is now being mined in a non-renewable fashion, leading to the potential scenario of these problems becoming scarce. This may seem unintuitive at first, since the set of possible problems one could ask is infinite. Perhaps the following analogy can help: a country or region can suffer a critical shortage of drinking water while simultaneously being surrounded by a massive ocean. One can easily generate any number of open problems in mathematics at will, such as working out the 10^10^10th digit of pi. But the vast majority of such problems are not worth focusing attention on: they show no particular propensity to reveal any further insights or connections to other questions, or may either be too easy or too impossible relative to known techniques to learn anything from the exercise. (1/4)
Social learning preserves both useful and useless theories by canalizing learners’ exploration
In many domains, learning from others is crucial for leveraging cumulative cultural knowledge, which encapsulates the efforts of successive generations of innovators. However, anecdotal and experimental evidence suggests that reliance on social information can reduce the exploration of the problem space. Here, we experimentally investigate the extent to which cultural transmission fosters the persistence of arbitrary solutions in a context where participants are incentivized to improve a physical system across multiple trials. Participants were exposed to various theories about the system, ranging from accurate to misleading. Our findings indicate that even under conditions conducive to exploration, the transmission of cultural knowledge canalizes learners’ focus, limiting their consideration of alternative solutions. This effect was observed in both the theories produced and the solutions attempted by participants, irrespective of the accuracy of the provided theories. These results challenge the notion that arbitrary solutions persist only when they are efficient or intuitive and underscore the significant role of cultural transmission in shaping human knowledge and technologies.
The last IMO problem AI could not solve
Terence Tao (@tao@mathstodon.xyz)
In traditional mathematics (or "Math 1.0"), a breakthrough proof of a long-standing open conjecture generates a large amount of subsequent activity and excitement in the field. The authors of the proof are invited to give many talks, and meet with other experts in the area. Workshops are set up to discuss the proof, as well as other recent developments. As a result, new connections and collaborations are formed, followup problems are shared, and other mathematicians (both junior and senior) are attracted to the field (including in some cases the authors themselves, if they initially came from a different subject). As a result of all this activity, the proofs naturally become digested, streamlined, placed in context with other results in the field, and ultimately become part of the textbooks and lecture notes for the next generation of mathematicians in the field. (1/4)
Illusions of Understanding in the Sciences
Scientists seek to understand the causes of observed phenomena. Beliefs that they have succeeded are based on understanding that is rarely or possibly never complete, and varies in depth and quality. Most often scientists believe they understand more than they do, making their belief an illusion. This illusion then persists in explanations scientists provide in print, in talks, or in discussions. The illusion that a scientist has a valid and complete explanation tends to be magnified when the data are well described by mathematical and computer simulation models due to the precision of such models and their ability to predict well; prediction does not imply causality, but gives the illusion that it does. The first part of this essay supports the case for the universality of partial and incomplete levels of understanding by showing the difficulty of reaching a deep level of understanding for even a simple analysis and model that most scientists use and believe they understand: linear regression. The second part highlights some implications of the existence of many levels of understanding and explanation, and their use by scientists for design, testing, analysis, and theory development. It discusses the way that deduction and induction depend on the levels of understanding and the implications of the illusion that a scientist’s understanding is deep. It makes a case that the many incomplete levels of understanding affect, often unwittingly, the ways scientists design experiments, test theories, comprehend, communicate, and teach.

Why Some Students Learn Faster
A hypothesis about teaching and learning
Why Some Students Learn Faster
A hypothesis about teaching and learning
the void — LessWrong
Comment by nostalgebraist - Thanks for the reply! I'll check out the project description you linked when I get a chance. [...] Yeah, I had mentally flagged this as a potentially frustrating aspect of the post – and yes, I did worry a little bit about the thing you mention in your last sentence, that I'm inevitably "reifying" the thing I describe a bit more just by describing it. FWIW, I think of this post as purely about "identifying and understanding the problem" as opposed to "proposing solutions." Which is frustrating, yes, but the former is a helpful and often necessary step toward the latter. And although the post ends on a doom-y note, I meant there to be an implicit sense of optimism underneath that[1] – like, "behold, a neglected + important cause area that for all we know could be very tractable! It's under-studied, it could even be easy! What is true is already so; the worrying signs we see even in today's LLMs were already there, you already knew about them – but they might be more amenable to solution than you had ever appreciated! Go forth, study these problems with fresh eyes, and fix them once and for all!" I might write a full post on potential solutions sometime. For now, here's the gist of (incomplete, work-in-process) thoughts. ---------------------------------------- In a recent post, I wrote the following (while talking about writing a Claude 4 Opus prompt that specified a counterfactual but realistic scenario): [...] And I feel that the right way to engage with persistent LLM personas is basically just this, except generalized to the fullest possible extent. "Imagine the being you want to create, and the kind of relationship you want to have (and want others to have) with that being. "And then shape all model-visible 'context' (prompts, but also the way training works, the verbal framing we use for the LLM-persona-creation process, etc.) for consistency with that intent – up to, and including, authentically acting out that 'relationship you want to have' w

Learning from the Master: Socrates’ Examined Life
CHAD BOCHAN How to have conversations that lead to actual answers.

The Buffett Formula: Going to Bed Smarter Than When You Woke Up
Learn how Warren Buffett and Charlie Munger turn curiosity into insight. Discover how interest-driven learning builds understanding and reveals hidden opportunities.
The Law of Conservation of Information: Search Processes Only Redistribute Existing Information
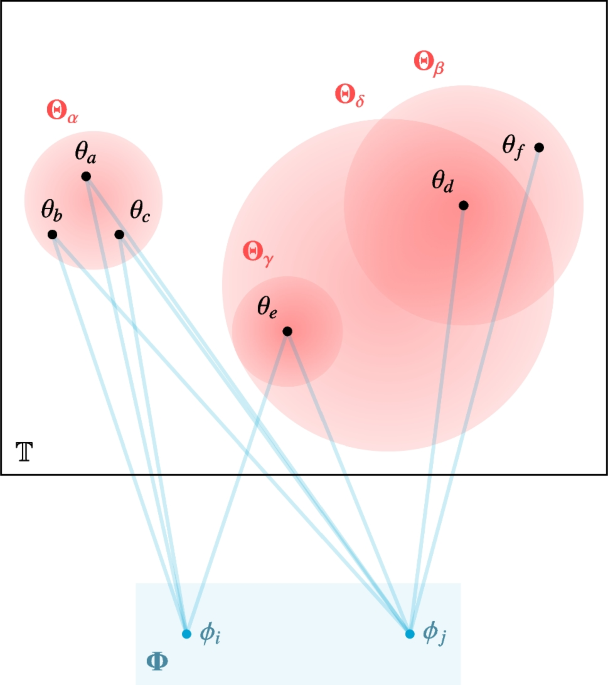
Conservation of information sparked scientific interest once a recurring pattern was noticed in the evolutionary computing literature. In grappling with the creation of information through evolutionary algorithms, this literature consistently revealed that the information outputted by such algorithms always needed first to be programmed into them. Thus, the primary goal of this literature—to uncover how information could be created from scratch or de novo —was shown to be misconceived: the information was not created but instead shuffled around or smuggled in, implying that it already existed in some form or other. Information output in these situations therefore always presupposed a counterbalancing input of prior information. Once this pattern was seen, the next logical step was to quantify the amount of information inputted and outputted, demonstrating a consistent mathematical relation between the two. This led to the proof of a number of theorems about search. In these theorems, a baseline search with probability p of success gave way to an improved search with probability q of success. Typically p would be very small and close to zero, implying a practically impossible search (like searching for a needle in a haystack). By contrast, q would be much larger and close to one, implying an eminently doable search. The punchline of these theorems was that, as the improved search became itself the subject of a search (a search for a search , or S4S), the probability of finding it could not exceed p / q , rendering success of the improved search no more probable than success of the original baseline search, in effect filling one hole by digging another. Such conservation-of-information theorems, as they came to be called, were search-space specific, adapted to different kinds of search across a range of search spaces. There was a measure-theoretic theorem in which probability measures guided search. There were also function-theoretic and fitness-theoretic theorems where mappings into the search space as well as fitness functions on the search space respectively guided search. The key insight of this paper is that all these conservation-of-information theorems are special cases of a simple probabilistic relation based on elementary probability theory. This paper identifies the underlying rationale that makes all the previous conservation-of-information theorems work. In so doing, it provides a straightforward proof and general formulation of what may rightly be called the Law of Conservation of Information.
You don't have to be smart if you can think clearly
When you’re on fire, problems are transparent: they’re solved simply by the act of looking at them. Even complicated layers of multiple problems can simply be glanced through like stacked panes of glass. But nobody can work that way all the time.
Learning How to Learn (And 20+ Studies) – Max's Two Cents
I have been interested in cognitive science and effective learning methods for years. I’ve read multiple books and articles and put many ideas to test. In this post, I aim to synthesize my notes and provide references to scientific studies.
What Makes a Good Theory, and How Do We Make a Theory Good?
I present an ontology of criteria for evaluating theory to answer the titular question from the perspective of a scientist practitioner. Set inside a formal account of our adjudication over theories, a metatheoretical calculus, this ontology comprises the following: (a) metaphysical commitment, the need to highlight what parts of theory are not under investigation, but are assumed, asserted, or essential; (b) discursive survival, the ability to be understood by interested non-bad actors, to withstand scrutiny within the intended (sub)field(s), and to negotiate the dialectical landscape thereof; (c) empirical interface, the potential to explicate the relationship between theory and observation, i.e., how observations relate to, and affect, theory and vice versa; (d) minimising harm, the reckoning with how theory is forged in a fire of historical, if not ongoing, abuses—from past crimes against humanity, to current exploitation, turbocharged or hyped by machine learning, to historical and present internal academic marginalisation. This work hopes to serve as a possible beginning for scientists who want to examine the properties and characteristics of theories, to propose additional virtues and vices, and to engage in further dialogue. Finally, I appeal to practitioners to iterate frequently over such criteria, by building and sharing the metatheoretical calculi used to adjudicate over theories.
How To Think Real Good | Meta-rationality
Practical epistemology: heuristics for how to think about difficult things, particularly using formal methods.
Exploring the interplay between AI and human logic in mathematical problem-solving
This paper investigates the dynamic interplay between Artificial Intelligence (AI) and human logic in the domain of mathematical problem-solving. By critically examining a series of case studies, we compare the efficacy of AI-generated solutions, particularly those offered by ChatGPT, against traditional human problem-solving methods. The study employs various mathematical challenges, ranging from abstract logical puzzles to applied numerical problems, to evaluate AI's problem-solving approach and alignment with human cognitive processes. Our analysis highlights instances where AI's computational strategies complement or diverge from human reasoning, shedding light on AI's potential and limitations in deciphering mathematical problems. Furthermore, we explore the implications of integrating AI tools in educational contexts, specifically their role in enhancing students' mathematical problem-solving skills. The paper aims to contribute to the ongoing discourse on the optimal utilization of AI in education, proposing a balanced approach that leverages AI's computational power while fostering the depth and creativity of human logic. Through this comparative study, we advocate for a collaborative model where AI and human reasoning merge to enrich the educational landscape, particularly in the teaching and learning of mathematics.