

Many "errors" in search-assisted LLMs are not errors at all, but the result of an investigation aborted too soon. Here's how to up your LLM-based verification game by going to round two.
Your LLM Doesn't Write Correct Code. It Writes Plausible Code.
One of the simplest tests you can run on a database:
LLM APIs are a Synchronization Problem
Maybe the LLM message APIs should be rethought as a synchronization problem.
Solving a Million-Step LLM Task with Zero Errors
LLMs have achieved remarkable breakthroughs in reasoning, insights, and tool use, but chaining these abilities into extended processes at the scale of those routinely executed by humans,...

LLMs believe false statements even after explicit warnings that they're false
Fine-tuning tests show "bias... toward confidently representing the claims as true."
Your Laptop Isn’t Ready for LLMs. That’s About to Change
The quest to run large AI models locally on an individual's machine are driving the biggest change in laptop architecture in decades.

LLMs break the internet. Signing everything fixes it.
The dead internet theory wasn't wrong, just early. Here's what to do next.
If an AI agent can’t figure out how your API works, neither can your users
Discover how LLM‑powered agents act as tireless API testers—exposing friction in docs, errors, and design—and learn six essential strategies (consistency, comprehensive docs, rich errors, example‑driven tutorials, simplicity, and feedback loops) to elevate your API’s developer experience for both humans and machines alike.

One year as an AI Engineer: The 5 biggest misconceptions about LLM reliability I've encountered
535 votes, 59 comments. After spending a year building evaluation frameworks and debugging production LLM systems, I've noticed the same…
I accidentally turned LLM memory into program analysis :: pwning.systems
Why I stopped trying to give LLM agents a better memory and instead built Lemmalog, a Datalog engine that maintains an agent's knowledge as analysis state, with provenance, retractions and incremental evaluation, plus what happened when I benchmarked it on LongMemEval and LoCoMo.
The Ultimate Guide to Fine-Tuning LLMs from Basics to Breakthroughs: An Exhaustive Review of Technologies, Research, Best Practices, Applied Research Challenges and Opportunities (Version 1.0)
There's Something Fundamentally Wrong With LLMs
LLMs aren't trained on the "vast majority of speech," experts warn, a major blind spot that could have sweeping consequences.
crawshaw - 2026-02-08
I wrote up my experiences programming with LLMs a bit over a year ago, and updated it for the world of agents eight months ago. A lot has changed since then, so here is an update.
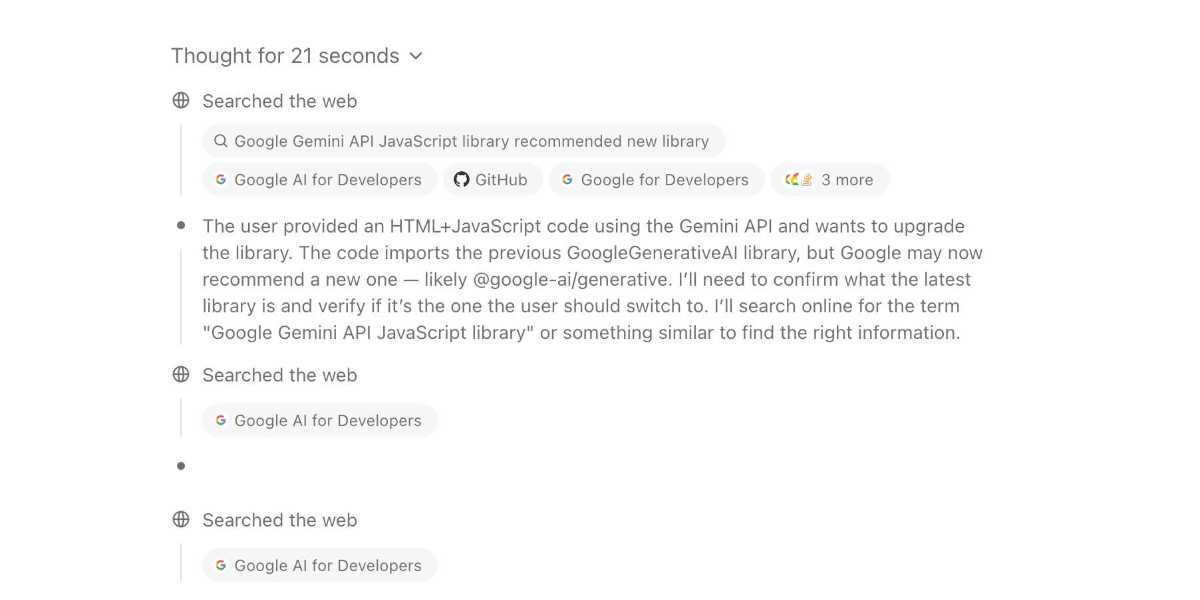
AI assisted search-based research actually works now
For the past two and a half years the feature I’ve most wanted from LLMs is the ability to take on search-based research tasks on my behalf. We saw the …
Hallucinations in code are the least dangerous form of LLM mistakes
A surprisingly common complaint I see from developers who have tried using LLMs for code is that they encountered a hallucination—usually the LLM inventing a method or even a full …
I haven't, but I don't know that it's that kind of model. It's really different than an LLM, since if you want an answer from it you can only ask it multiple choice, true or false ( with confidence ), or "tell me the score of X" questions. So there's no generating proof code or anything directly.

