

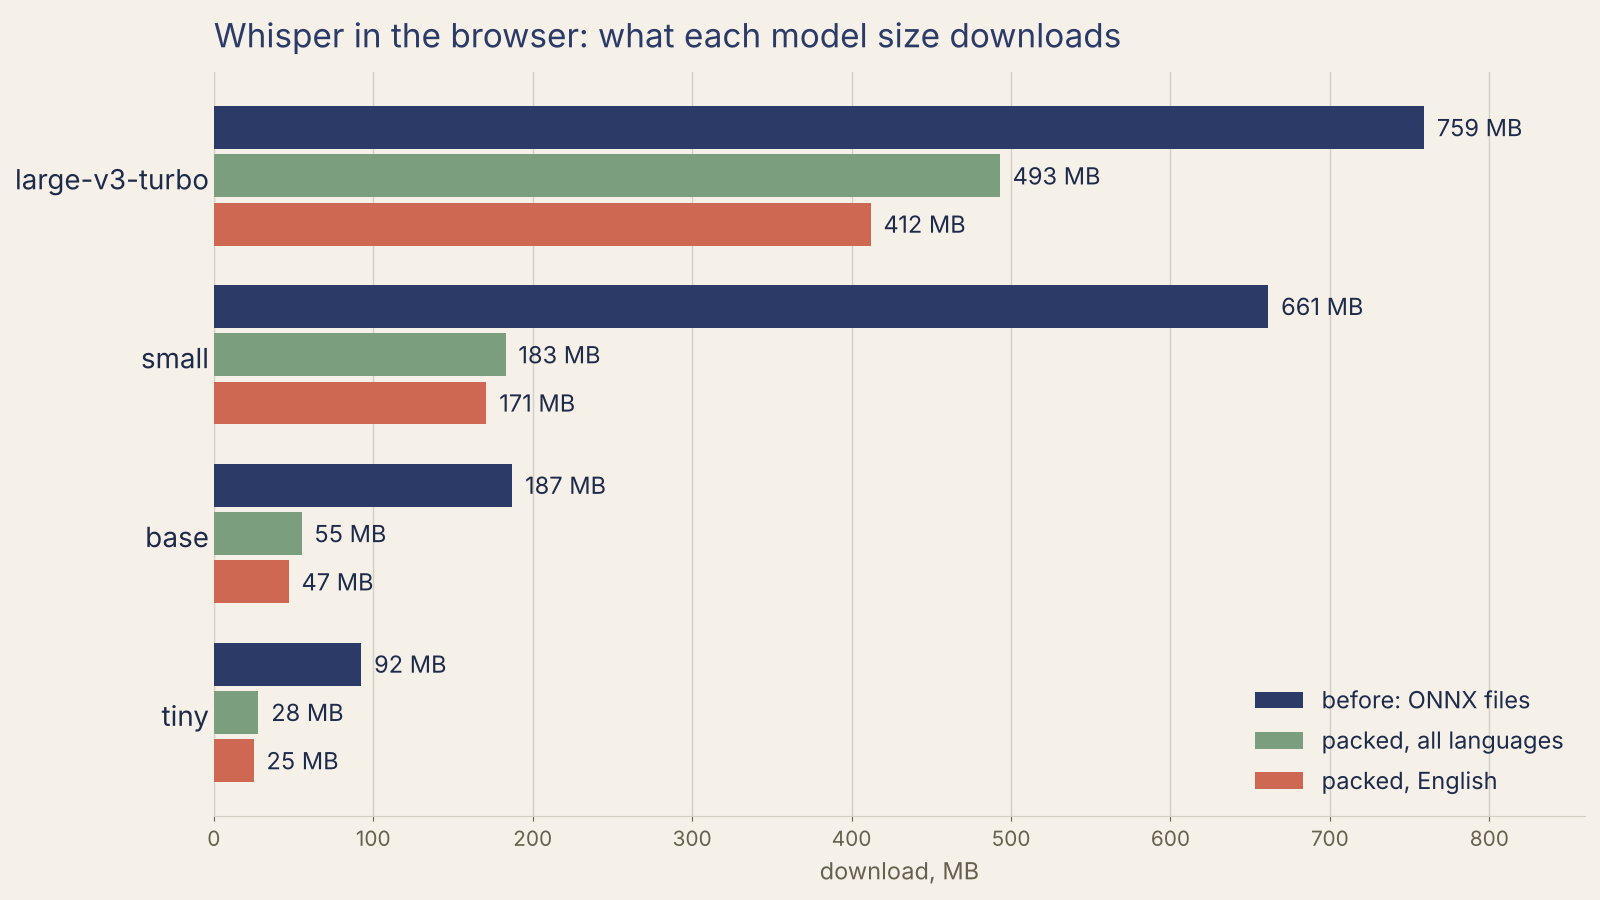
The speech-to-text model in Oskar's file converter now loads from quantized weight packs on hand-written WebGPU code: 412 MB instead of 759 MB for the largest model, a quarter of the old size for the small ones, with English accuracy unchanged and about one and a half times the speed.
Underdog Woof
Our text-to-speech models: one voice in 31.7 MB, or two voices in 40.6 MB with fewer word errors than Fish Audio Drama 3 at over 1,000 times smaller. They read phone numbers, dates, prices and codes the way people say them.

kwindla on Twitter / X
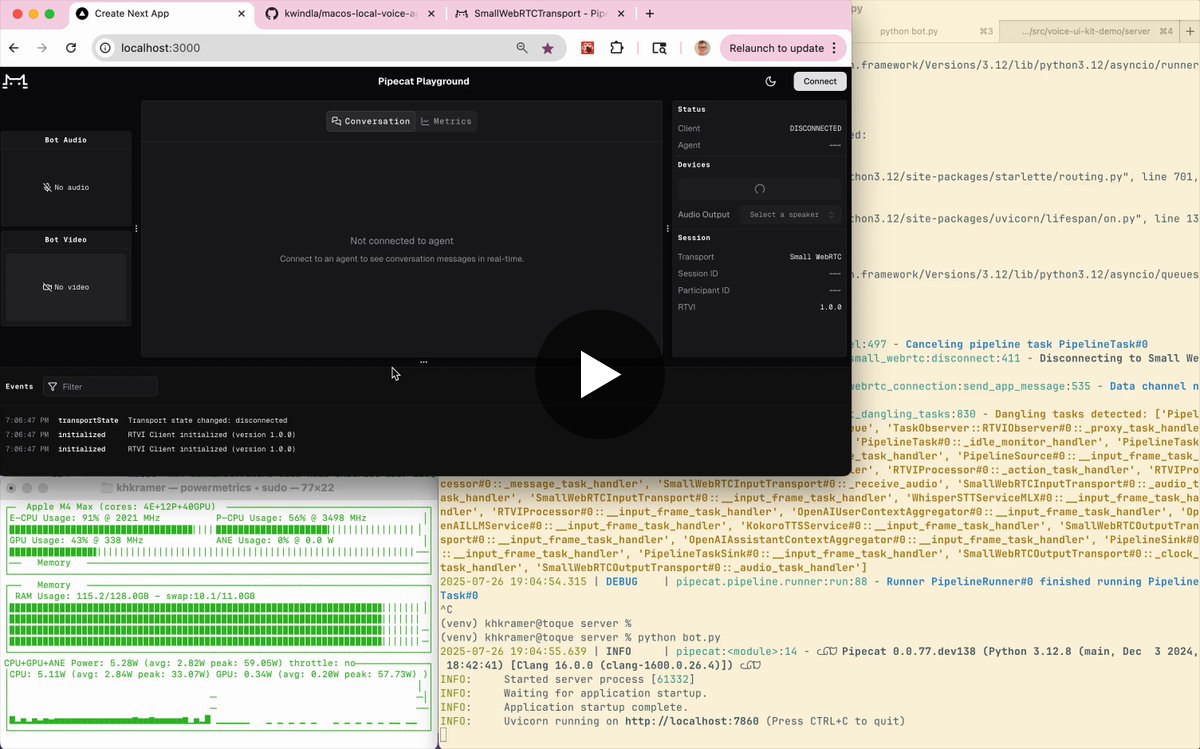
Local voice AI with a 235 billion parameter LLM. ✅- smart-turn v2- MLX Whisper (large-v3-turbo-q4)- Qwen3-235B-A22B-Instruct-2507-3bit-DWQ- KokoroAll models running local on an M4 mac. Max RAM usage ~110GB.Voice-to-voice latency is ~950ms. There are a couple of… pic.twitter.com/iYNQlb9JkI— kwindla (@kwindla) July 27, 2025
innovatorved/whisper.api
This project provides an API with user level access support to transcribe speech to text using a finetuned and processed Whisper ASR model.
ICML WhisperKit: On-device Real-time ASR with Billion-Scale Transformers
Real-time Automatic Speech Recognition (ASR) is a fundamental building block for many commercial applications of ML, including live captioning, dictation, meeting transcriptions, and medical scribes. Accuracy and latency are the most important factors when companies select a system to deploy. We present WhisperKit, an optimized on-device inference system for real-time ASR that significantly outperforms leading cloud-based systems. We benchmark against server-side systems that deploy a diverse set of models, including a frontier model (OpenAI gpt-4o-transcribe), a proprietary model (Deepgram nova-3), and an open-source model (Fireworks large-v3-turbo).Our results show that WhisperKit matches the lowest latency at 0.46s while achieving the highest accuracy 2.2\% WER. The optimizations behind the WhisperKit system are described in detail in this paper.
Ink-Whisper is fast! @cartesia released a new STT model yesterday, and it's as fast as you'd expect. Streamed transcription finishes in <100ms—before you can say the next sentence. I used it to build a live teleprompter that follows along with what you're saying. Code in 🧵
Ink-Whisper is fast!@cartesia_ai released a new STT model yesterday, and it's as fast as you'd expect. Streamed transcription finishes in <100ms—before you can say the next sentence.I used it to build a live teleprompter that follows along with what you're saying. Code in 🧵 pic.twitter.com/LAszg9nBUz— Shayne (@shayneparlo) June 11, 2025

OpenAI.fm
An interactive demo for developers to try the latest text-to-speech model in the OpenAI API
ChatGPT and Whisper APIs debut, allowing devs to integrate them into apps
New ChatGPT API can generate text that's a tenth of the cost of previous models.

atomic.chat on Twitter / X
Google Turbo Quant running Locally in Atomic ChatMacBook Air M4 16 GBModel: QWEN3.5-9BContext window: 50000Summarising 20000 words in just seconds..You can do 3x larger context window, processing 3x faster than before! pic.twitter.com/FRYkXCGjQb— atomic.chat (@atomic_chat_hq) March 27, 2026
Introducing Whisper – an open source voice note taking app! Record voice notes and transcribe them into lists, blogs, & more with AI. 100% free & open source. https://t.co/UZWGkUDJ6d
Introducing Whisper – an open source voice note taking app!Record voice notes and transcribe them into lists, blogs, & more with AI.100% free & open source. pic.twitter.com/UZWGkUDJ6d— Hassan (@nutlope) July 22, 2025

On-Device LLM Throughput Calculator - a Hugging Face Space by FL33TW00D-HF
This tool estimates and visualizes the throughput of Large Language Models on devices with memory bandwidth constraints. Users input device and model configurations, and the tool generates a plot s...
WhisperSpeech/WhisperSpeech
An Open Source text-to-speech system built by inverting Whisper.
The 49MB Web Page
A look at modern news websites. How programmatic ad-tech, huge payloads and hostile architecture destroyed the reading experience.

OBS Text-to-Speech AI Real-Time Local FREE No Cloud [Tutorial]
Kokoro Text-to-Speech (WebGPU) - a Hugging Face Space by webml-community
High-quality speech synthesis powered by Kokoro TTS
Introducing **transcribe.cpp** 🎙️ A new open-source C/C++ speech-to-text inference library for fast, local transcription. ✅ Multiple GGUF STT models ✅ GPU acceleration (Metal, Vulkan & CUDA) ✅ Portable across platforms Built through @mozilla.ai's BiR program. Blog: blog.mozilla.ai/announcing-transcribe-cpp/

Announcing transcribe.cpp
blog.mozilla.ai
