NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B
Open Source AI Inference Benchmark | InferenceX
Compare AI inference performance across GPUs and frameworks. Real benchmarks on NVIDIA GB200, B200, AMD MI355X, and more. Free, open-source, continuously updated.
Open-Source Agentic Inference Benchmark | InferenceX
Compare AgentX, InferenceX's long-context, multi-turn coding scenario, with fixed-sequence AI inference across chips and frameworks. Public NVIDIA and AMD runs update when configurations change.
XiongjieDai/GPU-Benchmarks-on-LLM-Inference
Multiple NVIDIA GPUs or Apple Silicon for Large Language Model Inference?
NVIDIA Shatters MoE AI Performance Records With a Massive 10x Leap on GB200 'Blackwell' NVL72 Servers, Fueled by Co-Design Breakthroughs
Scaling performance on MoE AI models is one of the industry constraints, but it appears that NVIDIA has managed to make a breakthrough.

SemiAnalysisAI/InferenceX
Open Source Continuous Inference Benchmark Research Platform — Kimi K3 2.8T, MiniMax M3, DeepSeekv4, GLM5 - GB200 NVL72 vs MI355X vs B200 vs GB300 NVL72 & soon™ TPUv6e/v7/Trainium2/3 | 开源持续推理基准研究平台 — Kimi K2.7-Code、MiniMax M3、DeepSeekv4、GLM5 - GB200 NVL72 vs MI355X vs B200 vs GB300 NVL72,即将推出™ TPUv6e/v7/Trainium2/3
TheStage AI – Faster, Cheaper AI Inference
Accelerate models on NVIDIA & edge. Full guides for setup, optimization & deploy. ANNA, QLIP, Elastic Models, CLI & API. Built for AI teams & devs.

Building with Open Models
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
Minions: A Dynamic and Distributed Virtual GPU Cloud Built on Idle Apple Silicon Devices
The increasing demand for GPU-accelerated machine learning inference has exposed limitations in centralized GPU infrastructures, including…

NVIDIA Rubin CPX Accelerates Inference Performance and Efficiency for 1M+ Token Context Workloads | NVIDIA Technical Blog
Inference has emerged as the new frontier of complexity in AI. Modern models are evolving into agentic systems capable of multi-step reasoning, persistent memory, and long-horizon context—enabling…

NVIDIA DGX Station for Windows Puts a Trillion-Parameter AI Supercomputer on Every Enterprise Desk
News Summary: NVIDIA announces DGX Station for Windows — the world’s most powerful deskside AI supercomputer for developing and running agents on Windows — built on the NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip, coming in Q4 this year. DGX Station brings frontier AI agents to Windows — enabling enterprise developers, researchers, engineers, designers and data scientists to build and deploy AI across the workflows and applications their business runs on. DGX Station will support NVIDIA OpenShell on Windows, built on new Windows security and containment primitives. TAIPEI, Taiwan, June 01, 2026 (GLOBE NEWSWIRE) - NVIDIA GTC Taipei - NVIDIA today announced NVIDIA DGX Station™ for Windows , the world’s most powerful deskside AI supercomputer designed to build, run and connect always-on AI agents to Windows applications and workflows, capable of running frontier AI models of up to 1 trillion parameters locally. Historically, heavy-duty enterprise AI workloads —
OpenAI’s Jalapeño chip is built for fast inference at scale, benchmarks show | TechCrunch
Tested on SemiAnalysis’ InferenceX benchmark, Jalapeño registered both more tokens per user and more throughput per kilowatt than the currently available state-of-the art.

ASUS Ascent GX10
Desktop AI supercomputer delivering up to 1 petaFLOP performance, powered by NVIDIA GB10 Grace Blackwell Superchip, supporting OpenClaw and Hermes Agent.
vik on Twitter / X
Photon, our inference engine, isn't fast just because of GPU kernels. A lot of the speedup comes from engine-level work: request scheduling, prefix caching, image processing, all tuned to keep the GPU saturated. https://t.co/3M7eFcFKo5— vik (@vikhyatk) May 2, 2026
Actual Computer › Case Study : GB300 and Nemotron 3.5 Super VL
Department-scale AI from one NVIDIA DGX Station: Nemotron 3.5 Super VL at 8,000+ tokens per second, shared by your whole team through api.actual.inc.
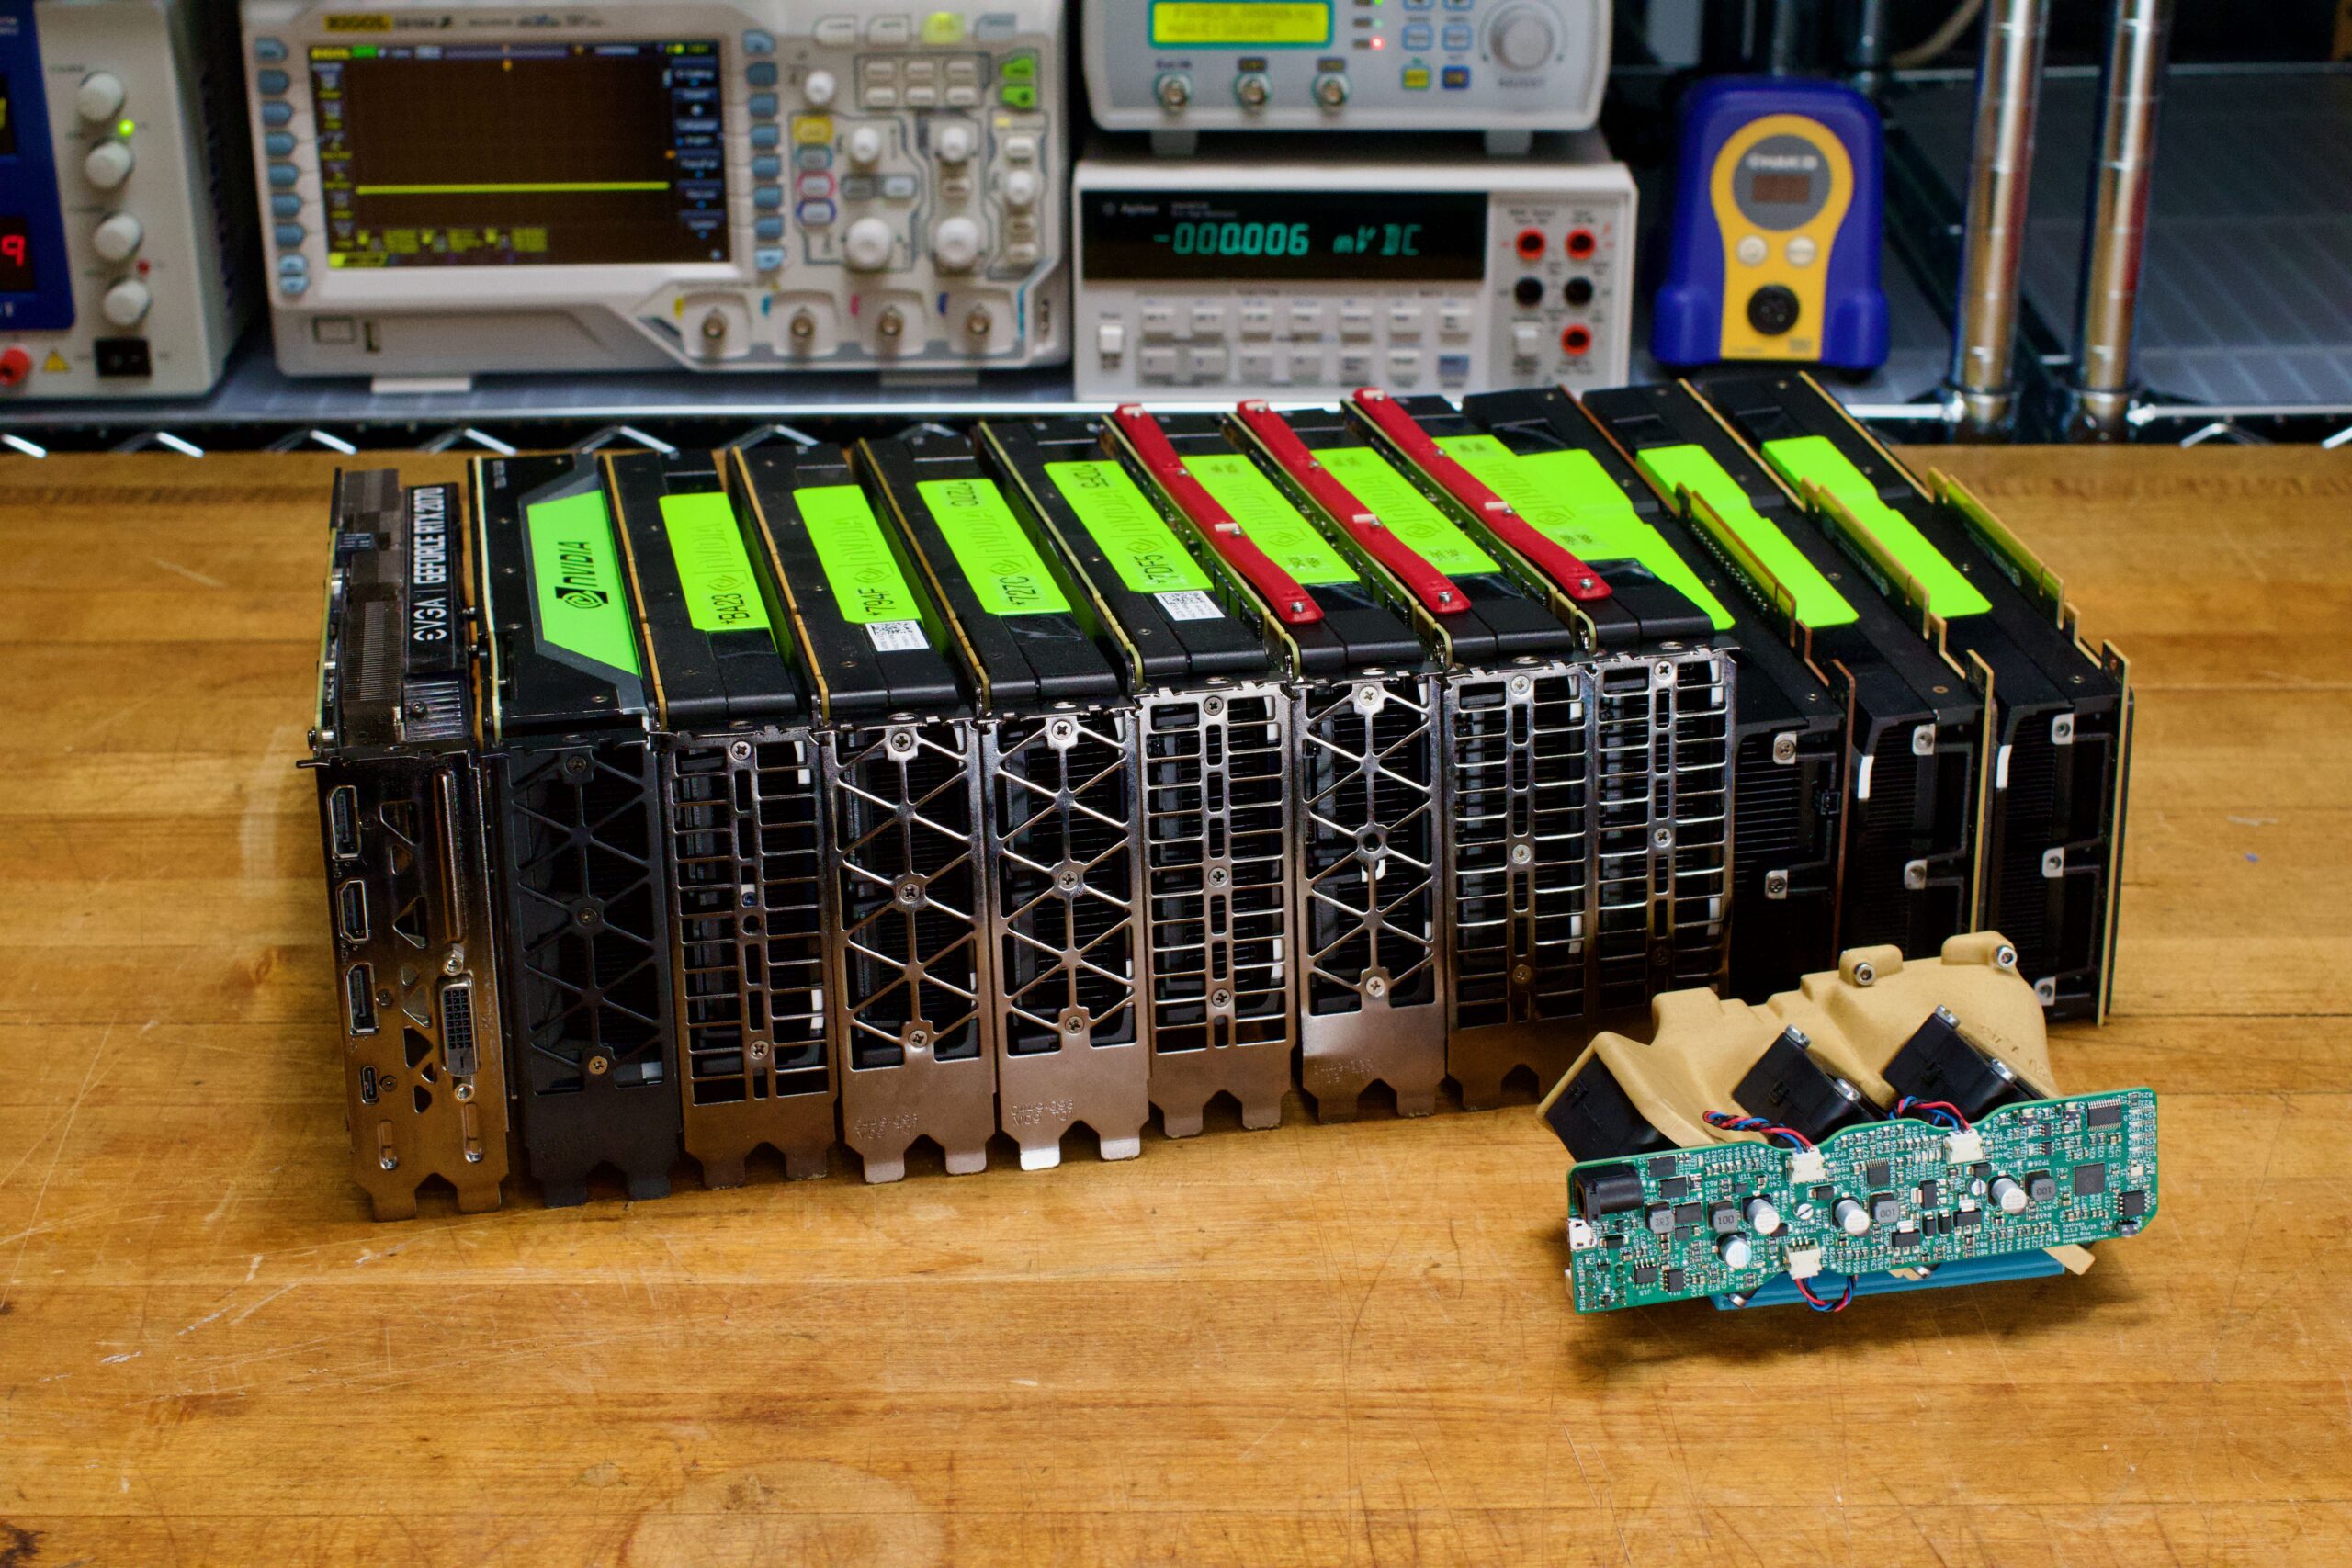
Benchmarking Tesla GPUs - esologic
Decommissioned enterprise tesla GPUs are widely available and extremely cheap. In this post, I benchmark tesla GPUs to see if they are useful