

Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
omlx/docs/experimental/dflash_mlx_integration.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
omlx/docs/oQ_Quantization.md at main · jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar - jundot/omlx
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
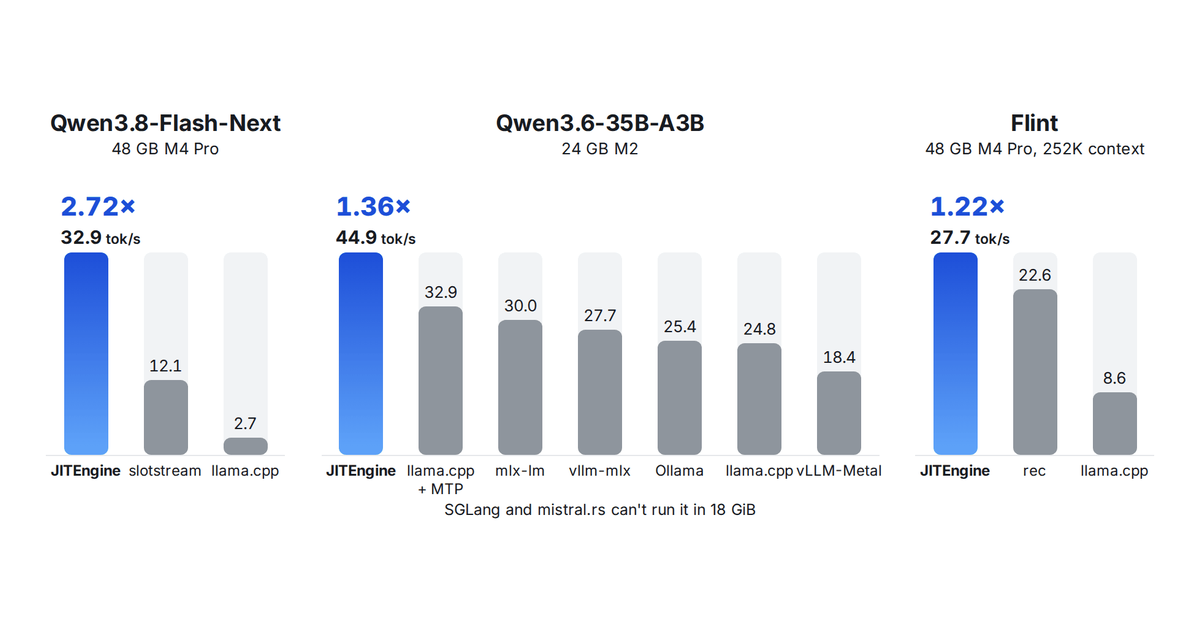
Your Mac Deserves Its Own LLM Engine
Six LLM serving engines for Apple silicon, built by coding agents with SkySynth. Up to 2.72x faster than the fastest other server we measured on the same Mac.
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

Combining NVIDIA DGX Spark + Apple Mac Studio for 4x Faster LLM Inference with EXO 1.0
Disaggregating Prefill and Decode: Faster First Tokens, Faster Streams
Combining NVIDIA DGX Spark + Apple Mac Studio for 4x Faster LLM Inference with EXO 1.0
Disaggregating Prefill and Decode: Faster First Tokens, Faster Streams
apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
JITEngine: LLM serving, synthesized for your Mac
LLM serving engines synthesized for your Mac, up to 2.7× as fast as the best other server we measured on the same Mac. Pick your Mac and get its commands, with the speeds we measured.
ModelScope on Twitter / X
🤯 400 Token/S on a MacBook? Yes, you read that right!Shaohong Chen just fine-tuned the Qwen3-0.6B LLM in under 2 minutes using Apple's MLX framework. This is how you turn your MacBook into a serious LLM development rig. A step-by-step guide and performance metrics inside! 🧵… pic.twitter.com/31Cmycy8Mh— ModelScope (@ModelScope2022) October 13, 2025
ARahim3/mlx-tune
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.
ARahim3/mlx-tune
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.