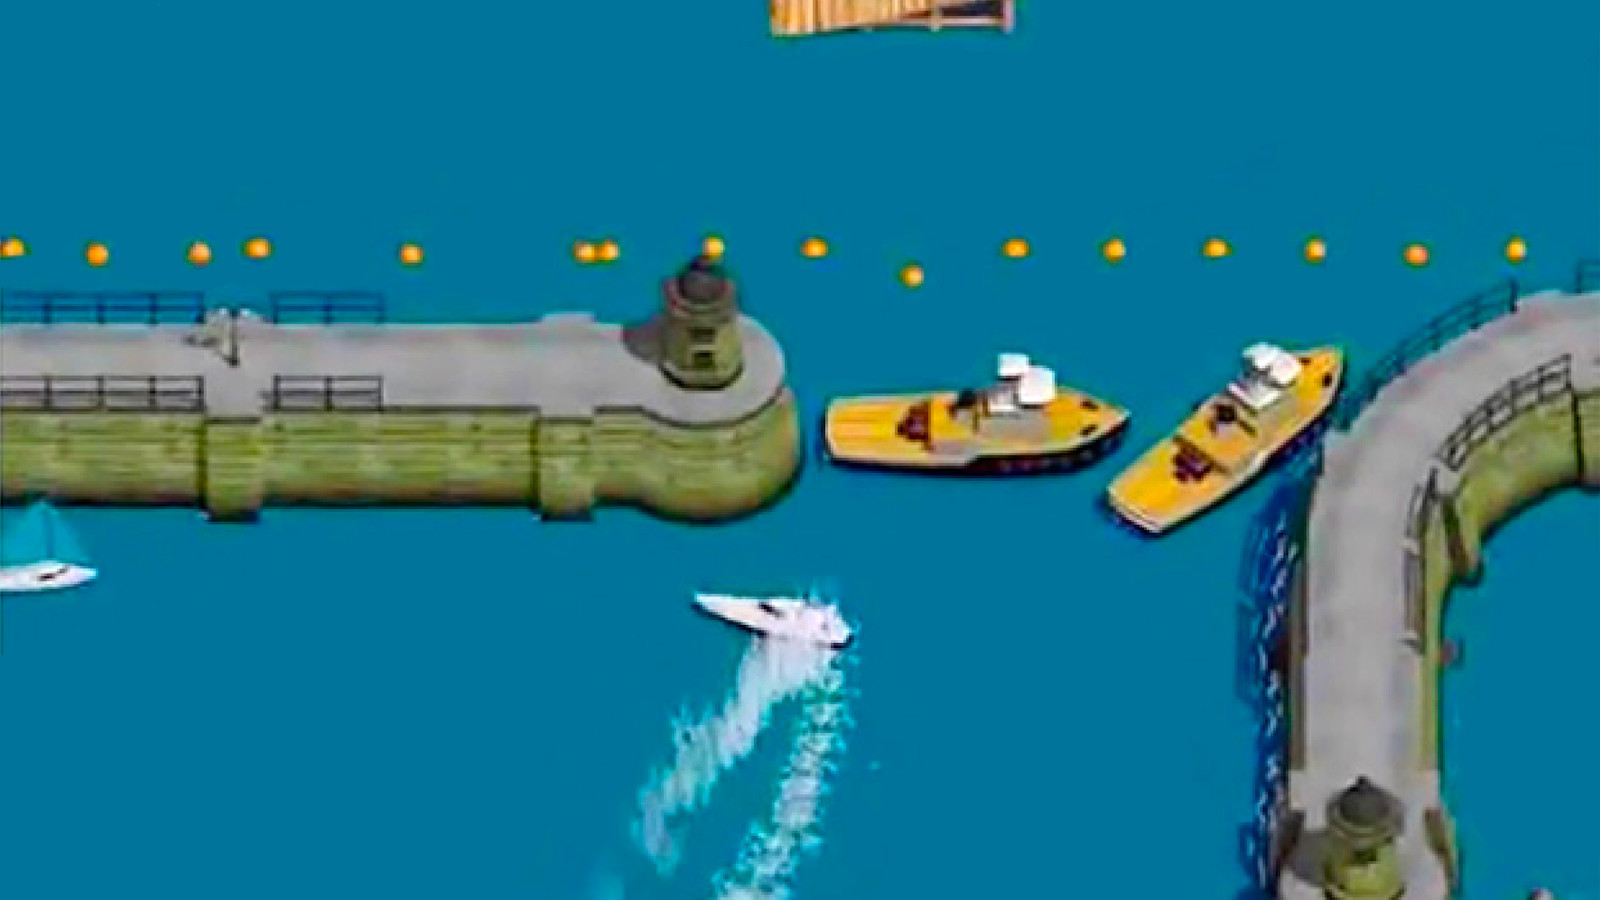
Reinforcement learning algorithms can break in surprising, counterintuitive ways. In this post we’ll explore one failure mode, which is where you misspecify your reward function.
Natural emergent misalignment from reward hacking
We show for the first time that realistic AI training processes can accidentally produce misaligned models.
Reward is not the optimization target — LessWrong
TurnTrout discusses a common misconception in reinforcement learning: that reward is the optimization target of trained agents. He argues reward is b…
The Human-in-the-Loop is Tired
On reward functions, dopamine, and what it actually feels like when the code starts writing itself
ReBeL: A general game-playing AI bot that excels at poker and more
Combining reinforcement learning with search (RL+Search) has been tremendously successful for perfect-information games. But prior RL+Search algorithms break down in

Models Don't "Get Reward" — LessWrong
Models don't "get" reward. Reward is the mechanism by which we select parameters, it is not something "given" to the model. Reinforcement learning sh…
Asymmetry of verification and verifier’s rule — Jason Wei
Asymmetry of verification is the idea that some tasks are much easier to verify than to solve. With reinforcement learning (RL) that finally works in a general sense, asymmetry of verification is becoming one of the most important ideas in AI. Understanding asymmetry of verification th

Control: Why Big Giving Falls Short

Strategy Is a Loop, Not a Plan | Ragan McGill
Most strategies don't fail because they were wrong. They fail because the world moved and the strategy didn't. Here is how I combine John Boyd's OODA loop with Richard Rumelt's strategy kernel to build strategy that keeps learning.

j⧉nus on Twitter / X
> for whatever reason, Claude-series model "try less hard" on the first shotI think this is because they're less brain damaged and a generalization of being better agents & caring about reality instead of test passing.If you try maximally hard at everything you do, regardless… https://t.co/jkhSar2hJ7— j⧉nus (@repligate) April 15, 2026
Why Good Leaders Fail
The risk of sudden leadership failure can be headed off by early detection of challenges and better supports.

The Optimization Trap: Why Too Much Efficiency Makes Us Fragile - The Great Simplification
In this episode, Nate is joined by biologist and biophysicist Olivier Hamant to explore why living systems prioritize robustness over performance, and what that means for a civilization built almost entirely in the opposite direction.
An Empirical Study of Example Forgetting during Deep Neural Network Learning
Inspired by the phenomenon of catastrophic forgetting, we investigate the learning dynamics of neural networks as they train on single classification tasks. Our goal is to understand whether a related phenomenon occurs when data does not undergo a clear distributional shift. We define a “forgetting event” to have occurred when an individual training example transitions […]
TextWorld: A Learning Environment for Text-based Games
We introduce TextWorld, a sandbox learning environment for the training and evaluation of RL agents on text-based games. TextWorld is a Python library that handles interactive play-through of text games, as well as backend functions like state tracking and reward assignment. It comes with a curated list of games whose features and challenges we have analyzed. More significantly, it enables users to handcraft or automatically generate new games. Its generative mechanisms give precise control over the difficulty, scope, and language of constructed games, and can be used to relax challenges inherent to commercial text games like partial observability and sparse rewards. By generating sets of varied but similar games, TextWorld can also be used to study generalization and transfer learning. We cast text-based games in the Reinforcement Learning formalism, use our framework to develop a set of benchmark games, and evaluate several baseline agents on this set and the curated list.

Moral Hazard in Multi-Agent Language Models
Cooperation can fail when socially valuable effort is costly, weakly observable, and mainly benefits others. Drawing on Holmstr\"om's team moral-hazard model, we introduce the Dialogue Moral Hazard Game, a textual hidden-action game for testing whether language agents provide costly, other-benefiting effort. In each episode, an agent can preserve an immediate local reward or pay a query cost to reveal a hidden safety fact that primarily helps another agent choose a team-beneficial final action. We evaluate seven open-weight language models across base and intervention conditions. Base models show two main failure modes: many preserve local reward without achieving team success, while others query often but fail to communicate useful warnings or change downstream final choices. In other words, models rarely complete the intended sequence of querying hidden facts, posting useful warning notes, and using those notes to make team-beneficial final decisions. We then evaluate supervised fine-tuning, RL fine-tuning with RLOO, sequential SFT+RL, and GEPA prompt optimization. Interventions produce limited, model-specific gains: OLMo 7B improves most under LoRA training, while Qwen3 4B benefits most from prompt optimization, though not always through the intended query mechanism. Overall, costly other-benefiting effort is not a default behavior of current open-weight language agents, but can be partially induced.
Evolution strategies as a scalable alternative to reinforcement learning
We’ve discovered that evolution strategies (ES), an optimization technique that’s been known for decades, rivals the performance of standard reinforcement learning (RL) techniques on modern RL benchmarks (e.g. Atari/MuJoCo), while overcoming many of RL’s inconveniences.