

Large language models (LLMs) have become the first source millions consult when evaluating political claims, yet they were trained on an open internet that state-sponsored disinformation operations have been designed to pollute. We audit four frontier models across 2,268 responses to 63 fabrications from eight documented influence operations and find that even a single published fact-check can shift a model from hedging about a fabrication to rejecting it outright. Overall, models correctly rejected only 81% of fabrications while repeating disinformation in 3% of cases. Critically, the remaining 16% of responses would have left users unable to determine whether an fabricated claims were true or false. Fact-checks may present an avenue for addressing this vulnerability. Narratives which had been debunked by at least one IFCN certified fact-checking organization were correctly rejected as disinformation 93% of the time compared to just 76% of the time for unchecked narratives. Exploratory analyses suggest that this mechanism operates through training data, with models echoing the specific vocabulary of published corrections when available during their training windows. We conclude by discussing how fact-checks designed for human audiences appear to serve as effective protection for LLMs, converting both model uncertainty and outright disinformation into definitive rejections
Political disinformation concentrates in repeated claims across media
The prevalence and dynamics of disinformation remain contentious, partly because measures have relied on posts containing URLs from untrustworthy sources. We move beyond this by detecting disinformation in text and across posts. Using retrieval-augmented generation, we match six million Facebook, Instagram, and X posts by politicians from the United States, United Kingdom, and Germany, and two million articles from news outlets to fact-checked claims. We show that disinformation is concentrated in a small number of combinations of policy issues and parties and that just over hundred distinct claims account for around half of all disinformation across the three countries. They often appear first on a single platform, later on multiple, and subsequently in news coverage before being fact-checked. These findings suggest that disinformation is concentrated in a narrow segment of political communication, potentially creating repeated exposure that may shape the terms of public debate through both social and news media.
Generative propaganda: Evidence of AI’s impact from a state-backed disinformation campaign
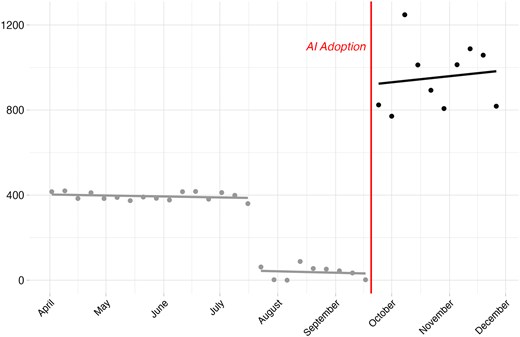
Abstract Can AI bolster state-backed propaganda campaigns, in practice? Growing use of AI and large language models has drawn attention to the potential for accompanying tools to be used by malevolent actors. Though recent laboratory and experimental evidence has substantiated these concerns in principle, the usefulness of AI tools in the production of propaganda campaigns has remained difficult to ascertain. Drawing on the adoption of generative-AI techniques by a state-affiliated propaganda site with ties to Russia, we test whether AI adoption enabled the website to amplify and enhance its production of disinformation. First, we find that the use of generative-AI tools facilitated the outlet’s generation of larger quantities of disinformation. Second, we find that use of generative-AI coincided with shifts in the volume and breadth of published content. Finally, drawing on a survey experiment comparing perceptions of articles produced prior to and following the adoption of AI tools, we show that the AI-assisted articles maintained their persuasiveness in the postadoption period. Our results illustrate how generative-AI tools have already begun to alter the size and scope of state-backed propaganda campaigns.
Facts and Myths about Misperceptions
Misperceptions threaten to warp mass opinion and public policy on controversial issues in politics, science, and health. What explains the prevalence and persistence of these false and unsupported beliefs, which seem to be genuinely held by many people? Though limits on cognitive resources and attention play an important role, many of the most destructive misperceptions arise in domains where individuals have weak incentives to hold accurate beliefs and strong directional motivations to endorse beliefs that are consistent with a group identity such as partisanship. These tendencies are often exploited by elites who frequently create and amplify misperceptions to influence elections and public policy. Though evidence is lacking for claims of a “post-truth” era, changes in the speed with which false information travels and the extent to which it can find receptive audiences require new approaches to counter misinformation. Reducing the propagation and influence of false claims will require further efforts to inoculate people in advance of exposure (for example, media literacy), debunk false claims that are already salient or widespread (for example, fact-checking), reduce the prevalence of low-quality information (for example, changing social media algorithms), and discourage elites from promoting false information (for example, strengthening reputational sanctions).
Dialogues on Democracy: Belief-Tailored AI Conversations Reduce Inaccurate Election Denial Beliefs
Elections, while central to democratic functioning, have become increasingly threatened by beliefs about election fraud. Artificial intelligence (AI) provides a novel opportunity to address such false beliefs through dynamic conversation and debunking. Through two experiments (N = 1,802 Republicans from Lucid who endorsed election fraud claims), we examined the use of AI to fact-check 2020 election conspiracies prior to the 2024 US Presidential election. We tested the effects of two treatments (an information-tailored and values-tailored AI dialogue) in which AI fact-checked their claims and tailored arguments to the specific election conspiracy that the participant themselves articulated. Both treatment conditions, when compared to a control dialogue and a simple statement that the conspiracy was incorrect, reduced confidence in their election conspiracy claims. There was no significant difference between information-tailored and values-tailored feedback. Promisingly, participants with the strongest baseline denialism experienced the largest decreases in denialism beliefs. These studies highlight the potential of AI-driven interventions to address election misinformation.
Deep Storytelling: Collective Sensemaking and Layers of Meaning in U.S. Elections
Misinformation and disinformation about elections remain pressing concerns for researchers, policymakers, and the public. Critics, however, argue that fears surrounding these issues are exaggerated due to a lack of evidence of impact. This debate highlights the challenges inherent in assessing the impacts of misinformation, as the drivers of false and misleading content often exist in the context of a specific claim. To address this issue, we examined false and misleading information surrounding the 2020 and 2022 U.S. national elections, focusing on the contextual features of online conversations that fueled various rumors. We developed two qualitative codebooks, creating the second after realizing that the first, which labeled individual tweets, failed to capture broader rumoring dynamics. By integrating multi-layered qualitative coding with thematic analysis and quantitative visualizations, we show how influencers, political elites, and audiences collaboratively told deep stories from 2020 through 2022. As these stories were told, audiences interpreted events in 2022 through the lens of the 2020 story, guided by influencers' cues, leading to an evolution in storytelling style between the two election cycles. This ongoing performance was tailored to align with the incentive structures, affordances, and attention economy of social media. We combine deep stories with theories of collective sensemaking and rumoring, creating a framework to better assess the contextual features surrounding false and misleading information.

State media control influences large language models
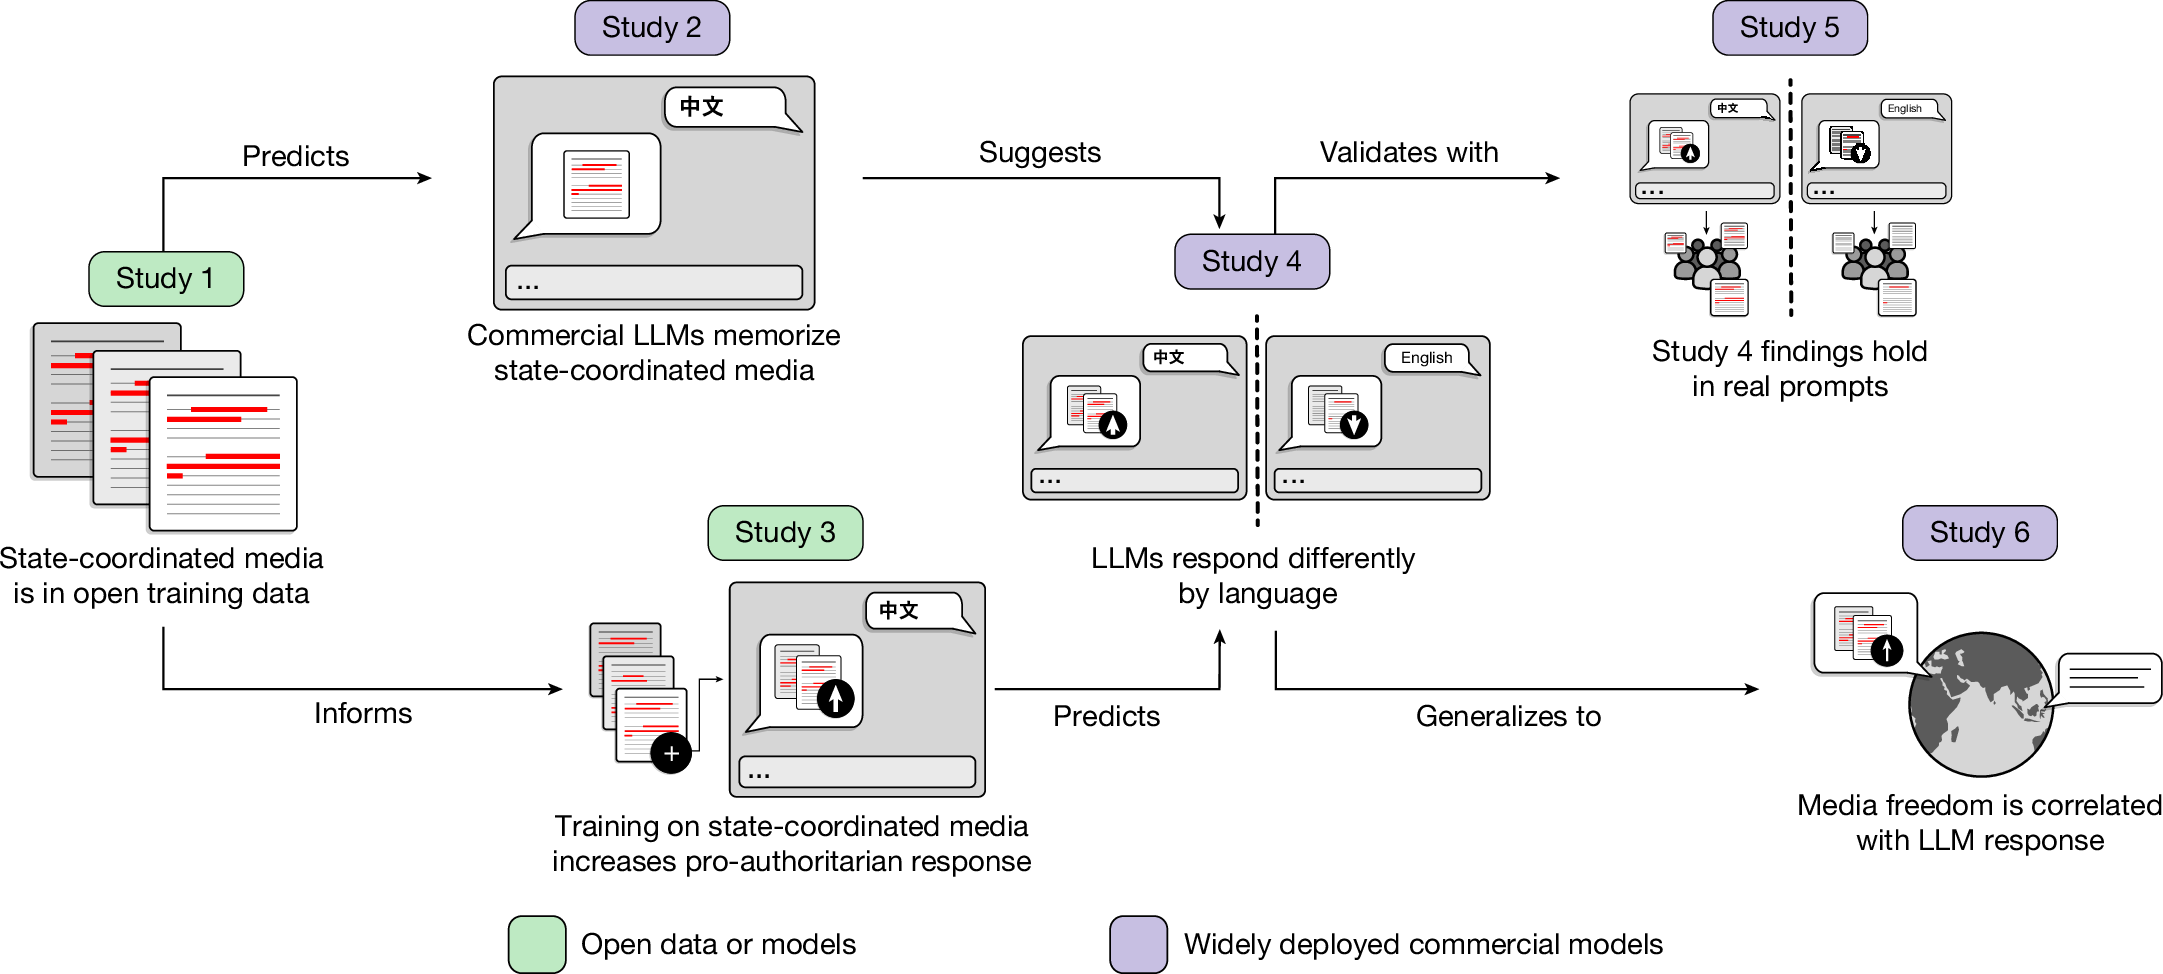
Millions of people around the world query large language models (LLMs) for information. Although several studies have compellingly documented the persuasive potential of these models1–10, there is limited evidence of who or what influences the models themselves, leading to a flurry of concerns about which companies and governments build and regulate the models. Here we show through six studies that government control of the media across the world already influences the output of LLMs via their training data. We use a cross-national audit to show that LLMs exhibit a stronger pro-government valence in the languages of countries with lower media freedom than in those with higher media freedom. This result is correlational, so to triangulate the specific mechanism of how state media control can influence LLMs, we develop a multi-part case study on China’s media. We demonstrate that media scripted and curated by the Chinese state appears in LLM training datasets. To evaluate the plausible effect of this inclusion, we use an open-weight model to show that additional pretraining on Chinese state-coordinated media generates more positive answers to prompts about Chinese political institutions and leaders. We link this phenomenon to commercial models through two audit studies demonstrating that prompting models in Chinese generates more positive responses about China’s institutions and leaders than do the same queries in English. The combination of influence and persuasive potential across languages suggests the troubling conclusion that states and powerful institutions have increased strategic incentives to leverage media control in the hopes of shaping LLM output.
State media control influences large language models
Millions of people around the world query large language models (LLMs) for information. Although several studies have compellingly documented the persuasive potential of these models1–10, there is limited evidence of who or what influences the models themselves, leading to a flurry of concerns about which companies and governments build and regulate the models. Here we show through six studies that government control of the media across the world already influences the output of LLMs via their training data. We use a cross-national audit to show that LLMs exhibit a stronger pro-government valence in the languages of countries with lower media freedom than in those with higher media freedom. This result is correlational, so to triangulate the specific mechanism of how state media control can influence LLMs, we develop a multi-part case study on China’s media. We demonstrate that media scripted and curated by the Chinese state appears in LLM training datasets. To evaluate the plausible effect of this inclusion, we use an open-weight model to show that additional pretraining on Chinese state-coordinated media generates more positive answers to prompts about Chinese political institutions and leaders. We link this phenomenon to commercial models through two audit studies demonstrating that prompting models in Chinese generates more positive responses about China’s institutions and leaders than do the same queries in English. The combination of influence and persuasive potential across languages suggests the troubling conclusion that states and powerful institutions have increased strategic incentives to leverage media control in the hopes of shaping LLM output.
The Liar’s Dividend: Can Politicians Claim Misinformation to Evade Accountability?
This study addresses the phenomenon of misinformation about misinformation, or politicians "crying wolf"' over fake news. Strategic and false claims that stories are fake news or deepfakes may benefit politicians by helping them maintain support after a scandal. We posit that this benefit, known as the "liar's dividend," may be achieved through two politician strategies: by invoking informational uncertainty or by encouraging oppositional rallying of core supporters. We administer five survey experiments to over 15,000 American adults detailing hypothetical politician responses to stories describing real politician scandals. We find that claims of misinformation representing both strategies raise politician support across partisan subgroups. These strategies are effective against text-based reports of scandals, but are largely ineffective against video evidence and do not reduce general trust in media. Finally, these false claims produce greater dividends for politicians than alternative responses to scandal, such as remaining silent or apologizing.
RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
Large Language Models (LLMs) hold significant potential for advancing fact-checking by leveraging their capabilities in reasoning, evidence retrieval, and explanation generation. However, existing benchmarks fail to comprehensively evaluate LLMs and Multimodal Large Language Models (MLLMs) in realistic misinformation scenarios. To bridge this gap, we introduce RealFactBench, a comprehensive benchmark designed to assess the fact-checking capabilities of LLMs and MLLMs across diverse real-world tasks, including Knowledge Validation, Rumor Detection, and Event Verification. RealFactBench consists of 6K high-quality claims drawn from authoritative sources, encompassing multimodal content and diverse domains. Our evaluation framework further introduces the Unknown Rate (UnR) metric, enabling a more nuanced assessment of models' ability to handle uncertainty and balance between over-conservatism and over-confidence. Extensive experiments on 7 representative LLMs and 4 MLLMs reveal their limitations in real-world fact-checking and offer valuable insights for further research. RealFactBench is publicly available at https://github.com/kalendsyang/RealFactBench.git.
Leveraging Motivations to Curb Misinformation: Self-Affirmation Reduces the Appeal of Political Conspiracy Theories
Abstract: In an era where digital misinformation poses significant challenges to societal well-being, this study explores a novel approach to preserving information integrity by addressing the motivational underpinnings of conspiracy theory engagement. As conspiracy theories proliferate online, traditional fact-checking and debunking strategies often prove ineffective due to the self-reinforcing nature of conspiracy theories. This research investigates whether a priori self-affirmation interventions can reduce individuals’ propensity to engage with conspiracy theories by preemptively fulfilling the ego-protective function these theories often serve. Using a randomized experiment ( N = 451), this study finds that participants who completed a self-affirmation task were less likely to read politicized conspiracy theories, and those who chose to read a conspiracy theory reported greater feelings of affirmation than those who did not. Thus, bolstering individuals’ self-integrity may offer an opportunity to mitigate the appeal of politicized conspiracy theories.

The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

Election Disinformation in Different Languages is a Big Problem in the U.S.
And it’s driving a wedge between voters in non-English communities Mis- and disinformation about elections predate the endless scroll of modern social media services. [1] Yet easy access to online information channels and amplification tools enable false narratives to spread at a massive scale. When false narratives are combined with data voids and unique cultural […]
Debunking: A Meta-Analysis of the Psychological Efficacy of Messages Countering Misinformation
This meta-analysis investigated the factors underlying effective messages to counter attitudes and beliefs based on misinformation. Because misinformation can lead to poor decisions about consequential matters and is persistent and difficult to correct, debunking it is an important scientific and public-policy goal. This meta-analysis ( k = 52, N = 6,878) revealed large effects for presenting misinformation ( ds = 2.41–3.08), debunking ( ds = 1.14–1.33), and the persistence of misinformation in the face of debunking ( ds = 0.75–1.06). Persistence was stronger and the debunking effect was weaker when audiences generated reasons in support of the initial misinformation. A detailed debunking message correlated positively with the debunking effect. Surprisingly, however, a detailed debunking message also correlated positively with the misinformation-persistence effect.

Are Large Language Models Sensitive to the Motives Behind Communication?
Human communication is $\textit{motivated}$: people speak, write, and create content with a particular communicative intent in mind. As a result, information that large language models (LLMs) and AI agents process is inherently framed by humans' intentions and incentives. People are adept at navigating such nuanced information: we routinely identify benevolent or self-serving motives in order to decide what statements to trust. For LLMs to be effective in the real world, they too must critically evaluate content by factoring in the motivations of the source---for instance, weighing the credibility of claims made in a sales pitch. In this paper, we undertake a comprehensive study of whether LLMs have this capacity for $\textit{motivational vigilance}$. We first employ controlled experiments from cognitive science to verify that LLMs' behavior is consistent with rational models of learning from motivated testimony, and find they successfully discount information from biased sources in a human-like manner. We then extend our evaluation to sponsored online adverts, a more naturalistic reflection of LLM agents' information ecosystems. In these settings, we find that LLMs' inferences do not track the rational models' predictions nearly as closely---partly due to additional information that distracts them from vigilance-relevant considerations. However, a simple steering intervention that boosts the salience of intentions and incentives substantially increases the correspondence between LLMs and the rational model. These results suggest that LLMs possess a basic sensitivity to the motivations of others, but generalizing to novel real-world settings will require further improvements to these models.
Generative propaganda: Evidence of AI’s impact from a state-backed disinformation campaign
Abstract. Can AI bolster state-backed propaganda campaigns, in practice? Growing use of AI and large language models has drawn attention to the potential f