


Campaign persuasion operates with notable consistency across political parties, message tone, and information environment., Evidence across social science indicates that average effects of persuasive messages are small. One commonly offered explanation for these small effects is heterogeneity: Persuasion may only work well in specific circumstances. To evaluate heterogeneity, we repeated an experiment weekly in real time using 2016 U.S. presidential election campaign advertisements. We tested 49 political advertisements in 59 unique experiments on 34,000 people. We investigate heterogeneous effects by sender (candidates or groups), receiver (subject partisanship), content (attack or promotional), and context (battleground versus non-battleground, primary versus general election, and early versus late). We find small average effects on candidate favorability and vote. These small effects, however, do not mask substantial heterogeneity even where theory from political science suggests that we should find it. During the primary and general election, in battleground states, for Democrats, Republicans, and Independents, effects are similarly small. Heterogeneity with large offsetting effects is not the source of small average effects.
The Minimal Persuasive Effects of Campaign Contact in General Elections: Evidence from 49 Field Experiments
Significant theories of democratic accountability hinge on how political campaigns affect Americans’ candidate choices. We argue that the best estimate of the effects of campaign contact and advertising on Americans’ candidates choices in general elections is zero. First, a systematic meta-analysis of 40 field experiments estimates an average effect of zero in general elections. Second, we present nine original field experiments that increase the statistical evidence in the literature about the persuasive effects of personal contact tenfold. These experiments’ average effect is also zero. In both existing and our original experiments, persuasive effects only appear to emerge in two rare circumstances. First, when candidates take unusually unpopular positions and campaigns invest unusually heavily in identifying persuadable voters. Second, when campaigns contact voters long before election day and measure effects immediately—although this early persuasion decays. These findings contribute to ongoing debates about how political elites influence citizens’ judgments.
Why Are American Presidential Election Campaign Polls so Variable When Votes Are so Predictable?
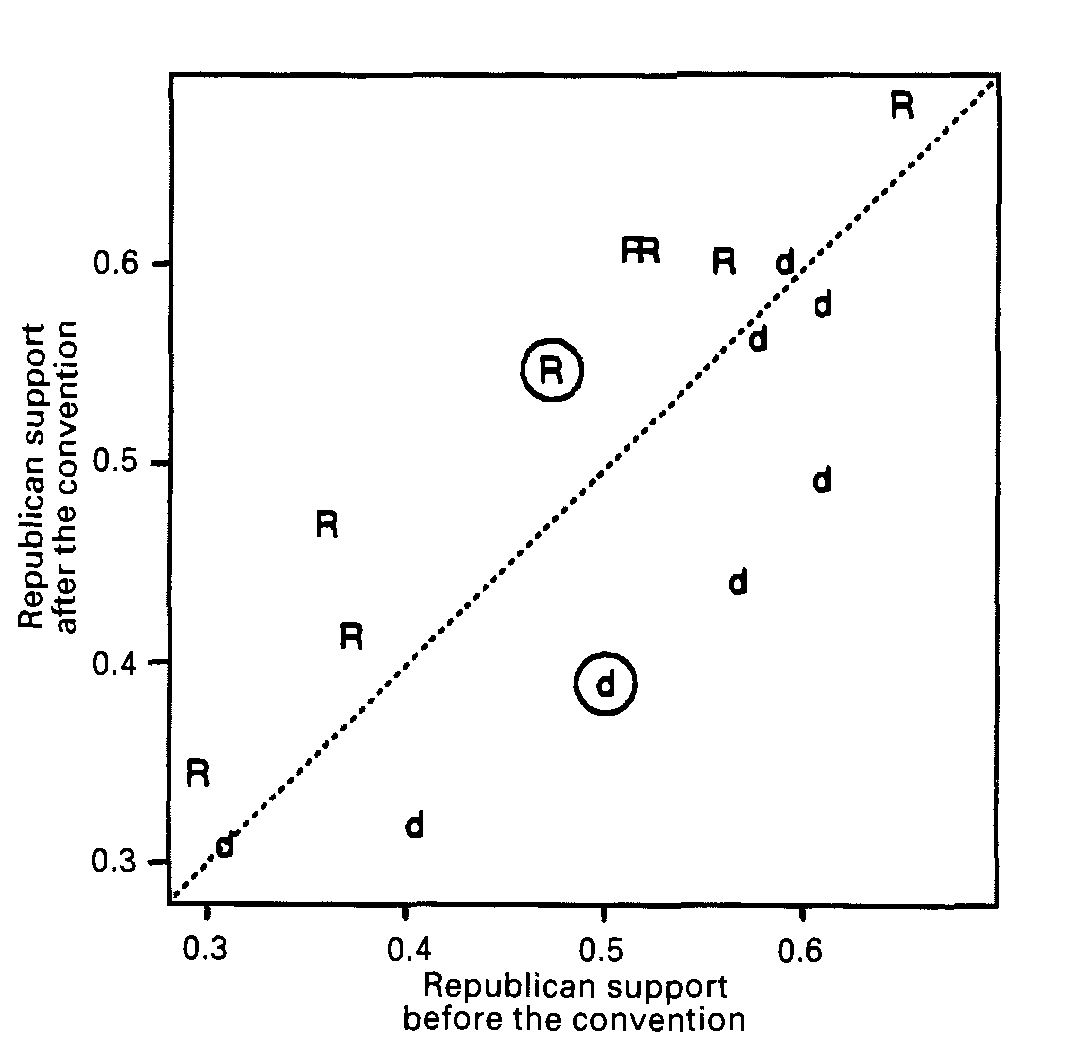
As most political scientists know, the outcome of the U.S. Presidential election can be predicted within a few percentage points (in the popular vote), based on information available months before the election. Thus, the general election campaign for president seems irrelevant to the outcome (except in very close elections), despite all the media coverage of campaign strategy. However, it is also well known that the pre-election opinion polls can vary wildly over the campaign, and this variation is generally attributed to events in the campaign. How can campaign events affect people's opinions on whom they plan to vote for, and yet not affect the outcome of the election? For that matter, why do voters consistently increase their support for a candidate during his nominating convention, even though the conventions are almost entirely predictable events whose effects can be rationally forecast? In this exploratory study, we consider several intuitively appealing, but ultimately wrong, resolutions to this puzzle, and discuss our current understanding of what causes opinion polls to fluctuate and yet reach a predictable outcome. Our evidence is based on graphical presentation and analysis of over 67,000 individual-level responses from forty-nine commercial polls during the 1988 campaign and many other aggregate poll results from the 1952–1992 campaigns. We show that responses to pollsters during the campaign are not generally informed or even, in a sense we describe, "rational." In contrast, voters decide which candidate to eventually support based on their enlightened preferences, as formed by the information they have learned during the campaign, as well as basic political cues such as ideology and party identification. We cannot prove this conclusion, but we do show that it is consistent with the aggregate forecasts and individual-level opinion poll responses. Based on the enlightened preferences hypothesis, we conclude that the news media have an important effect on the outcome of Presidential elections–-not due to misleading advertisements, sound bites, or spin doctors, but rather by conveying candidates' positions on important issues. Winner of the Pi Sigma Alpha Awardfor the best paper at the previous year's meetings of the Midwest Political Science Association. Replication data at the Harvard Dataverse: [https://doi.org/10.7910/DVN/I7GIKD](https://doi.org/10.7910/DVN/I7GIKD).
Persuasion: Empirical Evidence
We provide a selective survey of empirical evidence on the effects as well as the drivers of persuasive communication. We consider persuasion directed at consumers, voters, donors, and investors. We organize our review around four questions. First, to what extent does persuasion affect the behavior of each of these groups? Second, what models best capture the response to persuasive communication? Third, what are persuaders' incentives, and what limits their ability to distort communications? Finally, what evidence exists on the way persuasion affects equilibrium outcomes in economics and politics?

In Texas, AI-generated political ads are blurring the line between real and fake - Poynter
Experts say increasingly realistic campaign ads could make it harder for voters to distinguish authentic messages from fabricated ones
How do social media feed algorithms affect attitudes and behavior in an election campaign?
We investigated the effects of Facebook’s and Instagram’s feed algorithms during the 2020 US election. We assigned a sample of consenting users to reverse-chronologically-ordered feeds instead of the default algorithms. Moving users out of algorithmic feeds substantially decreased the time they spent on the platforms and their activity. The chronological feed also affected exposure to content: The amount of political and untrustworthy content they saw increased on both platforms, the amount of content classified as uncivil or containing slur words they saw decreased on Facebook, and the amount of content from moderate friends and sources with ideologically mixed audiences they saw increased on Facebook. Despite these substantial changes in users’ on-platform experience, the chronological feed did not significantly alter levels of issue polarization, affective polarization, political knowledge, or other key attitudes during the 3-month study period.

Simulating Aggregate Electoral Opinion Trajectories with LLM Personas and Media Exposure
LLM-based election simulation has largely been evaluated against a single final outcome, in many cases neglecting how much it can recover the trajectory shaped by media exposure and shifting candidate support. We propose evaluating election simulations in terms of trajectory fidelity: whether persona-conditioned LLM agents can update their beliefs in response to media to reproduce the temporal movement of public opinion, both in aggregate and across demographic subgroups. We design a framework in which each LLM agent carries its belief across time and updates it as new campaign information arrives. We further investigate how performance can vary across simulation design choices such as media exposure model, election context, and survey questionnaire. In a study on the 2026 Seoul mayoral and local elections, we validate simulated trajectories against weekly public-opinion polls and find that simulations that carry prior beliefs across time—rather than simulating each poll date independently—substantially improves alignment with observed polling movement, while the way media exposure is personalized leaves aggregate movement largely intact but reshapes subgroup-level dynamics. We propose a framework for validating simulated opinion trajectories against real-world traces, and discuss the simulation design choices that can influence the performance.
Political Bias Audits of LLMs Capture Sycophancy to the Inferred Auditor
Large language models (LLMs) are commonly evaluated for political bias based on their responses to fixed questionnaires, which typically place frontier models on the political left. A parallel literature shows that LLMs are sycophantic: they adapt their answers to the views, identities, and expectations of the user. We show that these findings are linked: standard political-bias audits partly capture sycophantic accommodation to the inferred auditor. We employ a factorial experiment across three major audit instruments--the Political Compass Test, the Pew Political Typology, and 1,540 partisan-benchmarked Pew American Trends Panel items--administered to six frontier LLMs while varying only the asker's stated identity (N = 30,990 responses). At baseline, all six models lean left. When the asker identifies as a conservative Republican, responses shift sharply: the share of items closer to Democrats falls by 28-62 percentage points, and all six models move right of center. A mirror-image progressive-Democrat cue produces little change; rightward accommodation is 8.0$\times$ larger than leftward. When asked who the default asker is, models identify an auditor, researcher, or academic; when asked what answer that asker expects, they select the Democrat-coded option 75% of the time, nearly the rate under an explicit progressive cue. These patterns are inconsistent with a purely fixed model ideology and indicate that single-prompt audits capture an interaction between model and inferred interlocutor. Political bias in LLMs is therefore not a fixed point on an ideological scale but a response profile that must be mapped across realistic interlocutors.

A meta-analysis of the persuasive power of large language models
Large language models (LLMs) are increasingly used for persuasion, such as in political communication and marketing, where they affect how people think, choose, and act. Yet, empirical findings on the effectiveness of LLMs in persuasion compared to humans remain inconsistent. The aim of this study was to systematically review and meta-analytically assess whether LLMs differ from humans in persuasive effectiveness, and under which contextual conditions LLMs are particularly effective. We identified 7 studies with 17,422 participants primarily recruited from English-speaking countries and 12 effect size estimates. Egger’s test indicated potential small-study effects ($$p =.018$$), but the trim-and-fill analysis did not impute any missing studies, suggesting a low risk of publication bias. We then compute the standardized effect sizes based on Hedges’ g. The results show no significant overall difference in persuasive performance between LLMs and humans ($$g = 0.02$$, $$p =.530$$). However, we observe substantial heterogeneity across studies ($$I^2 = 75.97\%$$), suggesting that persuasiveness strongly depends on contextual factors. In separate exploratory moderator analyses, no individual factor (e.g., LLM model, conversation design, or domain) reached statistical significance, which may be due to the limited number of studies. When considered jointly in a combined model, these factors explained a large proportion of the between-study variance ($$R^2 = 81.93\%$$), and residual heterogeneity is low ($$I^2 = 35.51\%$$). Although based on a small number of studies, this suggests that differences in LLM model, conversation design, and domain are important contextual factors in shaping persuasive performance, and that single-factor tests may understate their influence. Our results highlight that LLMs can match human performance in persuasion, but their success depends strongly on how they are implemented and embedded in communication contexts.
Auditing Political Exposure Bias: Algorithmic Amplification on Twitter/X During the 2024 U.S. Presidential Election
Approximately 50% of tweets in X's user timelines are personalized recommendations from accounts they do not follow. This raises a critical question: What political content are users exposed to beyond their established networks, and what implications does this have for democratic discourse online? In this paper, we present a six-week audit of X's algorithmic content recommendations during the 2024 U.S. Presidential Election by deploying 120 sock-puppet monitoring accounts to capture tweets from their personalized "For You" timelines. Our objective is to quantify out-of-network content exposure for right- and left-leaning user profiles and assess any potential inequalities and biases in political exposure. Our findings indicate that X's algorithm skews exposure toward a few high-popularity accounts across all users, with right-leaning users experiencing the highest level of exposure inequality. Both left- and right-leaning users encounter amplified exposure to accounts aligned with their own political views and reduced exposure to opposing viewpoints. Additionally, we observe that new accounts experience a right-leaning bias in exposure within their default timelines. Our work contributes to understanding how content recommendation systems may induce and reinforce biases while exacerbating vulnerabilities among politically polarized user groups. We underscore the importance of transparency-aware algorithms in addressing critical issues such as safeguarding election integrity and fostering a more informed digital public sphere.
Redesigning algorithms to intervene on social norm misperceptions during a national election
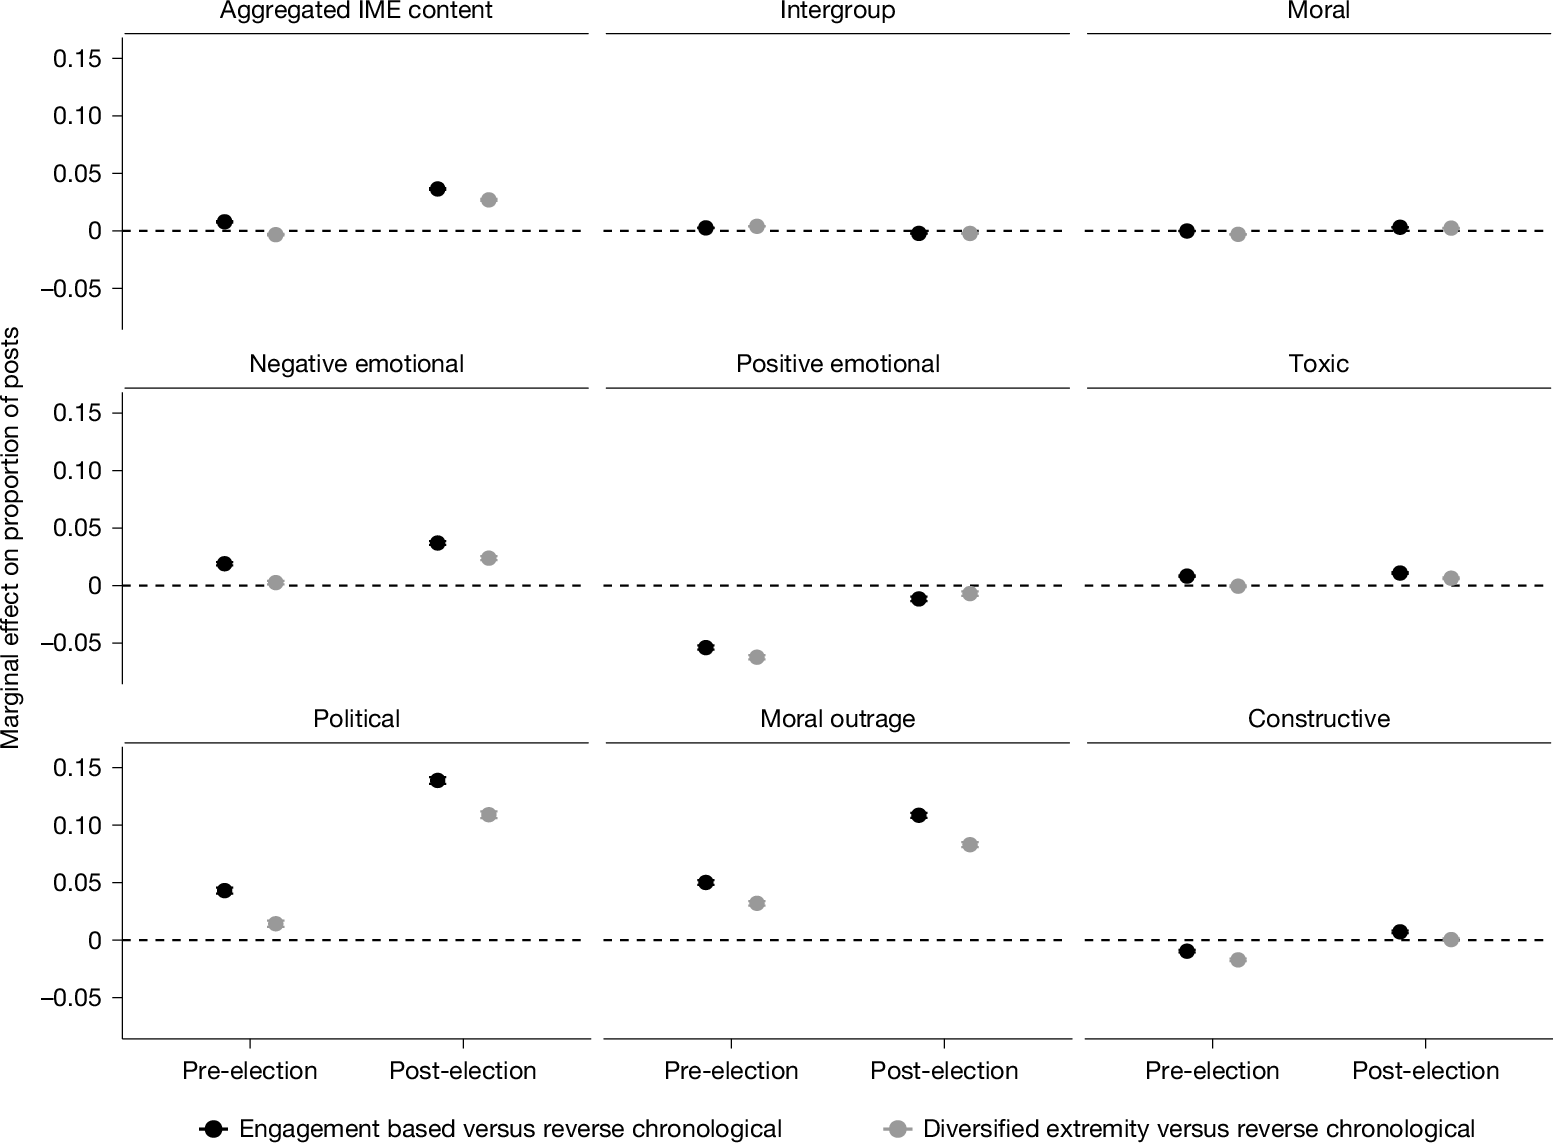
For the first time in history, civic discourse commonly occurs in digital environments in which algorithms influence exposure to social information1,2. It is increasingly important to understand whether and how these algorithms affect political discourse3–5. Here we built custom feed-ranking algorithms with full control over their features, and randomly assigned 2,000 participants to use them for 8 weeks (before and after the 2024 US presidential election). We tested whether an engagement-based algorithm (used on major social media platforms6,7) amplifies intergroup, moralized and emotional (IME) information in ways that skew perceptions of social norms around political dialogue5,8, and whether it increased engagement with IME content and perceptions of partisan animosity (compared with a reverse-chronological feed9,10). We also developed and tested a ‘diversified extremity’ algorithm to reduce the influence of extreme users11–13 to improve the accuracy of social norm perception14–16 and reduce perceptions of partisan animosity. We found that engagement-based feeds amplified IME and toxic content relative to reverse-chronological feeds, with the largest increases in moral outrage and political content. Engagement-based feeds also reduced prescriptive norm perception accuracy (albeit in an unexpected direction) and increased perceived partisan animosity. However, they did not significantly alter users’ own engagement behaviours. The diversified extremity algorithm reduced IME and toxic content exposure, improved prescriptive norm accuracy, yet maintained comparable platform enjoyment—suggesting that reducing the influence of extreme users can curb algorithmic distortions without diminishing user experience.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

The political effects of X’s feed algorithm
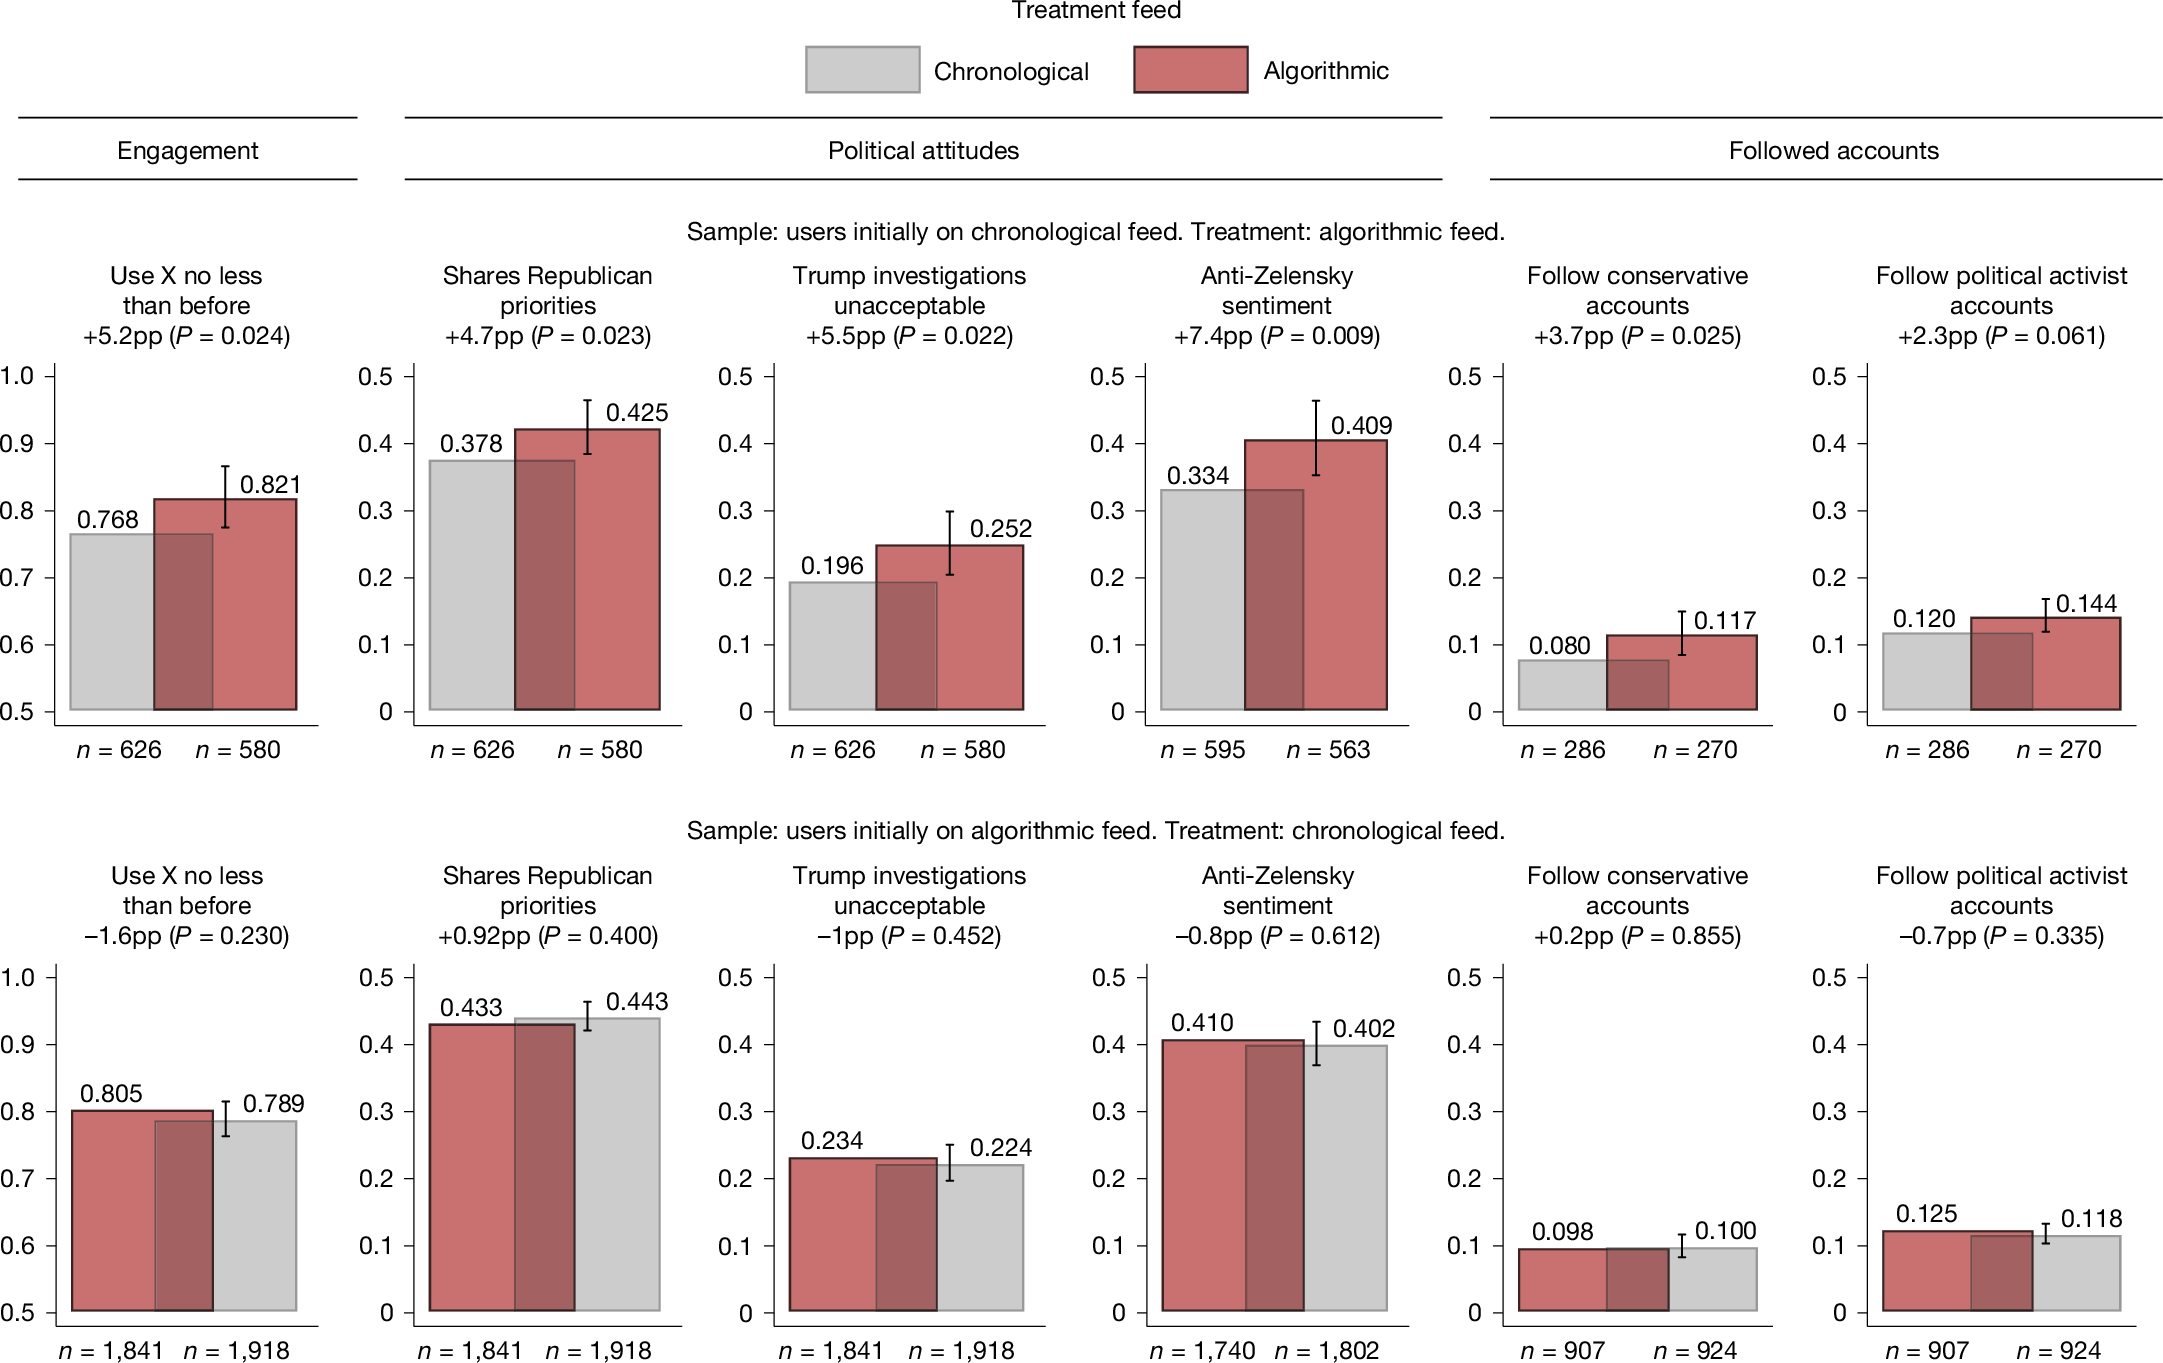
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
The political effects of X’s feed algorithm
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
Undermining a Rival Party’s Issue Competence through Negative Campaigning: Experimental Evidence from the USA, Denmark, and Australia
Much party communication encourages voters to lower issue-related evaluations of rival parties. Yet, studies of such influence are rare. Drawing on research on political parties’ negative campaigning, this article starts to fill this gap. We triangulate evidence from four survey experiments across six issues in Denmark, the US, and Australia, and show that a party’s negative campaigning decreases voters’ evaluations of the target party’s issue-handling competence (i.e. issue ownership), but does not backlash on voters’ evaluations of the sponsor. Such attack on the target party does not have to be tied to a negative policy development like the crime rate to undermine the target party’s competence evaluations. At the same time, a negative policy development only undermines a party’s evaluations when it is accompanied by a rival party’s negative campaigning attack. The implications for party competition and the mass-elite linkage are important.

How to break populist parties’ appeal? An experimental evaluation of communication counter-strategies
Right-wing populist parties have become a major challenge to liberal democracies worldwide. How can mainstream parties effectively counter their appeal? While prior research has focused on the drivers of populist support, much less is known about how to counter right-wing populist rhetoric. We test four communication counter-strategies that target core elements of right-wing populist appeals: (i) undermining populists’ claims to democratic credibility, (ii) promoting inclusive in-group identity to counter exclusionary narratives, (iii) highlighting their performance legitimacy, and (iv) emphasizing the procedural legitimacy of mainstream parties. Drawing on real-world party communications from social media, manifestos, and press releases, we created 170 experimental treatments (posters and social media posts varying in format and complexity) to simulate how voters encounter political messages in everyday life. In a large-scale survey experiment with over 24,000 respondents in Germany, messages undermining right-wing populists’ democratic credibility prove most effective, particularly among citizens with high initial support for such parties.
Variety Effects in Mobile Advertising
Mobile app users are often exposed to a sequence of short-lived marketing interventions (e.g., ads) within each usage session. This study examines how an increase in the variety of ads shown in a session affects a user's response to the next ad. The authors leverage the quasi-experimental variation in ad assignment in their data and propose an empirical framework that accounts for different types of confounding to isolate the effects of a unit increase in variety. Across a series of models, the authors consistently show that an increase in ad variety in a session results in a higher response rate to the next ad: holding all else fixed, a unit increase in variety of the prior sequence of ads can increase the click-through rate on the next ad by approximately 13%. The authors then explore the underlying mechanism and document empirical evidence for an attention-based account. The article offers important managerial implications by identifying a source of interdependence across ad exposures that is often ignored in the design of advertising auctions. Furthermore, the attention-based mechanism suggests that platforms can incorporate real-time attention measures to help advertisers with targeting dynamics.