

Ternary Bonsai 2 27B retains 98.2% of Qwen3.8 27B benchmark performance in a 5.9GB footprint, with multimodal and agentic capabilities.
PrismML on Twitter / X
1-bit Bonsai 8B running locally on an M4 Pro (MLX) alongside a standard 16-bit 8B model.Same class of model, very different deployment profile: far lower memory use and substantially higher throughput. pic.twitter.com/dxMFSyCZDG— PrismML (@PrismML) March 31, 2026

PrismML — Announcing 1-bit Bonsai: The First Commercially Viable 1-bit LLMs
Today, we are announcing 1-bit Bonsai models that bring advanced intelligence to the devices where people actually live and work.

A 30B Qwen Model Walks Into a Raspberry Pi… and Runs in Real Time
ByteShape's device-optimized release of Qwen3-30B-A3B-Instruct-2507.

Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
Friday’s big release was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen research lab. I’ve been looking forward to this one: 27B is an …
qwen3.5:27b
Qwen 3.5 is a family of open-source multimodal models that delivers exceptional utility and performance.
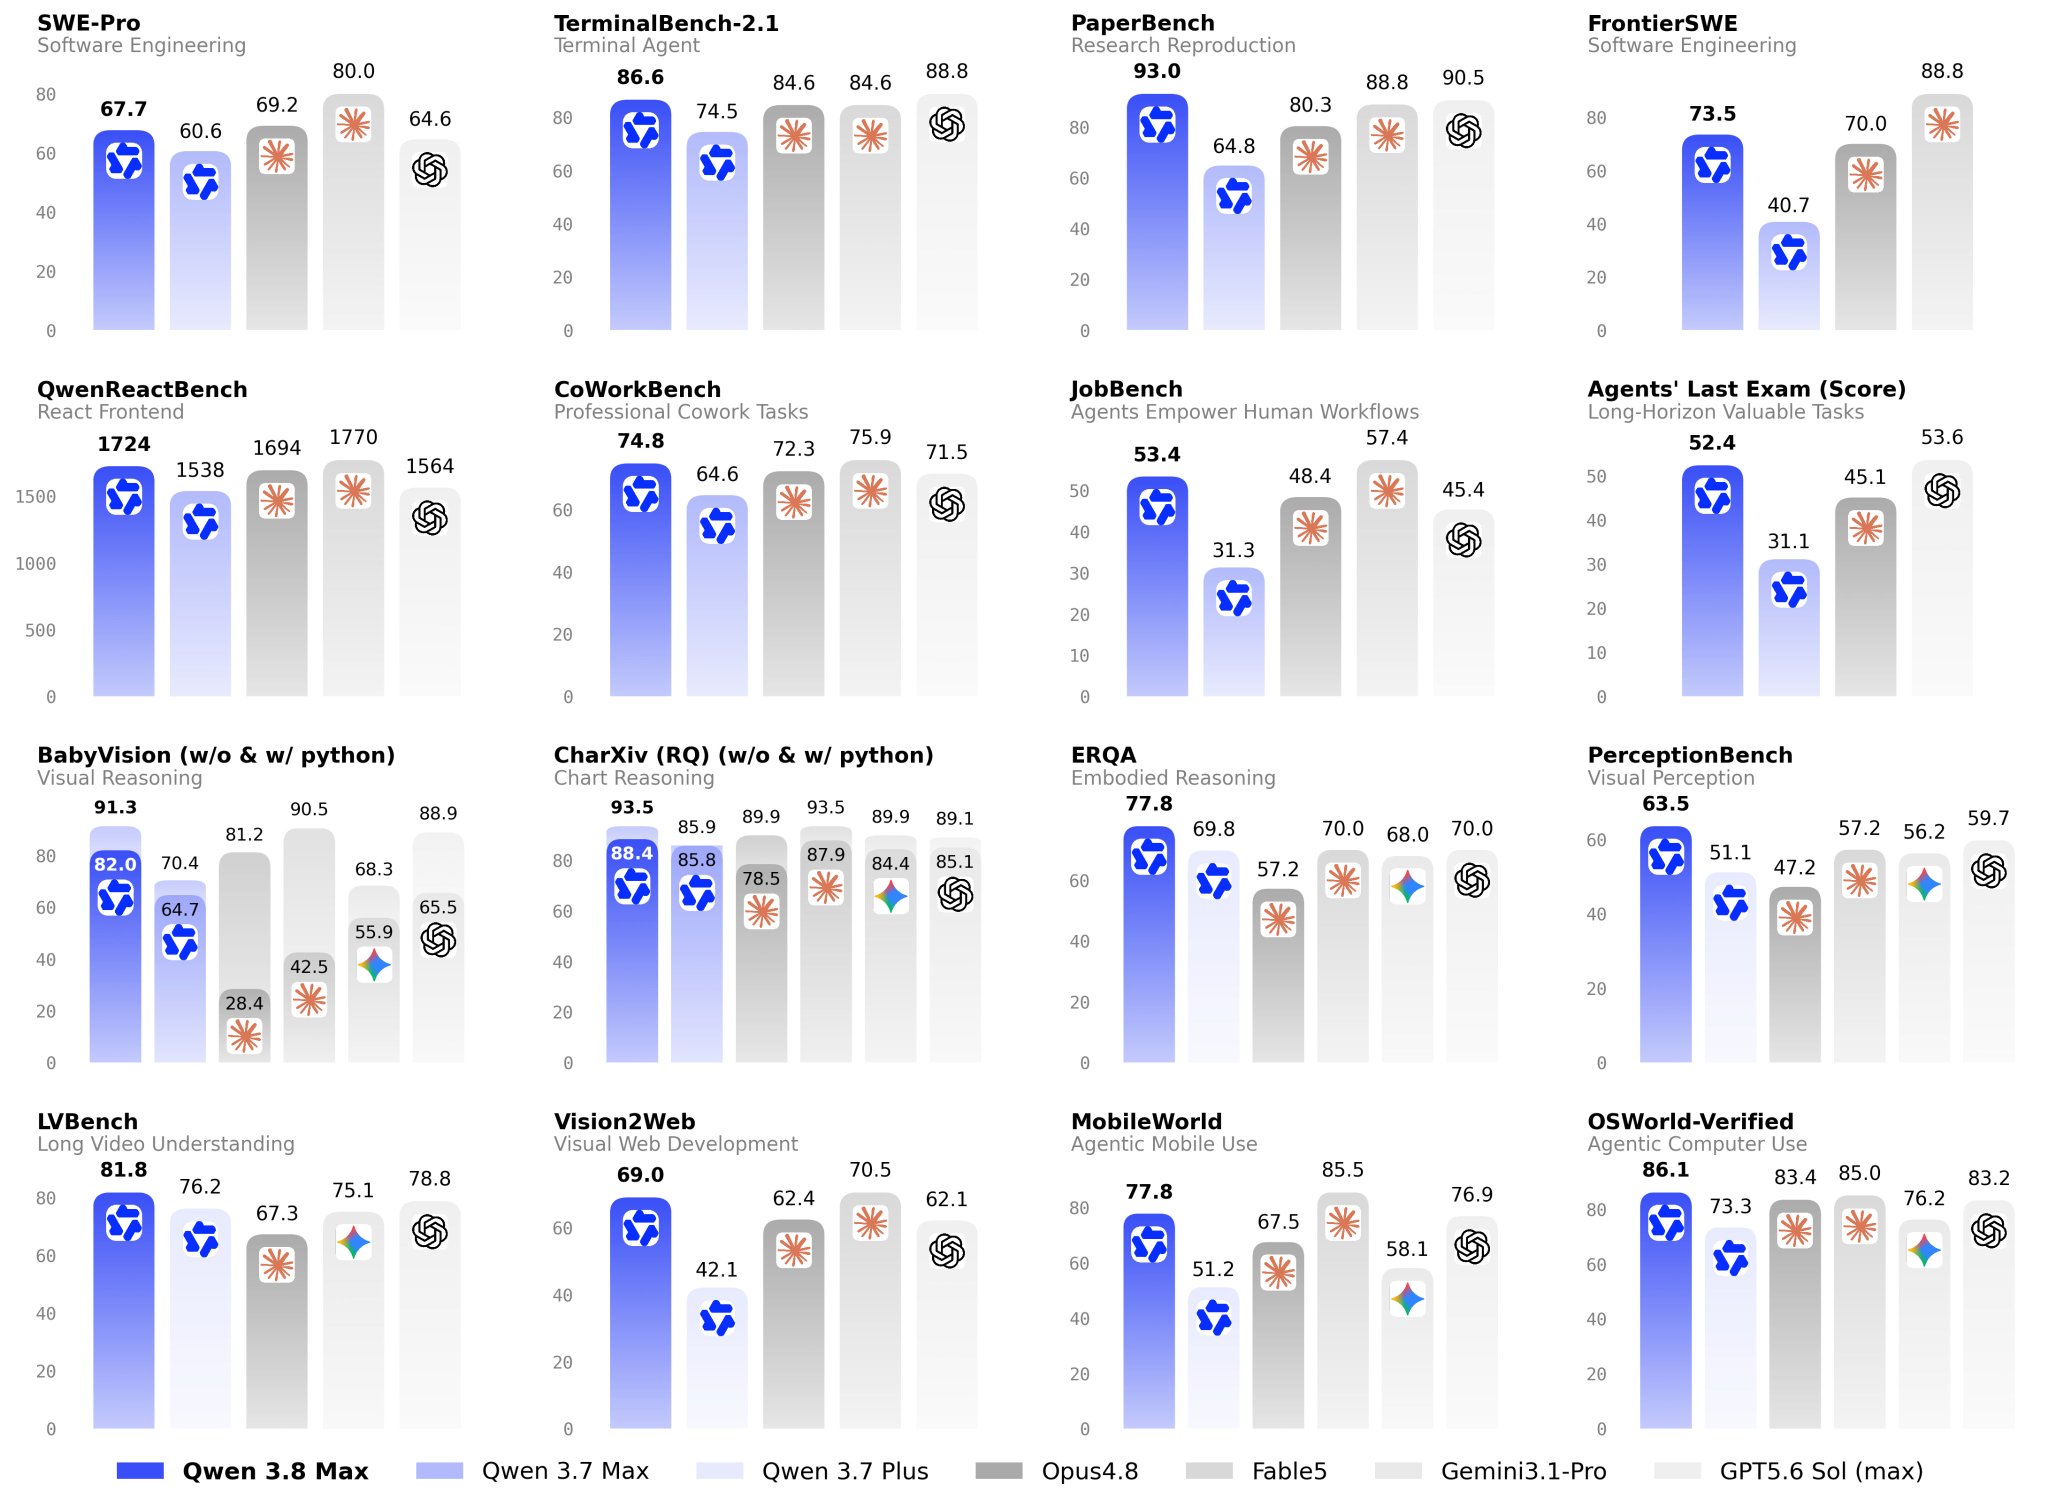
Alibaba Unveils Qwen3.8-Max: Its Largest and Most Capable Flagship Model to Date - Alibaba Cloud
Alibaba unveils Qwen3.8-Max, its most powerful model with 2.4 trillion parameters, excelling in coding, research, and visual intelligence.
Underdog Saluki 27B
Qwen3.8-27B in a 7.89 GB file that loads in stock llama.cpp, and how it compares with other 2-bit builds.

Qwen on Twitter / X
📢Meet Qwen3.8-Max — our most capable model to date. Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:- Autonomous coding: 10+ days of… pic.twitter.com/e3YFj2hqcT— Qwen (@Alibaba_Qwen) August 3, 2026
Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency
We’re releasing Gemma 4 quantization-aware training checkpoints, reducing memory requirements and improving on-device performance.
0xSero on Twitter / X
Are you compute poor? Do you want to run Qwen3.8-27B? Dude, if you have 8-16gb of vram or 16-24gb of MacOS memory this is by far the smartest model you can runPrimML is doing something phenomenal, they've created a ternary version of Qwen3.8-27B9x smaller 98.2% as smart! https://t.co/rtmNCsIQbA— 0xSero (@0xSero) September 17, 2026
Eric on Twitter / X
Qwen3.5 27B is awesome (the entire family above 9B is impressive). You can now try it directly in your browser at SOTA speeds with whatever GPU you have: https://t.co/avWxUd8vNLMy previous research in practice - The `Intel/Qwen3.5-27B-int4-AutoRound` is particularly good. https://t.co/QVSVNKM0Nk— Eric (@Ex0byt) March 21, 2026
Zhijian Liu on Twitter / X
🔥 DFlash x MLX is happening!Shoutout to @aryagm01 for the early work on this. We're building on the momentum. Native MLX support, more models (Qwen3.5), up to 4x faster. Lossless!👉 https://t.co/9CtLKDptNI pic.twitter.com/pMdaCH4oKi— Zhijian Liu (@zhijianliu_) April 15, 2026

Better bitmap performance with Roaring bitmaps
Bitmap indexes are commonly used in databases and search engines. By exploiting bit-level parallelism, they can significantly accelerate queries. However, they can use much memory, and thus we might prefer compressed bitmap indexes. Following Oracle's lead, bitmaps are often compressed using run-length encoding (RLE). Building on prior work, we introduce the Roaring compressed bitmap format: it uses packed arrays for compression instead of RLE. We compare it to two high-performance RLE-based bitmap encoding techniques: WAH (Word Aligned Hybrid compression scheme) and Concise (Compressed `n' Composable Integer Set). On synthetic and real data, we find that Roaring bitmaps (1) often compress significantly better (e.g., 2 times) and (2) are faster than the compressed alternatives (up to 900 times faster for intersections). Our results challenge the view that RLE-based bitmap compression is best.

Semantic Compression
An introduction to the idea that code should be approached with a mindset towards compressing it semantically, rather than orienting it around objects.
Artur Chakhvadze on Twitter / X
We are releasing our first quantized checkpoints for the Qwen3.5 series of models, co-designed jointly with our inference engine to achieve maximum possible performance on Apple hardwareStarting from 0.8B, 2B and 4B modelshttps://t.co/2R8BdhAfzv— Artur Chakhvadze (@norpadon) June 8, 2026
Qualcomm made a Pi 5 killer. Good luck getting one.