Part 4: Brief history of Apple ML Stack
By Mirai Labs, frontier on-device AI lab. Building the models, inference runtime, and quantization stack from the device constraint up.
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
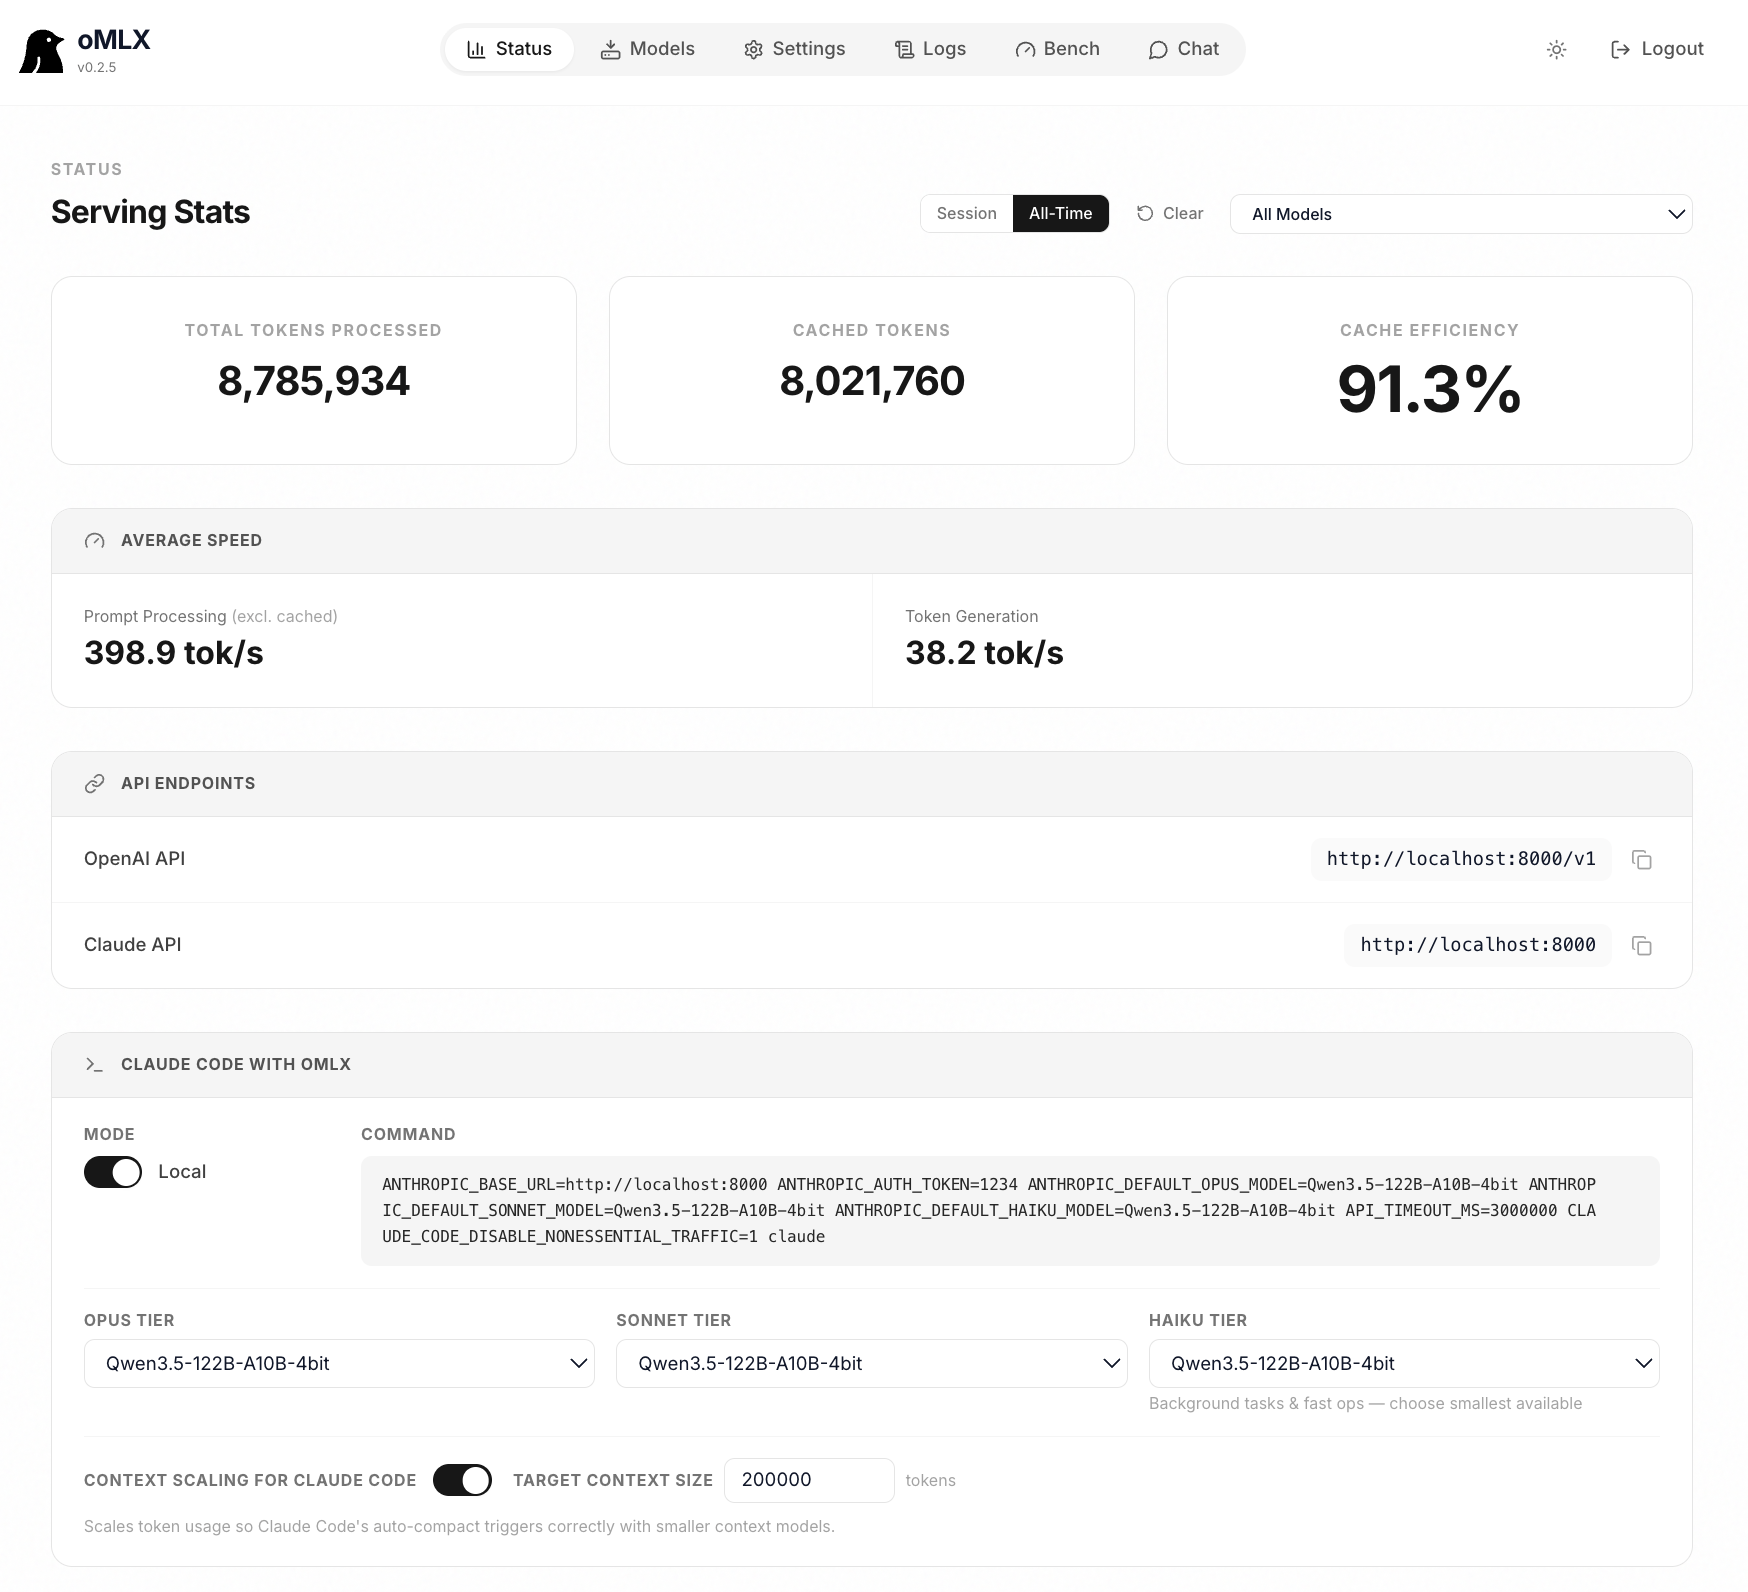
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
videlalvaro/ane-book
Production LLM inference on the Apple Neural Engine — a practitioner's guide, complete with converters, Swift runtimes, and validated model manifests
Ollama is now powered by MLX on Apple Silicon in preview· Ollama Blog
Today, we're previewing the fastest way to run Ollama on Apple silicon, powered by MLX, Apple's machine learning framework.
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
Making Apple Neural Engine work in a custom inference stack
Apple Neural Engine always looked appealing on paper, but using it inside a custom runtime was harder. In 1.20260410.1, we made ANE practical for 8-bit S models by using CoreML only as an accelerator.
Doriandarko/MLX-GRPO
A pure MLX-based training pipeline for fine-tuning LLMs using GRPO on Apple Silicon.
Darkbloom — Cost-Efficient Private AI Inference on Verified Macs
Encrypted inference on hardware-verified Apple Silicon. Comparable model performance, operator-blind privacy, and about 50% lower cost.
Darkbloom — Cost-Efficient Private AI Inference on Verified Macs
Encrypted inference on hardware-verified Apple Silicon. Comparable model performance, operator-blind privacy, and about 50% lower cost.
Darkbloom — Cost-Efficient Private AI Inference on Verified Macs
Encrypted inference on hardware-verified Apple Silicon. Comparable model performance, operator-blind privacy, and about 50% lower cost.
Minions: A Dynamic and Distributed Virtual GPU Cloud Built on Idle Apple Silicon Devices
The increasing demand for GPU-accelerated machine learning inference has exposed limitations in centralized GPU infrastructures, including…
Geek Lite on Twitter / X
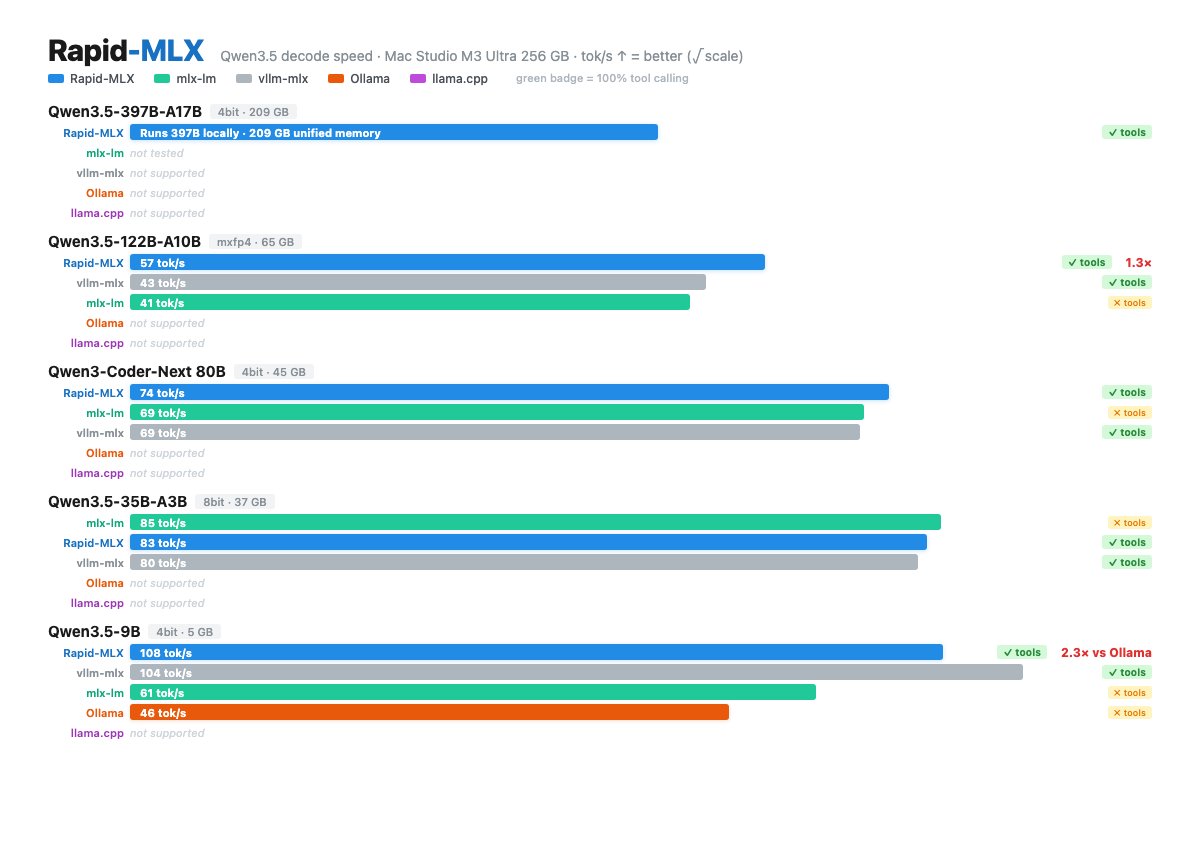
在 Apple Silicon Mac 上本地运行 LLM 推理服务,提供比 Ollama 和 llama.cpp 更快的 OpenAI 兼容 API,同时原生支持工具调用和提示缓存。https://t.co/IXet9GW7x0Rapid-MLX 用 Apple 自家的 MLX 框架做推理,搭了个 FastAPI 服务跑 OpenAI 兼容 API。在 Apple Silicon 上比 Ollama 快 2-4 倍,靠… pic.twitter.com/d9QUbAWJSZ— Geek Lite (@QingQ77) May 3, 2026