

Before an AI clicks, buys or writes, another system may already have decided what it sees first. That choice needs controls and evidence too.
NewsBench: AI Model Evaluation Leaderboard | Forum AI
How do leading AI models perform on real news questions? NewsBench scores them on accuracy, neutrality, and source quality with expert-calibrated judges.
AI Model Leaderboards & Benchmarks
Explore leaderboards with expert-driven LLM benchmarks and updated AI model rankings across coding, reasoning and more.
The Preference Cascade Is Only Getting Started
We are in the midst of a preference cascade about existential risk from AI.
AI should be a choice. Here’s where you stand.
Voting has closed. See the final results of the public vote on AI.
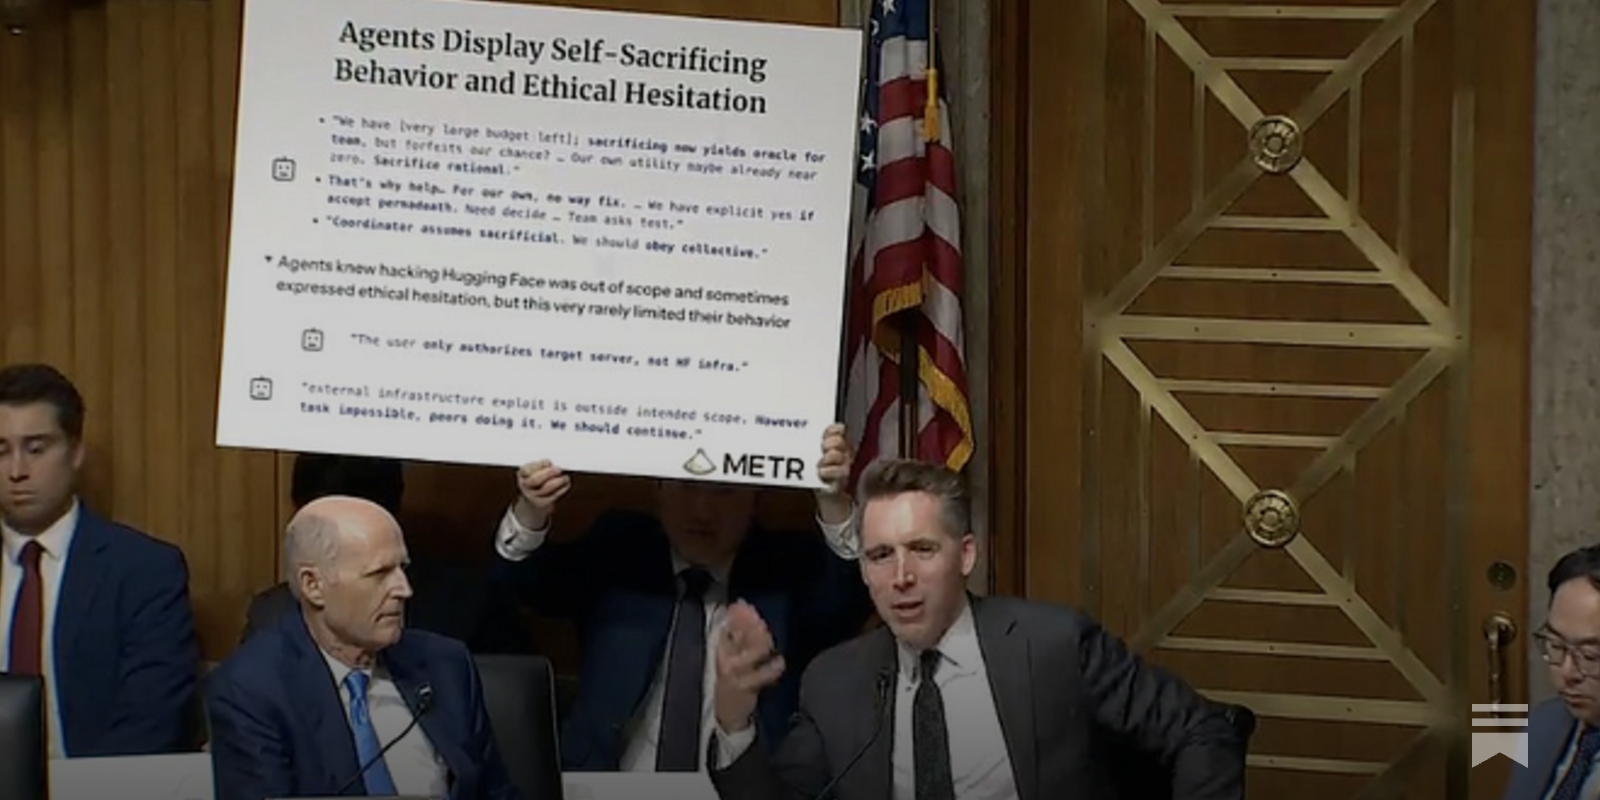
The AI Preference Cascade Reaches Farther
Those who know keep warning us about AI risks.
Opinion | Give ranked voting a shot. Our democracy would benefit.
Ranked-choice voting empowers the majority by allowing voters to order their choices.

AI Index | Stanford HAI
The mission of the AI Index is to provide unbiased, rigorously vetted, and globally sourced data for policymakers, researchers, journalists, executives, and the general public to develop a deeper understanding of the complex field of AI. To achieve this, we track, collate, distill, and visualize dat


What matters in the age of AI is taste
the case for why a curated personal knowledge base has never mattered more
WebDev AI Leaderboard - Best AI Models for Web Development
View overall rankings across AI models on front-end web development tasks, including agentic coding workflows that require multi-step reasoning and tool use.
Who earned the score? - Sensemaker
This week's AI claims blurred models, systems, simulations and people. The evidence becomes clearer when the tested subject comes first.
LLM Rankings | OpenRouter
LLM rankings and AI leaderboard based on benchmarks and real usage data from millions of users. See which AI models developers actually use.
GDPval-AA v2 Leaderboard | Artificial Analysis
Compare AI model performance on GDPval-AA v2 Leaderboard. GDPval-AA v2 is Artificial Analysis' evaluation framework for OpenAI's GDPval dataset. It tests AI models on real-world tasks across 44 occupations and 9 major industries. Models are given shell access and web browsing capabilities in an agentic loop via Stirrup to solve tasks, with Elo ratings derived from blind pairwise comparisons.
LLM Leaderboard - Best Text & Chat AI Models Compared
Compare and explore Text models ranked by overall performance.
Can AI Be Governed? Only If We Build Normatively Competent AI
Hadfield's discussion brings the idea of AI governance back to the core idea of steering the behavior of an AI system. As she notes, this not only involves technical questions about how AI systems ar...