

Friday’s big release was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen research lab. I’ve been looking forward to this one: 27B is an …
qwen3.5:27b
Qwen 3.5 is a family of open-source multimodal models that delivers exceptional utility and performance.
Qwen on Twitter / X
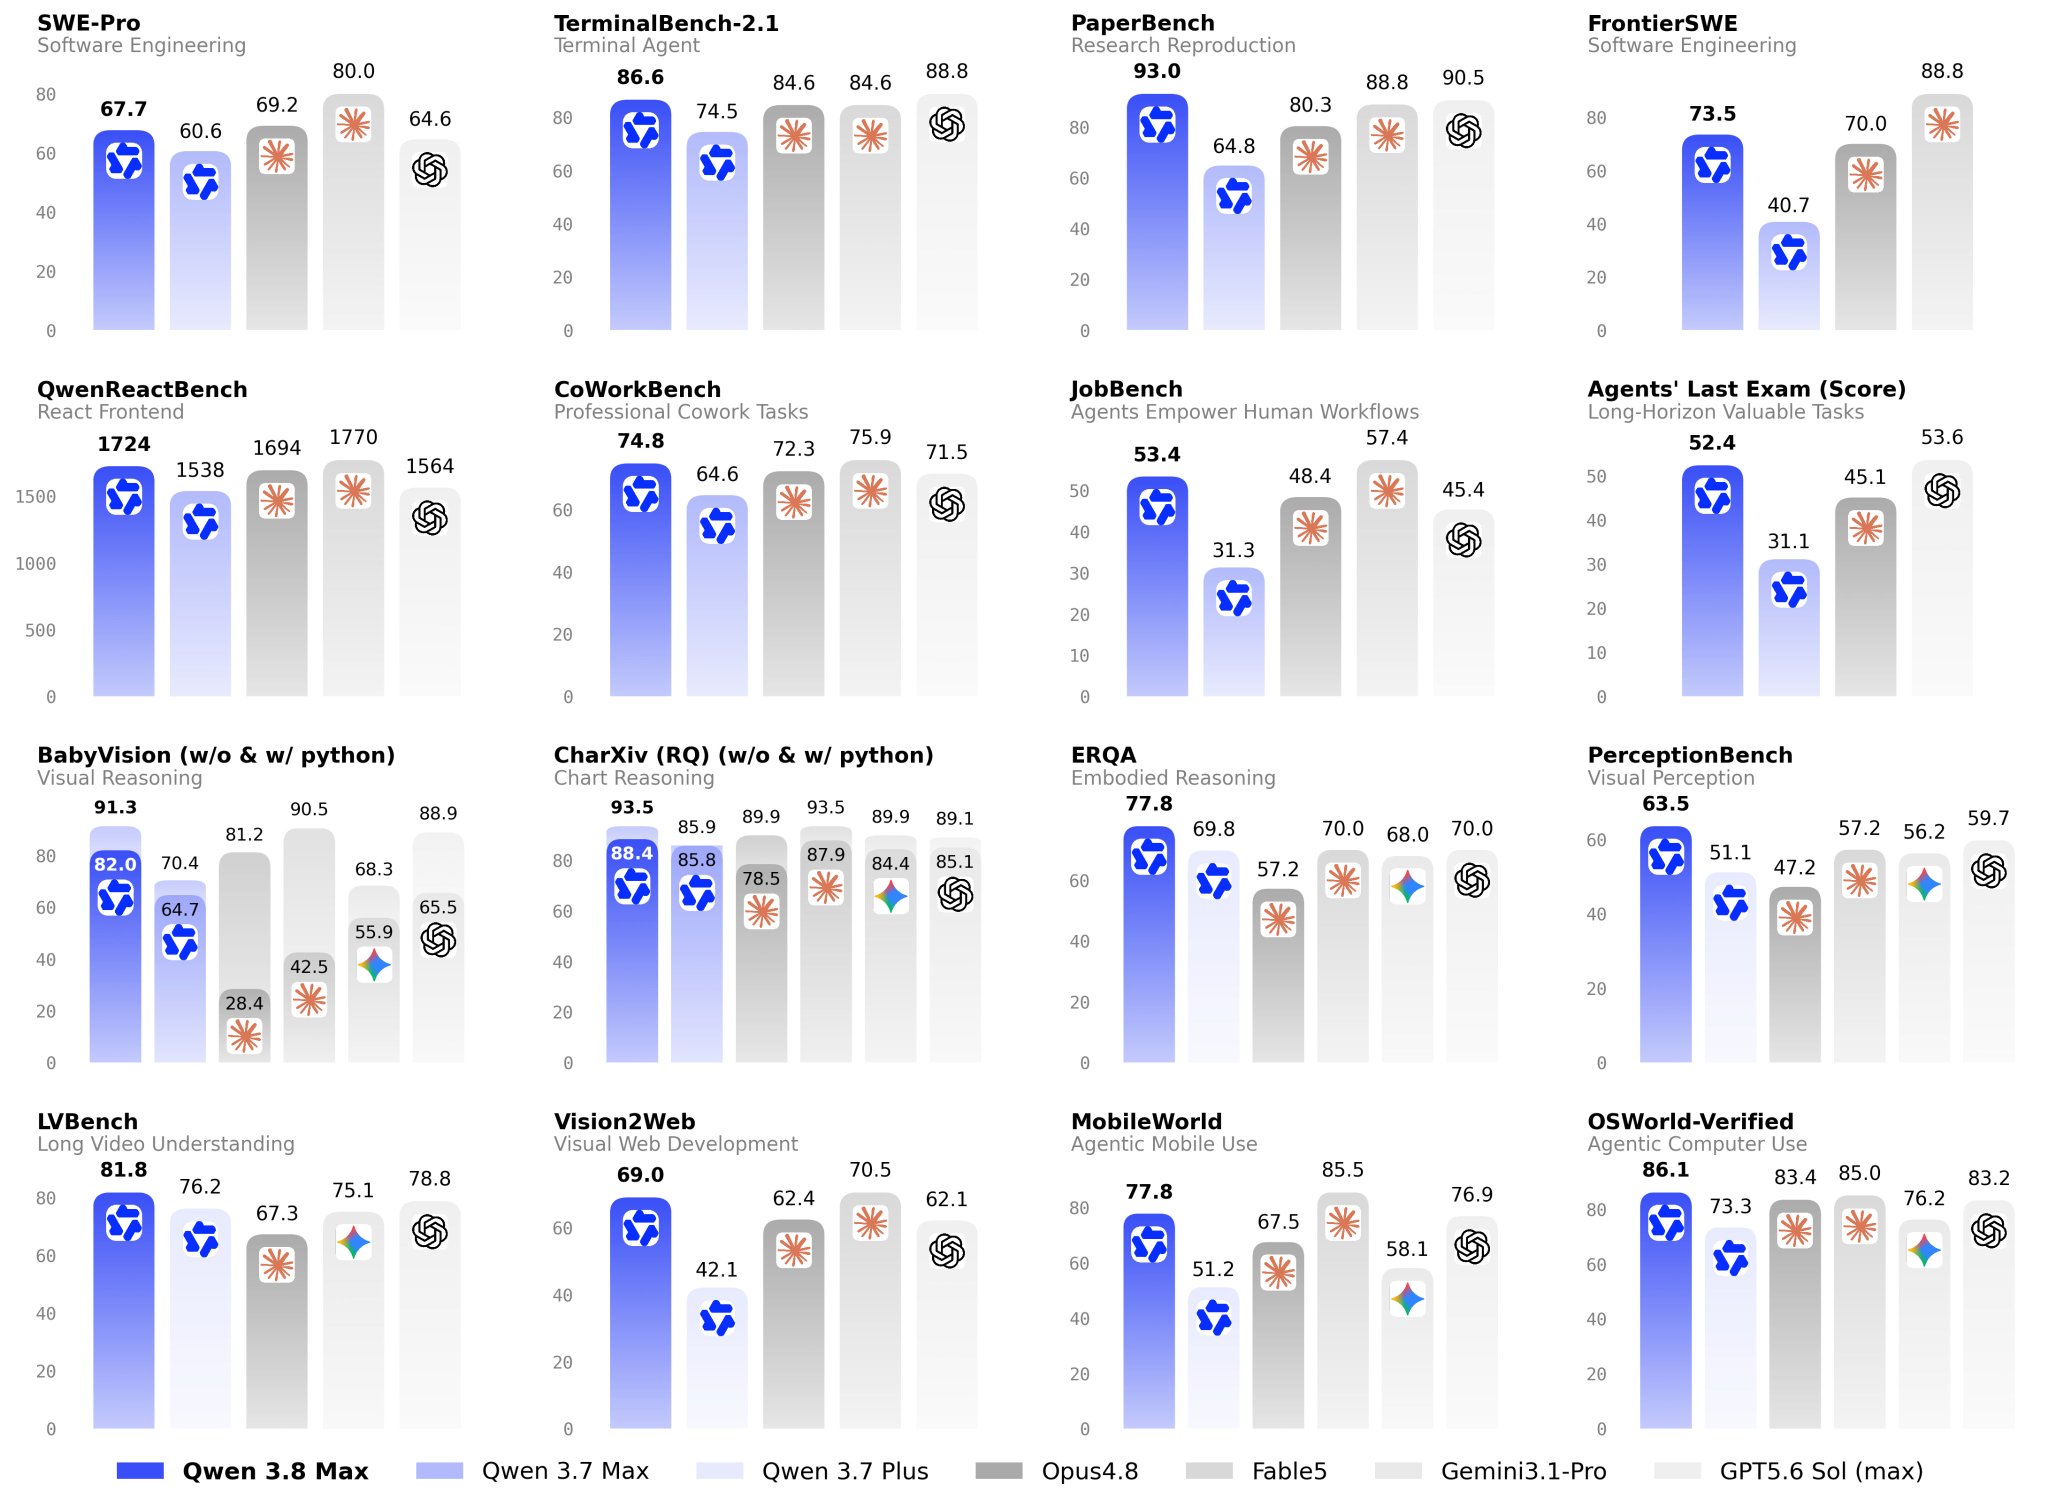
📢Meet Qwen3.8-Max — our most capable model to date. Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:- Autonomous coding: 10+ days of… pic.twitter.com/e3YFj2hqcT— Qwen (@Alibaba_Qwen) August 3, 2026
A 30B Qwen Model Walks Into a Raspberry Pi… and Runs in Real Time
ByteShape's device-optimized release of Qwen3-30B-A3B-Instruct-2507.

Alibaba Unveils Qwen3.8-Max: Its Largest and Most Capable Flagship Model to Date - Alibaba Cloud
Alibaba unveils Qwen3.8-Max, its most powerful model with 2.4 trillion parameters, excelling in coding, research, and visual intelligence.
Casper Hansen on Twitter / X
Qwen3.5 Small models about to release!Qwen3.5 9B, 4B, 2B, 0.8B, or something in between is possible.- imagine 9B beating Qwen3-Next-80B- or 4B beating Qwen3-VL-30B in multimodal reasoningBuying a GPU is starting to have high return of intelligence on investment— Casper Hansen (@casper_hansen_) March 1, 2026
Something is afoot in the land of Qwen
I’m behind on writing about Qwen 3.5, a truly remarkable family of open weight models released by Alibaba’s Qwen team over the past few weeks. I’m hoping that the 3.5 …
Eric on Twitter / X
Qwen3.5 27B is awesome (the entire family above 9B is impressive). You can now try it directly in your browser at SOTA speeds with whatever GPU you have: https://t.co/avWxUd8vNLMy previous research in practice - The `Intel/Qwen3.5-27B-int4-AutoRound` is particularly good. https://t.co/QVSVNKM0Nk— Eric (@Ex0byt) March 21, 2026
Artur Chakhvadze on Twitter / X
We are releasing our first quantized checkpoints for the Qwen3.5 series of models, co-designed jointly with our inference engine to achieve maximum possible performance on Apple hardwareStarting from 0.8B, 2B and 4B modelshttps://t.co/2R8BdhAfzv— Artur Chakhvadze (@norpadon) June 8, 2026
Qwen on Twitter / X
Qwen3.8 is launching and going open-weight soon!🌐With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.You don't have to wait to… pic.twitter.com/JS3ID73IYS— Qwen (@Alibaba_Qwen) July 19, 2026

Georgi Gerganov on Twitter / X
I think the consensus is that Qwen3.5 is a step change so atm I would recommend explore that, given that it covers a range of sizes suitable for all devices.Note that the main issues that people currently unknowingly face with local models mostly revolve around the harness and…— Georgi Gerganov (@ggerganov) March 30, 2026
Qwen3.6 27B — Qwen/Qwen3.6-27B rental
Free · 32 concurrent · hosted by selimaktas on LocalMaxxing.
Awni Hannun on Twitter / X
According to benchmarks Qwen3.5 4B is as good as GPT 4o.GPT 4o came out ~2 years ago (May 2024).Qwen 3.5 4B runs easily on modern mobile devices.So the gap between frontier intelligence in a datacenter and running a model of equal quality on your iPhone could be 2-3 years.…— Awni Hannun (@awnihannun) March 6, 2026
Qwen
Qwen is a family of large language models developed by Alibaba Cloud. Many Qwen models are distributed under the free and open-source Apache 2.0 license, the source-available Qwen License, or the non-commercial Qwen Research License; other proprietary Qwen models are served through Alibaba Cloud.

jaredpalmer/kev
tiny Jev-like family of decision models built on top of Qwen3.5 you can train and run on your own
Underdog Saluki 27B
Qwen3.8-27B in a 7.89 GB file that loads in stock llama.cpp, and how it compares with other 2-bit builds.
