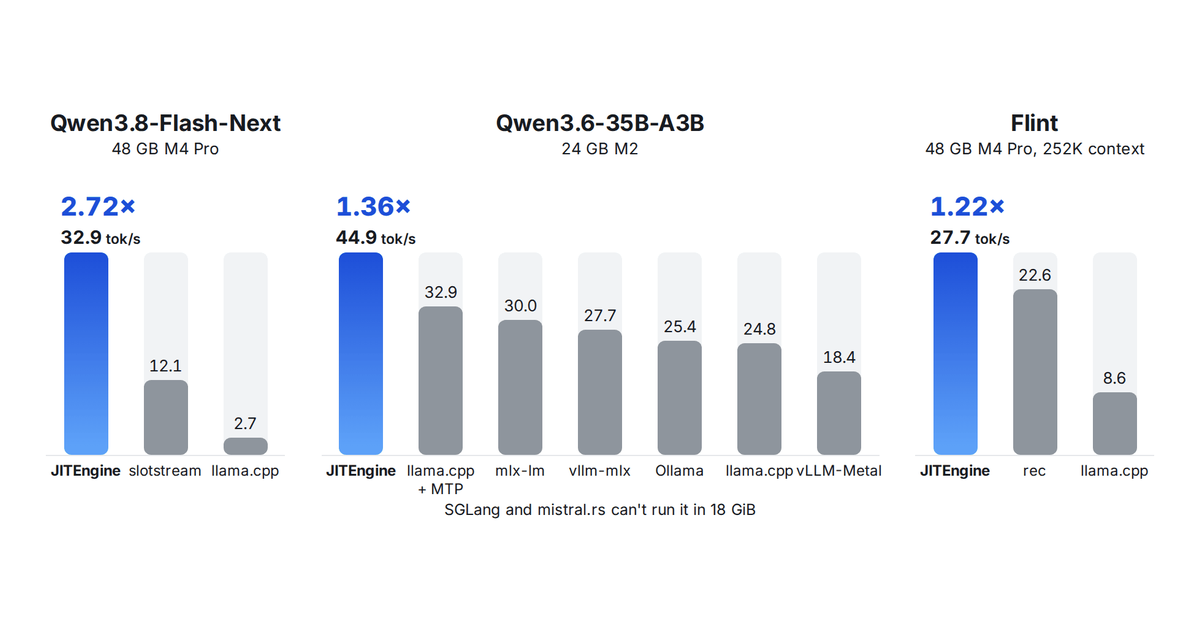
Six LLM serving engines for Apple silicon, built by coding agents with SkySynth. Up to 2.72x faster than the fastest other server we measured on the same Mac.
JITEngine: LLM serving, synthesized for your Mac
LLM serving engines synthesized for your Mac, up to 2.7× as fast as the best other server we measured on the same Mac. Pick your Mac and get its commands, with the speeds we measured.
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
ModelScope on Twitter / X
🤯 400 Token/S on a MacBook? Yes, you read that right!Shaohong Chen just fine-tuned the Qwen3-0.6B LLM in under 2 minutes using Apple's MLX framework. This is how you turn your MacBook into a serious LLM development rig. A step-by-step guide and performance metrics inside! 🧵… pic.twitter.com/31Cmycy8Mh— ModelScope (@ModelScope2022) October 13, 2025
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

jundot/omlx
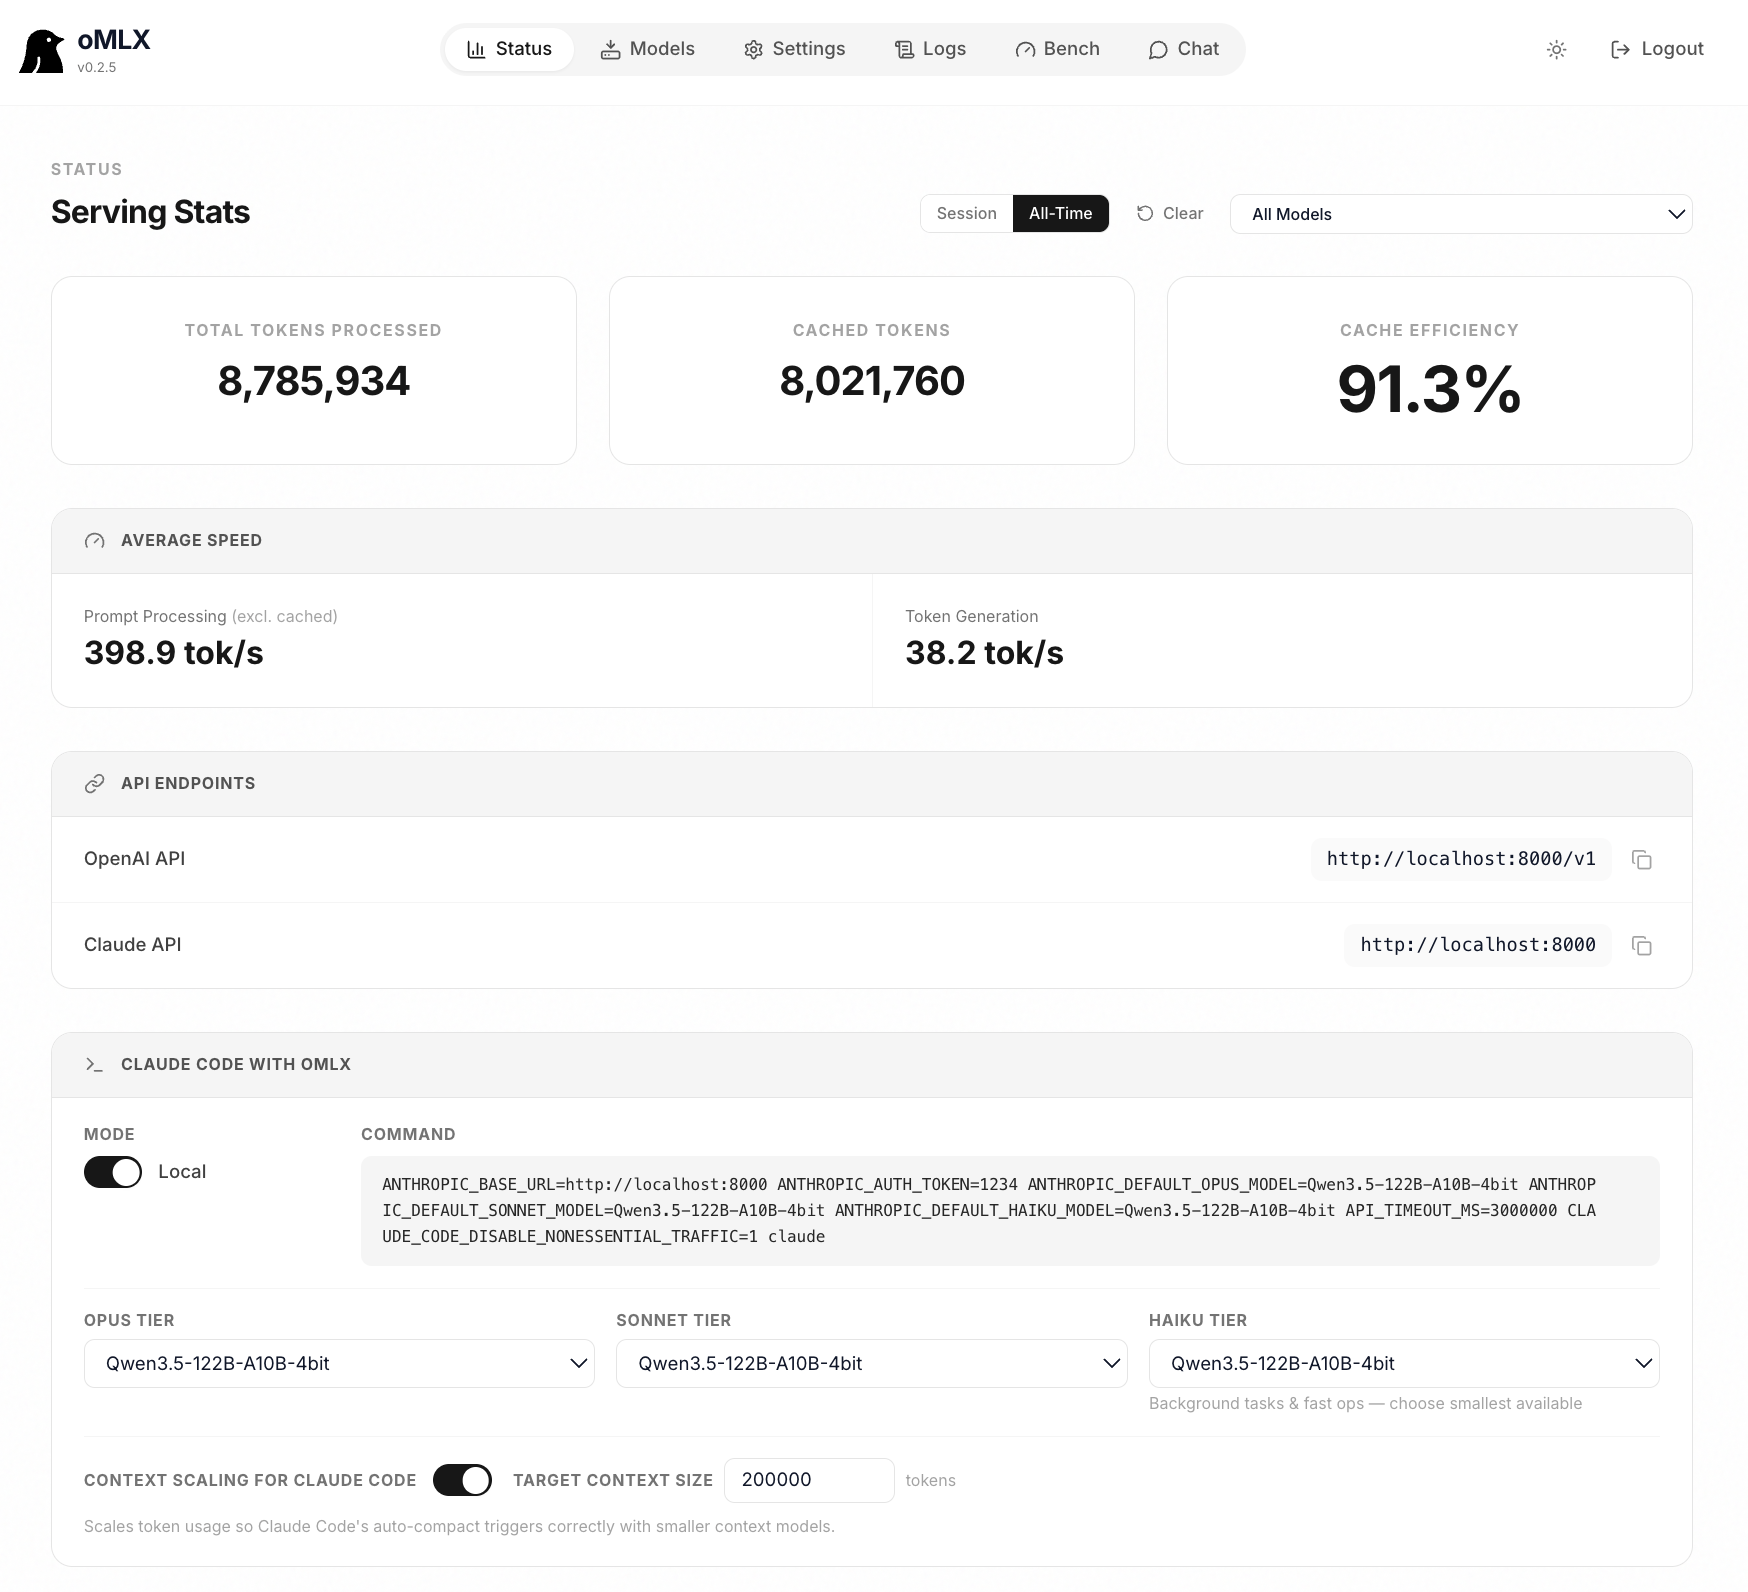
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
mzau/broke-cluster
A Poor Man's Apple Silicon LLM Cluster — tuned for MLX, scalable without shame.
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
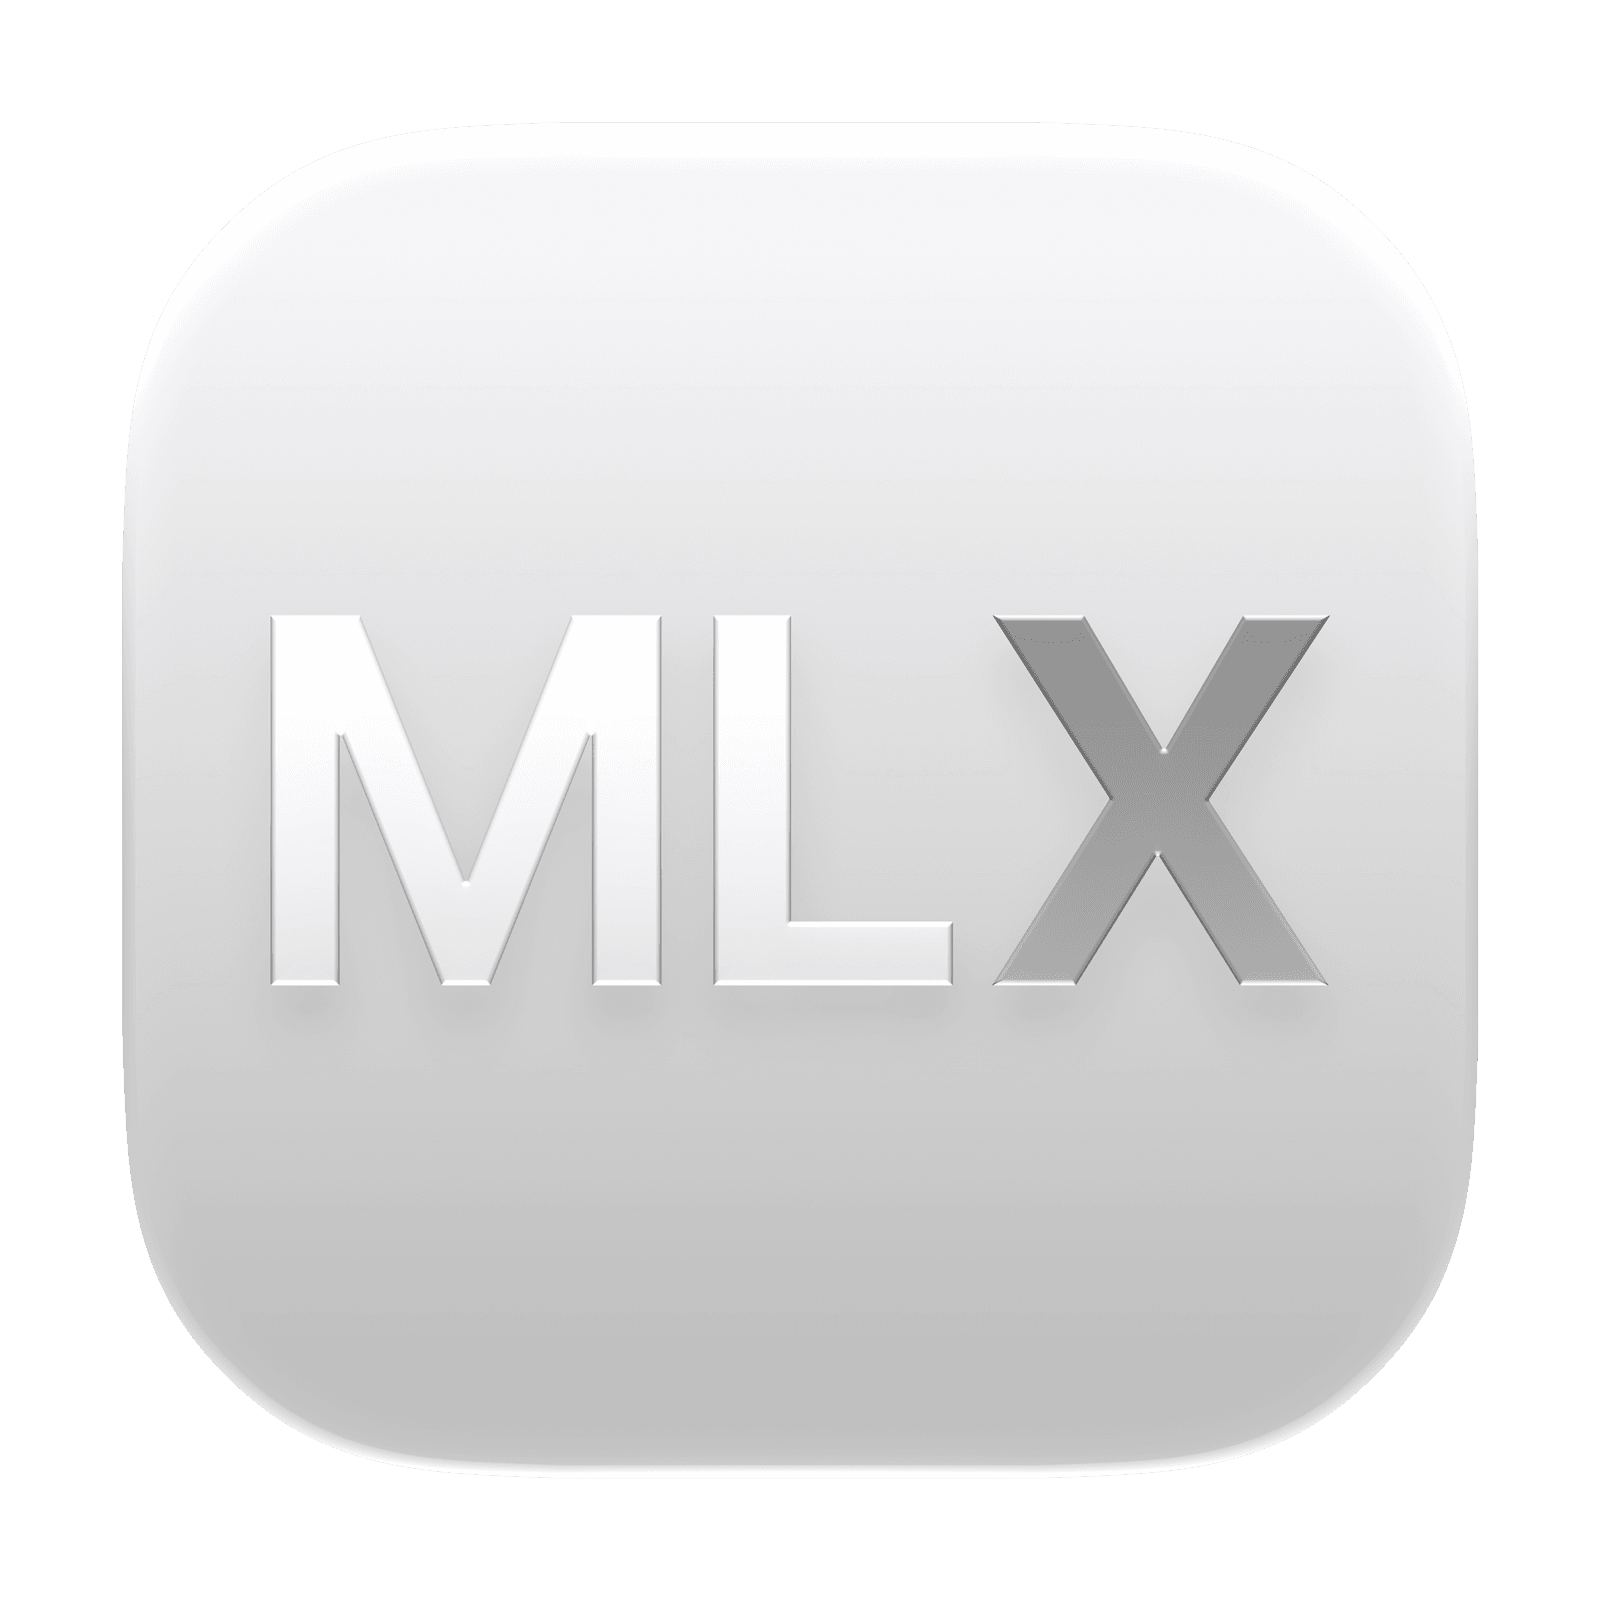
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
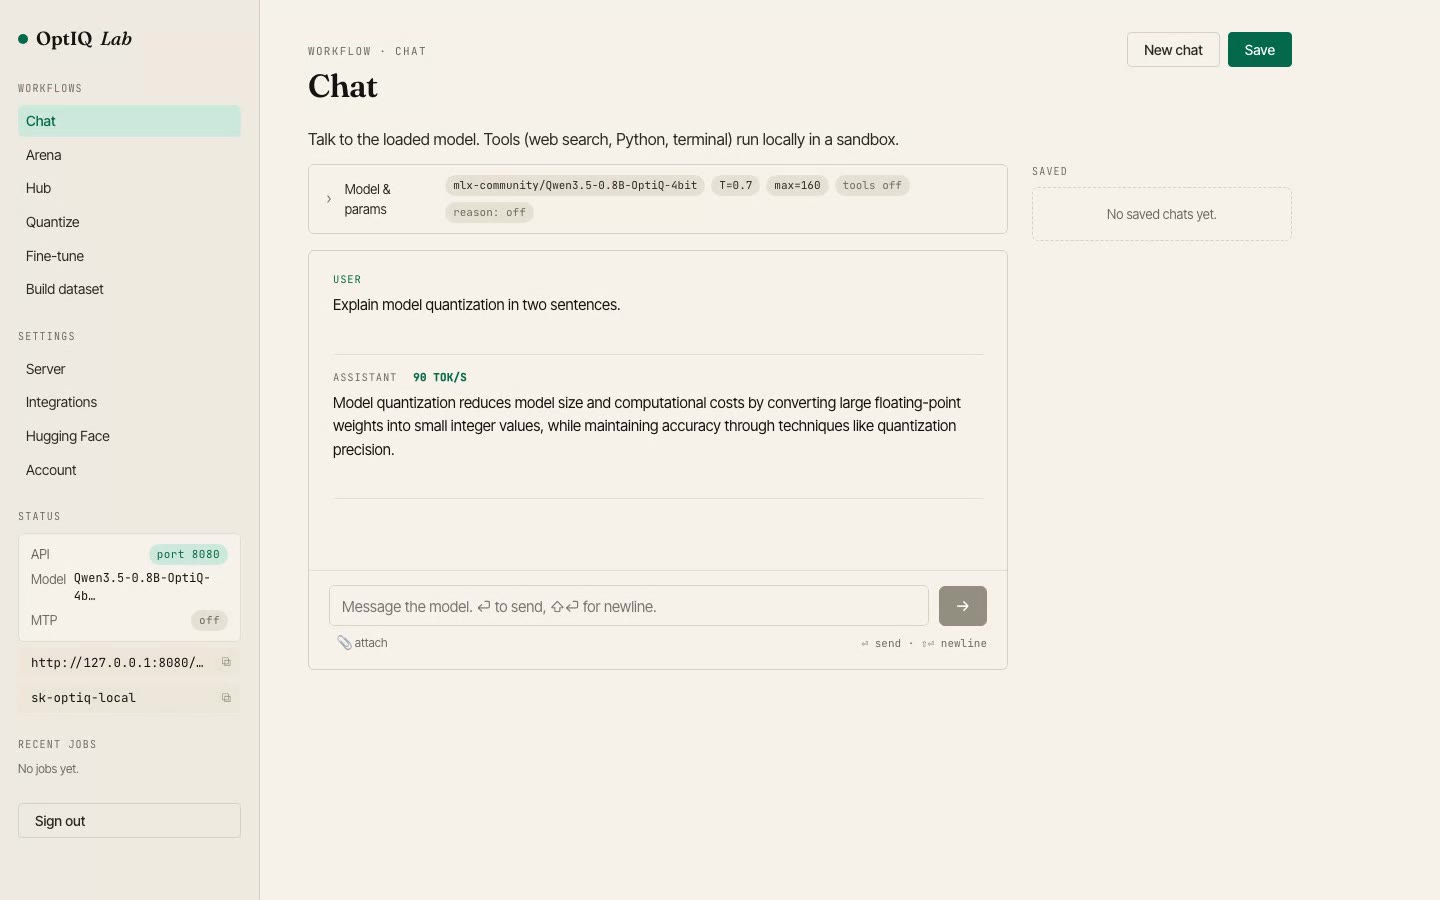
M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents
For the past few days, I’ve been testing the (currently) top-of-the-line M5 Ultra Mac Studio with 256 GB of RAM. I’ll cut to the chase: the M5 Ultra Mac Studio is a dream machine for local AI agents. This computer makes it possible to run personal assistants powered by local models with great performance and
Rohan Paul on Twitter / X
👨🔧 Github: Native, Apple Silicon–only local LLM server. Similar to Ollama, but built on Apple's MLX- OpenAI API compatible, - Ollama‑compatible- OpenAI‑style tools + tool_choice, with tool_calls parsing and streaming deltasgithub. com/dinoki-ai/osaurus pic.twitter.com/G0NbWnEJcQ— Rohan Paul (@rohanpaul_ai) September 3, 2025

Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
Mac at any scale | Namespace
What it takes to run Macs in a datacenter: custom MacBook racks, virtualizing macOS with Apple's Virtualization framework, and building and distributing huge VM images across the fleet.
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
The Potential of M6 and M5 Ultra for Local AI on macOS
Earlier today, Apple unveiled the new generation of Mac mini and Mac Studio, featuring the latest entries in the Apple silicon family of chips: the M6, available in the Mac mini, and the M5 Ultra, exclusive to the Mac Studio. You can read more details about the announcement and related specs in John’s overview. As