NVL72 puts all 72 GPUs in a rack on one NVLink fabric, but only rack-local jobs get the speedup. How SkyPilot keeps multi-node training and inference on NVLink with topology-aware placement, in-place recovery from GPU failures, and automatic defragmentation.
TheStage AI – Faster, Cheaper AI Inference
Accelerate models on NVIDIA & edge. Full guides for setup, optimization & deploy. ANNA, QLIP, Elastic Models, CLI & API. Built for AI teams & devs.

NVIDIA Shatters MoE AI Performance Records With a Massive 10x Leap on GB200 'Blackwell' NVL72 Servers, Fueled by Co-Design Breakthroughs
Scaling performance on MoE AI models is one of the industry constraints, but it appears that NVIDIA has managed to make a breakthrough.

ASUS Ascent GX10
Desktop AI supercomputer delivering up to 1 petaFLOP performance, powered by NVIDIA GB10 Grace Blackwell Superchip, supporting OpenClaw and Hermes Agent.
NVIDIA Personal AI Router (PAIR) — Route AI Inference Across Your Devices
NVIDIA PAIR beta connects your RTX, DGX Spark, and Mac as a private local AI cluster. No cloud required. Route inference across Ollama, LM Studio, and more.
InferenceMAX™: Open Source Inference Benchmarking
NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B
NVIDIA Live at CES with CEO Jensen Huang
TPUs vs. GPUs and why Google is positioned to win AI race in the long term | Hacker News
To quote The Next Platform: "An Ironwood cluster linked with Google’s absolutely unique optical circuit switch interconnect can bring to bear 9,216 Ironwood TPUs with a combined 1.77 PB of HBM memory... This makes a rackscale Nvidia system based on 144 “Blackwell” GPU chiplets with an aggregate of 20.7 TB of HBM memory look like a joke."
Mesh LLM: distributed AI computing on iroh
How Mesh LLM pools existing GPU resources across machines into a single OpenAI-compatible API, built on iroh.
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
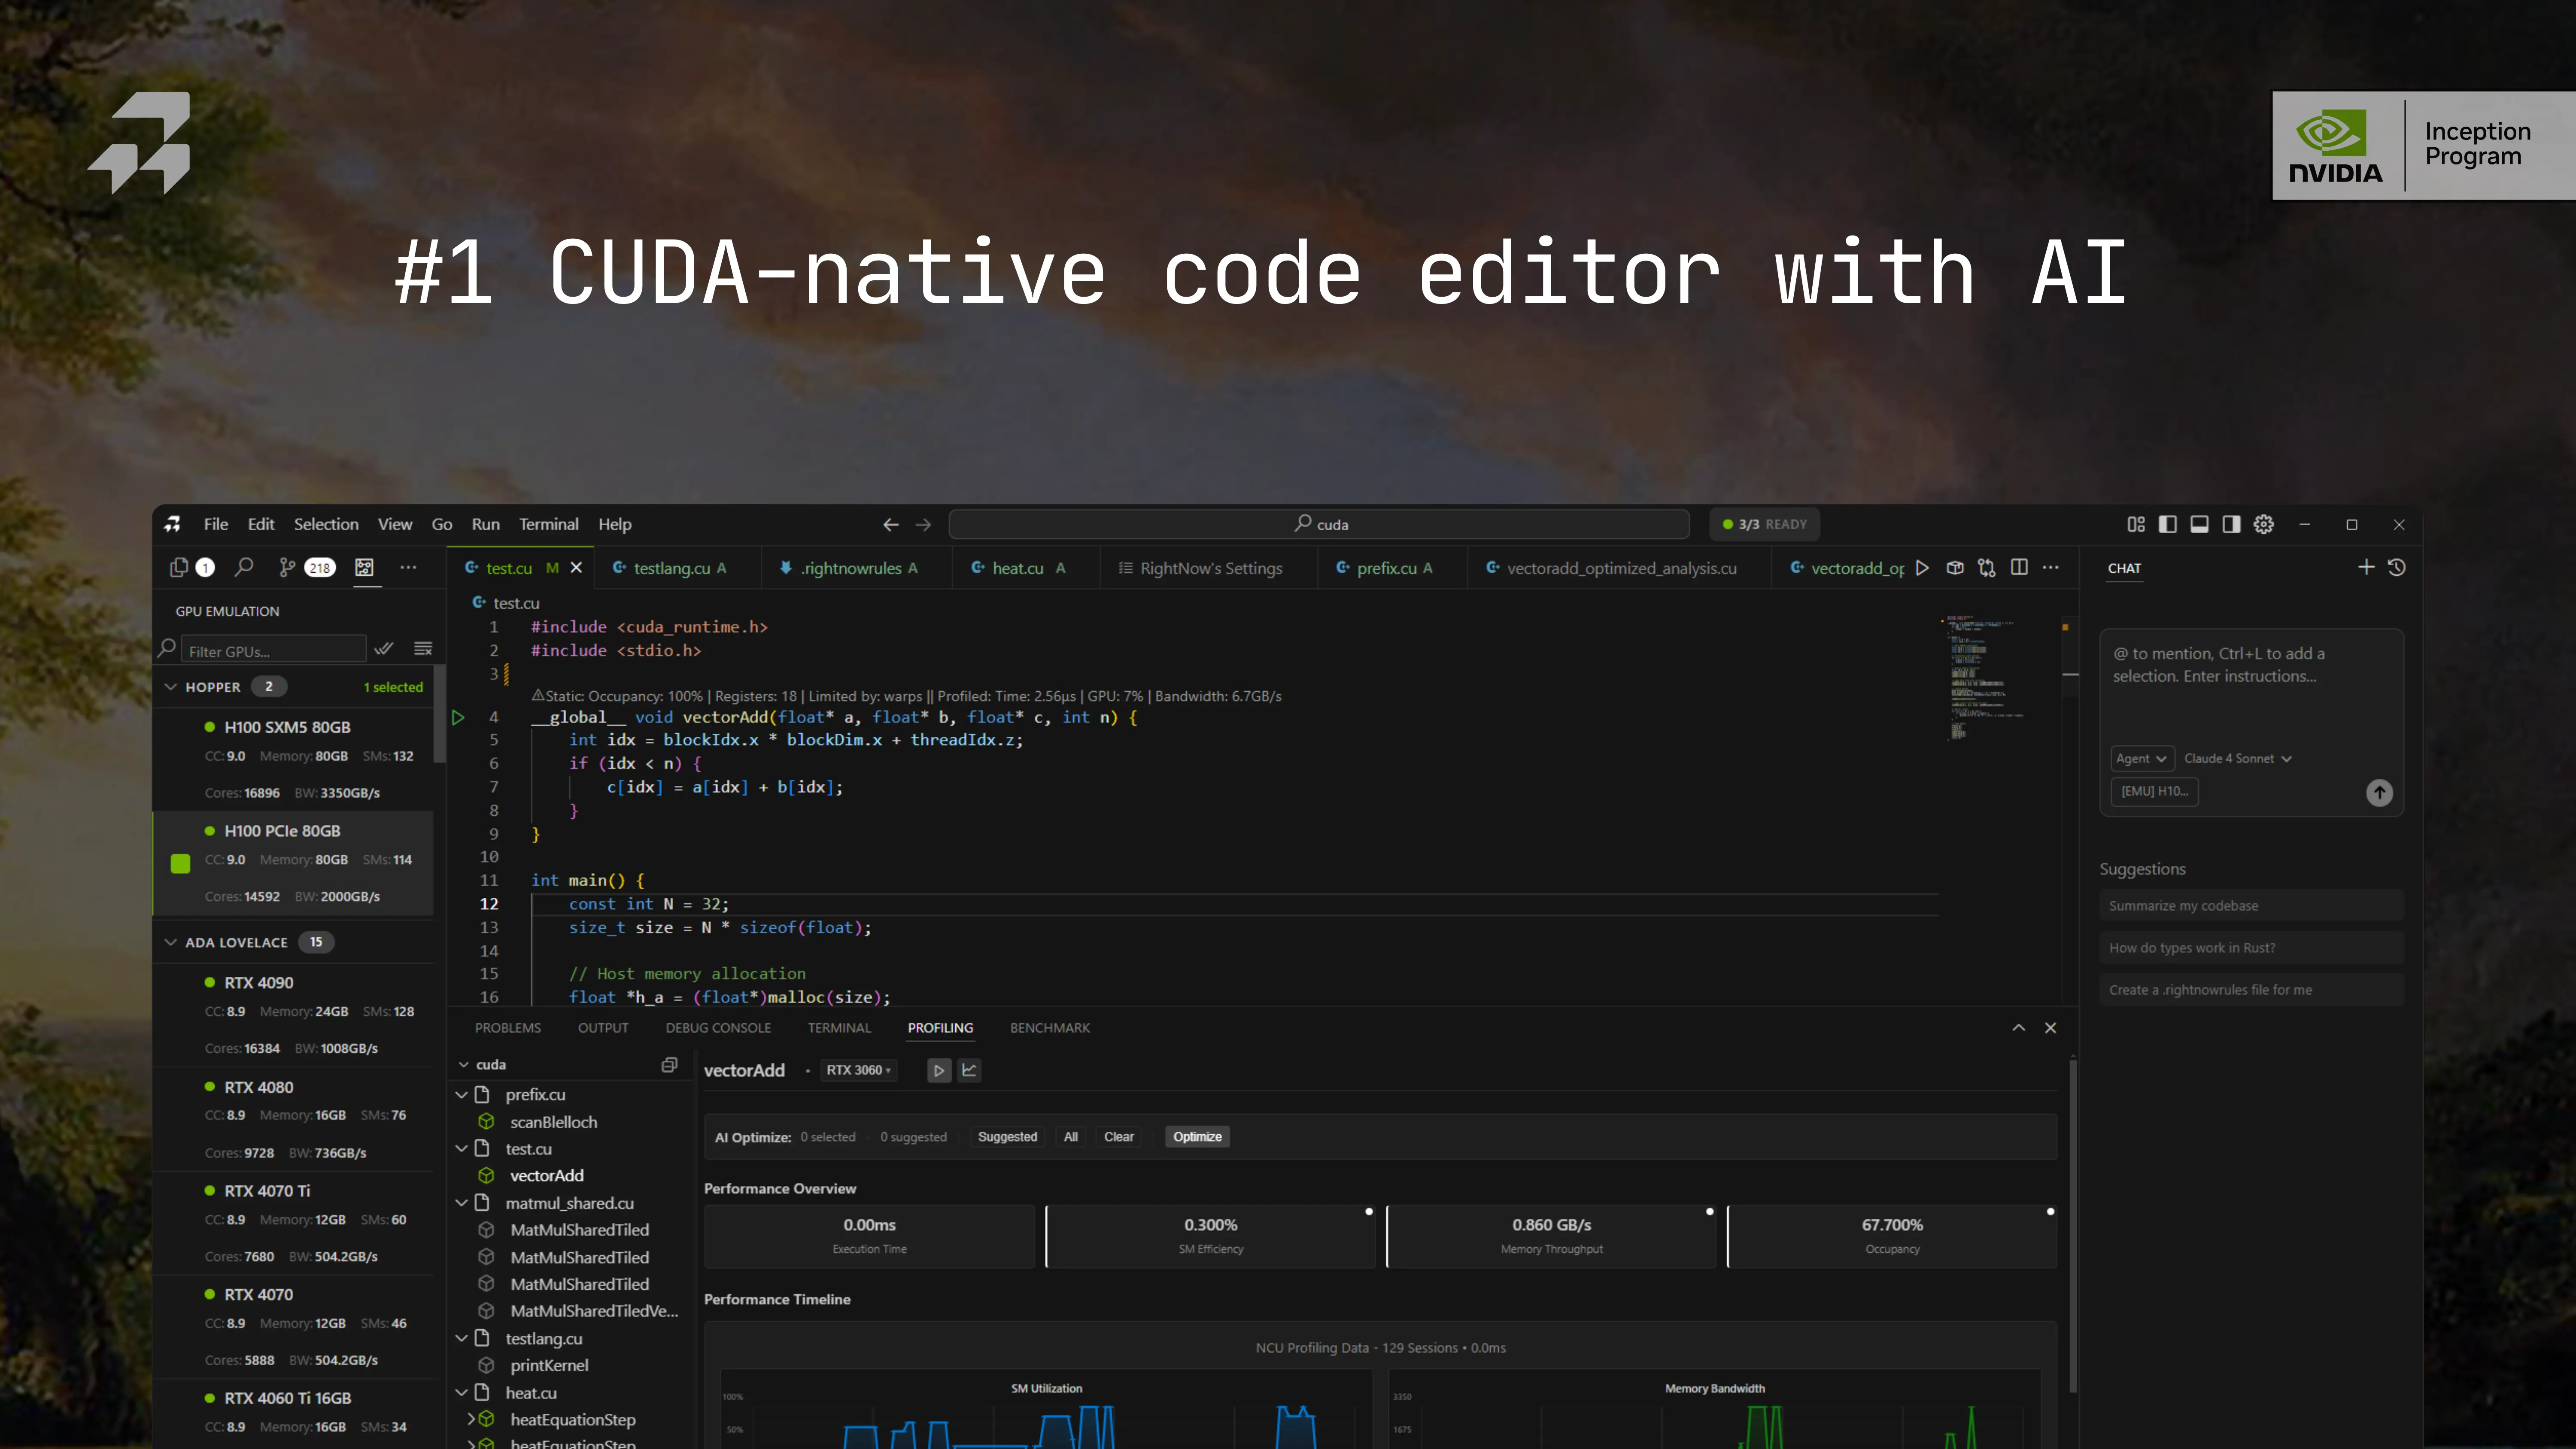
Open Source AI Inference Benchmark | InferenceX
Compare AI inference performance across GPUs and frameworks. Real benchmarks on NVIDIA GB200, B200, AMD MI355X, and more. Free, open-source, continuously updated.
Accelerating GPT-5.6 Sol Ultrafast with OpenAI
Cerebras powers OpenAI’s GPT-5.6 Sol Ultrafast in the OpenAI API, delivering frontier intelligence at real-time speeds for critical AI work.
Claude Meets Blackwell Ultra: Anthropic’s Models Now Run on NVIDIA GB300 in Azure
Now generally available in Microsoft Foundry, Claude on NVIDIA GB300 Blackwell Ultra gives Azure-native enterprises a new foundation for building autonomous and domain-specific AI agents.
NVIDIA DGX Station for Windows Puts a Trillion-Parameter AI Supercomputer on Every Enterprise Desk
News Summary: NVIDIA announces DGX Station for Windows — the world’s most powerful deskside AI supercomputer for developing and running agents on Windows — built on the NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip, coming in Q4 this year. DGX Station brings frontier AI agents to Windows — enabling enterprise developers, researchers, engineers, designers and data scientists to build and deploy AI across the workflows and applications their business runs on. DGX Station will support NVIDIA OpenShell on Windows, built on new Windows security and containment primitives. TAIPEI, Taiwan, June 01, 2026 (GLOBE NEWSWIRE) - NVIDIA GTC Taipei - NVIDIA today announced NVIDIA DGX Station™ for Windows , the world’s most powerful deskside AI supercomputer designed to build, run and connect always-on AI agents to Windows applications and workflows, capable of running frontier AI models of up to 1 trillion parameters locally. Historically, heavy-duty enterprise AI workloads —

The Universal Execution Layer for AI
Optimize any AI model on any engine, across all hardware. Dria’s topology-aware compiler and peer-to-peer runtime merge CPUs, GPUs, NPUs & chiplets into one fabric—maximising utilisation, cutting inference cost and ending vendor lock-in.

NVIDIA Levels Up Local AI Agents Across RTX PCs and DGX Spark
Announced at GTC Taipei at COMPUTEX, NVIDIA OpenShell brings secure agents to Windows with 2x inference performance on llama.cpp — plus, Adobe rebuilds its apps with performance and memory enhancements, and Blender adds NVIDIA DLSS 4.5 Ray Reconstruction for NVIDIA RTX Spark.