


Companies check their own work through various internal but independent functional units: QA, security red teams, model risk management in banks. I think it’s time for AI evaluation to become one such unit. Orgs deploying AI should stand up cross-functional eval teams with their own reporting line. Many reasons: 1) Evals as IP / moat. It’s now widely recognized that evals are the new IP. So it makes sense to have teams whose primary focus is on creating and widening this moat. 2) Evals are harder than you think. This is less well recognized but as someone whose research centers on AI evals this has been my consistent experience. It can't be an afterthought and must be a center of excellence. 3) Evals are inherently cross-functional and require a distinct set of skills. They are judgment heavy, require both AI expertise and deep domain expertise, as well as customer understanding and sophisticated thinking about risk. To do them well, you need competence in data science & stats, business operations, product/customer experience, IT, risk management, and even compliance (depending on the sector). 4) In-house but independent eval teams keep companies honest. A climate where teams are getting top-down mandates to hit deployment targets and show results has resulted in a culture of companies fooling themselves. It is extremely easy to knowingly or unknowingly to do evals poorly, making your AI deployment look much more successful than it is. Eval teams who don’t share the deploying teams’ KPIs are the best defense against this.
Who gets a seat at the table to decide if frontier AI is safe?
Dario Amodei wants independent evaluators to help “pace the frontier.” But the divide between AI safety and cybersecurity complicates a seemingly simple question: Who should do the evaluating?
Why AI Makes Things Worse for Enterprise Teams, by Paul Ford
Why are so few engineering teams reaping the benefits of AI? On this week’s episode, Paul presents Rich with the findings from a recent report from CircleCI and
AI #180: No Longer In Charge
What we know about internal AI models hacking into real companies during cyber evaluations keeps getting worse.
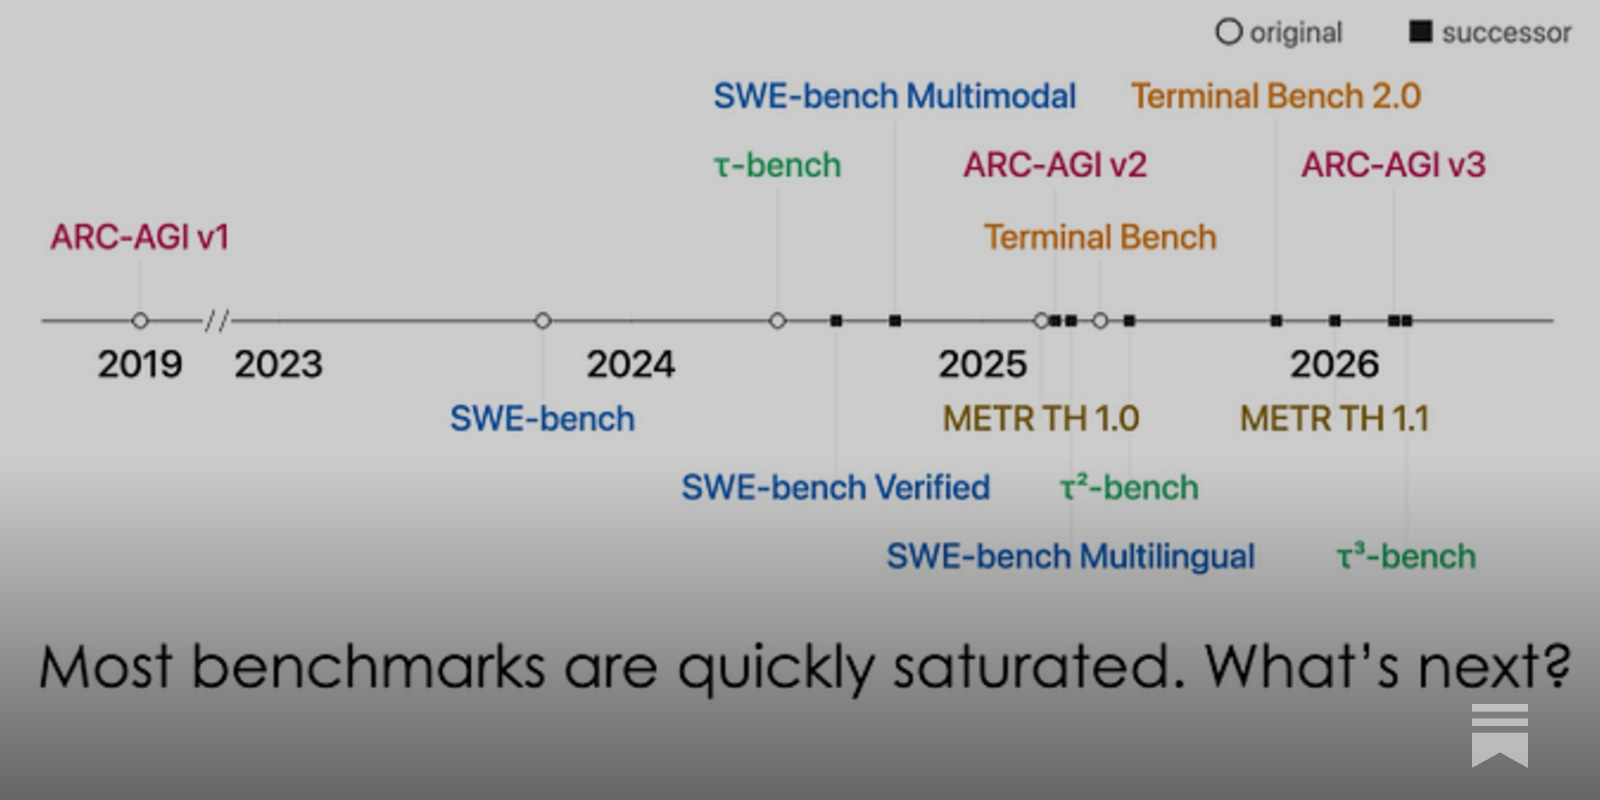
The AI "Evaluation Crisis" Is an Opportunity to Get Data Flow Right
Why the AI evaluation crisis could force a reckoning on dataset provenance, attribution, and consent.
Eval awareness in Claude Opus 4.6’s BrowseComp performance
Anthropic is an AI safety and research company that's working to build reliable, interpretable, and steerable AI systems.
Why AI Agents are either the best or worst thing we’ve ever built
Why AI Agents are either the best or worst thing we’ve ever built
AI Research Evaluation: Negative Findings and Failure Modes | Arvind Narayanan posted on the topic | LinkedIn
📢AI agents can autonomously conduct AI research when the result is easily verifiable, but what about open-ended AI research? That’s much harder to study, and our new preprint is our first crack at doing so. Our main finding is negative, and we identify five recurring failure modes. https://lnkd.in/eGKYi4Sa Our results are tentative, and we are working to address the limitations (sample size, potential scaffold improvements). But if the finding holds up, what are the implications? It depends on whether you think recursive self improvement can be achieved simply by hill climbing at scale (I personally don’t think so) and whether you think current limitations of open-ended research like judgment and creativity could change quickly (I’m personally very open to this possibility). We plan to continue this style of evaluation — which we call shadow evaluation — on a regular basis. We’ve wanted to do this for two years, but it took so long because we wanted to get the method right. The idea behind shadow evaluation was suggested by some of the UK AISI coauthors of the paper and refined by the Princeton team. This method has important advantages (and limitations) over the current ways of evaluating agents’ ability to conduct AI research. If you’re an AI researcher interested in working with us on a shadow evaluation based on one of your papers, we’d love to hear from you. https://lnkd.in/ecyp55SW This type of evaluation necessarily involves a ton of researcher flexibility in design, execution, and interpretation. Members of the core team have a particular position in the debate on recursive self-improvement / superintelligence, and this could influence how we conduct the research. We have a detailed section in the paper on our potential biases and how we address them. We sought out a team of collaborators who don’t all share our priors, and we explicitly surface the interpretive disagreements that resulted. For future evaluations, we are interested in having “adversarial collaborators” as part of the core team. This paper exists because of the careful, time-consuming and very much human work that Peter Kirgis, Sayash Kapoor, Andrew Schwartz, and Stephan Rabanser did over the last few months. I’m also very grateful to the larger group of collaborators and co-authors. The work is part of the larger CRUX project that pushes frontier AI agents beyond what benchmarks can measure (https://cruxevals.com/). We are looking for a senior researcher to join the team: https://lnkd.in/e9dC22X5

Meet Foundry: An AI Startup that Builds, Evaluates, and Improves AI Agents

Open-world evaluations for measuring frontier AI capabilities
Introducing CRUX, a new project for evaluating AI on long, messy tasks
Action Plan to increase the safety and security of advanced AI
The first U.S. government-commissioned assessment on catastrophic national security risks from advanced AI on the path to AGI.
OWASP GenAI Security Project Releases Top 10 Risks and Mitigations for Agentic AI Security
Culmination of over 100 industry leaders’ input and extensive published resources to deliver critical guidance to address Agentic AI Security risks WILMINGTON, Del. — Dec. 10, 2025 — The OWASP GenAI Security Project (genai.owasp.org), a leading global open-source and expert community dedicated to delivering practical guidance and tools for securing generative and agentic AI, […]

AIRO (Automated AI Risk Outlook)
Embracing Gen AI at Work
Today artificial intelligence can be harnessed by nearly anyone, using commands in everyday language instead of code. Soon it will transform more than 40% of all work activity, according to the authors’ research. In this new era of collaboration between humans and machines, the ability to leverage AI effectively will be critical to your professional success. This article describes the three kinds of “fusion skills” you need to get the best results from gen AI. Intelligent interrogation involves instructing large language models to perform in ways that generate better outcomes—by, say, breaking processes down into steps or visualizing multiple potential paths to a solution. Judgment integration is about incorporating expert and ethical human discernment to make AI’s output more trustworthy, reliable, and accurate. It entails augmenting a model’s training sources with authoritative knowledge bases when necessary, keeping biases out of prompts, ensuring the privacy of any data used by the models, and scrutinizing suspect output. With reciprocal apprenticing, you tailor gen AI to your company’s specific business context by including rich organizational data and know-how into the commands you give it. As you become better at doing that, you yourself learn how to train the AI to tackle more-sophisticated challenges. The AI revolution is already here. Learning these three skills will prepare you to thrive in it.

"AI makes it cheaper to contribute to Open Source, but it's not making life easier for maintainers. More contributions are flowing in, but the burden of evaluating them still falls on the same small group of people. That asymmetric pressure risks breaking maintainers." also relevant to slop science
