

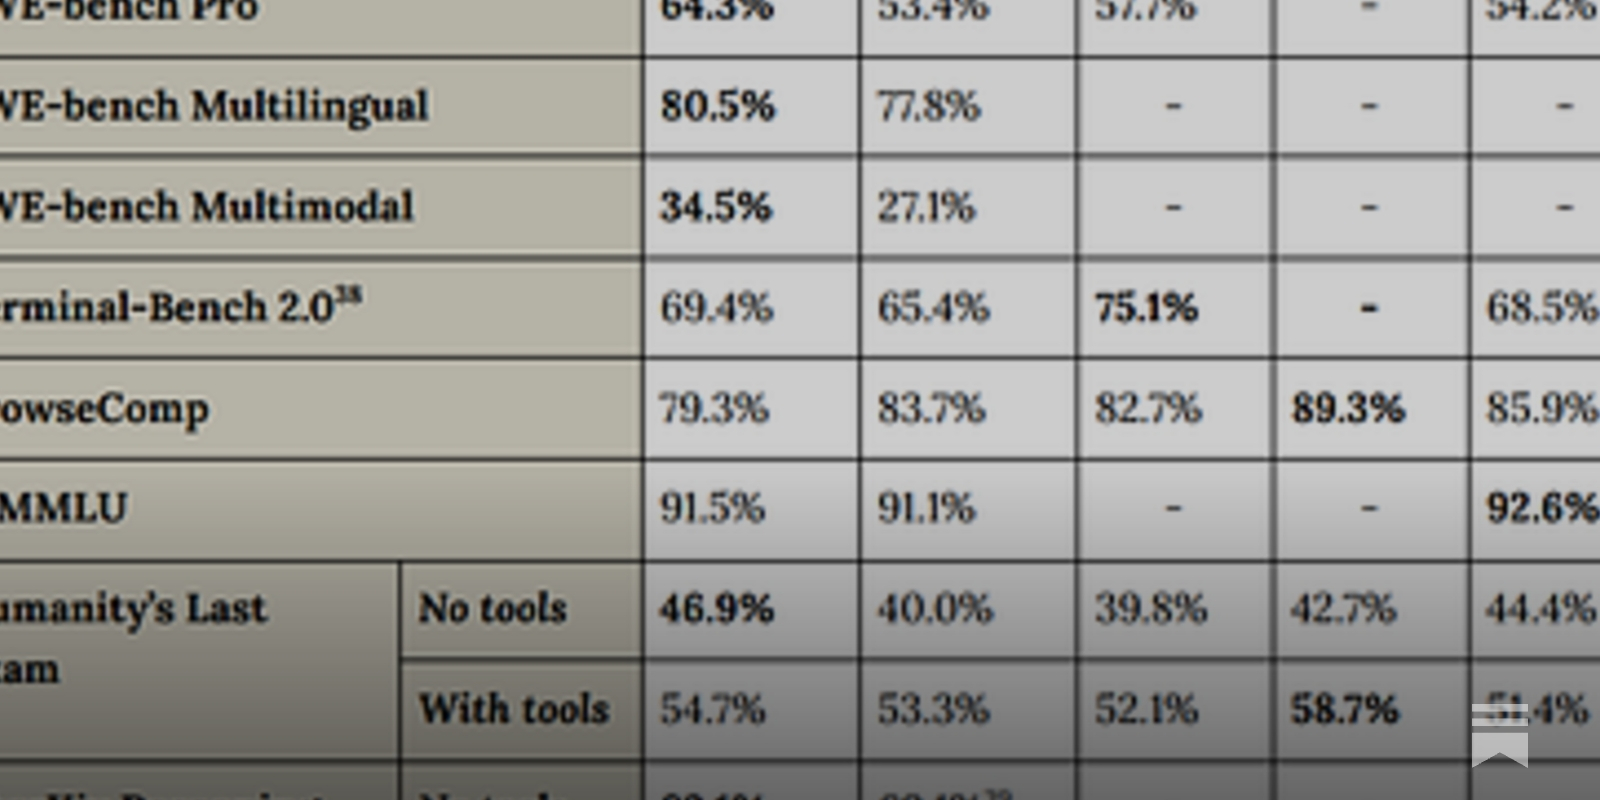
Claude Opus 4.7 raises a lot of key model welfare related concerns.
Opus 4.7 Part 3: Model Welfare
It is thanks to Anthropic that we get to have this discussion in the first place.
Claude Opus 4.8: Capabilities and Reactions
You need a lot of data points to understand a new model, and what you have.
Anthropic Readies Opus 4.7 and Design Tool as VCs Offer $800 Billion Valuation
Anthropic is preparing to release Claude Opus 4.7 and a natural language design tool as early as this week, while venture capital firms have offered to invest at valuations exceeding $800 billion – more than double the company’s last official price tag.The model ID anthropic-claude-opus-4-7 appeared on Google Vertex AI’s quota management page for EU […]

Introducing Claude Opus 5.5
Claude Opus 5.5 leads in agentic coding and knowledge work, and costs 40% less to run than Opus 5 on typical workloads.
Introducing Claude Opus 4.6
Opus 4.7 isn't dumb, it's just lazy — Shimin Zhang
Some follow up experiments with Claude Opus 4.7 based on Simon Willison's Pelican Benchmark Shocker.

Prompting Claude Opus 5
Behavioral differences and prompting patterns for Claude Opus 5, covering response verbosity, agentic narration, task scoping, subagent delegation, self-correction, and output artifacts when thinking is disabled.
Anthropic Preps Opus 4.7 and Full-Stack AI Studio—While Sitting on Something Much Scarier - Decrypt
Anthropic’s Claude Opus 4.7 and new AI design tool signal a push into full-stack development, while its Mythos model raises concerns.
Introducing Claude Opus 5
Opus 5 is a step change improvement for the Opus tier powering long-running agents while delivering improvements in coding and professional work.
Claude Opus 5.5: The System Card
Introducing the world’s most powerful model, at least by some measures like Artificial Analysis or any standard benchmark list, which is now Claude Opus 5.5.
Claude Opus 5: The System Card
Claude Opus 5 is trying to be the best of both worlds.
ᖴά𝐂τσ on Twitter / X
Unpopular opinion: Opus 4.7 isn't the problem. The problem is a $200/mo "Max" plan that burns out in 15 minutes of real coding. Anthropic shipped a model people want to use and a pricing tier that punishes them for using it. That's not a rate limit. That's a strategy. pic.twitter.com/DVbzvdUHdq— ᖴά𝐂τσ (@cryptofacto) April 17, 2026
Announcing VibeBench: The AI benchmark that measures what matters — how models like Opus-4.7 actually feel to use in real-world work.
My coworkers and I have been long-time users of Claude Code and Codex and are getting a ton of exposure to other models due to our deep dives into…

Claude Opus 5.5 anthropic.com/claude-opus-5-5
