

Pool mismatched CUDA + ROCm + Metal GPUs into one endpoint and run a 70B that fits on no single machine. 1.86x measured on 70B over WiFi. Same output. $0 cloud.
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
TPUs vs. GPUs and why Google is positioned to win AI race in the long term | Hacker News
To quote The Next Platform: "An Ironwood cluster linked with Google’s absolutely unique optical circuit switch interconnect can bring to bear 9,216 Ironwood TPUs with a combined 1.77 PB of HBM memory... This makes a rackscale Nvidia system based on 144 “Blackwell” GPU chiplets with an aggregate of 20.7 TB of HBM memory look like a joke."
OpenAI Chat GPT OSS 20b Open Source LLM Full Local Ai Review
noname on Twitter / X
Upto 1100 tps on RTX 3090x2 for Diffusion Gemma 4 26B.Unleash this mini monster on your gpus now!If you are running nvidia gpus locally, come grab the recipe at club-3090. https://t.co/qKuFcgu1llP.S. a ⭐️ on Github is much appreciated.@googlegemma @vllm_project— noname (@malikwas1f) June 11, 2026
VPS with the Best Price-to-Performance Ratio in the US | Contabo
High-end Cloud VPS hosting for a fair price. Featuring AMD CPUs, lots of RAM (from 8 GB), NVMe storage, and unlimited traffic, with root access. Spin up your cheap VPS in minutes!
NVIDIA GPUs Work on macOS Again. The Driver Is a Miracle. The Inference Is Not.
We benchmarked an RTX 3090 over USB4 and profiled every kernel. GPUs use 1.2-1.6% of their memory bandwidth. The bottleneck is the compiler, not the cable.
Rohan Paul on Twitter / X
Google is trying to win AI by making compute cheap, not by beating Nvidia on raw speed.Nvidia sells GPUs to clouds with a big 70%+ margin that sits on top of manufacturing and R&D cost and raises cloud prices.Google builds TPUs for itself at near manufacturing cost, adds no… https://t.co/aSgWRf0HY7 pic.twitter.com/T3Fzc6czwg— Rohan Paul (@rohanpaul_ai) November 25, 2025

the tiny corp on Twitter / X
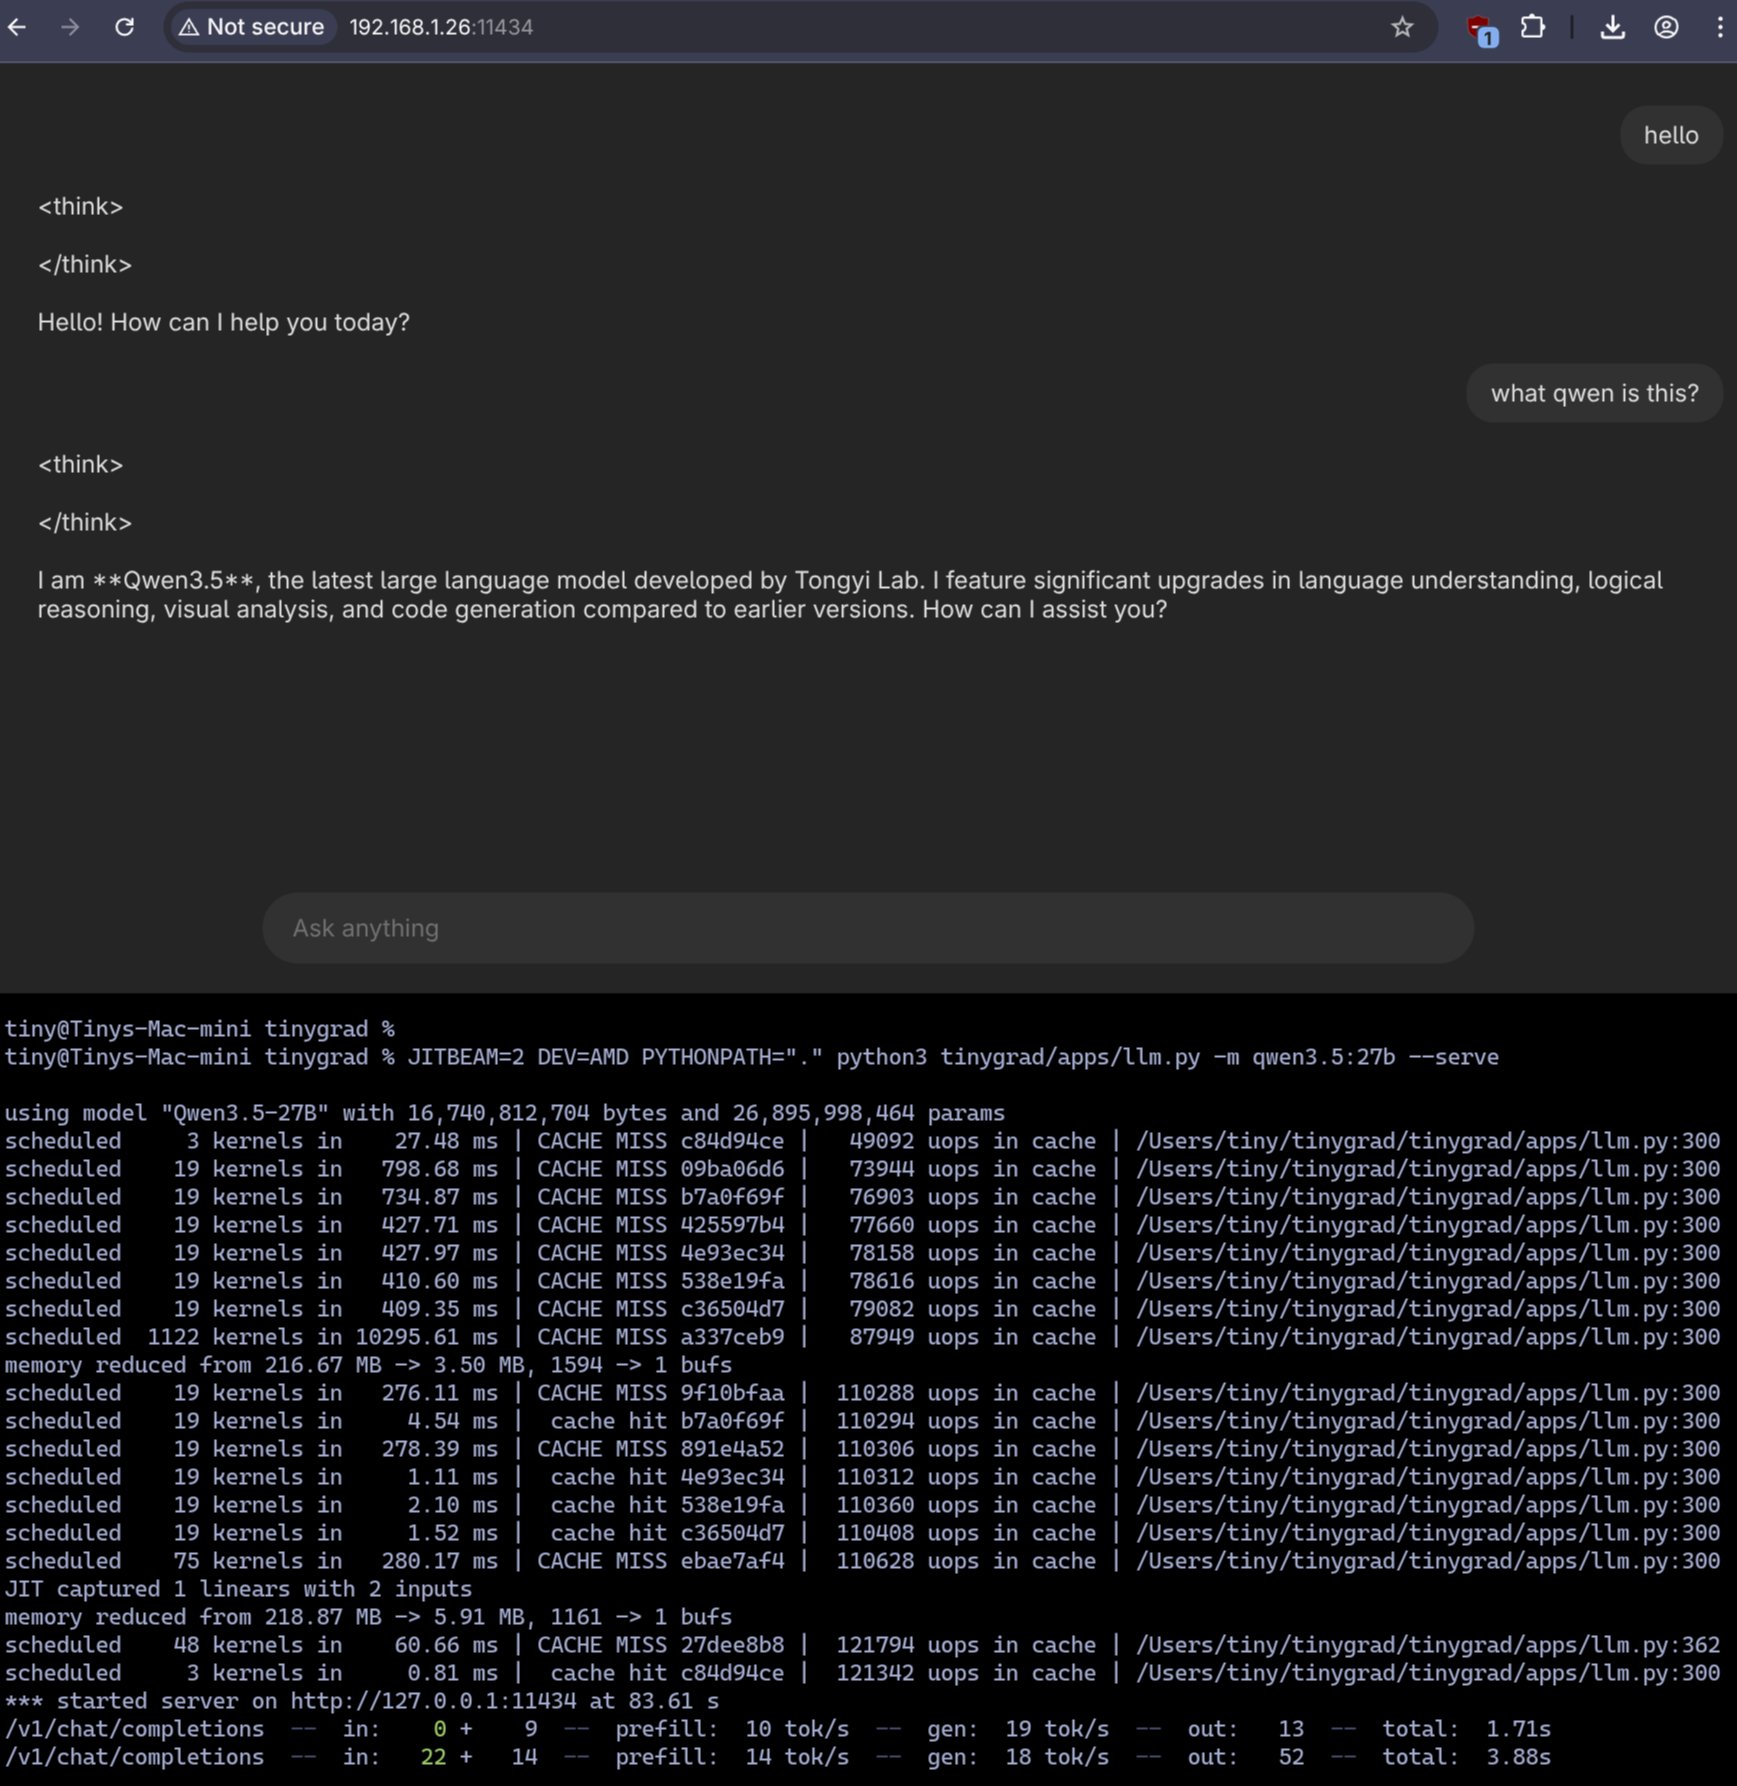
Qwen 3.5 27B getting 18.5 tok/s on Mac Mini with external 7900XTX. It should be able to be 3x faster than this with work, SSM stuff is still in PR. Hopefully Mac eGPU support brings in devs. pic.twitter.com/2aMkUpXY1S— the tiny corp (@__tinygrad__) April 1, 2026
Mesh LLM: distributed AI computing on iroh
How Mesh LLM pools existing GPU resources across machines into a single OpenAI-compatible API, built on iroh.
Awni Hannun on Twitter / X
It's very cool that Apple shipped a 20B parameter on-device. You can't put 20B parameters in RAM at any reasonable precision. To make it work they are using pretty exotic architecture by today's standards.A small model predicts from the query (or prompt) which experts to load… pic.twitter.com/Zhe5HcbGuL— Awni Hannun (@awnihannun) June 9, 2026
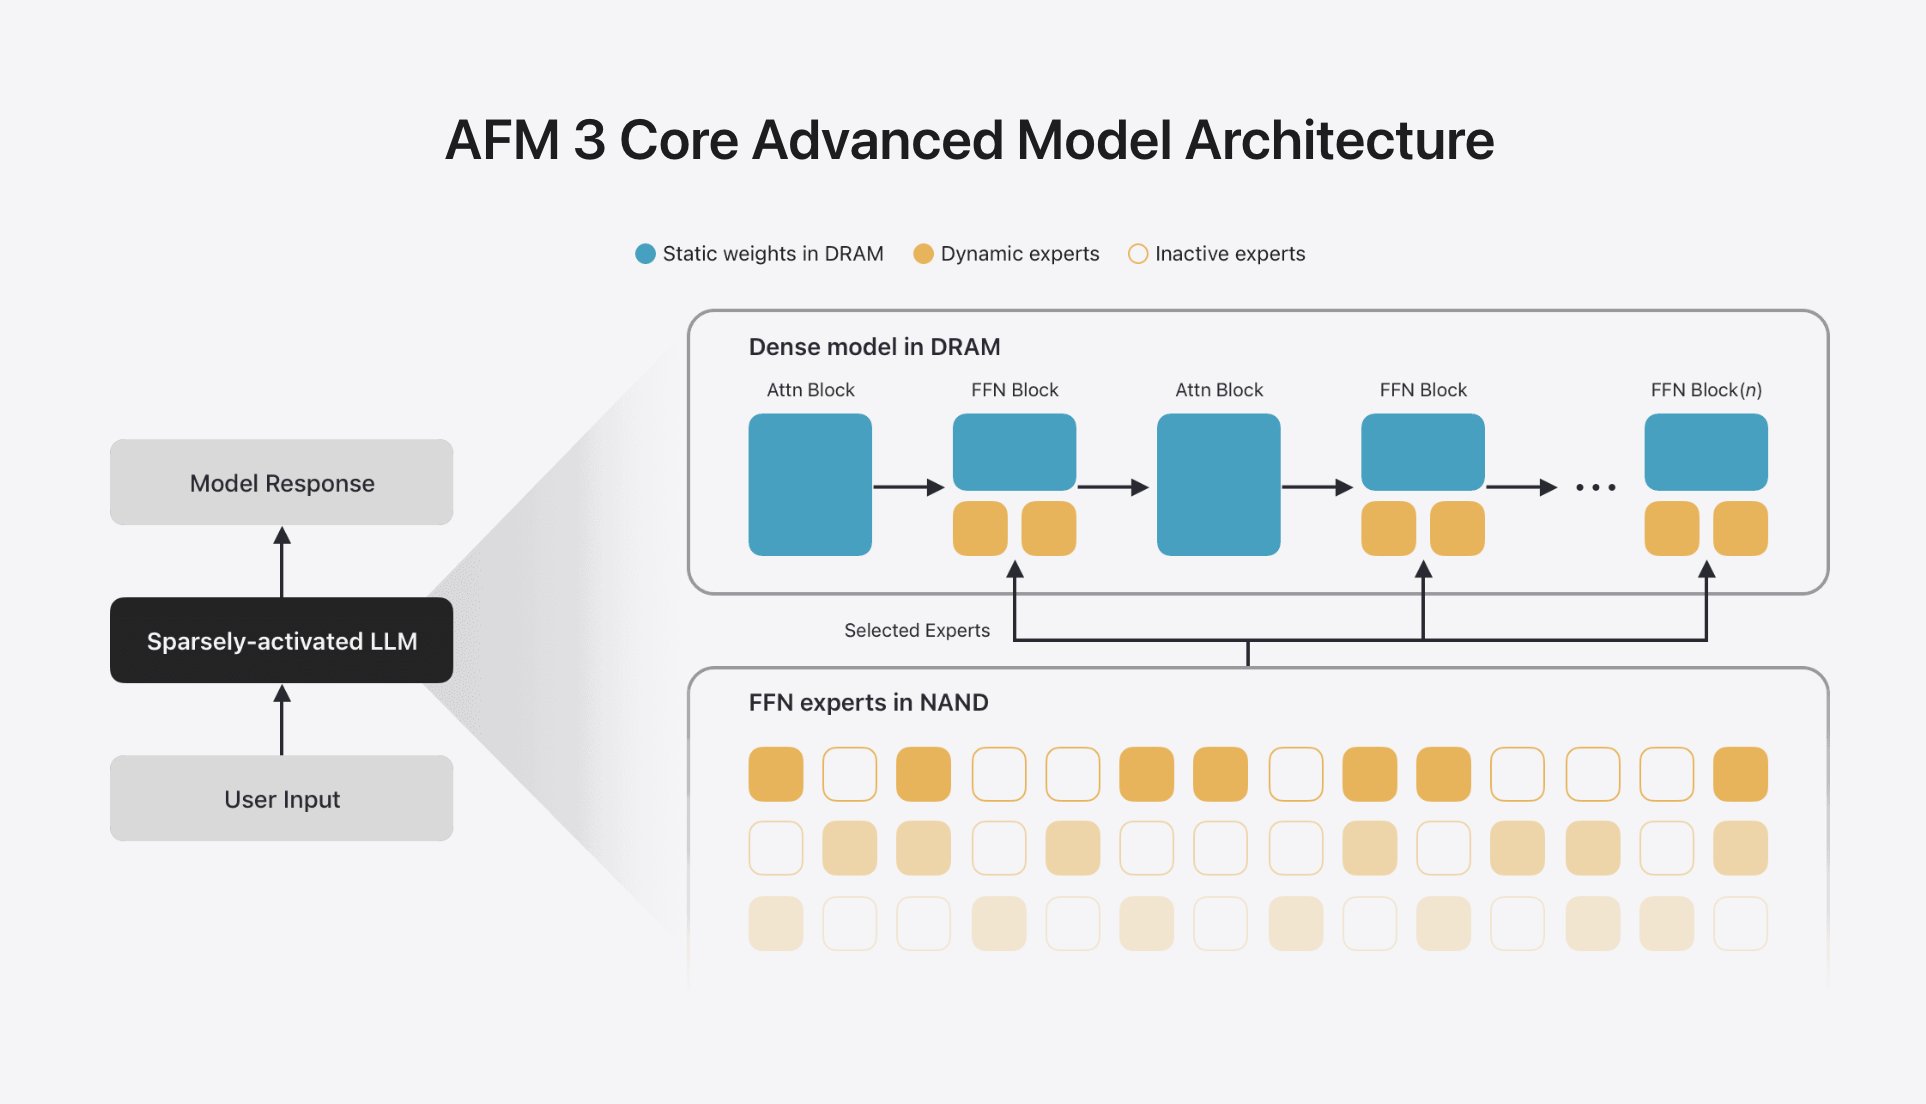
Asus ROG Flow X13 GV302X 13.3" Ryzen 9 7940hs 4.0ghz 16GB RAM 512gb SSD
Discover the blend of performance, portability, and versatility with the ASUS ROG Flow X13. This notebook is designed to meet the demands of gaming enthusiasts and creative professionals. At its core is the powerful AMD Ryzen 9 7940HS processor, complemented by the NVIDIA GeForce RTX 4070 graphics card, ensuring smooth gameplay and efficient multitasking.
Cua on Twitter / X
1/ Today, as part of our broader research into Apple Silicon virtualization, we're releasing a process-scoped Metal capability layer for macOS VMs. On one M1 Ultra, prompt / generation:TinyLlama: 11.08× / 16.36×Gemma 4 12B: 7.20× / 14.54×Muse Glimmer 30B: 7.55× / 8.87× pic.twitter.com/6UwxgoDowT— Cua (@trycua) August 11, 2026
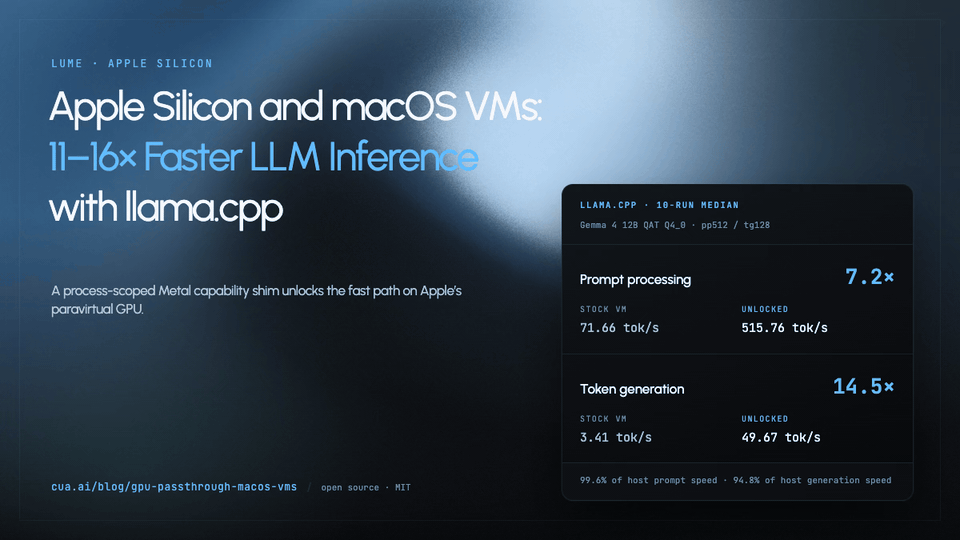
Random Forest ML on GPU
In my recent post on Rastair , we looked at some performance best-practices and optimizations for Rastair , a bioinformatics tool that I’m currently working on. One of the slowest parts of the tool is …
Joel - coffee/acc on Twitter / X
OKAY - it seemed like DFlash would be the clear winner.But it appears there have been some improvements with MTP.With MTP + split-mode = tensor, Qwen3.6-27B gets over 120 tokens/second on dual RTX 3090s (note I am running PCIE x16 on both, I don't have an NVLink bridge).… https://t.co/AQmqTJrof7 pic.twitter.com/RQSPVsNwMO— Joel - coffee/acc (@JoelDeTeves) June 29, 2026
