

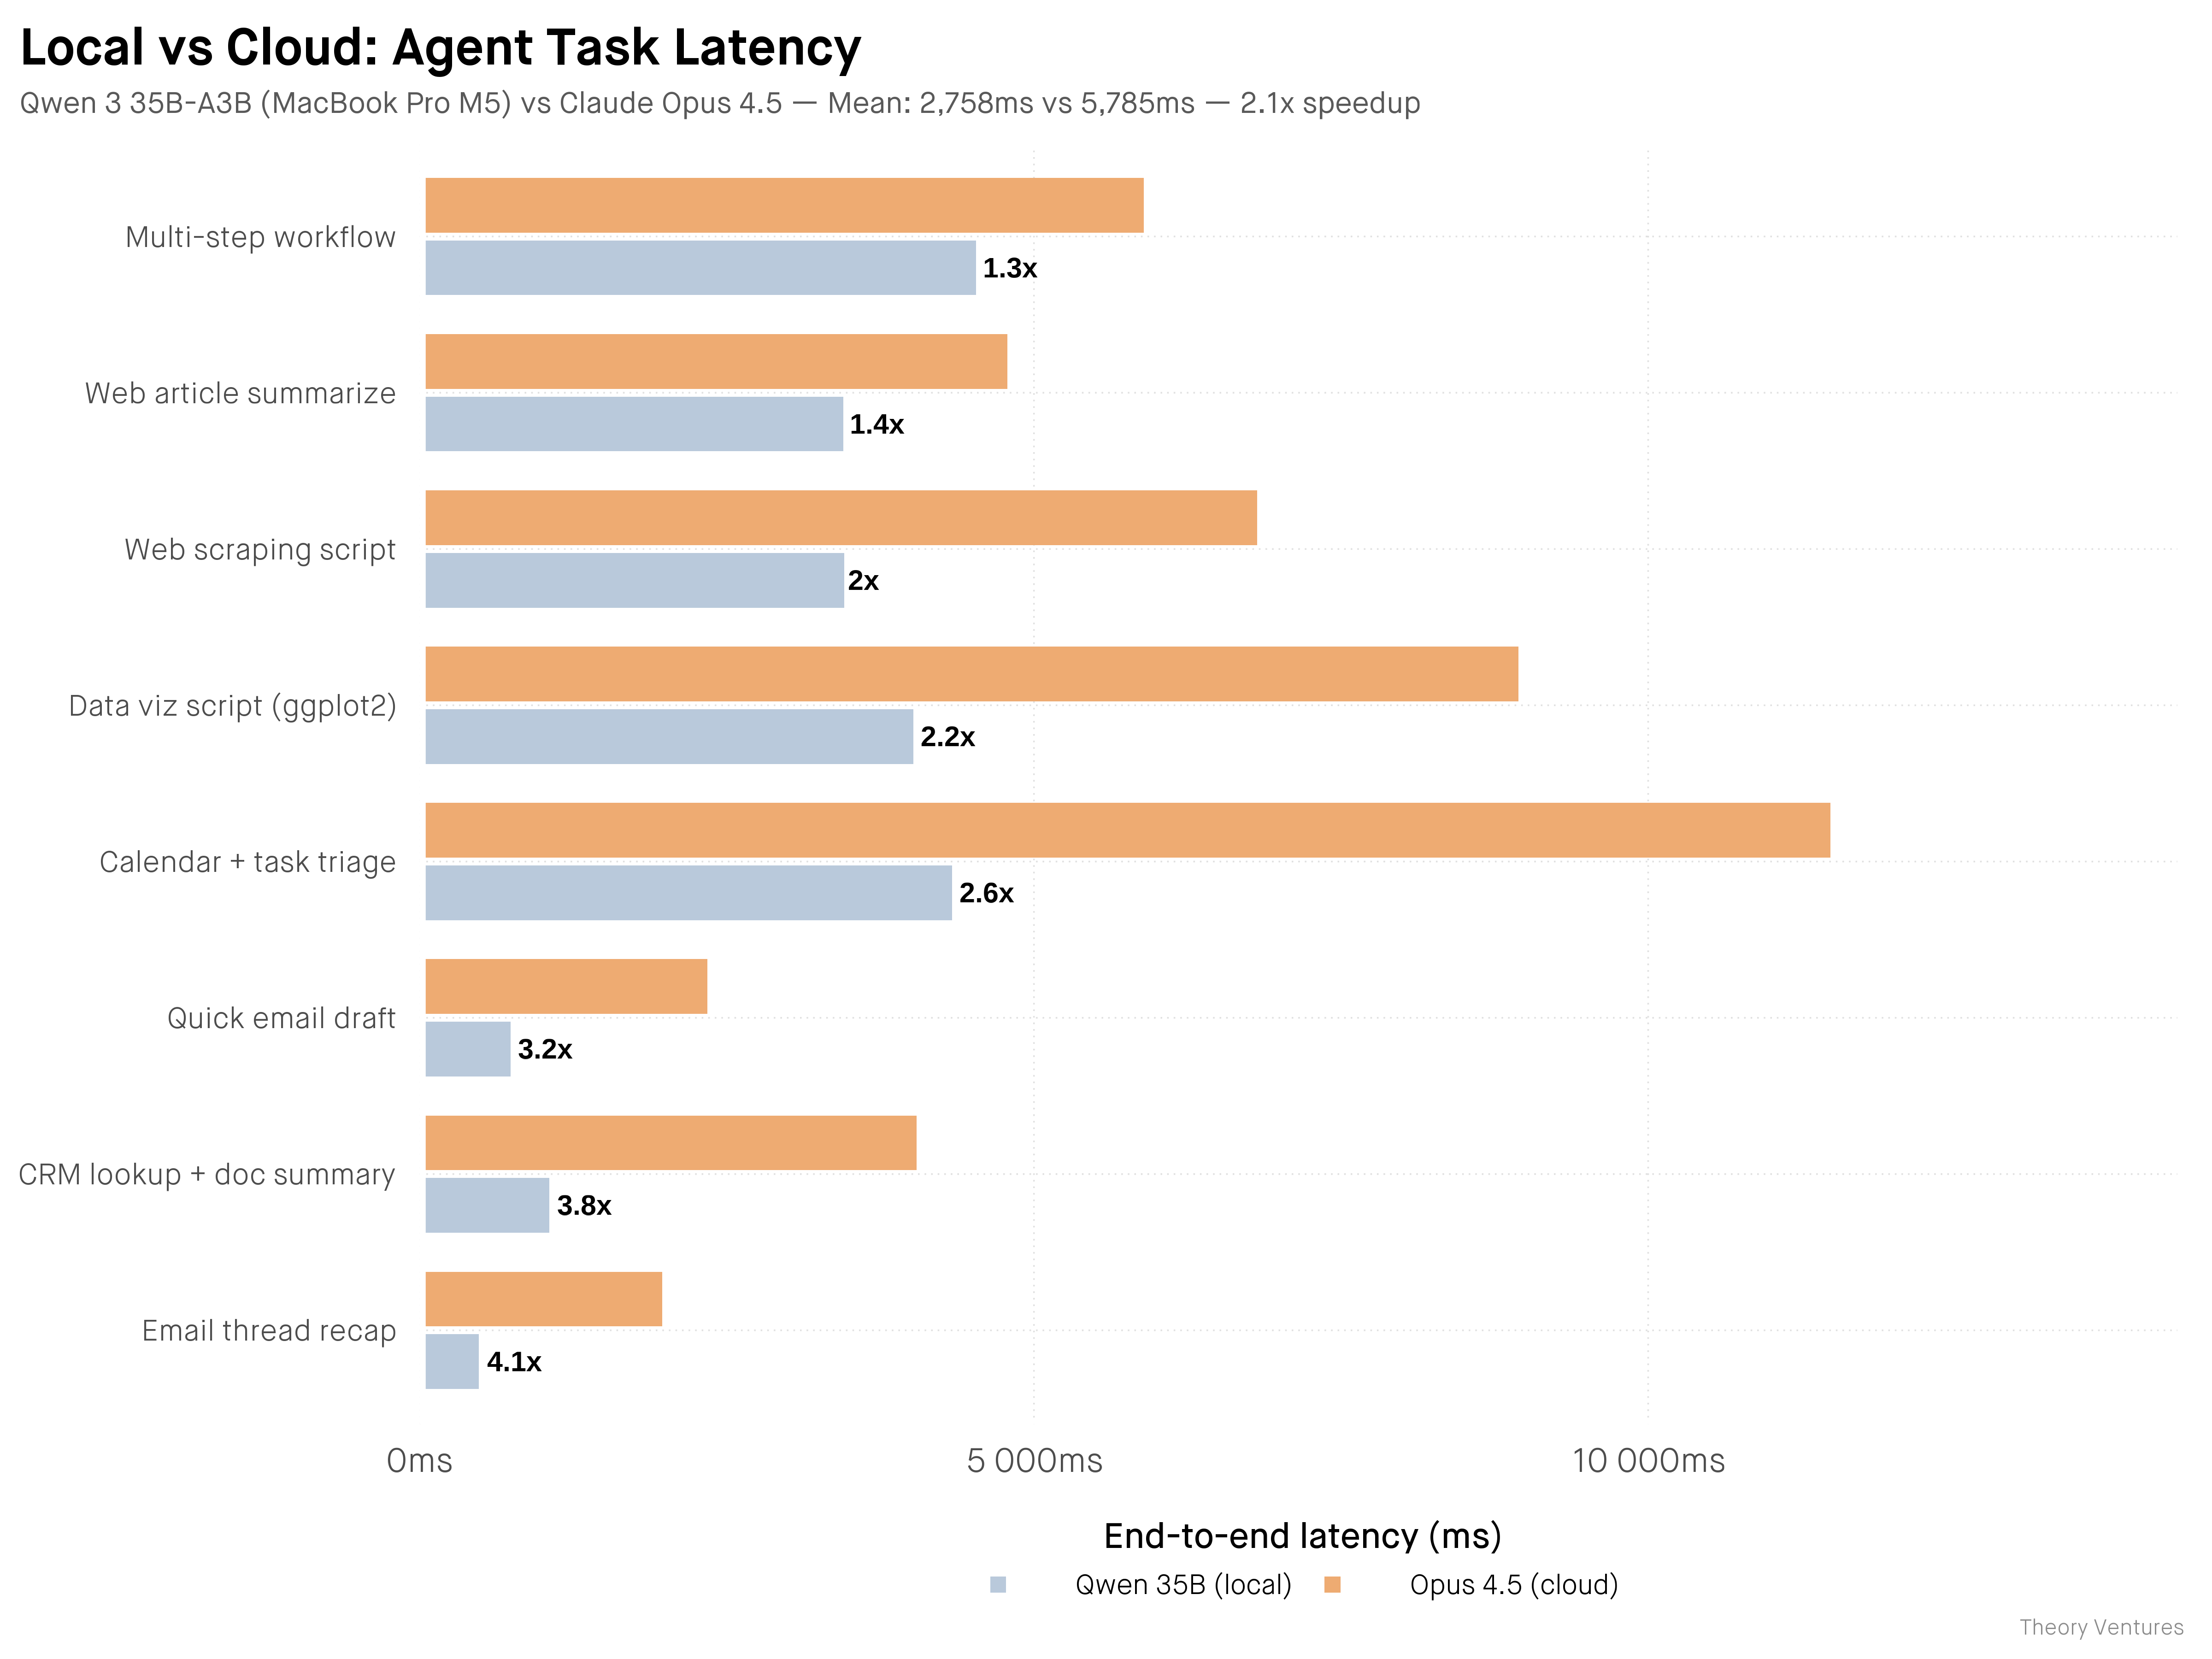
About half of agent tasks can run on a local 35B model. The real advantage isn't cost or privacy — it's latency. 2.1x faster means more iteration cycles per session.
Running local models is good now
Local agentic coding has gotten great over the past few months
Alex Cheema on Twitter / X
This is why we need open benchmarks for local AI.Otherwise it turns into tribalism and name calling.We will be publishing the largest database of open benchmarks for local AI, tested on 1,000+ real hardware setups. Every device, every interconnect, different… https://t.co/ZsU3PCdSsZ— Alex Cheema (@alexocheema) March 9, 2026
View @Jefflau's post on Firefly
I think what's interesting is that the desire for local AI may inadvertently create a lot more local node users. It's a fraction of the actual compute local AI needs and just requires a decent amount of disk space.
local.ai — Charting the transition from cloud AI to local AI.
Independent benchmark quality and measured serving performance for local hardware you can buy.
Qwen3.6 27B — Qwen/Qwen3.6-27B rental
Free · 32 concurrent · hosted by selimaktas on LocalMaxxing.
Ankesh Bharti - Tiles: Own your AI with local models and open protocols
Ankesh Bharti - Tiles: Own your AI with local models and open protocols
NVIDIA Levels Up Local AI Agents Across RTX PCs and DGX Spark
Announced at GTC Taipei at COMPUTEX, NVIDIA OpenShell brings secure agents to Windows with 2x inference performance on llama.cpp — plus, Adobe rebuilds its apps with performance and memory enhancements, and Blender adds NVIDIA DLSS 4.5 Ray Reconstruction for NVIDIA RTX Spark.
M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents
For the past few days, I’ve been testing the (currently) top-of-the-line M5 Ultra Mac Studio with 256 GB of RAM. I’ll cut to the chase: the M5 Ultra Mac Studio is a dream machine for local AI agents. This computer makes it possible to run personal assistants powered by local models with great performance and
Why MLX — Prince Canuma, Neywa Labs
NativeLink — Build infrastructure for the agentic era
When agents write your code, your build system is the bottleneck. NativeLink is the high-performance remote build cache and execution platform for Bazel and beyond.
The Shape of Memory Benchmarks
Why the familiar memory benchmarks are outdated, how the agent-native work looks today and why design your own.
Improving LM Studio's MLX Engine for Agentic Workflows
mlx-engine v1.8.5 dramatically improves performance for repeated, long-context agentic workflows by checkpointing your KV cache.
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
Teaching AI to Optimize AI Models for Edge Deployment
How our agent, Möbius automated a Core ML port in ~12 h (vs. 2 weeks), hit 0.99998 parity, and made it 3.5× faster, while staying on the CPU.
Liquid AI on Twitter / X
Today, we release LFM2.5-350M. Agentic loops at 350M parameters.A 350M model trained for reliable data extraction and tool use, where models at this scale typically struggle.<500MB when quantized, built for environments where compute, memory, and latency are constrained.🧵 pic.twitter.com/zZPKzcCwH9— Liquid AI (@liquidai) March 31, 2026
