Compressing one billion bytes of Wikipedia into 105.39 MB with a Transformer that learns online and an offline trained initialization.
Dictionary Compression is finally here, and it's ridiculously good
Dictionary compression could completely change how applications send data over the web. It's recently gained broad support, and offers absurd real-world...
Google Publishes Zopfli, an Open-Source Compression Library - Slashdot
alphadogg writes "Google is open-sourcing a new general purpose data compression library called Zopfli that can be used to speed up Web downloads. The Zopfli Compression Algorithm, which got its name from a Swiss bread recipe, is an implementation of the Deflate compression algorithm that creates a ...
Linkup - SPARSEUP: Linkup's Open-Source Sparse Embedding Model
Linkup Research releases SPARSEUP, an open-source sparse embedding model under 150M parameters. SOTA on BEIR-13, sub-millisecond retrieval, Apache 2.0 license.
DSPy on Twitter / X
DSPy is the highest-bandwidth language to talk to computers in a just-precise-enough way.First 36 lines below:1. Take arbitrarily long content: `chunks`.2. Build a global Table of Contents.3. Distribute chunks into sections to be written.4. Recursively write each section. pic.twitter.com/7NN61isFLs— DSPy (@DSPyOSS) May 13, 2025

Compression Dictionary Transport - HTTP | MDN
Compression Dictionary Transport is a way of using a shared compression dictionary to dramatically reduce the transport size of HTTP responses.
Wikidata
the free knowledge base with 120,900,955 data entities that anyone can edit.
Better Than Free
[Translations: Belarusian, Chinese, Estonian, French, German, Italian, Japanese, Polish, Portuguese, Russian, Spanish, Turkish] The internet is a copy machine. At its most foundational level, it copies every action, every character, every thought we make while we ride upon it. In order to … Continue reading →
HatchZip
Extract huge archives without needing double the disk space. Free and open source, for Windows, macOS and Linux.
The Internet's Most Powerful Archiving Tool Is in Peril
As major news outlets cut off the Wayback Machine, journalists and advocacy groups are rallying to protect the Internet Archive’s vast collection of web pages.

Wikipedia:archive.today guidance
The English Wikipedia has decided to stop using archive.today and its related websites. This decision was agreed on after a request for comment with more than 200 participants concluded in February 2026, and is due to multiple concerns, including the site using editors' and readers' computers to run a denial-of-service attack and evidence that the website has tampered with some archived pages.
Wikipedia Is Battling for the Soul of the Internet
The internet’s largest stockpile of free knowledge is under threat from MAGA, A.I. and foreign autocrats. A bibliophile ex-ambassador is here to help.

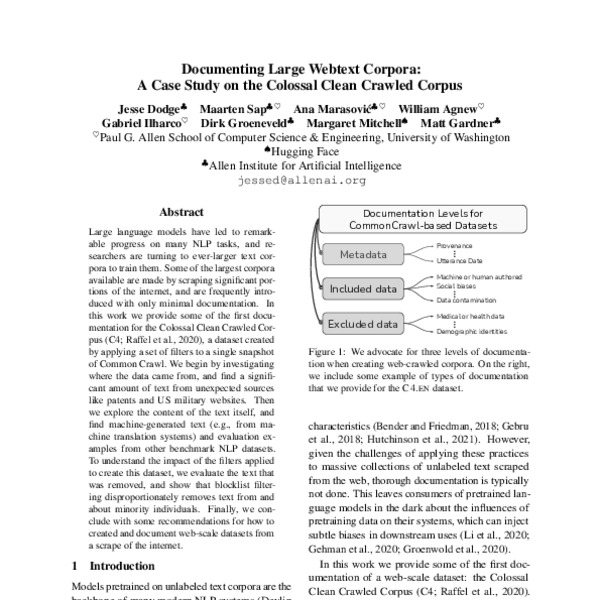
Documenting Large Webtext Corpora: A Case Study on the Colossal Clean Crawled Corpus
Large language models have led to remarkable progress on many NLP tasks, and researchers are turning to ever-larger text corpora to train them. Some of the largest corpora available are made by scraping significant portions of the internet, and are frequently introduced with only minimal documentation. In this work we provide some of the first documentation for the Colossal Clean Crawled Corpus (C4; Raffel et al., 2020), a dataset created by applying a set of filters to a single snapshot of Common Crawl. We begin by investigating where the data came from, and find a significant amount of text from unexpected sources like patents and US military websites. Then we explore the content of the text itself, and find machine-generated text (e.g., from machine translation systems) and evaluation examples from other benchmark NLP datasets. To understand the impact of the filters applied to create this dataset, we evaluate the text that was removed, and show that blocklist filtering disproportionately removes text from and about minority individuals. Finally, we conclude with some recommendations for how to created and document web-scale datasets from a scrape of the internet.

Semantic Compression
An introduction to the idea that code should be approached with a mindset towards compressing it semantically, rather than orienting it around objects.