

Inaugural blog post about the development of turbopuffer, a search engine that uses object storage and SSD caching for cost-effective, low latency search. This post describes into the motivation behind its creation, its unique architecture, and how it significantly reduces costs for large-scale vector searches. Discover how turbopuffer is transforming search infrastructure for companies like Cursor and Suno, offering a scalable and reliable solution.
Introduction
A complete search engine and RAG pipeline in your browser, server or edge network with support for full-text, vector, and hybrid search in less than 2kb.
Fast Embeddings on GPUs
Fast and accurate search is vital to all of Perplexity, from Search and Computer to our API Platform. Behind the scenes, the heavy lifting is done by embedding

How Notion Cut Millions from Their Vector DB Bill Without Sacrificing Search Quality
CompactLTJ: Space & Time Efficient Leapfrog Triejoin on Graph Databases
Leapfrog Triejoin (LTJ) is arguably the most practical and popular worst-case-optimal (wco) algorithm for solving basic graph patterns in graph databases. Its main drawback is that it needs the database triples (subject, predicate, object) represented as paths in a trie, for each of the six orders of subject, predicate, and object. The resulting blowup in space makes most systems disregard LTJ or implement it only partially, which makes their corresponding algorithms non-wco. In this paper we show that, by using compact data structures, it is possible to build an index that at the same time matches the query time performance of the fastest classic wco index, and uses a fraction of the space of non-wco indices (which are much slower). Concretely, we make use of compact tree representations to store functional tries using one bit per trie edge, instead of one pointer, and further reduce the space by storing partial tries. Our most compact variant uses 5–6 times less space than classic wco implementations and 2–3 times less than classic non-wco systems. At solving queries, it is on par with the fastest classic wco system, and 30–40 times faster than non-wco systems. We further incorporate improved query resolution strategies into CompactLTJ variants, which makes it considerably faster than classic wco systems as well, on queries that do not output too many results. Finally, we show how CompactLTJ can incorporate dynamism without altering its performance, even under very demanding update regimes. We leave a public fully-functional implementation of CompactLTJ that can be directly used by practitioners.

project-you-apps/vector-plus-studio
Semantic search via 16M-neuron CUDA lattice. Content-addressable memory with noise tolerance.
DuckDuckGo Lite: Fast, Lightweight Private Search
The lightest weight version of DuckDuckGo private search. Loads fast on slow connections and compatible with text-based browsers.
Vultr: High Performance SSD Cloud.
Vultr Global Cloud Hosting - Brilliantly Fast SSD VPS Cloud Server Login

Meilisearch: Unified Search & AI Retrieval Platform
Build lightning-fast search and AI retrieval with Meilisearch. Open-source, developer-friendly search engine trusted by 20,000+ teams worldwide.
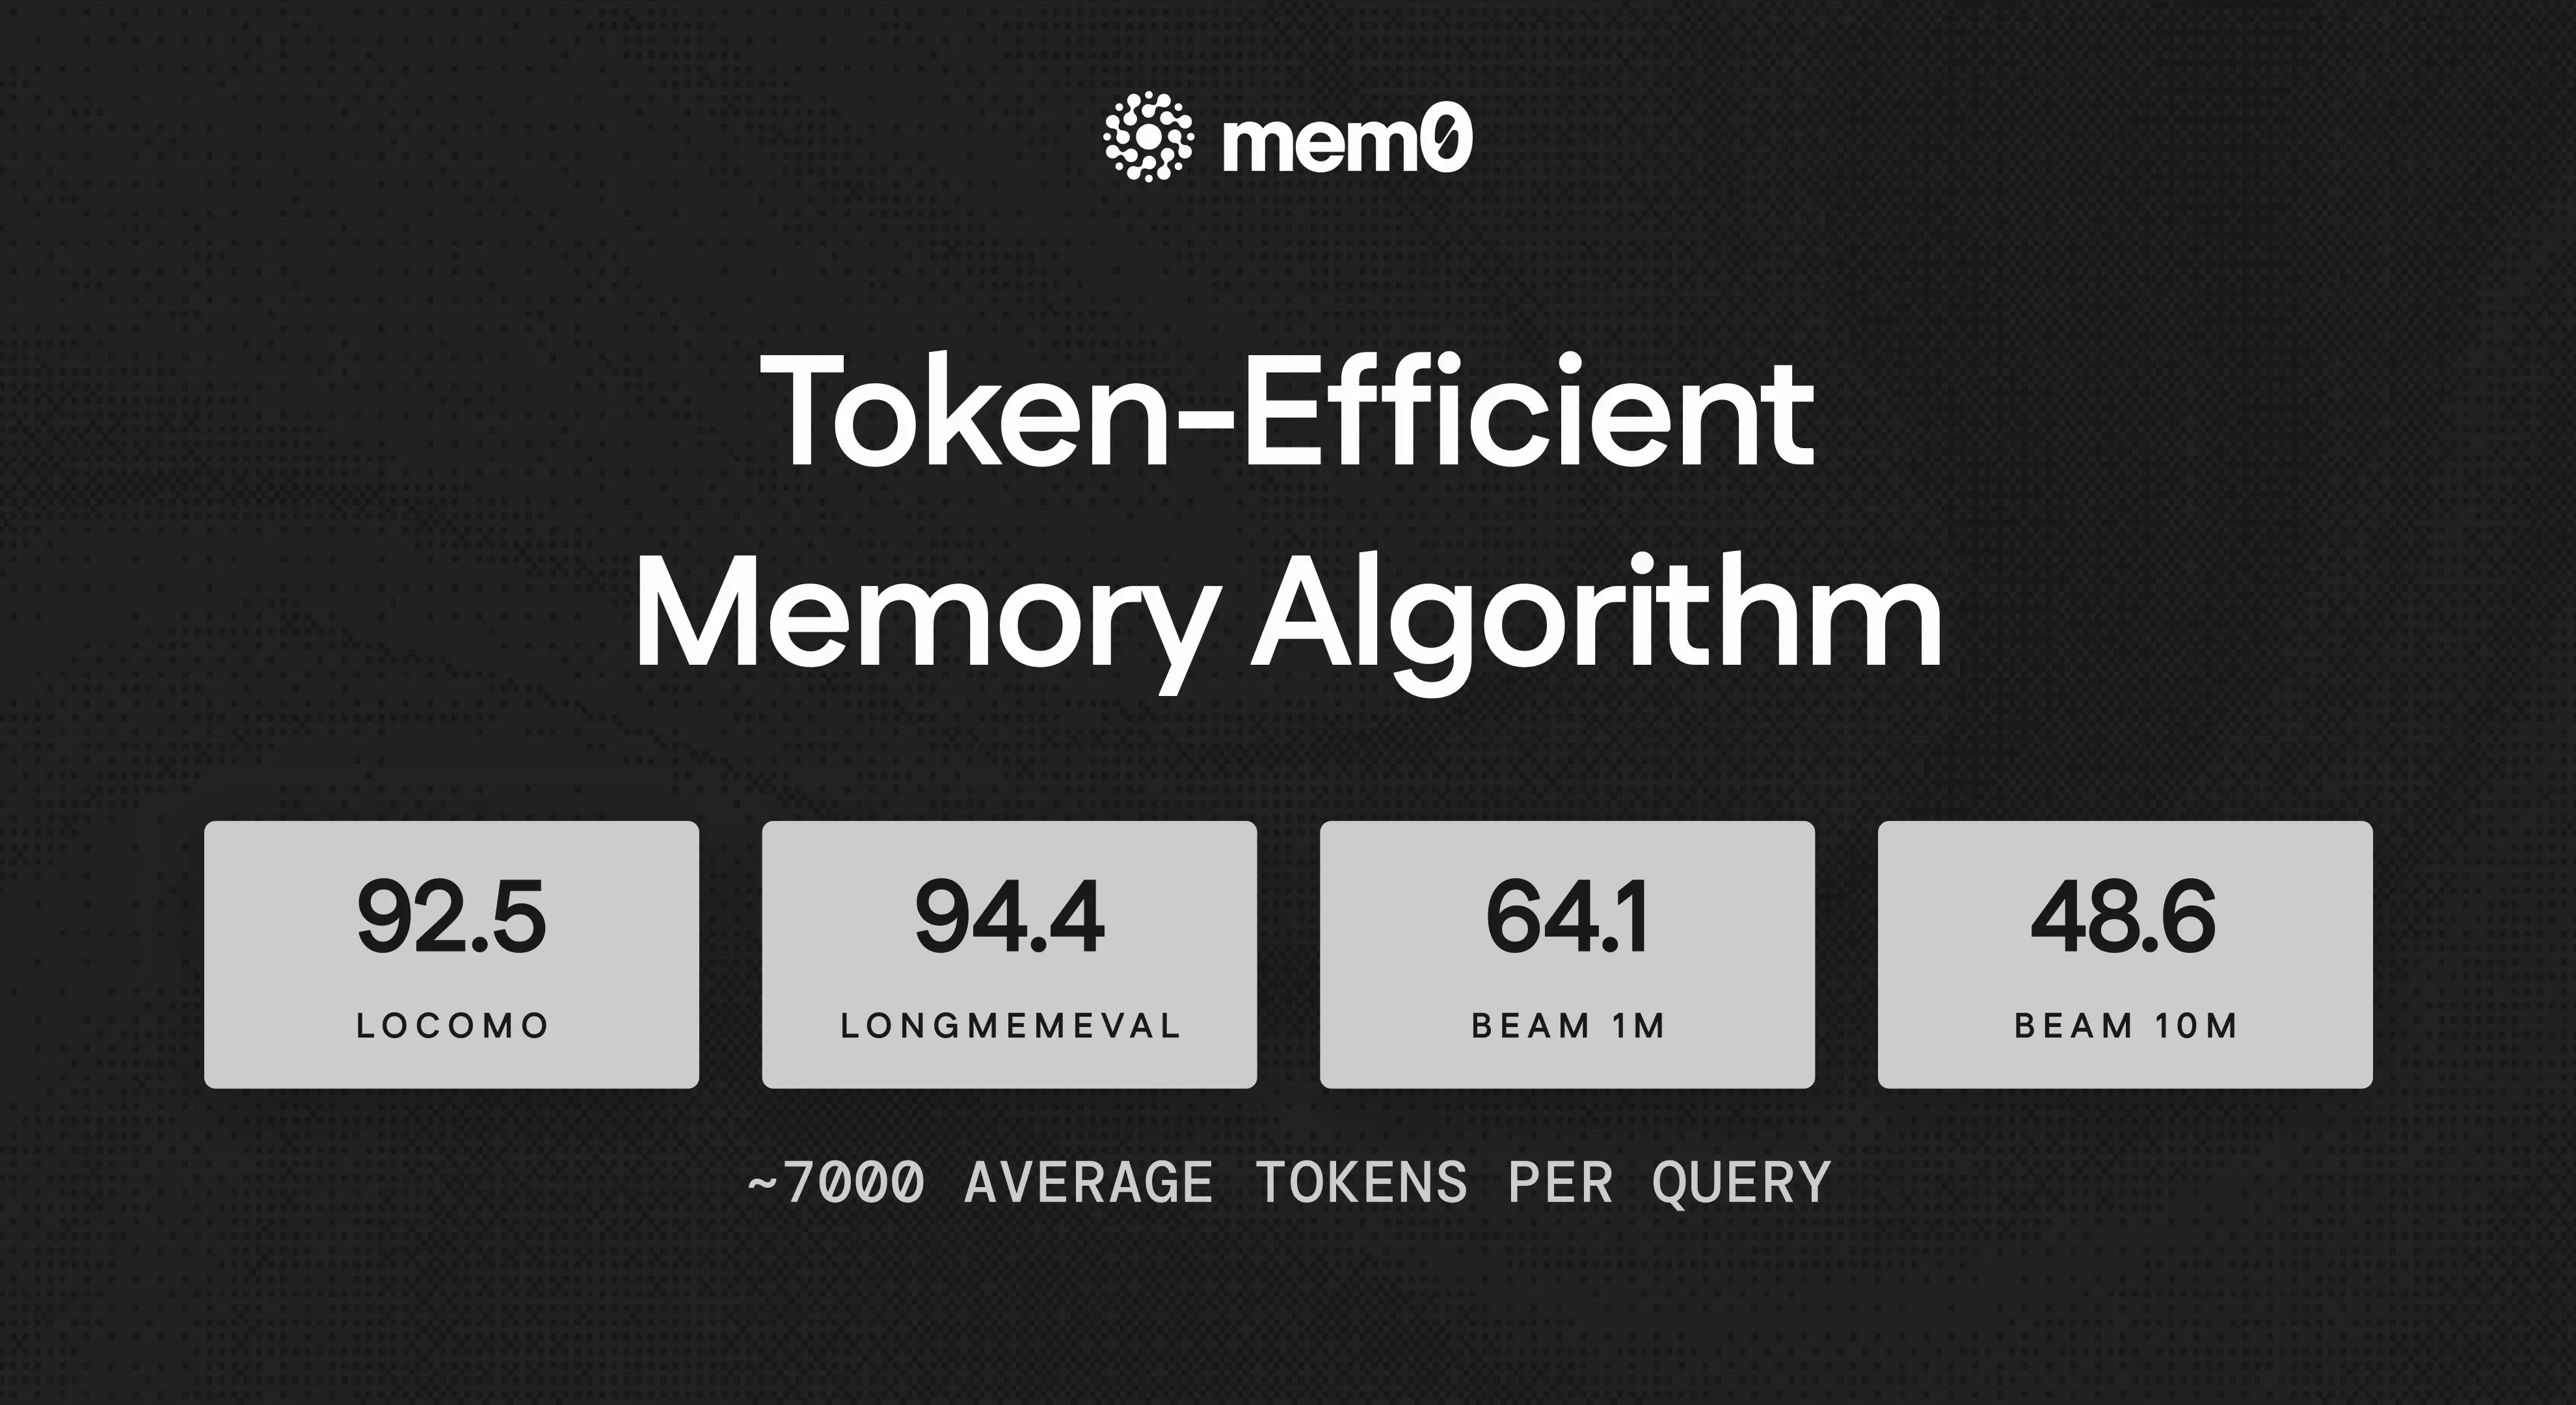
Mem0 Research Paper: Token-Efficient Memory Algorithm
Benchmarked across LoCoMo, LongMemEval, and BEAM, achieves competitive accuracy while using under 7,000 tokens per retrieval call. For comparison, full-context approaches on these benchmarks routinely consume 25,000+ tokens per query.
Your Data Fits in Memory (GraphD Part 1)
We need a fast way to query multiple potentially large sets of data on-demand at interactive speeds. Sometimes the easiest solution to a hard problem is to build the right tool for the job.
Benchmarking Subquadratic’s latest model & SSA Kernel | Appen
56× faster than FlashAttention-2 at 1M tokens. Independent efficiency, retrieval, and SWE-Bench benchmark of sparse self-attention. Download the full report.
Turbocharging Web Apps: Efficient AI Model Caching in Chrome
jdefrancesco/dskDitto
Ultra fast and easy duplicate file finder. Awesome TUI/GUI to manage results.
quick_cache - Rust
Lightweight, high performance concurrent cache. It allows very fast access to the cached items with little overhead compared to a plain concurrent hash table. No allocations are ever performed unless the cache internal state table needs growing (which will eventually stabilize).
Hi protocol friends! I've been cooking up a Very Large PDS (vlpds) implementation capable of scaling up to billions of accounts and down to just one. It uses Object Storage as its only state, supports HA operation, live scaling up and down, is feature-complete with the reference PDS, and is FOSS.

Overview · vlpds docs
vlpds.jazco.dev