

Let's build a RAG app using MetaAI's Llama-3 (100% local):— Akshay 🚀 (@akshay_pachaar) April 19, 2024
Llama 4: How to Run & Fine-tune | Unsloth Documentation
How to run Llama 4 locally using our dynamic GGUFs which recovers accuracy compared to standard quantization.

llama.app : website + unified `llama` binary · ggml-org llama.cpp · Discussion #23875
Overview We are launching an official website for llama.cpp: https://llama.app/ The main goal of the website is to provide a simple way for new users to install and run llama.cpp on their machines....
Retrieval Augmented Generation (RAG): What, Why and How? | LLMStack
Retrieval Augmented Generation (RAG) is a simple yet powerful approach that can be used to improve the performance of LLMs on a wide range of tasks.
Why RAG Applications Fail in Production
It worked as a prototype; then all went down!
Talking to your second brain: Build a Flowise RAG to chat with your Obsidian Vault
This guide covers how to build a fully local RAG application based on notes in your Obsidian Vault, without writing a single line of code.

RAG Is Not Agent Memory
Although RAG provides a way to connect LLMs and agents to more data than what can fit into context, traditional RAG is insufficient for building agent memory.
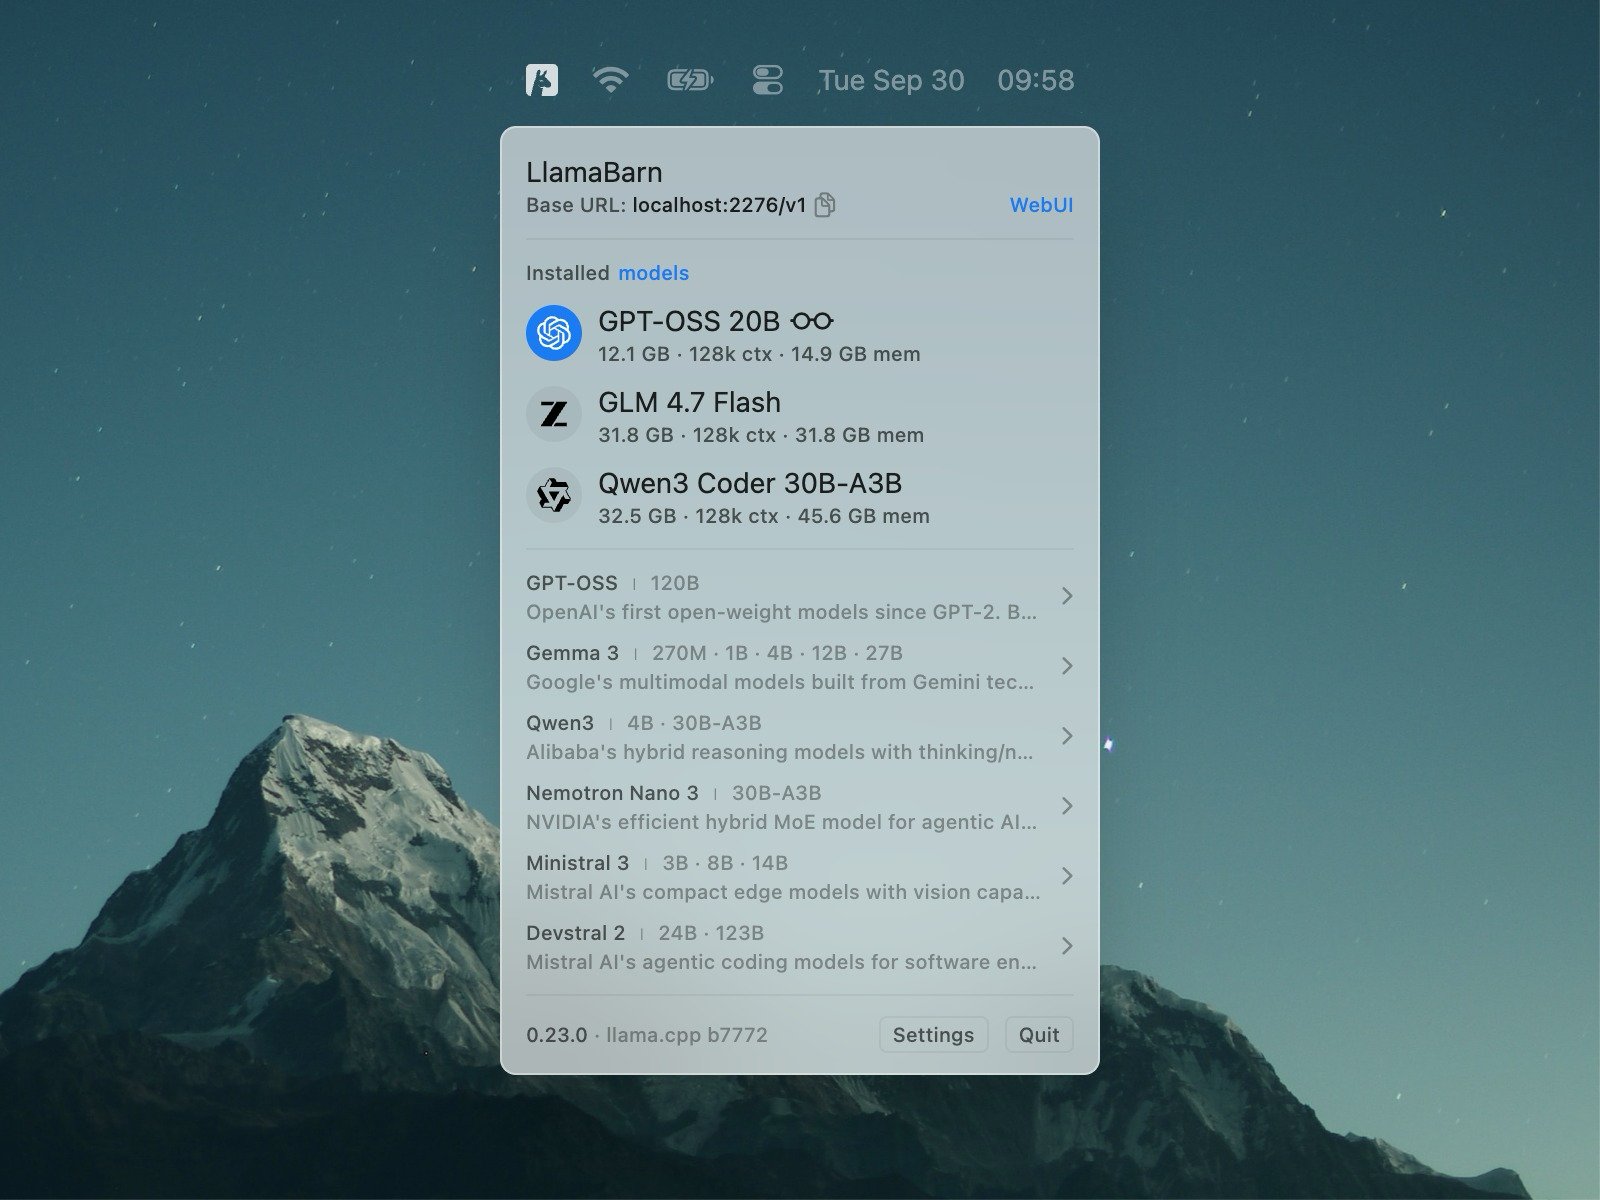
Georgi Gerganov on Twitter / X
Introducing LlamaBarn — a tiny macOS menu bar app for running local LLMsOpen source, built on llama.cpp pic.twitter.com/F1Z3DVl9Kg— Georgi Gerganov (@ggerganov) January 29, 2026
Shlok Khemani on Twitter / X
It's telling that neither ChatGPT nor Claude uses RAG for their memory systems, despite having:- the most data (oldest services, highest usage, general purpose)- strong incentives for memory (user lock-in)- A+ talent and alpha on model trajectoriesMaybe RAG just doesn't…— Shlok Khemani (@shloked) September 15, 2025
Retrieval augmented generation: Keeping LLMs relevant and current - Stack Overflow
Retrieval augmented generation (RAG) is a strategy that helps address both LLM hallucinations and out-of-date training data.
Meta says it's making its Llama models available for US national security applications | TechCrunch
Meta confirmed that it's making its Llama models available to U.S. government contractors for national security applications.
Karpathy shares 'LLM Knowledge Base' architecture that bypasses RAG with an evolving markdown library maintained by AI
Karpathy proposes something simpler and more loosely, messily elegant than the typical enterprise solution of a vector database and RAG pipeline.
Improve RAG for Your LLM Knowledge using InfraNodus and Open-WebUI, Dify, or ChatGPT
RAG, or Retrieval-Augmented Generation, is used to add additional context to AI user queries. However, one of its main problems is that it doesn't have an overview of the whole context. This is...