


Our text-to-speech models: one voice in 31.7 MB, or two voices in 40.6 MB with fewer word errors than Fish Audio Drama 3 at over 1,000 times smaller. They read phone numbers, dates, prices and codes the way people say them.
How Large Language Models Actually Work
Jailbreaking Large Language Models: If You Torture the Model Long Enough, It Will Confess!
A Cautionary Tale…

jack on Twitter / X
We believe voice is the most natural way to interact with intelligence, so we created Dessa, the most authentic full-duplex speech model ever built. Talking with it feels like talking with a person…full of emotion, nuance, pauses, and a natural cadence. https://t.co/r0qFLdvd6c— jack (@jack) October 23, 2026
On the Dangers of Stochastic Parrots: Can Language Models Be Too Big? 🦜
OpenAI.fm
An interactive demo for developers to try the latest text-to-speech model in the OpenAI API
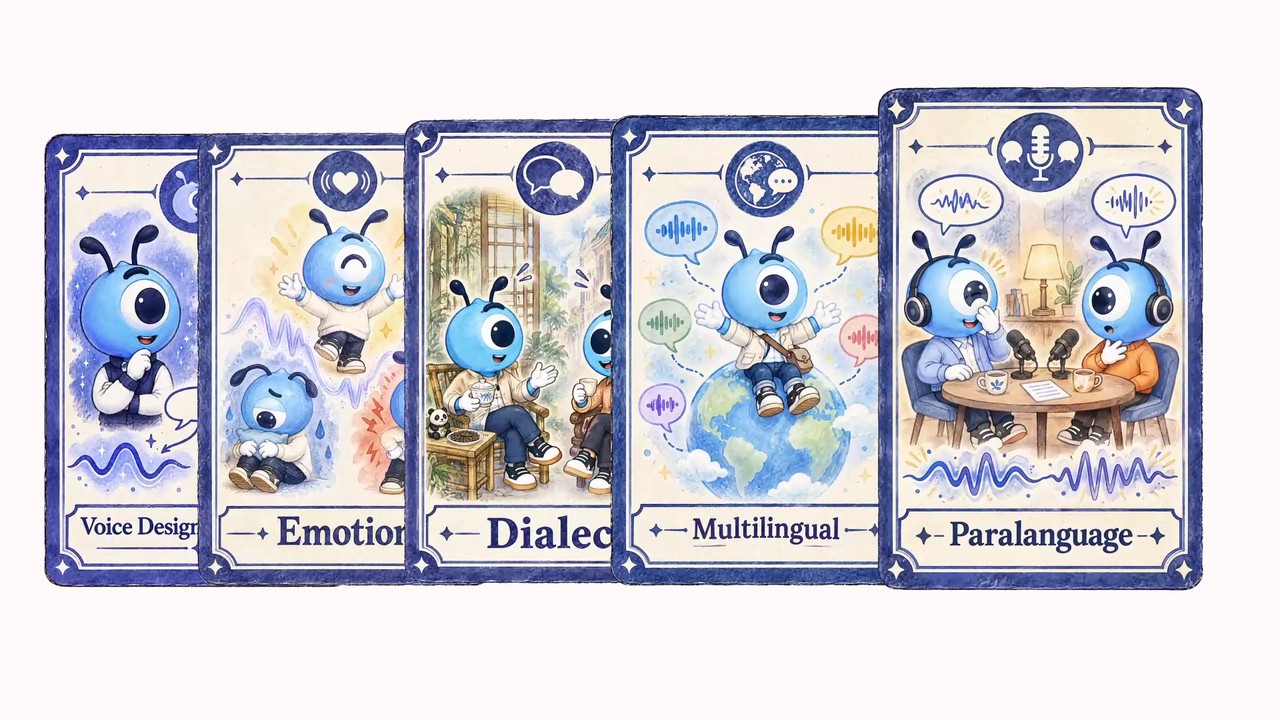
\robotoslablightdots.tts Technical Report
Text-to-speech (TTS) systems have largely solved intelligibility on standard read-speech benchmarks. What users expect from a modern system is broader: expressive and controllable output, real-time synthesis, and coverage of neutral reading, emotional dialogue, paralinguistic events, singing, and general audio. Current systems pursue this goal along three roughly distinct technical routes, and each route has its own unresolved problem.
Ming-3.0-tts
Open-weights speech generation for audio stories, short-video narration and product assistants.
The risks of OpenAI's Whisper audio transcription model
Writing at the end of the world, from Hveragerði, Iceland
kwindla on Twitter / X
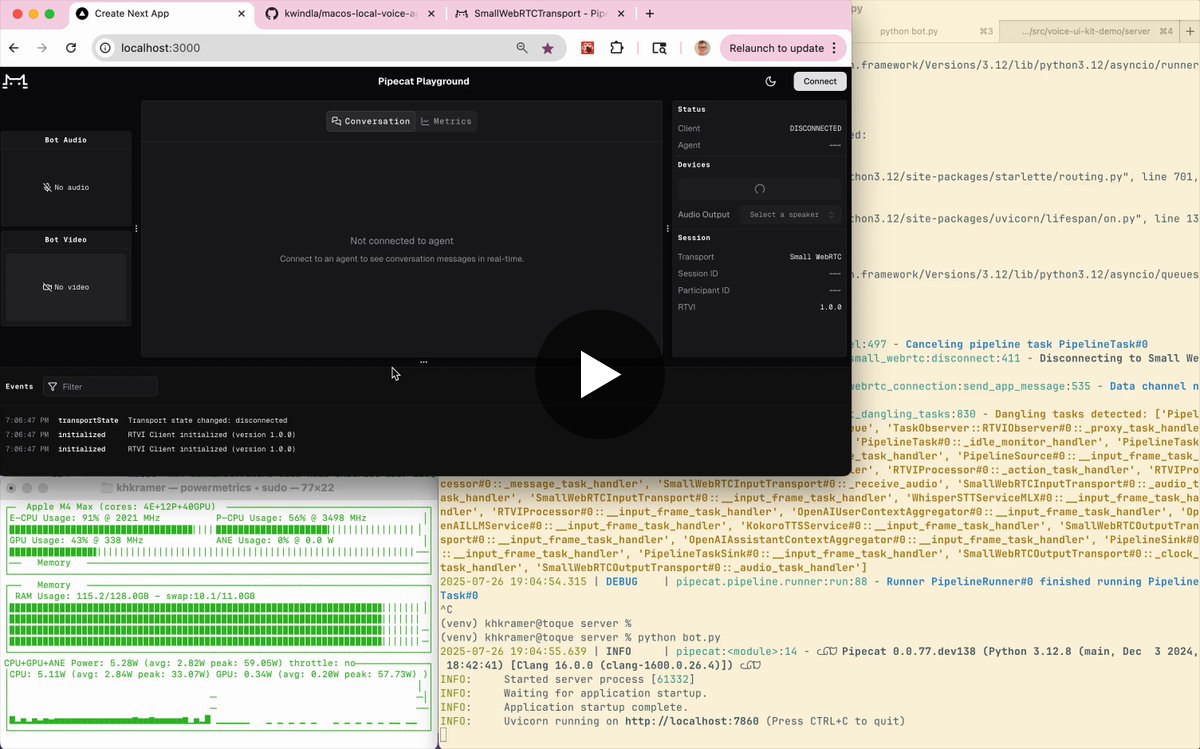
Local voice AI with a 235 billion parameter LLM. ✅- smart-turn v2- MLX Whisper (large-v3-turbo-q4)- Qwen3-235B-A22B-Instruct-2507-3bit-DWQ- KokoroAll models running local on an M4 mac. Max RAM usage ~110GB.Voice-to-voice latency is ~950ms. There are a couple of… pic.twitter.com/iYNQlb9JkI— kwindla (@kwindla) July 27, 2025
How to Make Small Language Models Outperform Large Language Models Using DSPy!
How a 3B Language Model Surpasses an 8B Counterpart with DSPy? “In an era where language models (LMs) are revolutionising countless tasks, their potential is only as powerful as we interpret …
On-Device LLM Throughput Calculator - a Hugging Face Space by FL33TW00D-HF
This tool estimates and visualizes the throughput of Large Language Models on devices with memory bandwidth constraints. Users input device and model configurations, and the tool generates a plot s...
Voiceflow, which allows anyone to make voice apps without coding, raises $3.5 million | TechCrunch
The market for voice apps has opened up -- Amazon Alexa's platform alone has more than 80,000 skills as of earlier this year -- and there's little sign of

WhisperSpeech/WhisperSpeech
An Open Source text-to-speech system built by inverting Whisper.
voiceome.org
Find information, resources and relevant links for voiceome.org. This domain may be for sale.
Luozhu on Twitter / X
I taught a speech model to understand context in conversation. This is what happenedIt adjusts voice and tone to express urgency, comfort, understanding from the dialogue. Just like a real human being520M model. Runs locally on consumer devicesHow this is achieved 🧵 pic.twitter.com/oMgSh2TKbO— Luozhu (@LuozhuZhang) February 27, 2026
