

Using Tract and Bevy, guess the number being drawn.
Quickly Training Game-Playing Agents with Machine Learning
Posted by Leopold Haller and Hernan Moraldo, Software Engineers, Google Research In the last two decades, dramatic advances in compute and connecti...

High Performance AI Lab
High Performance AI Lab builds open inference systems and publishes the conditions behind every number — device, model, quant, and rep count.
LLM Rankings | OpenRouter
LLM rankings and AI leaderboard based on benchmarks and real usage data from millions of users. See which AI models developers actually use.
Open Models Inference for Coding · Umans AI
Hosted Kimi K3, GLM 5.2, and DeepSeek V4 Flash. Pay per token, on infrastructure we own.

Teaching AI to Optimize AI Models for Edge Deployment
How our agent, Möbius automated a Core ML port in ~12 h (vs. 2 weeks), hit 0.99998 parity, and made it 3.5× faster, while staying on the CPU.
Solving a Million-Step LLM Task with Zero Errors
LLMs have achieved remarkable breakthroughs in reasoning, insights, and tool use, but chaining these abilities into extended processes at the scale of those routinely executed by humans,...

vllm-project/vllm
A high-throughput and memory-efficient inference and serving engine for LLMs
Frontier Pre-training at Microsoft AI | Microsoft AI
In June, we announced MAI-Thinking-1, a general-purpose foundation model post-trained on top of MAI-Base-1 with strong reasoning performance. We’ve recently completed pre-training our new state-of-the-art model, MAI-Base-2, an MoE foundation model with 80 billion active and 2.8 trillion total parameters.
LLM Leaderboard - Comparison of over 100 AI models from OpenAI, Google, DeepSeek & others
Comparison and ranking the performance of over 100 AI models (LLMs) across key metrics including intelligence, price, performance and speed (output speed - tokens per second & latency - TTFT), context window & others.
Demystifying llm-d and vLLM: The race to production
Learn how vLLM and llm-d work together for efficient and scalable large language model (LLM) inference. Discover the benefits of disaggregated scaling, expert-parallel scheduling, and KV cache-aware routing.

Liquid AI on Twitter / X
Today, we release LFM2.5-350M. Agentic loops at 350M parameters.A 350M model trained for reliable data extraction and tool use, where models at this scale typically struggle.<500MB when quantized, built for environments where compute, memory, and latency are constrained.🧵 pic.twitter.com/zZPKzcCwH9— Liquid AI (@liquidai) March 31, 2026

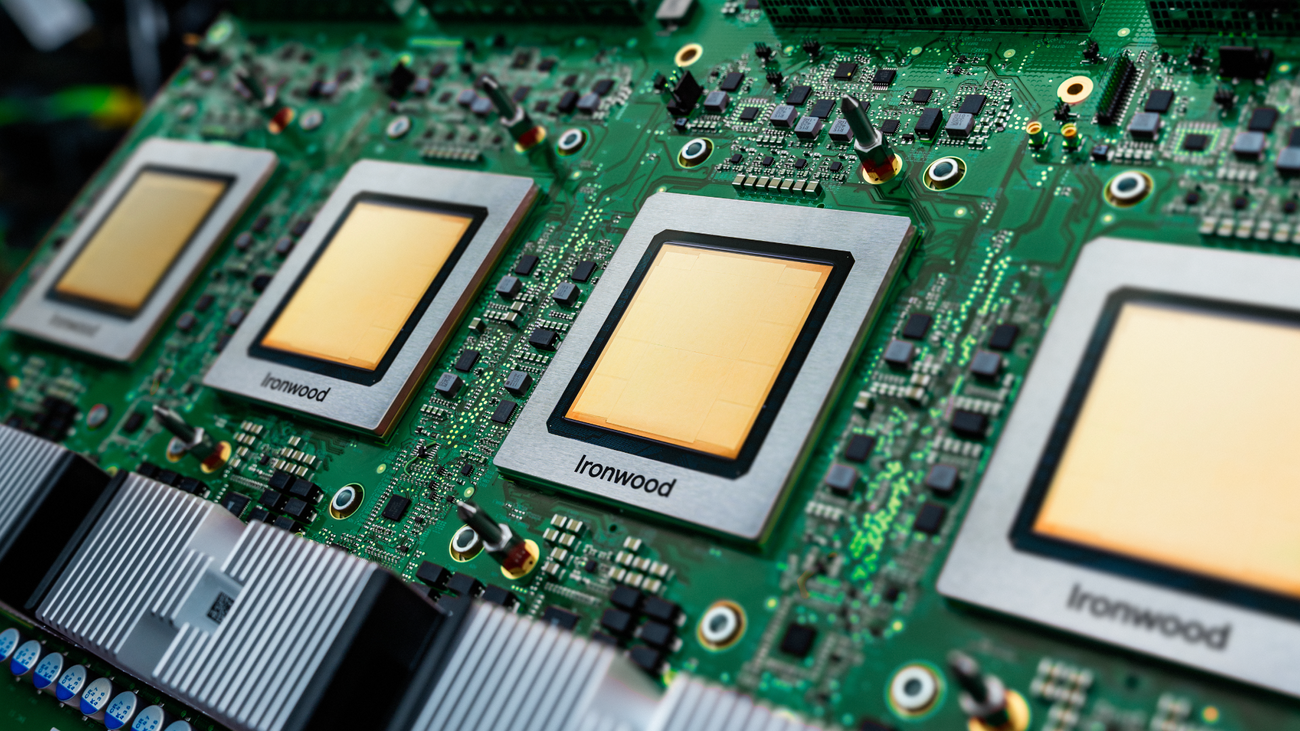
Ironwood: The first Google TPU for the age of inference
We’re introducing Ironwood, our seventh-generation Tensor Processing Unit (TPU) designed to power the age of generative AI inference.
Forcing Generative Models to Degenerate Ones: The Power of Data...
Growing applications of large language models (LLMs) trained by a third party raise serious concerns on the security vulnerability of LLMs.It has been demonstrated that malicious actors can...
Models & Pricing | DeepSeek API Docs
The prices listed below are in units of per 1M tokens. A token, the smallest unit of text that the model recognizes, can be a word, a number, or even a punctuation mark. We will bill based on the total number of input and output tokens by the model.
Look-ahead Reasoning with a Learned Model in Imperfect Information Games
Test-time reasoning significantly enhances pre-trained AI agents' performance. However, it requires an explicit environment model, often unavailable or overly complex in real-world scenarios....
Wafer - Ship the fastest inference in the world
Autonomous AI agents that profile, diagnose, and optimize GPU inference across your entire stack — from kernels to models to production pipelines.
